A content SEO checker score is a lint result, not a release gate: how a technical team should wire content checks into a pipeline that also verifies claims against the product
Automate SEO linting, but verify product claims separately before shipping.
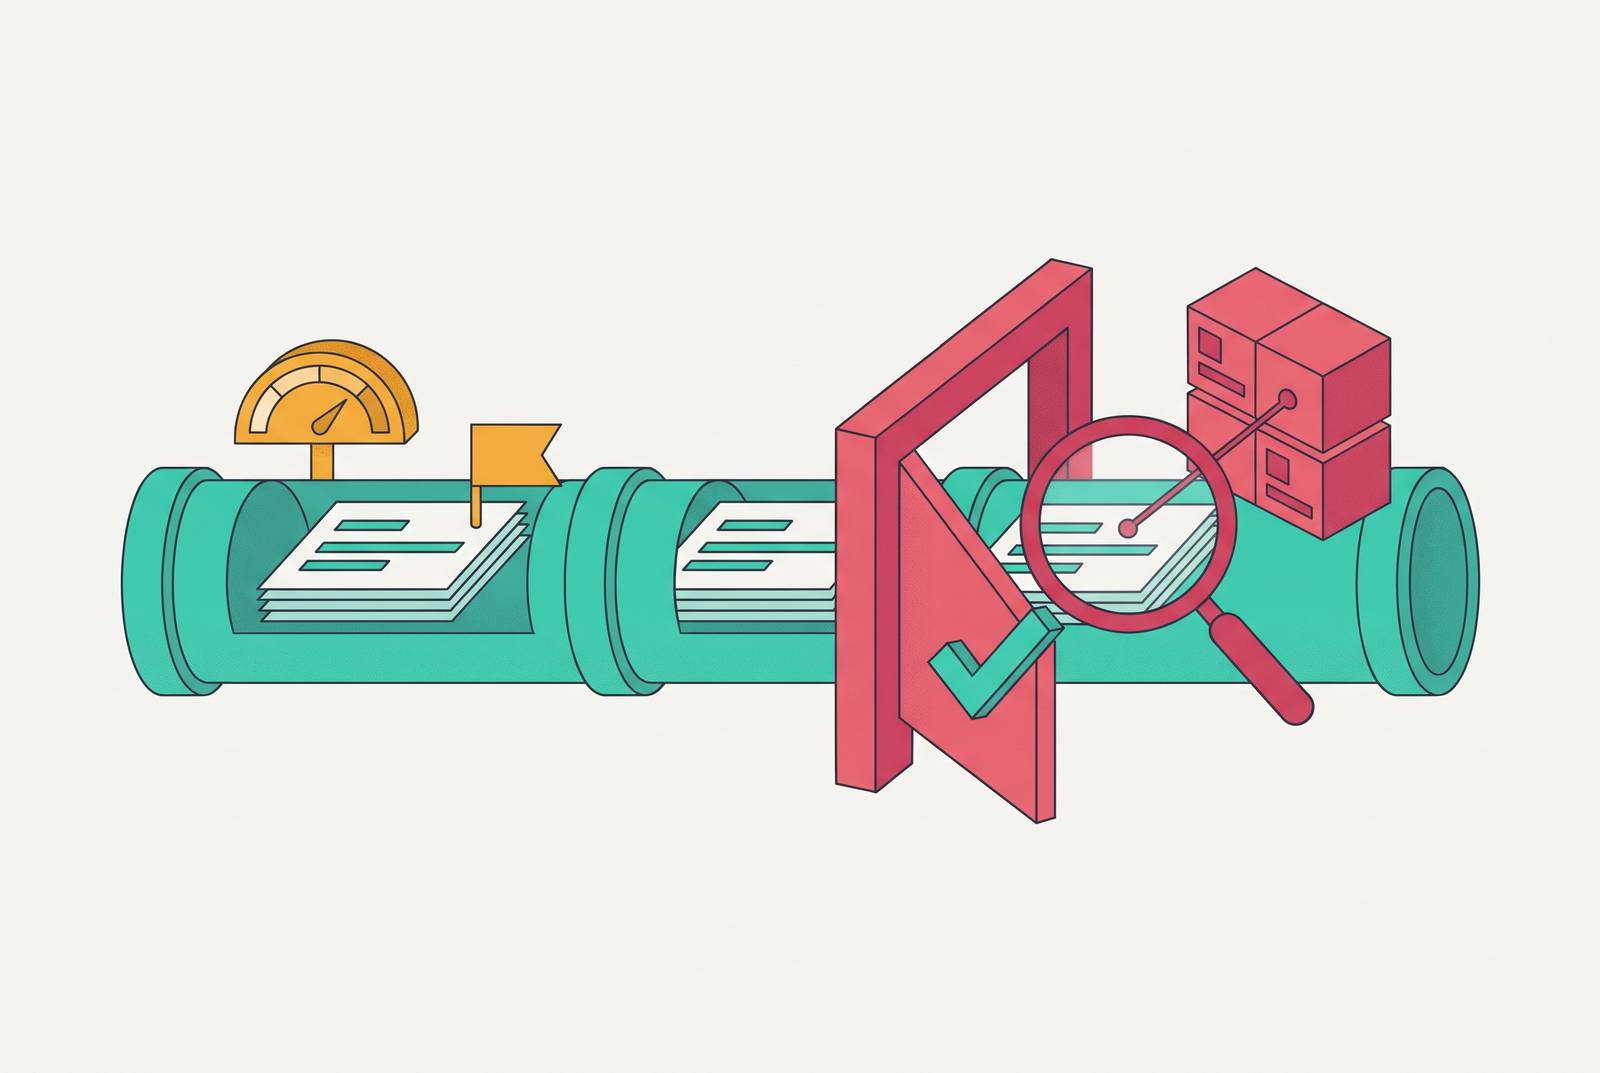
A content SEO checker belongs in a publishing pipeline, but its score should not decide whether a page is ready to ship. It produces a lint result. A technical team should automate those checks, version the results with the draft, and run a separate verification track against the product’s source of truth before measuring what happens after publication.
What a content SEO checker actually measures, and why that makes it a lint result
ESLint can flag a missing semicolon without knowing whether a function does what the product manager asked for. A content SEO checker has the same boundary. It can flag a missing keyphrase in a slug without knowing whether the paragraph beneath the heading describes the product correctly. Both tools inspect observable patterns against rules. Neither establishes that the work fulfills its purpose.
The @power-seo/content-analysis package illustrates the surface area of these checks. They include keyword density and distribution, title and meta description checks, heading structure, word count, image alt text, and link presence. Each check returns a score and a maxScore. That output tells a team which rule a draft satisfies and where it falls short, making the result useful for finding specific repairs.
The seo lint tool flags habits such as “not X” contrasts, verbless fragments, and stock idioms that could fit any company. Its findings fall into the categories ai, copy, and seo, with a named pattern and a concrete fix. It does not guess who wrote the page. Like a code linter, it identifies a pattern that an author or automated process can change.
Even apparently precise thresholds need that context. The tool’s documentation describes its 30–60 character title guidance as “rules of thumb for what fits in a search result, not limits Google enforces”. A warning calls for someone to judge whether there is a failure. More broadly, a content score is a proxy for coverage and structure, including how closely a page resembles pages that already rank. How closely pages match can help with editing, but it cannot show whether those pages, or the draft that follows their pattern, tell the truth.
What a score cannot verify: product claims, statistic sources, indexing and canonicals
Product and factual claims form the first failure category. A page can score 90 while misstating a pricing tier, presenting an unsupported benchmark figure, or describing a deprecated feature. The checker misses these errors because it checks the form of the text without checking its claims against product facts. Close to true is still wrong. A claim can use the right words and sound as though it could work while promising something the product does not support.
Statistic provenance is the second failure category. A citation may lead to a primary source, or it may lead to a secondary aggregate that repeats a number without preserving its origin. Citation presence cannot distinguish those cases. A checker can reward the existence of a reference without evaluating the source chain behind it. The visible sign of support is not the same as evidence that supports the particular claim.
Indexing and canonicals form the third failure category. A strong content score can coexist with an incorrect canonical tag that directs authority toward a duplicate URL. The Plerdy SEO checker surfaces canonical URLs, noindex and nofollow directives, and heading hierarchy, showing that on-page tools can expose relevant technical data. But reporting a condition is not enforcing it. When a wrong canonical remains one data point inside a passing score, the workflow has failed to treat it as a blocking error.
Ranking also depends on search intent, usefulness, factual accuracy, competition, backlinks, site quality, and technical SEO, none of which a content score measures directly. Some technical signals can be surfaced by a checker, while factual support requires another kind of examination. The key distinction is between having information about a page and having evidence that it meets each condition for publication.
Why treating a composite score as a release gate creates a false sense of readiness
A single number with a threshold looks familiar to an engineering team. It offers a clear go-or-no-go decision. That simple decision makes it tempting to use a content score to decide when to release a page instead of just helping to edit it, even though the score does not check for errors that can confuse a customer.
A composite can also blur two different kinds of judgment. Keyword density, readability, and word count admit degrees, while a required canonical or H1 is present or absent. If those signals go into the same weighted total, a high keyword score can make up for a missing canonical. The arithmetic may be valid, but the tradeoff is not. Better keyword coverage cannot fix a wrong URL signal.
The seoscoreapi.com CI/CD example shows how individual checks can sit beside a score threshold. Its custom Python variant adds a missing meta title, meta description, canonical, and a below-threshold score to a shared failures list, then fails if any are found. The official GitHub Action instead fails on a configurable score threshold. That difference is important to the implementation. A team seeking hard failures for specific conditions must encode those conditions rather than assume that a score threshold enforces them.
What about a team whose threshold has worked so far? Past acceptance does not show that the gate can detect a wrong product claim. The appropriate role for the score is a CI warning or secondary degradation check. Deterministic failures need their own gates, and factual claims need a parallel verification track.
A pipeline that counts, verifies, then measures after publishing
Stage 1, before the draft, is scope and count. Its question is whether the piece should be written at all. A team should generate a demand map from search and product data, cluster keywords by intent and template fit, and score those clusters by opportunity, difficulty, and product fit. Work items for the strongest clusters should spell out the acceptance criteria they must meet. This connects the decision to commission a piece with the facts it must eventually get right.
Instead of asking only whether the finished copy sounds credible, the team can test whether it meets the product claims established during scoping. For AI-generated drafts, pre-generation prompting controls belong here as part of that preparation. They do not replace later fact-checking. The workflow still needs post-generation verification and a human editor to sign off before the piece is published.
Stage 2, on the draft, runs lint and verification in parallel. The lint track should run automatically on every draft through an API or CLI, checking SEO compliance, structural standards, readability, and voice before human review. Results should be versioned with the content so that the findings stay attached to the draft they describe. The seo lint tool supports CLI and MCP integration. An agent can therefore be instructed to check its own draft and fix every error before an editor receives it.
The verification track has a different job. It checks claims against the product’s own source of truth and looks at the primary sources behind statistics, going beyond whether a citation is present. High-confidence claims auto-pass, medium-confidence claims are flagged with source links, and low-confidence claims block publication until a human fact-checker verifies them. The confidence decision belongs to verification.
A low keyword density finding and a misstated pricing tier require different expertise, so work on one need not wait for the other. Both tracks still feed the release decision. A draft that clears automated gates moves to human editorial review, where the editor can polish supported copy rather than begin with unresolved machine-detectable errors.
Stage 3 brings together the technical release gate and the checks run after the page is published. The technical checks must run before the URL goes live, while measurement comes after the page is published. Canonical tags must be present and correct, every page must have at least one internal link, links must not be broken, and each page must have an H1 and meta description. The sitemap must include all published URLs. A page intended for indexing must also not ship with noindex, and missing meta titles should block the build.
After publication, the question changes from compliance to performance. A team should set a mandatory re-check after a fixed interval and log the before and after content scores together with the GSC ranking position for the target keyword at both points. Over three or four audit cycles, that record can reveal which fixes are associated with ranking movement on the particular domain. The score remains useful evidence about what changed. It is no longer mistaken for the outcome the changes were meant to produce.
How answer engines and agents change what "ready to publish" means
Traditional SEO focuses on pages, connecting a target keyword with a URL and its ranking. Answer Engine Optimization, or AEO, makes content easier to extract for snippets and direct answers, while Generative Engine Optimization, or GEO, aims to make it usable as a citation in synthesized answers. These goals overlap without being interchangeable. A page can pass keyword checks while leaving an answer engine without a clear passage to quote.
That shifts part of the draft check from pages to passages. A self-contained Q&A block can serve as an independent citation candidate because it answers a question without requiring the surrounding article. Five well-structured Q&A blocks give a model five such candidates to choose from, so it does not have to piece an answer together from narrative prose. Structure gives the verification and lint tracks another concrete question to ask, namely whether a passage is complete, unambiguous, and supported when read on its own.
Entity grounding adds a separate readiness check. Organization schema should contain an accurate name, URL, logo, and sameAs properties linking to the relevant Wikidata, LinkedIn, and Crunchbase records. Consistency across those records and the About page gives systems corroborating information about the brand’s identity. A keyword-density score does not test that agreement. Where no Wikidata entry exists, schema markup, Crunchbase, LinkedIn, and consistent third-party citations can still contribute to entity validation.
When reviewing a draft, the team should check its passage-level Q&A structure and primary-source citations, while the technical track should check that the entity schema is complete and correct. Brand mentions, citations, and AI referral traffic show how a page does in ways that GSC ranking position cannot. A team targeting both search results and AI answers therefore needs evidence from both, rather than treating success in one as proof of success in the other.
Freshness extends that plan beyond the first release. AI systems favor recent, frequently updated content, and a consistent publishing cadence can signal active expertise. Automated content quality scans, SEO/GEO audits, and bulk indexing can support that upkeep at scale. Publication is not the last checkpoint. A publish-and-forget workflow leaves no regular opportunity to revisit either the content or the signals used to assess it.
Will an agent trust this page enough to cite it or act on it? A lint result cannot answer that question, even when every finding has been resolved. The pipeline must also establish factual support, technical readiness, extractable answers, and a plan to measure real use.