Algorithmic Topic Selection Before Content Production
Pick topics based on what AI engines actually ask about, not traditional search keywords.
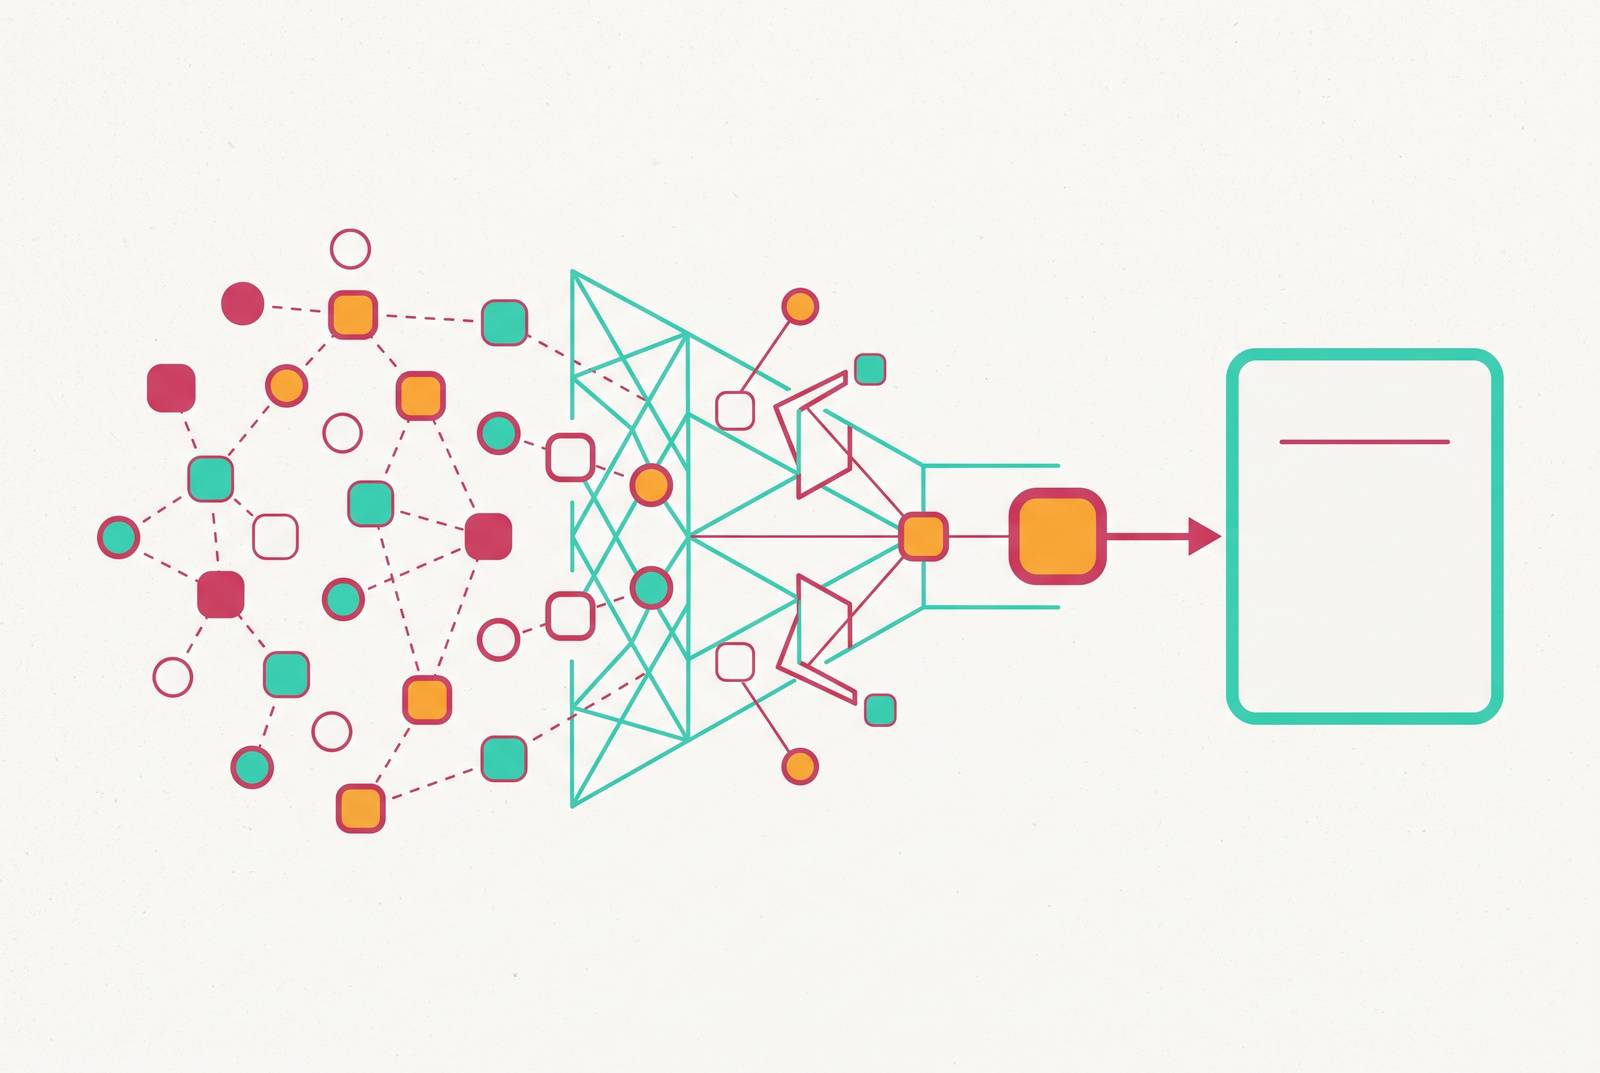
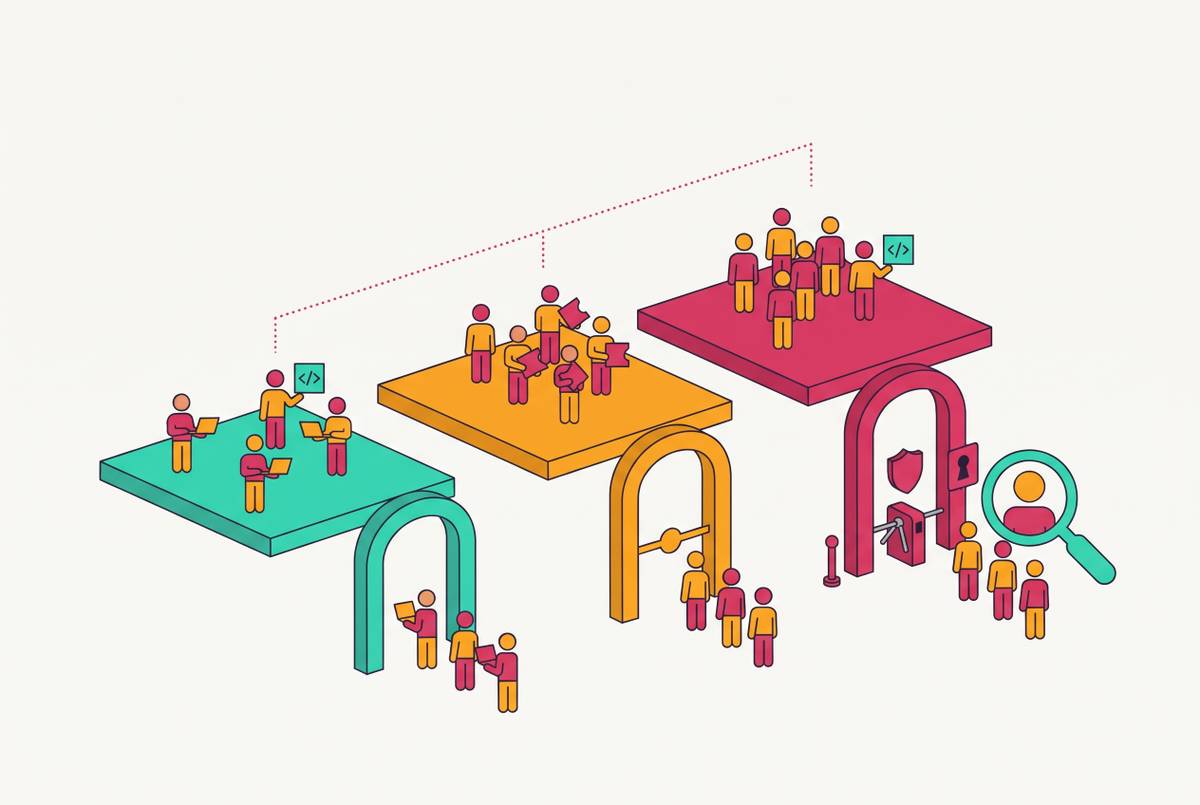
Algorithmic topic selection means you choose what to write based on what AI answer engines actually retrieve and cite, and it decides whether a piece can earn a citation long before anyone drafts a single sentence. AI answer engines retrieve and surface content at the query level, not the domain level, so a piece built on the wrong topic earns nothing, no matter how well it's written. Systems built on retrieval-augmented generation anchor their answers to external knowledge sources, whether indexed documents, databases, or web content, for a specific query, and that content has to clear a sequence of gates before it ever reaches a reader: it must be crawlable and indexed, retrieved for that particular query, ranked against competing candidates, and finally trusted enough to be named in the answer. A piece can fail any one of those gates quietly, even when it covers its subject with complete accuracy, and the failure produces no error message, no warning, just silence where a citation might have been. That silence has a real consequence: a page that never ranked in Google can be cited regularly by an AI engine, and a page that ranks well in Google can go months without appearing in a single AI answer. The two retrieval jobs run on different logic, and the decision about which topic to pursue in the first place is the only point in the process where a team can account for both at once.
How AI query patterns differ from keyword search patterns
The queries that AI engines field look structurally different from the keyword strings that built the last two decades of search optimization. They run longer, read more conversationally, and take the shape of actual questions, rather than the clipped, head-term-plus-modifier patterns that keyword tools were built to count. Topic Intelligence's 2026 cluster methodology marks this shift explicitly: the data inputs that inform cluster design have expanded beyond keyword research to include AI query analysis. The question landscape now governs which articles are worth producing, not the keyword landscape alone. A traditional keyword scan surfaces head terms and their modifiers. An AI query scan surfaces full questions, and those questions map far more directly onto the actual prompts people type into ChatGPT, Perplexity, Claude, and Gemini. If a content team scans keyword volume and stops there, it will miss the questions those engines field most often, and the open citation opportunities sit right there. The practical reframe follows from that gap: topic selection has to start with questions rather than keywords, because AI engines are built to answer prompts, and the content that earns citations is the content that mirrors how people actually ask for help.
Identifying a retrievable, citable gap before committing to production
A citable gap is a question that AI engines are being asked at meaningful frequency, but that the existing web answers poorly. Finding that combination is the core analytical task of algorithmic topic selection, and Topic Intelligence's methodology names it directly: the GEO layer identifies which questions in a cluster hierarchy are being asked of AI systems at high frequency while current web content answers them poorly, and those questions become priority cluster articles that close a search gap and an AI citation gap in the same move. Two conditions have to hold together for a gap to count. The question has to be asked often enough to matter, and the content currently answering it has to be thin, vague, or structurally incompatible with how AI systems retrieve information. Neither condition alone is sufficient: a high-frequency question with a strong existing answer isn't a gap, and a poorly answered question nobody asks isn't worth the production budget. Testing for both is straightforward enough to do by hand. Run the candidate query through the AI engines a team is targeting and look at what comes back: does the answer name a source, does it lean on something visibly thin, or does it hedge with language like "I don't have reliable information"? Each of those outcomes points to a gap that a well-structured piece could fill. The sequencing matters as much as the diagnosis. If a team identifies citable gaps before drafting begins, it aims every piece at a confirmed retrieval opportunity, but if it picks topics first and checks AI behavior only after publication, it has no reliable signal about what to write next, because it's assembling evidence after the decision it was meant to inform. Gap identification has to run as a repeatable analytical step against every candidate topic, not as a one-time audit performed at the start of a content program and then forgotten.
Topic cluster architecture and compounding AI authority
A single citable piece earns a citation. A well-built topic cluster earns authority, and the distinction is what separates a content program that compounds from one that merely accumulates pages. AI retrieval systems reward the cluster because coherent topical depth signals that a site is the authoritative source on a subject rather than merely the source of one well-answered query. Topic Intelligence's 2026 cluster model describes the pillar article as doing three jobs at once: targeting the primary keyword cluster for SEO, directly answering the most common AI queries on the subject for GEO, and serving as a navigational hub to every piece of cluster content beneath it. That design serves both retrieval systems at once, instead of choosing one and hoping the other follows. Cluster articles then take up the subtopics and questions the pillar introduces but doesn't fully resolve, and the standard is a high one: every significant question a person interested in the main topic might ask should eventually have a cluster article addressing it directly, which functions as both the SEO strategy and the GEO strategy for that subject. None of this compounds without the internal linking architecture holding it together. The pillar links to every cluster article, every cluster article links back to the pillar, and related cluster articles link to each other where the relationship is genuine rather than forced, and that structure is what signals topical authority to search engines and AI retrieval systems alike. Each new cluster article that closes a citable gap also strengthens the authority signal of the pillar and of the articles around it, so the return on any single piece includes its own citations plus its contribution to the cluster's aggregate retrieval signal. If teams publish cluster articles without building that linking architecture, they end up with a collection of loosely related pages rather than a cluster, and the authority signal never compounds, because retrieval systems have no structural way to see the topical relationship the team intended.
Content for AI citation versus content for organic traffic as different architectural decisions
Treating every piece as a dual-purpose asset, serving Google organic and AI citation at once, tends to produce content optimized for neither, because the two retrieval logics differ enough that topic selection needs to name the primary job before drafting starts. Google's own documentation states that many of the suggested "hacks" for AI citation aren't effective and aren't supported by how Google Search actually works, and that institutional position matters here because it confirms the two jobs run on different systems rather than a single unified ranking logic that a team could satisfy with one well-rounded piece. The architectural split appears in practice: some content is built specifically for Google organic, commercial category pages, high-intent comparison content, transactional pages designed to convert a visitor who has already decided to buy. Other content is built specifically for LLM citation: definitional content, entity relationship pages, and brand authority signals that help an AI engine understand who a company is and what it's known for. Conflating the two carries a real cost. A piece built to rank on Google with high commercial intent can read as too promotional and too shallow on definitional substance for an AI engine to cite with confidence, but a piece built for AI citation can run too encyclopedic to capture the transactional intent that drives organic conversions. Neither failure mode reflects poor execution. Both trace back to a topic selection decision that never specified which job the piece was supposed to do, and that specification belongs upstream, at the point a topic gets chosen, not somewhere in the editing process after a draft already exists.
Signals inside an AI engine's behavior that reveal which topics to prioritize next
AI engines leave observable traces in their own answers, and if you read those traces systematically, you can see exactly where coverage is weak and which topics deserve production resources first. Four signals do most of the work. An engine that answers a query by saying it's working from general knowledge, or that fails to name a source at all, is signaling that nothing it retrieved was trusted enough to cite, and that silence functions as a direct invitation for a well-structured piece on the subject. An engine that cites something visibly shallow, outdated, or only tangentially related to the query is revealing a different kind of gap: the absence isn't content, it's quality content, and a better-structured piece on the same topic can displace what's currently sitting there. An engine that consistently cites a competitor for a query a brand should reasonably own confirms that the topic is both high-frequency and citable, and the selection decision that follows is simple: build a stronger piece aimed at the same retrieval opportunity. And because engines don't behave identically, a topic that earns a confident citation on one engine while drawing a hedged non-answer on another is showing patchy coverage across the landscape. A single well-built piece could close more than one citation gap at the same time. None of these checks require specialized tooling to observe. Running them systematically across a full list of candidate topics, before a single brief gets written, is what turns topic selection from anecdotal observation into a repeatable intake process, and that repeatability is what makes the whole approach algorithmic rather than a matter of editorial instinct.
Structuring the topic selection intake so that every brief enters production already validated for AI citability
The highest-leverage intervention available to a content team is at the intake stage, before drafting begins, in the form of a validation gate that confirms every proposed topic is aimed at a retrievable, citable gap before it becomes a brief. That gate runs four checkpoints in a fixed order. The first is query confirmation: run the proposed topic as a natural-language question through each target AI engine and record what each one returns, whether that's a citation, a hedge, or outright silence. The second is gap quality assessment: where an engine does cite something, evaluate whether that source is genuinely strong or just the best option available among weak choices; if it's the latter, the gap is confirmed real. The third is cluster placement: confirm where the proposed topic sits in the cluster hierarchy, whether as the pillar, a primary cluster article, or a supporting piece, and verify that the linking architecture connecting it to the rest of the cluster will actually be in place before publication. The fourth is job assignment: tag the piece as primarily serving Google organic, primarily serving AI citation, or genuinely dual-purpose, and confirm the brief specifies a format and depth that match that job. Recording all four checkpoints before any topic advances to a draft brief makes every downstream production decision purposeful. This gate functions as the pre-generation setup stage of a properly designed content pipeline, and it's the single point in the process where human judgment about strategic fit and AI behavior carries the most weight, because it's the last moment before any production resource gets committed to a topic that might not have been worth pursuing.
Measuring whether the selection process is working once content publishes
The only way to confirm that topic selection is actually working is to measure AI citation behavior after publication against the baseline recorded at intake, and without that closed loop, the entire selection process remains intuition dressed up with extra steps. The measurement has to start with a distinction that's easy to blur: mentions, where a brand appears somewhere in an AI result, and citations, where a piece of content is actually used as a cited source, are different signals, and citations carry the stronger authority evidence because they're the direct outcome the selection process was built to produce. Engines need tracking separately rather than as a blended average, because the same topic can earn a confident citation on one engine while drawing a non-answer on another, and an aggregate "AI visibility" figure flattens that variance into a number that gives the next selection cycle nothing to act on. Topic Intelligence's cluster measurement framework names four metrics that matter beyond any single article's performance: topic visibility score, which tracks what percentage of the queries across a topic's full question landscape the cluster actually has content for; cluster ranking distribution, which counts how many articles land in positions 1 through 3, 4 through 10, and 11 through 20; AI citation frequency, which tracks how often the cluster's content appears in AI-generated responses to queries in that domain; and cluster engagement quality, measured through average scroll depth, time on page, and the rate at which readers navigate between cluster articles. Individual article metrics miss what these four capture together, because they can't see the compounding authority that a cluster builds over time. The feedback runs in both directions: a piece that earns strong citations confirms that the gap identification method worked, while a piece that earns none despite solid coverage of its topic points to a structural problem, either in how the gap was identified or in how the content itself was built. That loop is what makes topic selection algorithmic rather than a one-time judgment call made at the start of a content program. The system learns from each publication cycle, narrows the distance between what the selection logic predicts and what the engines actually cite, and produces an increasingly accurate map of where the next citable gap is sitting, establishing topic selection as the upstream lever that steers production.