A "marketing strategy consultant for B2B startups" page promises a hundred ideas scored down to a few: what a founder should ask to see before trusting the scoring, and what a coding-agent workflow makes inspectable
Ask to see the weights, the evidence, and the rejected ideas.
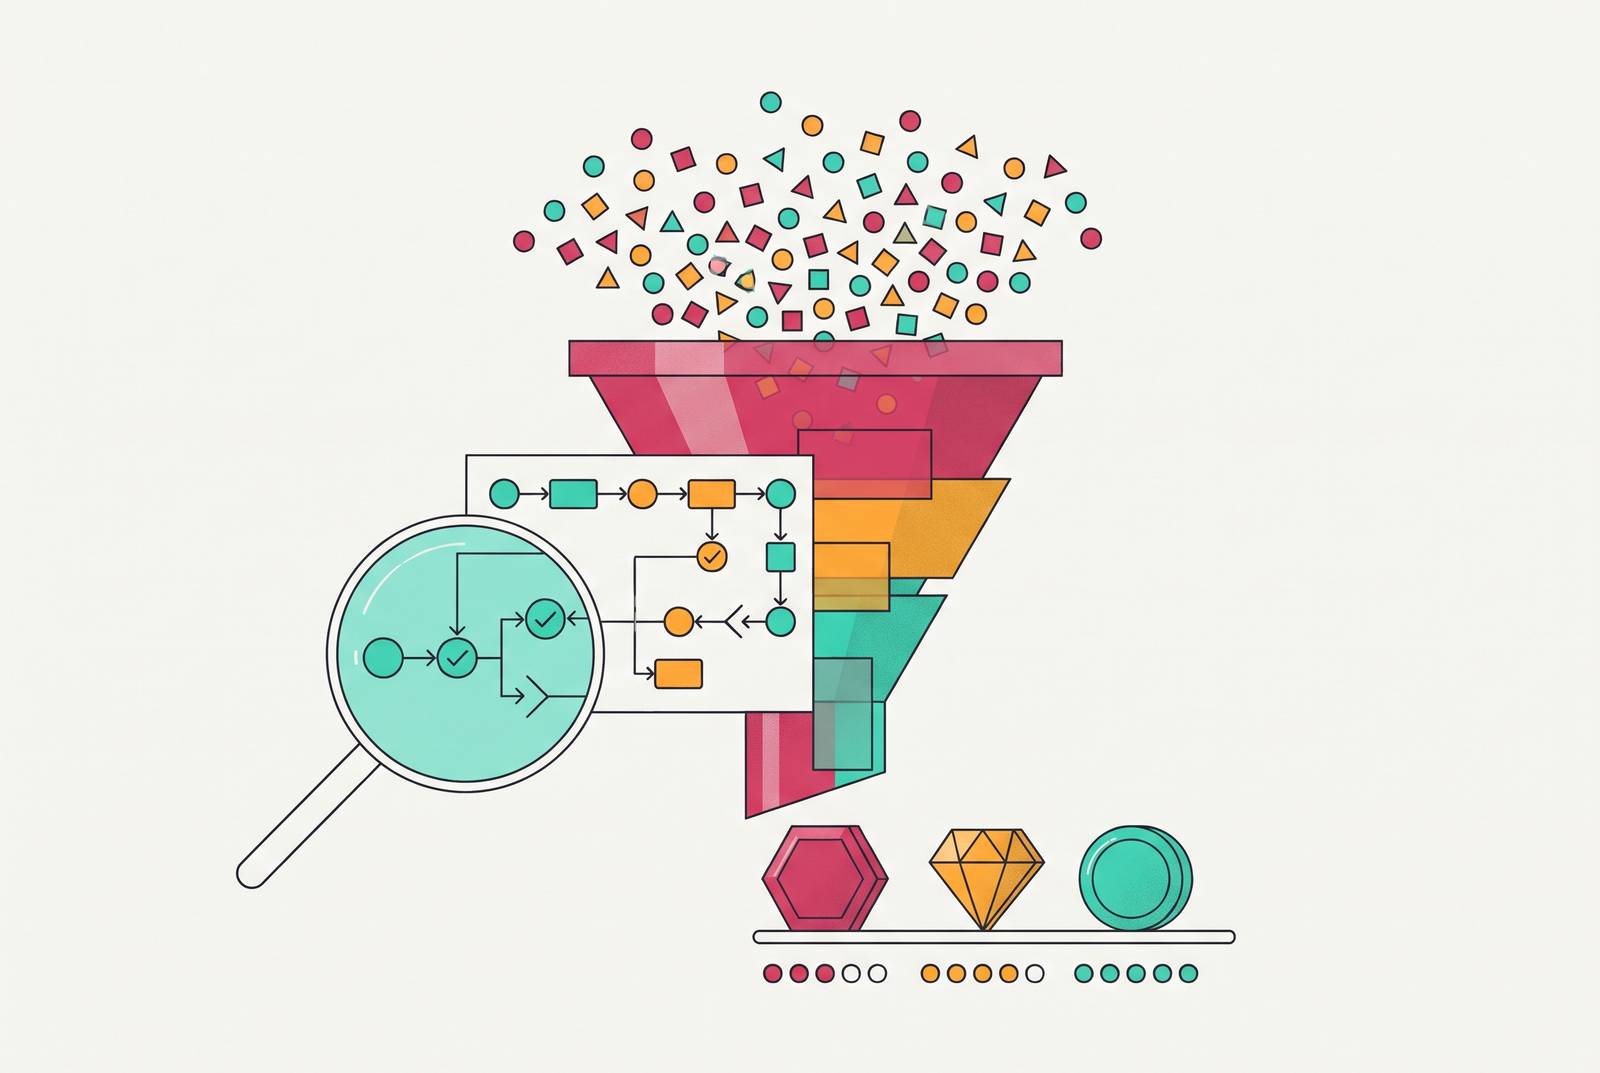
A consultant’s promise to turn a hundred growth ideas into a shortlist raises a question about evidence and expertise. A founder should trust the scoring only when its inputs, buyer-prompt tests, and decision rules are open to inspection. A coding-agent workflow can make that record auditable and company-owned, without replacing the human judgment that gives it value.
Why a "100 ideas scored to a shortlist" pitch is worth scrutinizing
The consultant page offers a familiar kind of relief. Rather than leave a founder with an unruly set of growth options, it promises roughly a hundred ideas, scores them against criteria, and delivers a prioritized shortlist. That is an appealing service for a team struggling to choose. A senior outside perspective can reveal options the team has missed and force a decision about which deserve time.
But a ranked list is not evidence by itself. The page says that “one success in five experiments would be a good outcome,” presenting an expectation. What counts as success, and has that rate ever been measured against actual outcomes? Without those answers, a founder may take a reasonable hope to be a benchmark.
The claim that a weekly conversation can “move the channel” deserves the same scrutiny. It could describe useful judgment about where to invest next, but the phrase leaves the trigger for that decision unstated. The value of the conversation can be real. The gap is whether its reasoning becomes something the company can examine.
What modern B2B discovery does to any scoring model that ignores it
A scoring model built only around search rankings starts from an incomplete picture of B2B discovery in 2026. Buyers find brands through both search results and AI answers, but what works in one may differ from what works in the other. Google rewards a ranked URL, while AI answer engines retrieve quotable passages. The unit of discovery is different. A scoring pass that treats the two as interchangeable can misjudge what an idea is likely to achieve.
For example, a page can rank on the first page of search results and earn zero AI citations. Its search position does not establish that an answer engine will find sentences it can lift and attribute. Keyword performance can support a case for search visibility, but it cannot, by itself, establish the case for inclusion in an AI answer.
AI citations can point beyond the brand’s own domain to third-party review platforms, earned media, and communities. Owned content is only part of the picture. A shortlist that puts “publish more blog posts” above “seed credible third-party mentions” therefore needs evidence for that choice. Otherwise, it may favor the surface the company knows how to measure over the one its buyers are using.
The five things a founder should ask to see before trusting any scored list
What dimensions were scored, how much weight does each have, and why are those weights right for this company’s stage and channel mix? The criteria need to be written down. A consultant may have excellent reasons for favoring one idea over another, but those reasons cannot be audited if they remain implicit. Written weights also expose what the model favors before anyone debates its recommendations. When the company’s situation changes, the team can then examine which assumptions need to change with it.
Which signals were pulled before scoring began, including analytics, Search Console, sales notes, and buyer-prompt tests against AI answer engines? Evidence from the company itself is what makes a ranking fit that company. Search performance shows one part of the opportunity, conversion data another, and sales notes reveal what prospects are saying. Without them, a shortlist may claim to address modern discovery while relying only on keyword data.
Can the founder see the bottom quartile of ideas and the stated reason each was cut? The rejected pile tests whether the scoring actually discriminated between options. A shortlist alone cannot show whether the process challenged what the consultant already believed or just put numbers beside those beliefs. Vague reasons tell the founder very little. Specific reasons make it possible to examine why an idea lost out and whether new evidence would justify reconsidering it.
Before the test starts, what will be written down as success and failure for each experiment? This is what makes the “one success in five experiments” expectation testable. A result cannot be judged against a threshold chosen after it arrives. Learning may still come from a failed test, but learning and success are not interchangeable labels.
When a channel was switched or dropped, what triggered the call, and is there a written record? A change in direction should have a rationale that survives the call in which it was agreed. Otherwise, the consultant is running the instrument in their head. When the engagement ends, the company may retain the recommendation but lose the reasoning needed to operate without its author.
What "inspectable" actually means for a scoring pass and an experiment log
An inspectable scoring pass puts its logic in a file a human can open. Neither person has to remember what was meant in a conversation for the scoring pass to be understood. Effort and good intentions are not enough. The record has to show how the current ranking was produced, which evidence supports it, and how the company can revisit it when conditions change.
Versioning gives that record a history. A change to criteria or weights needs a reason and a date, so the founder can distinguish an altered judgment from an altered input. The current score is only one view. Without the earlier versions, a team cannot reconstruct why an idea rose or fell, or tell whether a new result prompted a revision to the model.
The artifact also needs to be queryable and separable from its author. A founder should be able to ask which ideas scored highest on AI-citation potential versus search-ranking potential and get an answer they can trace back to the record, with more than another summary to go on. A new team member should be able to use the record without debriefing the consultant. Ownership has a practical meaning here. Possessing a document is not enough if only its creator can explain how to operate it.
The same standard applies to an experiment log. Its success threshold must sit in a written record that predates the result. Agentic pipeline design offers a useful parallel. When a stage produces weak output, a human can open the artifact, correct it, and restart only the downstream work. A scoring document should support the same pattern of opening the logic, correcting the criteria, and rerunning what depends on them.
How a coding-agent workflow makes each of these requirements auditable rather than assumed
A coding-agent workflow can turn these requirements into working parts of the process. Scoring criteria live in a versioned file, experiments live in structured records, and operations are callable through an API. That is marketing treated as engineering. The benefit is that the strategic choice rests on logic and evidence the company can inspect.
For scoring, a configuration file under version control keeps a record of changes with a commit message, a date, and a diff. The diff shows exactly what changed. An agent can read the same file to re-score the ideas when new signals arrive, such as a shift in search performance or AI-citation share. The team does not have to rebuild the criteria from memory. Written weights then become a rule for how the work is done, going beyond a promise to show them in the final presentation.
For the workflow to be open to inspection, it must keep the signals used in the pass, including the buyer prompts tested, and the reasons ideas were cut. Code alone does not guarantee that record. But when those inputs and decisions are kept as artifacts, a founder can examine whether a low score followed from the evidence or from a criterion that deserves challenge.
Structured experiment records make the success test machine-readable. An agent can compare the actual outcome with the pre-filed threshold and flag a pass, a fail, or an inconclusive result. That keeps the comparison separate from later interpretation. The channel-switch log can also be a queryable table, so a founder can ask how many switches took place in the last two quarters and what led to each one.
Human review remains part of this design. A brief is approved before work starts, an outline is checked before the draft is written, and the work is reviewed before it is published. The draft-PR pattern makes the division clear. The agent stages the work, and the human merges it. These gates keep human judgment in the process and spell out when it is needed, rather than leave it to someone to notice weak output.
API and MCP reachability extend that process beyond the meeting. Re-scoring an idea list, logging an experiment result, and triggering a channel-switch review should be callable by an agent rather than dependent on a person attending a weekly conversation. The instrument can work between calls. That separates routine operation from the availability of the person who designed it.
What a human consultant genuinely provides that a coding-agent workflow does not replace
An auditable workflow does not manufacture good judgment. A model can be transparent and still use poor criteria, and an experiment can be well recorded while testing a weak hypothesis. Inspectability makes those weaknesses easier to challenge. It does not supply the experience needed to recognize them or decide what a company should try instead.
An experienced consultant can spot patterns that a dataset from a single company cannot show. Someone who has seen a dozen B2B SaaS companies at Series A may have calibrated intuitions about channel bets that tend to fail early. Those intuitions can guide the first ideas to test, as long as the scoring record shows where judgment comes in and what evidence might change it.
The hundred-idea exercise also has value before scoring begins. A senior outside perspective can generate hypotheses that an internal team, anchored to what it already knows, would not have considered. Breadth can be the real contribution. A workflow can preserve and test those hypotheses, but an orderly ranking cannot compensate for a narrow set of ideas.
Stakeholder navigation is another distinct human contribution. A consultant may be able to explain that a channel is underperforming because sales and marketing are misaligned and be heard where a dashboard flag would not be. A record cannot substitute for that conversation. Afterward, the diagnosis, experiment thresholds, and reasons for changing direction need to remain with the company as operable artifacts. The choice is not consultant or workflow, but whether the engagement leaves a system the team can use.
A short checklist a founder can use on any consultant page or proposal
Before signing, a founder can put these requests into an email. Can the scoring criteria and weights be seen in writing before work starts? Which data inputs will be used, including AI-citation signals and buyer-prompt tests as well as search rankings? Will the rejected ideas be available, with reasons for each cut?
The remaining questions test execution and ownership. Will every experiment have a written success threshold before it runs? What record will explain a channel switch or a decision to stop investing? When the engagement ends, which artifacts will the company own, and can another team member operate them without debriefing the consultant?
The same test applies to a consultant engagement, an AI-generated plan, or a hybrid workflow. The provider’s category does not answer it. The evidence is what the company can open, question, revise, and keep.