ChatGPT Shopping Is a Visibility Problem, Not a Checkout Problem
Getting into ChatGPT Shopping depends on data quality, not checkout optimization.
ChatGPT Shopping is a visibility problem before it is a checkout problem. For technical marketing teams, the competitive question is whether an agent can read a product, trust the evidence around it, and recommend it for a shopper’s needs. A smoother transaction cannot rescue a brand that never enters the shortlist. Structured data, crawlability, catalog consistency, and third-party corroboration are where that contest begins.
How ChatGPT Shopping actually works as a discovery engine
ChatGPT Shopping helps people decide what to buy. Its product carousels provide outbound links to merchant storefronts, where the transaction happens on the brand’s own site. Shoppers can describe a need, refine their constraints, and compare products before leaving ChatGPT. The merchant receives the visit after some of the decision has already happened.
That distinction changes what a brand needs to solve. OpenAI’s help center, updated at the end of October 2026, states, “Product results are selected independently by ChatGPT and are not ads, nor influenced by any OpenAI partnerships”. Appearing in those results is not simply a purchased placement. It depends on the information available to the system and how that information fits the request.
Why the shortlist dynamic changes what invisibility costs
A tenth Google result is still a result. A product that ChatGPT does not name is absent from the shopper’s immediate comparison, with no visible position waiting farther down a search page. Discovery and shortlisting happen before the click. Advertising, retargeting, and people already knowing the brand cannot put a product into that answer if it was left out. This gives non-appearance a different competitive cost from a low search ranking.
The resulting visits also have a different character. A shopper may already have explained constraints and compared alternatives before reaching the storefront, so the referral arrives with more context than a standard non-branded organic visit. The channel remains a small share of overall organic revenue for most stores, but its visitors tend to be warmer and convert at higher rates. Even so, the value of each AI referral may differ. It does explain why traffic volume alone understates the role of the shortlist.
Why prioritize a channel that is still small? The case rests on how visibility can compound. Early appearances can establish citation patterns that third-party coverage and training data reinforce. Brands that wait for the channel to grow may join after those patterns have taken shape.
The two-layer signal architecture that decides which products appear
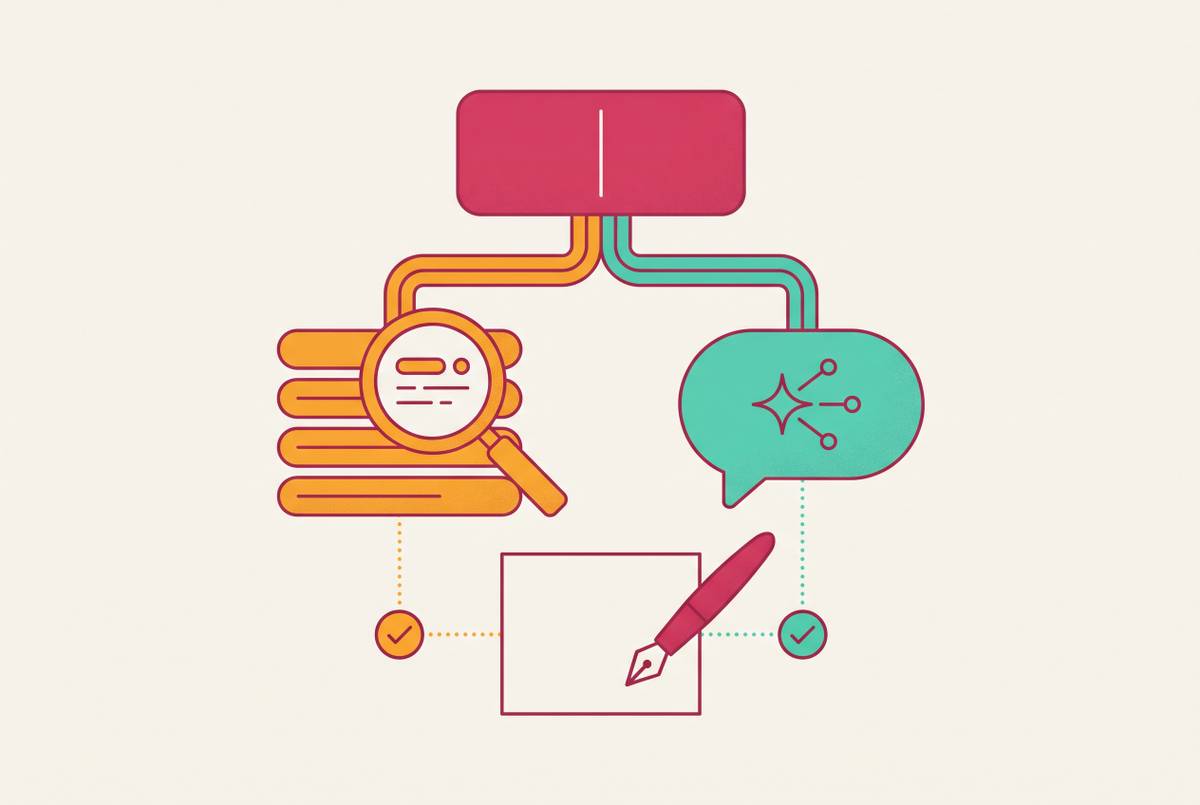
Two signal layers help explain how inclusion works. The feed layer contains structured commercial data, including price, availability, GTIN, and rating, that populates visual carousels. Much of this comes from Google Shopping’s ecosystem. It gives the system a commercial record of the product. It does not, by itself, explain why that product is right for a particular person.
The conversational layer supplies that judgment and framing. It shapes which attributes ChatGPT highlights, how it compares alternatives, and whether it recommends a product for the stated use case. The quality of reviews, third-party editorial coverage, and clear descriptions on product pages all help shape this layer. Priorities also shift with the query, as a budget constraint can give price more weight while another request emphasizes ease of use or design. A product can therefore appear for one intent and disappear for another.
These layers are a useful model. OpenAI’s help center names structured metadata and other third-party content, model responses generated before new search results are considered, and safety standards and product policies. The same help center says merchants are ranked based on availability, price, quality, and whether they are the maker or primary seller. Commercial accuracy and recommendation context work together. Improving one does not automatically repair the other.
Crawlability and structured data as preconditions, not optimizations
For teams acting on this model, access comes first. ChatGPT browses through OAI-SearchBot, so blocking that bot in robots.txt prevents it from reading the page. A strong review profile cannot make a blocked page readable.
Machine-readable structure is the next requirement. Schema.org Product markup gives explicit meaning to fields such as name, brand, price, and availability, with AggregateRating, Offer, GTIN, and MPN where applicable. This removes ambiguity about what the page represents. The markup must agree with the visible content and the Shopping feed, because conflicting prices or stock information undermine the reliability of the record. A valid schema implementation is not enough if it describes something different from the landing page.
The implementation burden depends on the storefront. Shopify stores connecting through Google Merchant Center inherit much of this work automatically, while custom or headless storefronts need explicit feed and schema implementation. That makes legibility an engineering responsibility as well as a marketing concern. A team in that position should first make sure the agent can reach the pages, the markup is in place, and the feed agrees with the pages, before expecting better copy to help products get found.
Catalog consistency as an invisibility driver brands systematically underestimate
A readable page can still describe an ambiguous product. When names and attributes conflict across sources, the agent has to resolve whether those records refer to the same thing. This is entity fragmentation. It can exclude a product before ranking begins. The system may never have reached a confident understanding of the candidate.
Consider “Ultra Pro Wireless Earbuds” on a brand’s site and “UltraPro BT Earphones” on third-party retail platforms. A person might treat the difference as harmless shorthand. Across a catalog, however, inconsistent names, identifiers, prices, and availability create classification ambiguity that can reduce the model’s confidence enough to exclude the product. Internally, this looks like untidy data. Externally, it appears as silence, with no explanation that the brand was filtered out.
Being present on Google Shopping does not settle the question. Its tolerance for minor inconsistencies is higher than ChatGPT’s, where understanding must be assembled across sources. The recommended response is entity discipline, with canonical names, consistent GTINs and MPNs, and agreement from feed to page to retailer. This belongs in the publishing standard. A one-time cleanup cannot keep new products and later changes coherent.
Why third-party corroboration outweighs on-site optimization for the conversational layer
Product recommendations rely more on independent editorial roundups, buyer guides, forum discussions, and review platforms than on brand-owned pages. Those sources help establish how a product performs and where it fits. The site can state a claim clearly. Independent coverage gives the conversational layer a basis for evaluating it against alternatives.
This explains why search success is not a reliable proxy for AI citation. Many AI-cited pages do not rank in the organic top ten, while a high search ranking does not automatically earn a place in an answer. The two forms of visibility overlap without being interchangeable. Working only to raise the rankings of a brand’s own pages can leave the system with little evidence to recommend its products. The gap is not necessarily another missing keyword.
Digital PR, review presence on Trustpilot, Google, and niche category sites, Reddit community participation, and publisher relationships belong within AI-visibility work. Owned content defines the entity and gives others accurate material to cite, while earned coverage supplies much of the corroboration. The work must also span platforms, because citation strength on one assistant does not guarantee recognition on another.
The protocol layer — ACP and UCP as infrastructure decisions, not features
OpenAI’s Agentic Commerce Protocol, or ACP, and Google’s Universal Commerce Protocol, or UCP, are competing open standards for AI-native commerce. ACP supports conversational product discovery and multiple delivery paths, including providers such as Salesforce and Stripe. OpenAI intends it to support broader experiences involving personalization, local availability, and ETAs. This is infrastructure.
Google and Shopify announced UCP on January 11, 2026, at NRF, with a launch on Google Search AI Mode and Gemini. Its high-intent search context differs from ACP’s conversational discovery context. For many brands, supporting both is therefore a strategic priority. Catalog delivery, completeness, and freshness belong in an engineering discussion that serves multiple discovery surfaces. Marketing’s need for inclusion supplies the reason for that work.
OpenAI’s documentation states that “no additional work is required from individual merchants” for Shopify merchants whose catalogs are already integrated through Shopify Catalog to appear in organic results. That qualification is important. ACP integration can improve catalog completeness and freshness, but it is not a universal gate to organic recommendation. Smaller brands should address legibility and consistency without waiting for a full protocol implementation.
What content strategy looks like when agents read the whole site, not one page
Content has to support the same coherent product picture. AI answer engines synthesize across a site and across external sources. A product page, buying guide, and comparison page therefore contribute to the same understanding of the brand. Conflicting positioning weakens that understanding even when each page reads well alone. The unit of coherence is larger than a page.
Most product pages explain what an item is. The missing step is often when it becomes the right choice, and when it does not. Content teams should connect features to use cases and decision criteria, stating who the product is for and who it is not for. Answer-first buying guides and honest comparisons with category leaders help meet this need because shoppers ask what will work in their situation.
ChatGPT’s abstraction bias toward high-level desirability can favor premium or high-performance products over practical feasibility. Budget-positioned products need both a lower price in the feed and content that clearly explains the use cases in which they are a good fit. This gives the agent reasons to recommend them while making clear that they suit some shoppers better than others.
New products, revised specifications, and changing competitive positions need to propagate through owned content, feeds, and third-party citations. A one-time audit cannot perform that continuing work. PR, content, SEO, and product marketing consequently share a coordination problem. Each team contributes evidence that the agent may combine into one recommendation.
Measuring AI shopping visibility rather than assuming it
Direct measurement is the test of that coordination. Google rankings and organic traffic cannot establish whether ChatGPT recommends a product for the prompts that influence its buyers. Teams should regularly run priority shopping prompts through ChatGPT, Perplexity, and Google AI surfaces, recording the products and brands named. The same record should include which competitors appear and which third-party sources the answer cites. That connects the outcome to the evidence used in the answer.
Why did the assistant recommend that competitor for that request? Citation analysis can show that a recommendation draws on a particular review publication, which may be a publisher to build a relationship with. It also helps distinguish a missing mention from a missing source of corroboration.
The cadence should be monthly at minimum, across platforms. Quarterly reviews can miss changes in citation patterns before they compound, while one-platform tracking can create a false picture of overall visibility. Category-level monitoring can help connect prompts, products, competitors, and cited sources. The resulting work starts upstream of checkout, with the evidence needed for a shopper to reach the store.