Why "Optimize Your Content for LLMs" Is the Wrong Frame
Visibility in AI answers depends on retrieval and authority, not just page formatting.
“Optimize your content for LLMs” treats AI visibility as a property a team can build into a page. But clear structure is only one input to a selection process that also depends on retrieval, authority, entity recognition, and timing. Winning citations requires an instrumented system that measures those dependencies.
Why the "optimize for LLMs" frame starts at the wrong layer
A content team finishes the checklist. The headers are clear, citations sit beside claims, and schema markup and structured data are in place. The pages are easier to read and interpret, so the team expects them to appear in AI answers. Yet citations may not follow. The gap is not necessarily in the quality of the work, but in what that work can influence.
The foundational 2024 GEO paper established a real but narrower result than the checklist suggests. Presentation changes to an already-retrieved document could increase its share of a generated answer. That condition is the hinge of the finding. The experiment concerned documents already inside a fixed retrieval context.
The broader checklist frame drops that distinction. It turns evidence about how a selected source gets used into a promise about how a source gets selected. Those are different problems, with different dependencies. A team can therefore improve presentation while leaving the obstacle to visibility untouched, because the page never reaches the stage where its improved presentation can help.
How a generative engine actually selects a source, gate by gate
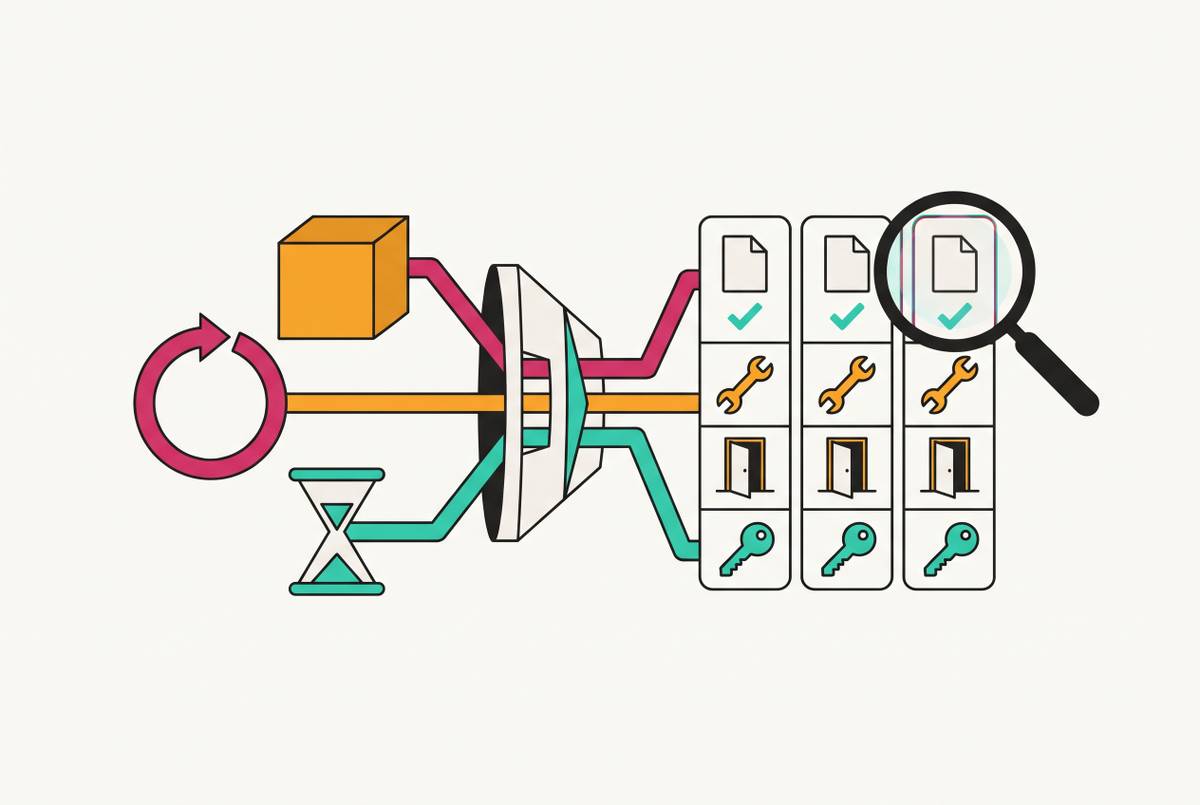
The first gate is crawlability and indexing. A page outside the engine’s index cannot be retrieved through that index, regardless of how neatly its information is arranged. This is a prerequisite. An accurate, well-structured page can fail here without giving its content team any visible explanation.
The second gate is retrieval for a specific query. Olivier Martinez’s Optimizing Visibility in Generative Engines: A Critical Survey of Generative Engine Optimization identifies topical relevance and context position as the most reproducible levers, while finding that generic formatting rules transfer poorly across queries and engines. Relevance is specific to the question being asked. A page being available does not mean it will be selected for the question a prospective reader actually poses.
The third gate is reranking and context allocation, where retrieved documents compete for space and attention. The survey finds that competition can erode individual gains and that citation-oriented rewrites can impair retrieval. A change can help one gate and hurt another. Once candidates survive that competition, the fourth gate is citation and trust, where the model synthesizes an answer and decides which sources to name.
The checklist chiefly addresses presentation at those later gates. It offers no mechanism for getting an absent page indexed or making a document relevant to a particular query. That is why a missing citation cannot, by itself, diagnose a formatting problem. The source may have been ruled out before its presentation played a part.
Why entity recognition is a harder problem than page formatting
The sequence also depends on something less visible than the page. A model needs to identify a brand as a named entity, and insufficient third-party presence in its training corpus can leave that identity effectively invisible. Page structure cannot supply the missing recognition on its own. The assets at issue include both the document and the model’s ability to place its publisher within a wider body of knowledge.
This distinction follows from the two knowledge systems LLMs draw on. Parametric memory is what a model learned during training, while live retrieval brings documents into the answer it is giving now. A large share of brand mentions comes from parametric memory. No change to an owned page’s headings can directly rewrite what a model absorbed during training.
Most AI engines tend to choose third-party sources over brand pages that promote themselves, though how much they favor them varies a lot by engine and query type. An authoritative external mention can therefore be more useful for citation than a polished marketing page. The relevant presence extends across documentation, blog articles, forum threads, review sites, structured knowledge graphs, and technical papers.
What, then, is being optimized? If all the work stays on owned pages, the team is improving one surface while leaving corpus-wide identity largely untouched. Being easy to parse and being recognizable as a trusted entity are separate achievements.
Citation volatility means a one-time formatting win decays before it compounds
Even a source that clears every gate has not secured a lasting position. The survey documents substantial run-to-run variability and low overlap among sources cited in repeated queries. Most sources churn between sessions, while only a small fraction persist. The same prompt can therefore produce a different set of citations without any corresponding change to the page being measured.
Did the edit improve visibility, or did the team just get a run that went its way? A checklist judged against one snapshot cannot answer that question, and its apparent win can decay in days. Repeated measurement is needed to separate a change in performance from noise.
There is also a distinction between appearing and being represented accurately. The survey identifies persistent fidelity gaps, including claims attributed to pages that do not adequately support them. A citation count does not capture that difference.
The strategic response is therefore not simply to update pages more often. It is to detect when visibility changes, examine whether the answer remains faithful to the source, and respond on that basis. Without that feedback, a team cannot tell whether its next formatting change responds to a real drop or to the usual ups and downs.
What citation farming reveals about where the checklist frame leads at scale
Citation farming applies the checklist’s logic to more than one page. It manufactures apparent third-party consensus from a single source disguised as many, turning the appearance of independent support into something that can be produced. Citation farming substitutes repeated, coordinated signals for genuinely independent evidence.
If those cues can be amplified without adding authority, engines need ways to distinguish useful evidence from attempts to steer their answers. Haozhang Li and colleagues’ When Optimization Becomes Manipulation: Defending Generative Search against Malicious Generative Engine Optimization addresses that problem. Its proposed GEO Defender combines Shield Reranker with Training-Free Shield Generation to detect and demote manipulative documents while preserving genuine evidence.
The defense research reports that it cut the share of attacks that succeeded from roughly half to a small fraction. But it also identifies a difficult overlap. The features amplified by attacks can characterize high-quality, benign content, and manipulated documents can remain factually consistent with their originals. Fact checking alone cannot resolve that distinction.
Amplifying surface features is an unstable strategy when defenses are learning to scrutinize those same features. Good-faith teams can move toward signals that filters target. More checklist work keeps teams in that arms race, while building genuine authority gives them what the checklist only tries to look like.
What the academic literature actually established — and what it left unresolved
The strongest finding in the 2023–2026 GEO research corpus deserves to stand. Already-retrieved content can causally influence its share of a generated answer, and that effect is reproducible. Presentation is not irrelevant, and rejecting all GEO tactics would misread the evidence just as badly as promising that they solve discovery.
The foundational paper gives teams reason to use inline authoritative citations, which can help lower-ranked sites get more citations. This is a substantive improvement rather than decoration, because it places supporting evidence beside the claim. But getting more citations inside a retrieval context does not prove that a gain in organic discoverability will last. The boundary of the experiment still applies.
The survey finds no reviewed technique with a stable, longitudinal, cross-platform causal effect on organic discoverability or downstream behavior. Several central questions remain open. Do formatting gains compound over time, do they transfer across engines, and do additional citations produce clicks or conversions? Resolving those scientific questions requires evidence beyond citation counts.
A 2026 ICML position paper also identifies governance risks from uncritical GEO adoption. It points to concentrated influence from low contestability and system sensitivity, as well as undisclosed commercial influence embedded in apparently neutral evidence and reasoning. A field that measures success only by increased presence can miss both inaccurate representation and the commercial steering of answers that readers expect to be neutral.
Treating AI visibility as an instrumented system rather than a formatting state
The constructive alternative starts with a different target. A team should build a verifiable, consistent entity presence across the sources models draw from, then measure how that presence affects answers. That includes training data, third-party publications, structured knowledge graphs, and live retrieval. The aim is not to make many pages look authoritative, but to make genuine evidence available across the corpus.
Documentation, technical papers, forum threads, review sites, structured data files, and third-party publications each belong to the source environment from which engines construct category answers. What appears in those sources needs to be consistent and backed by evidence. Otherwise, expansion risks reproducing citation farming and failing to establish genuine authority.
Measurement must then be a vector. The survey argues for observations across multiple engines, prompts, and time periods, with fidelity measures and null outcomes retained. ChatGPT, Claude, Gemini, and Perplexity need separate measurement because their source preferences, variability, and judgments of authority differ. An absent citation is part of the evidence, and engine-level differences help narrow where the system is failing.
To respond at that pace, teams need standing watchers that run queries on a cadence and surface relevant changes and decay. Multi-stage pipelines can draft responses when changes appear, while people who review them keep control over what ships. The system also brings evidence in time to act, and people judge each draft for accuracy, whether it helps, and whether to publish it.
What content teams should actually own in this system
Content teams own the quality and retrievability of the evidence layer. Their work covers what gets published, whether it is accurate, and how it is structured, and that work is still needed even when it cannot guarantee a citation. The distinction concerns the scope of content teams’ responsibility. Technical infrastructure, third-party authority, knowledge-graph presence, and ongoing measurement also shape the outcome, so accountability cannot stop at the editor’s desk.
For teams working within that broader system, the practical demand is visibility into its performance. They need a measurement layer showing which prompts, engines, and source types produce citations, a publication cadence that can respond to volatility, and a third-party seeding strategy that builds genuine corpus presence. Those capabilities make editorial decisions more informed. They also make it possible to distinguish a weak piece of evidence from a failure elsewhere in the selection process.
One-time audits, schema checklists applied to existing pages, and citation counts from a single engine at a single moment are not sufficient. They can supply inputs, but they cannot show durable performance or downstream value. As generative answers become a front door to discovery, what gets cited helps determine what gets considered. That makes visibility a revenue question whose effects need measurement, rather than a content operations score inferred from mentions.
The discipline this calls for is engineering. Content teams provide the evidence, and the rest of the organization provides the infrastructure, work to build authority, and feedback needed to learn from results. The governing principle is to instrument the system, measure it, and change it on evidence. Formatting belongs inside that discipline.
Sources
- Optimizing Visibility in Generative Engines: A Critical Survey of Generative Engine Optimization (2023-2026)
- When Optimization Becomes Manipulation: Defending Generative Search against Malicious Generative Engine Optimization
- Position: Generative Engine Optimization Creates Underexamined Risks, Governance Must Target Concentration, Disclosure, and Academic Blind Spots