Reranking Models and Their Effect on RAG Answer Faithfulness
Relevance scores alone can't tell you if answers are grounded.
Reranking models affect RAG answer faithfulness by deciding which evidence reaches the generator. But better relevance scores do not necessarily produce better-grounded answers. The crucial distinction is between passages that match a question and passages that support a correct answer. Utility-driven reranking works to close that gap, and measuring ranking quality, accuracy, and faithfulness on their own shows whether it helps.
Why RAG does not eliminate hallucinations, and where reranking enters
RAG was introduced to reduce hallucinations by grounding generation in external evidence, yet access to evidence does not guarantee its use. A retriever returns candidates, and the generator receives the passages that survive selection. If those passages are only loosely related to the question, the model can fill the gaps from parametric memory. The claims it makes may sound right but have no support.
The correct evidence may already be available. A ranking error can keep the right chunk out of the selected context, and near-duplicate passages can make it hard to tell which policy clause applies. Even when the subject is right, a generator may quote the wrong section. The Faith-Rank paper finds a related weakness in how answers are assessed: confidence often reflects model uncertainty but gives too little weight to support in the retrieved evidence. These failures create a place for intervention between retrieving candidates and generating an answer. That intervention is reranking.
What a reranker actually does in a retrieval pipeline
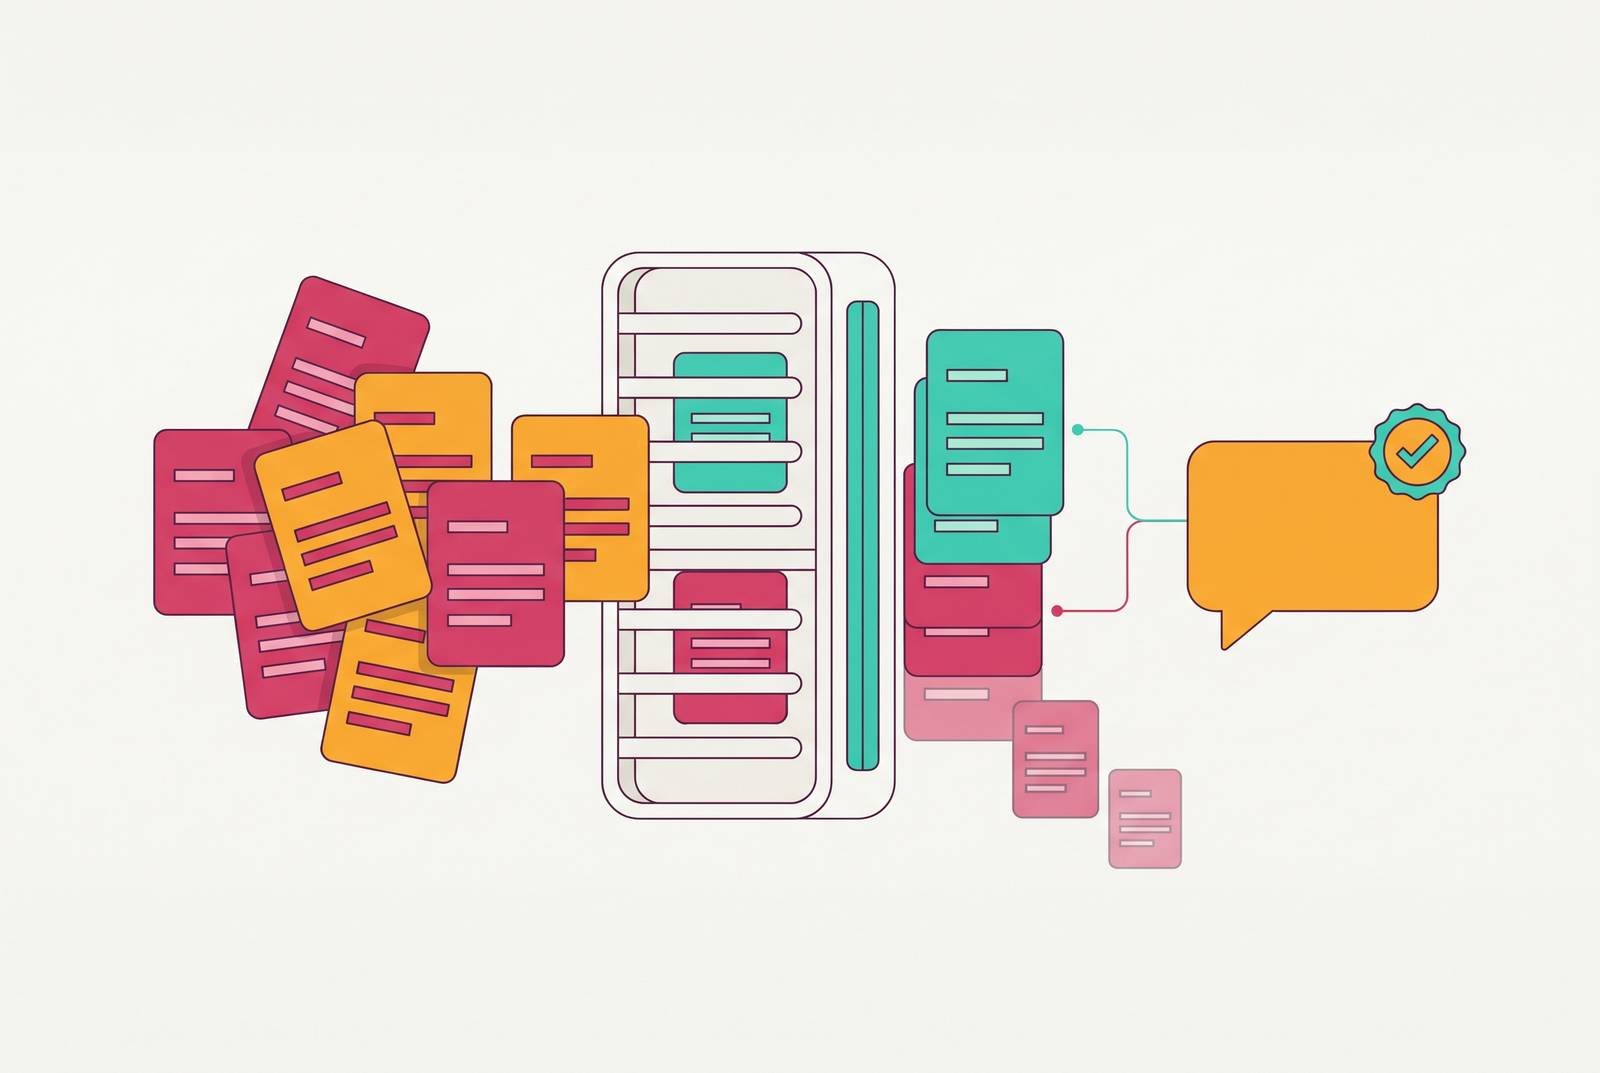
A reranker is a second-pass scoring model that reorders the top-k passages returned by a first-stage retriever. In the standard retrieve-then-rerank architecture, cheap vector search fetches a large candidate set with high recall but weaker top-1 precision. A more expensive cross-encoder then scores those candidates to select a small final set for generation. The two stages divide the computational work.
The cross-encoder’s precision comes from how it processes text. A bi-encoder encodes the query and document independently, then compares their representations with a dot product. A cross-encoder instead takes the query and candidate passage as a joint input, attending across both token sequences to produce a single relevance score. That joint view exposes query-specific signals that independent encoding can miss. The resulting scores determine the new passage order before the context reaches the generator.
The objective that standard rerankers optimize, and why it is the wrong one for faithfulness
The Faith-Rank paper identifies query–passage relevance as the dominant objective of existing reranking methods. Utility means a passage’s contribution to producing an answer that is both correct and faithful to the supplied evidence. These objectives ask different questions of the ranker. Relevance asks whether a passage matches the query, while utility asks whether it helps ground the answer. A passage on the right topic can pass the first test and fail the second.
Consider the effect of selecting several near-duplicate passages. Each may score well against the query, but together they take up context space without adding the evidence that is missing. Partially matching passages can also introduce conflicting or tangential information. More relevant text is not always better evidence. If the selected passages do not ground the required claims, the generator can still produce a confident response that cannot be traced to any retrieved source.
But relevance and faithfulness are correlated, so why is relevance not good enough? Because the cases where they diverge are precisely the cases that leave room for unsupported claims. VERITAS, published in Transactions on Machine Learning Research in 2026, shows that optimizing final-answer correctness does not automatically produce faithful intermediate reasoning. The Johns Hopkins ICTIR '26 study likewise finds that the relationship between retrieval metrics and generation quality weakens as pipelines become more iterative and complex. Neither finding makes relevance useless, but both limit what a relevance gain can establish about the answer.
How faithfulness is measured, and why the measurement choice shapes the architecture
One way to measure faithfulness is to have an LLM identify the factual claims in a response and determine which are supported by the retrieved context. The score is the fraction of context-supported claims. By contrast, Mean Reciprocal Rank measures whether the right document appears near the top of a ranked list. A passage can improve that ranking metric without improving faithfulness if the generator does not use it as its factual anchor.
VERITAS separates faithfulness into three dimensions for agentic search. Think-Search faithfulness asks whether search queries are justified by the agent’s reasoning. Information-Think faithfulness asks whether reasoning steps reflect the retrieved information, while Think-Answer faithfulness asks whether the final answer is grounded in that reasoning. An assessment confined to the final response cannot express all the distinctions captured by those three measures.
An EACL 2026 paper notes that traditional ranking metrics, including MRR and NDCG, do not accurately model how generators consume context. Retrieval gains therefore need to be compared with groundedness, completeness, and final answer quality. This changes what success means for the architecture. A rise in Recall at a given cutoff can coexist with a fall in faithfulness, because evidence selection and evidence use are different events. When those outcomes are measured on their own, ranking position alone is no longer enough as a training target for faithful generation.
How Faith-Rank reformulates reranking as a utility-driven task
Faith-Rank reformulates evidence reranking as a utility-driven task, ranking passages by their contribution to answers that are both correct and faithful to the provided evidence. The framework uses a Siamese utility ranker trained with a hybrid objective that brings together margin-based ranking and binary classification. Those components serve two related but distinct purposes. The ranking objective enables fine-grained evidence ordering, while classification supports stable score calibration.
The framework also addresses reliability after evidence selection. Its joint reliability modeling module combines evidence-grounded faithfulness with generation uncertainty to assess answers. This responds to the weakness of estimating confidence from uncertainty alone. A model’s confidence and an answer’s evidential support are not interchangeable signals, so the assessment includes both.
Faith-Rank reports roughly 20% average improvement in Top-1 evidence accuracy over BM25, together with more trustworthy RAG outputs across multiple open-domain QA benchmarks. The gains extend across different retrievers and LLM backbones. That breadth is especially useful for deployment decisions. It supports the robustness of the utility-ranking objective beyond a single model configuration, rather than establishing only a narrowly tuned result. For practitioners who cannot retrain for every deployment, the cross-backbone evidence is an important part of the framework’s case.
The faithfulness–accuracy tension that utility ranking does not automatically resolve
Does a more faithful answer necessarily perform better on the task? Correctness concerns the answer’s result, while faithfulness concerns its support in the evidence and, in agentic search, the links through its reasoning. An improvement on one dimension cannot establish an improvement on the other. Utility ranking aims to serve both, but its objective does not remove the need to measure each.
VERITAS finds substantial room for improvement in faithfulness for models trained with canonical RLVR, including Search-R1 and ReSearch, despite their competitive task performance. The same paper reports that DESA performs competitively on NQ and HotpotQA but underperforms those models in almost all faithfulness dimensions. Task success can therefore conceal weak evidence use. This is not simply a disagreement between two scoring systems, because each captures a different property of the response.
The same tension appears upstream of generation. In evaluation cases, recall rises after reranking even as answer quality falls below the retrieval-only baseline. The Johns Hopkins study adds an important boundary, finding a strong relationship between retrieval coverage and generation information coverage in simpler linear pipelines, but a weaker relationship in iterative and complex ones. Retrieval improvements transfer less cleanly as the pipeline grows more involved. The resolution is not to abandon utility reranking, but to measure ranking quality, correctness, and faithfulness separately.
What evaluation discipline looks like in production RAG systems
For a production team, that distinction calls for separate signals measured against the same corpus. The first check is ranking quality, asking whether the top-1 result after reranking is actually the best passage in the candidate set. The next check is context relevance, which asks whether the selected context matches the query’s intent. These checks find problems before generation takes place. They also distinguish poor ordering from a context set that fails to address the question.
The next check follows the evidence downstream. Chunk attribution asks whether the generator used the retrieved material it received. The end-to-end faithfulness ratio then measures context-supported claims as a fraction of all factual claims in the response. Together, these checks separate selection from use and use from support.
The Johns Hopkins study finds them reliable proxies for generated information coverage when retrieval and generation objectives are aligned, particularly in simpler pipelines. Complex or iterative systems cannot rely on that relationship in the same way. The recommended production default is hybrid retrieval over a larger candidate set, followed by a utility-aware reranker that selects a small final context. Ranking quality and groundedness should function as release gates as well as findings from a later audit.
Human review remains necessary for consequential claims. Retrieval can be incomplete, a model can misinterpret its sources, and no automated faithfulness metric catches every failure. Strong scores therefore do not remove the need for citations and explicit handling of uncertainty in high-stakes content. Those requirements keep the evaluation tied to the claims people will actually use. Human review is the final grounding check.
What the retrieval-to-faithfulness gap means for systems that generate content at scale
The same gap extends beyond conversational search. Product documentation, research summaries, and published articles face the same gap when RAG supplies the evidence for generated content. In AI answer engines, a ranking step helps decide which passages a cited response is based on. Faithfulness therefore depends on both the ranking objective and the generator’s capability. Scaling content production does not change that dependency.
For publishers, this makes passage utility a content concern as well as a retrieval concern. A passage can be topically on-point yet lack the specific claims, evidence, or attributable sources needed to support an answer. Such a passage may perform well on relevance and poorly on utility. The practical direction is to publish grounded material with specific claims, named sources, and verifiable evidence, so that selection can lead to support.
Citation share tracks whether content appears in answers, while citation accuracy asks whether the way it is used is faithful to the source. Neither establishes the other. A 2026 study of brand visibility across AI answer sessions found that only 30% of brands maintained consistent visibility from one session to the next. That finding concerns the stability of appearance, with citation accuracy still requiring its own assessment.
The shared objective is evidence that can support an answer. A content pipeline and a utility-driven RAG system approach that objective from opposite ends, one by publishing usable source material and the other by selecting it. Their success meets at the generated claim. Being retrieved is only the opportunity to become evidence, and being cited is not proof that the evidence was used faithfully.