The Reasonable Surfer Model Is a Signal Graph, Not a Style Guide
Google's ranking model learns link weights from user behavior, not formatting rules.
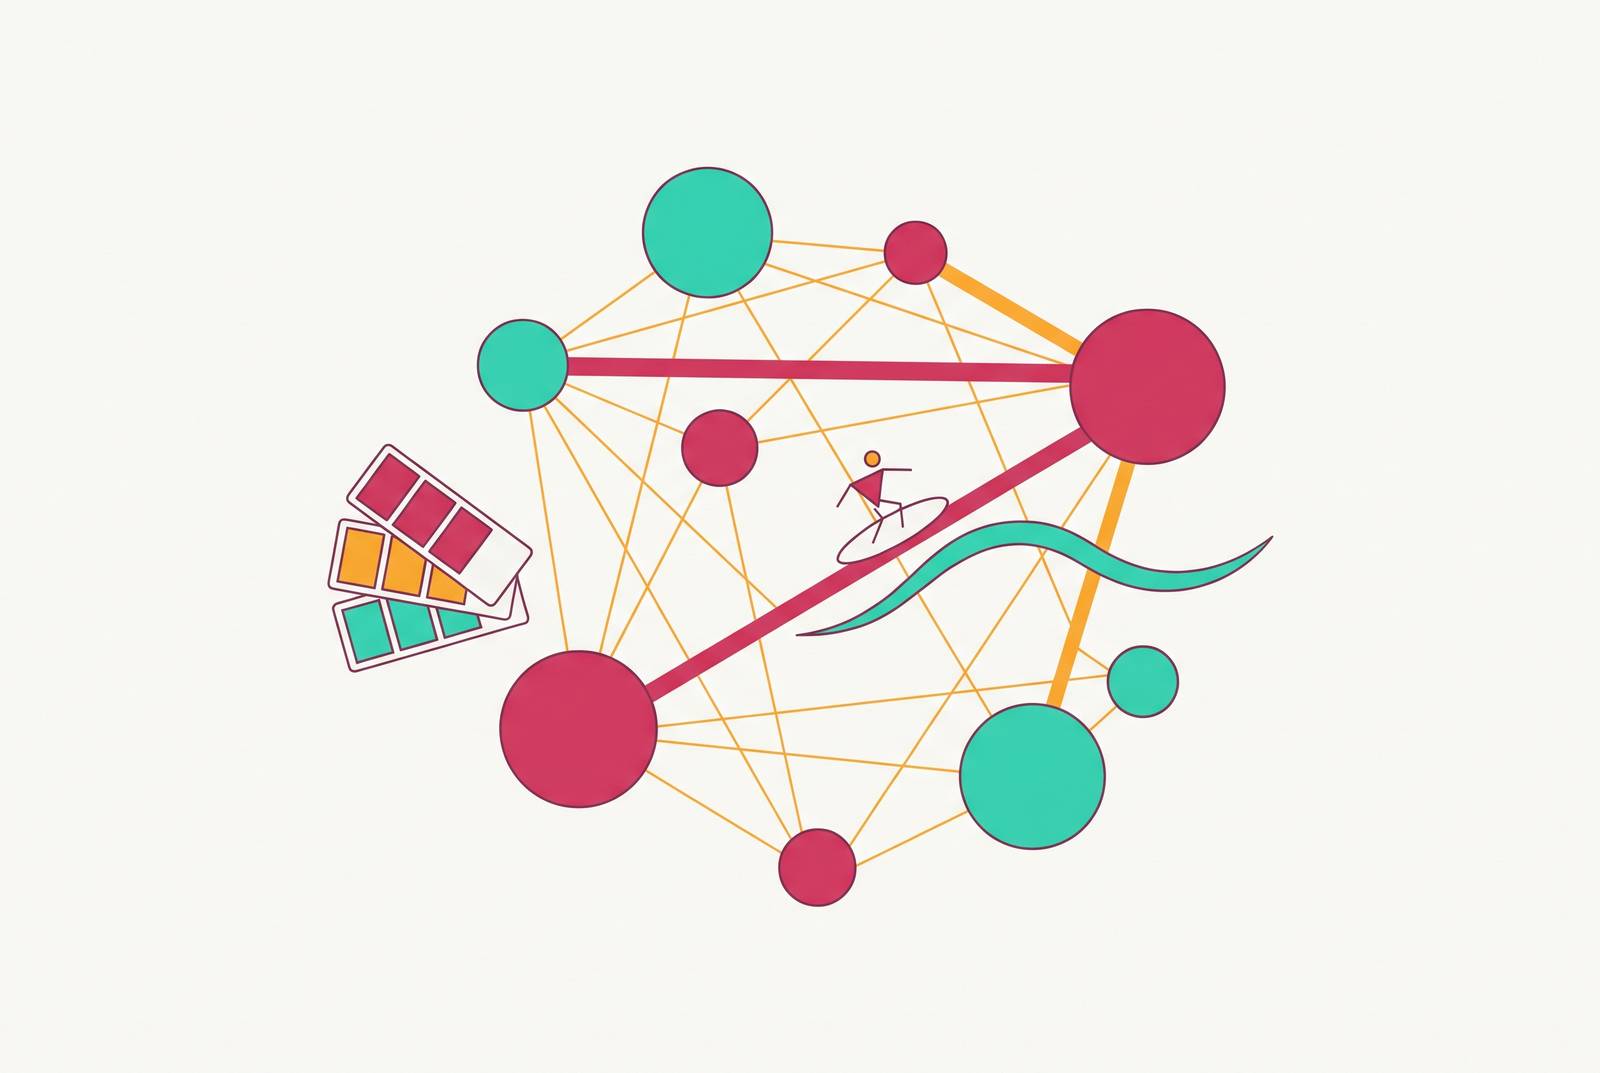
Google’s Reasonable Surfer Model is a signal graph. It describes how link features and user behavior can determine the probability of following each link. For founders and developers, the useful question is therefore not whether a link looks well placed, but how its learned weight interacts with the authority and connections of the pages around it.
What the Reasonable Surfer patent actually encodes
The Reasonable Surfer patent, US7716225B1, moves away from the Random Surfer assumption that every outgoing link has the same probability of being followed. Its stated premise is that “when a surfer accesses a document with a set of links, the surfer will follow some of the links with higher probability than others”. Each link gets its own probability. Terms of Service links, banner advertisements, and links unrelated to the document are examples of links unlikely to be followed.
The patent generates its model from feature data and user behavior data about navigational actions associated with links. Its link-level features include anchor font size, color and styling, document position, list position, anchor word count, the words themselves, and how commercial they are. It also includes surrounding context words, the anchor’s topical cluster, whether the link goes on-domain or off, and whether it is text or an image. For image links, the model also uses aspect ratio. Position includes above or below the fold, footers, sidebars, and lists.
The inputs also extend beyond the link itself. Source-document features include URL and site identity, total link count, other words, heading words, topical cluster, and the match between the source’s cluster and the anchor’s cluster. Target-document features include URL and site identity, whether the target shares the host or domain, and the words and length of its URL. The model uses these features with behavior data to assign document ranks.
Why the patent's input variables describe a weighted directed graph, not a checklist
Those inputs describe how documents relate to each other, without acting as separate tests that a link passes or fails. Documents are nodes, and links are directed edges from source to target. Each edge has a learned weight that stands for the link’s click probability. Some inputs are numerical and others categorical, but their joint output is a scalar weight. In this representation, PageRank flows along outgoing edges in proportion to their weights.
Consider two links in the same position on pages that are otherwise different. One has anchor text and surrounding words that closely match its source page’s topic, while the other points toward an unrelated subject. Their placement is the same, but their inputs differ. A model that evaluates those inputs together need not assign the same probability to both links. A visual audit would miss that distinction.
Could a relevant footer link outweigh an irrelevant above-fold link? The model allows this, though the feature list alone cannot show what would happen for a given pair. DOM position helps set the weight but cannot set it on its own. Moving a link upward changes one input while leaving its anchor, context, and topical relationships largely untouched. That can be a useful adjustment, but it is not a complete account of the edge’s value.
How the Seed Distance patent adds a second graph layer that modulates what Reasonable Surfer weights are worth
A link’s probability of being followed does not establish how much authority its source has available to pass. Seed Distance PageRank, US9953049B1, uses distance from trusted seeds to account for how much authority the source has. Invented by Nissan Hajaj, it was filed in 2015 with a priority date of 2006 and granted in 2018. The patent describes human-curated seed sites and names Google Directory and The New York Times as examples.
The patent assigns links lengths based on the source page’s outdegree, meaning its number of outgoing links. The more outgoing links a page has, the longer each link’s length. The system then computes shortest paths from the k nearest seeds, with k = 3–6 described in the patent. Scores decay exponentially with distance, while pages unreachable from any seed receive no score through this process.
The 2024 Google API leak documentation names PagerankNS, or Pagerank-NearestSeeds, and describes it as “the production PageRank value teams should use”. That is evidence consistent with a nearest-seeds design. It does not show that the exact patented formula runs in production today or how it works with Reasonable Surfer. As a combined model, however, the two dimensions are useful. An equally weighted edge from a seed-distant page would pass less absolute equity than one from a seed-proximate page, because the source authority being apportioned differs.
What the patent's update history reveals about the model's learning mechanism
The Reasonable Surfer continuation, US8117209B1, keeps the relationship between features and navigational behavior central to the model. The abstract specifies that user behavior data helps generate the model, rather than merely supplying a final check on a hand-written placement rule. Learning is part of the mechanism being described. The continuation’s existence does not, by itself, reveal a production update schedule or the values assigned to particular features.
The patent describes behavior data from visitors’ actions on pages and from a web browser or browser toolbar. These observations provide the basis for learning how features relate to navigation. What happens when aggregate behavior changes? A learned weight function can change with it, so a formatting rule inferred at one point need not remain a reliable approximation. The patent provides input classes.
Navboost offers brief corroborating context because it uses aggregated click data to re-rank results. That does not make it the same system or establish that it shares Reasonable Surfer’s weights. Clicks can document outcomes and feed learning. For developers, the implication is to treat edge weights as learned parameters whose inputs are partly known.
Why the nofollow-sculpting era proves that treating the model as a style guide produces predictable failures
The nofollow-sculpting era illustrates what goes wrong when a graph is reduced to a local control lever. The tactic assumed that practitioners could change link eligibility to send more equity to the destinations they preferred. That reasoning depended on assumptions about the graph’s redistribution rules. Google changed how nofollow links were processed at the graph level, leaving the intended redistribution unrewarded. The intervention’s meaning depended on the system processing it.
This was a failure of the mental model. A local markup change cannot establish the behavior of the wider ranking function. The same holds for advice to move links up, make anchor text larger, or avoid footers. Each changes an input without explaining its interaction with the other inputs. The error is assuming that a visible adjustment has a predictable effect on total flow.
The reverse mismatch is also possible. A genuine editorial endorsement in a blogroll may get few clicks and thus carry less weight than its author intended. Click probability and editorial intent are different quantities. This exposes a limit of the model itself. A careful interpretation must distinguish what the system estimates from what a human endorsement means.
How to model Reasonable Surfer correctly as an engineer — a weighted graph with learned edge weights
The engineering alternative is to represent pages as nodes and links as directed edges with estimated, learned weights. Those estimates are rough values for the probabilities that the documented feature classes could produce. They are not recovered Google parameters. An illustrative edge-weight function would depend on position, topical match, anchor features, surrounding context, styling, source outdegree, and target URL characteristics. It keeps the variables and how they work together in view without claiming to give a formula for an unknown function.
For a developer applying that model, topical coherence deserves particular attention. Source-to-anchor cluster match is a feature named in the patent, while source-to-target coherence helps model a broader relationship for which the patent gives no coefficient. Both help distinguish substantive relevance from a formatting change. Source link count also belongs in the model because outgoing edges share the available flow. In the seed-distance layer, outdegree separately affects link length, so the two roles should not be collapsed into one assumed penalty.
To reason about absolute equity, the model should combine an edge’s estimated weight with a proxy for source-node authority. This makes structural questions possible. Does a page have many inbound edges but few strong paths onward to priority targets, making it an equity sink? Is a priority page connected to seed-proximate nodes through strong edges, or reachable only through long, weak chains? A formatting intervention can then be judged against those relationships, with its estimated effect kept separate from any claim about Google’s actual weights.
What the graph model means for content structure decisions, not just link audits
Once links are modeled as edges, creating a page becomes a decision about graph topology. A new document has a topic, outgoing connections, and a position relative to other nodes. Those relationships begin before publication. A content hub built around a coherent topical cluster can make the source-to-anchor matches across its internal links stronger. Related pages and anchors change the inputs evaluated together.
That gives content authors a direct role in shaping edge features. The patent includes anchor words, their commercial character, and context before and after the link. Placing an editorial link within running prose can change several inputs together, including position, surrounding words, and the relationship between anchor and topic. The value of “body text” comes from the particular combination of features.
Link format belongs in the same reasoning. The patent distinguishes text from image links and includes image aspect ratio, so format is more than an aesthetic choice within the model. It gives no rule that makes every image link weaker. For teams writing content briefs, the practical implication is to specify target documents, candidate anchor text, and topical coherence as well as keywords and headings. Those choices establish outbound edge features before anyone conducts a retrospective link audit.
Where measuring AI citation visibility intersects with the same graph logic
AI citation visibility presents a related selection problem, but not an identical graph. Reasonable Surfer concerns the weighting of hyperlinks between documents. AI answer engines select sources from training and retrieval material, with co-occurrence, entity recognition, retrieval relevance, and cross-source consistency offering a different way to describe their relationships. The analogy concerns weighted evidence and selection. It does not mean that AI engines run Reasonable Surfer or convert hyperlink equity directly into citations.
Google’s US11769017B1, “Generative summaries for search results”, and US11836177B2, “Providing knowledge panels with search results”, describe retrieval and synthesis systems beyond ordinary link ranking. Assuming that generated answers inherit organic rankings does not explain how these systems work. A brand’s position in the hyperlink graph therefore does not settle whether it will appear in an answer. Citation visibility needs its own measurement. Otherwise, an assumption about one system stands in for an observation of another.
Teams measuring AI visibility should enumerate the relevant inputs, model how sources are selected for generated answers, and measure outputs through fixed prompts run across engines on a schedule. Mentions and citations should be recorded separately, with citation rate treated as a signal measured independently of search performance. This preserves the distinction between a model of how selection might work and evidence of what it produced.