What a "HubSpot marketing automation for B2B startups" comparison leaves out: per-seat pricing, contact caps and the workflow paywall vs. composable, agent-callable primitives
Feature checklists hide how costs scale and who owns your logic.
A marketing automation comparison is only useful if it shows what happens after a startup outgrows the entry tier. For a technical B2B founder, the choice comes down to how costs grow, who owns the automation logic, and whether software can call and verify it. A feature checklist can miss all three, even when every check mark is accurate.
What a starter-tier comparison page actually compares
Comparison pages usually organize the decision around feature presence. They show forms, email sends, basic sequences, and integrations listed by name, making it easy to see which package includes which tool. That is a useful first filter for buyers. But it answers a narrower question than a technical founder needs answered, because a feature’s presence says little about its limits or how it connects to the rest of a system.
How does the bill respond when both the team and its contact list expand? Can an internal service call the automation, and can a CI pipeline inspect its logic? A comparison built around a monthly entry price rarely makes those properties visible.
The three structural traps inside the Starter pricing model
The listed price is the least the team pays per person, so each new hire adds to the base cost before contact volume is counted. The mechanism is simple but easy to overlook. A feature table can show the same capabilities for a small team and a growing one while concealing how much more the latter pays to use them.
A contact cap introduces a different constraint. In a model where reaching that cap halts sending, list growth affects not only the bill but also the ability to run campaigns. A comparison that reports only the included contact allowance leaves out the more consequential question of what happens when that allowance is exhausted.
Form-triggered, linear actions are not equivalent to behavioral triggers, persona branches, or a multi-step nurture campaign, even though both can appear under an “automation” check mark. When those richer capabilities require a higher tier, the entry plan also limits how the team can express its process.
What the pricing cliff looks like when the bill scales on two axes at once
Seats and marketing contacts are independent billing axes. As a startup hires and grows its list, both can increase at the same time, while the need for richer automation pushes it toward a more expensive base plan. A mandatory onboarding fee adds a significant fixed cost at the moment of upgrade. The budget therefore has four moving parts to examine, including seats, contacts, the tier’s base cost, and onboarding. They do not all behave like a single monthly subscription.
The gap becomes especially consequential during a long B2B buying cycle. Behavioral triggers, lead scoring, A/B testing, and persona branching help a team respond to more than one decision-maker across repeated touchpoints. These are not simply decorative additions to an email tool. If access to them requires a dramatic increase in monthly cost, developing the nurture process becomes a budget decision as well as a marketing decision.
Why not budget for the higher tier from the start? That avoids a surprise upgrade, but a mandatory onboarding fee becomes a sunk cost before the team has validated its approach, and per-seat charges still grow with hiring. For a technical buyer, this raises a different question. If automation logic sits behind a vendor interface and a paywall, what would it take to own that logic instead?
Where the automation logic actually lives, and why that is an architectural question
Ownership begins with where the rules are expressed and stored. In a UI-bound workflow system, branches are configured through a point-and-click builder and held in the vendor’s database. The interface becomes the home of the process. When that is the only usable representation, the team cannot version the logic with product code, write tests against it, or move it elsewhere without recreating the branches.
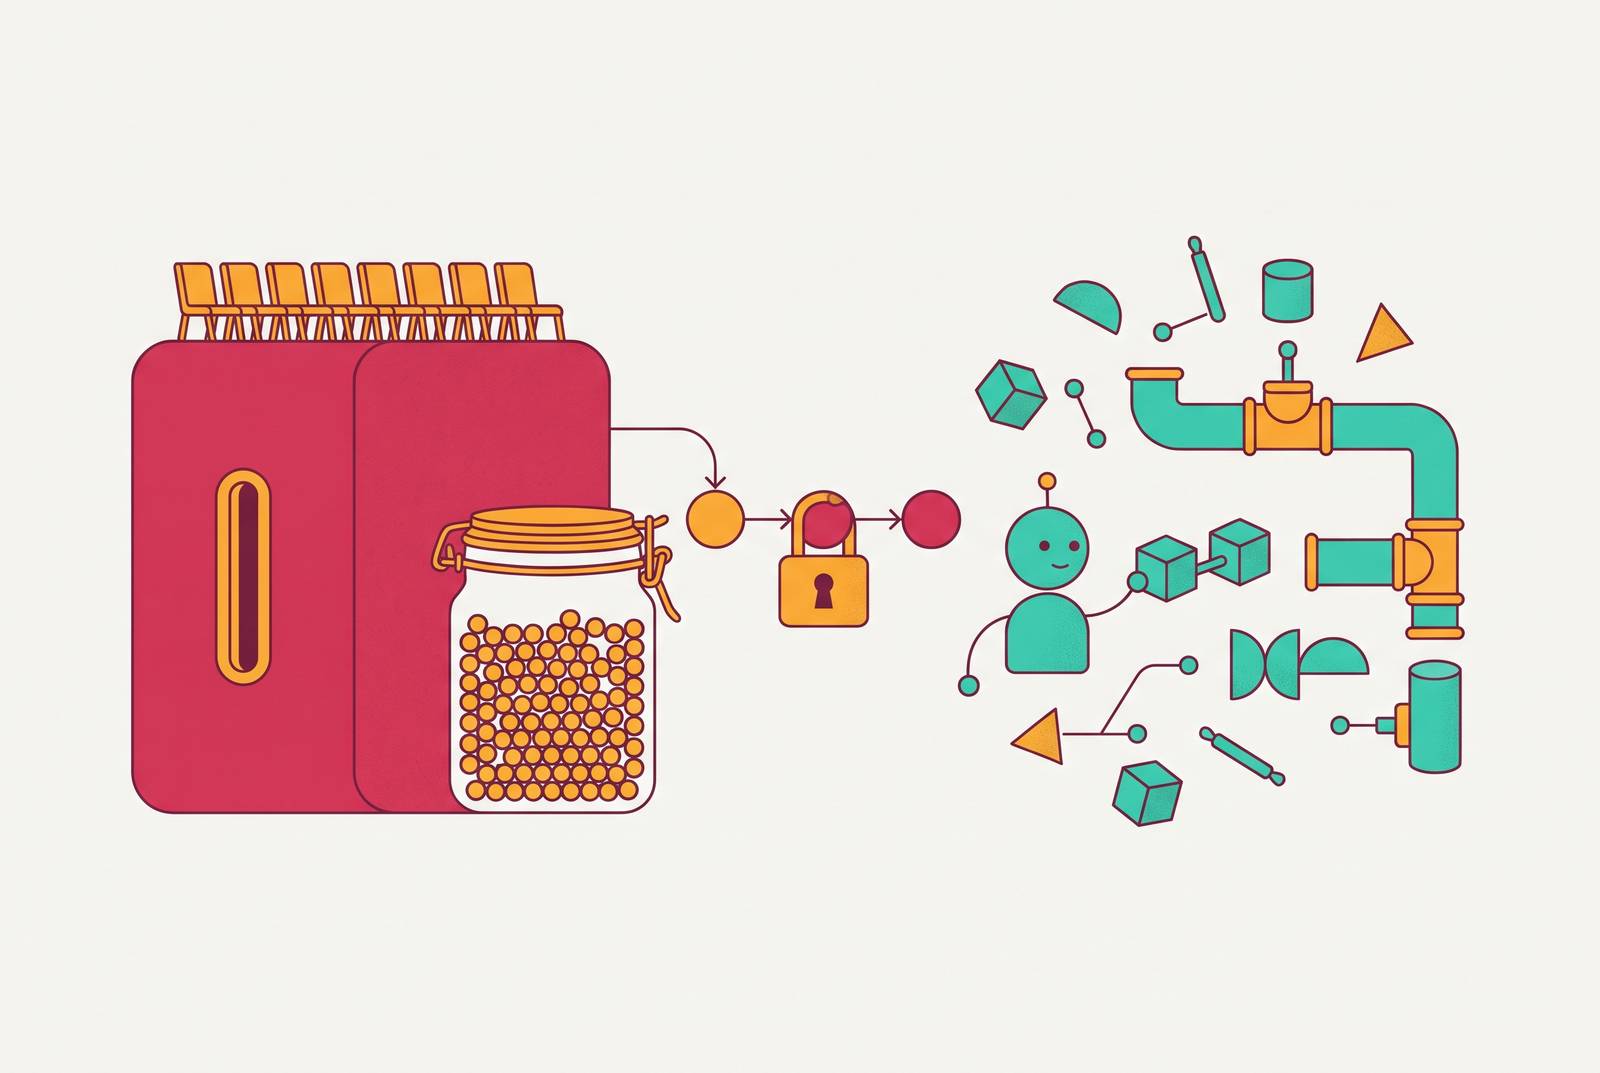
A composable architecture changes what the team owns. It treats segmentation, campaign creation, send triggering, and measurement as discrete API-callable primitives, with the connecting logic in code the team owns. Each primitive does a bounded job. The team can combine those jobs without keeping the only record of how the process works in one vendor’s workflow builder.
“Agent-callable” describes a further property of those primitives. An agent can invoke a segmentation or send function directly, receive a structured JSON response, and use that response to decide what comes next. It need not operate by clicking through a dashboard. This is the architectural distinction a feature table misses, because two products can both claim automation while giving software callers very different access to it.
What agent-readiness actually requires from a marketing platform
An API alone does not establish agent-readiness. The stronger test is whether the interface is designed for machine callers that need to discover tools, understand their inputs, and act within limited permissions. A production MCP server or equivalent tool-use interface provides that callable surface without custom integration code. OAuth-scoped authentication lets the team grant narrow, revocable access. Structured JSON responses with a canonical schema give the agent something it can evaluate without interpreting free-form text.
Schema-clean webhooks with read-write symmetry allow an agent to listen for changes and trigger actions using the same data model. A REST API and a Zapier integration can work for integrations that people build while lacking the permissions, discovery, and response structure that agents need for this level of interoperability.
Klaviyo provides a concrete market example through its MCP server. It exposes audience segmentation, campaign creation, and flow creation and management as tool calls, with audience data returned as structured JSON. A human still has to confirm before anything is sent.
The broader architecture has four layers with separate jobs. A spec holds the natural-language brief and disqualifiers, an orchestrator routes the work, a tools layer exposes typed calls, and a verification layer checks outputs against the spec. Many startups are not running this kind of marketing stack today. Even so, the interface chosen at the entry tier shapes what they can compose later, which makes agent-readiness a useful comparison criterion before agents become part of daily operations.
What a composable, token-metered alternative looks like for a technical B2B team
A composable content and marketing stack applies the same separation to research, drafting, publishing, citation monitoring, and measurement. Each capability is independently callable, combinable in a different sequence, and replaceable without changing the others. Replacement is part of the design. The architecture does not require the team to accept one suite’s workflow simply because it needs one of that suite’s functions.
Token-metered billing changes the basis of the charge. Instead of increasing with seats and contact volume together, cost follows usage associated with work such as a brief, a draft, or a measurement run. A line-by-line bill makes that usage auditable. This is not a guarantee of lower spending, because the case rests on an inspectable meter rather than a claim that every workload will be cheaper.
API/MCP/CLI-first access also separates operation from the dashboard. An agent, a CI pipeline, or a person in a terminal can reach the same capabilities, while push/pull APIs or MCP hooks connect them to the existing stack. Human review remains a configurable gate. AI-generated outputs can be reviewed and reversed before publication, whether the rest of the pipeline runs autonomously or pauses at selected stages. The concrete properties a founder can verify are an inspectable bill, logic held in code, and functions an agent can call.
Why AI answer-engine visibility is now a missing column in any marketing platform comparison
Owning the workflow does not settle whether it measures the right result. In 2026, AI answer engines are a primary discovery channel for B2B buyers, so a content stack needs to measure more than search rankings, clicks, and impressions. Did an answer cite the brand, recommend a competitor, or omit the category? Classic web analytics and SEO tools have no native mechanism for answering that different kind of question.
Generative engine optimization, or GEO, brings this discovery surface into the comparison. Share of Model, or SoM, is the percentage of AI-generated responses across a defined query set that include a brand. The query set gives the metric its scope. Without that definition, a claim about visibility does not tell the reader which buyer questions the measurement represents.
Measurement must also take into account how engines differ. Some get much of what they cite from conventional search results, while others draw on a wider set of sources that is harder to predict. Success in one engine does not automatically transfer. A stack that reports only one engine’s results therefore leaves part of the demand-generation surface unmeasured, regardless of how well its publishing workflow is engineered.
The content itself affects that visibility. Statistics backed by primary-source citations, authoritative sources from outside the team, recent updates, and appearances in trusted third-party sources get cited more often at rates that can be measured. Those sources include online encyclopedias, review sites, top-tier publications, and ranked “best-of” formats. Ranqo/Pratyush Kumar research analyzing a large corpus of prompt responses across more than a hundred brands from March–May 2026 found that ranked “best-of” listicles were the most-cited content format. The architectural implication is that citation monitoring and measurement need their own place in the stack alongside publishing.
The questions a technical founder should actually bring to any marketing automation comparison
For a founder evaluating a platform, the lesson is to replace feature presence with questions about boundaries and evidence. On which axes does the bill scale, including seats, contacts, sends, and API calls? What happens when each grows, and can the charges be inspected line by line? The upgrade boundary deserves equal scrutiny. Which capabilities require a higher tier, what mandatory fees accompany it, and what happens to the work already built below that boundary?
Does the logic live in a vendor UI or in code the team can version, test, and migrate? Can an agent call every needed capability without a dashboard, using scoped permissions and structured responses? Access alone is not enough to establish control. Can generated outputs and planned actions be reviewed and reversed before they ship, with human approval configured at the appropriate stage?
Does the platform measure AI answer-engine presence across a defined query set and across engines, or stop at clicks and impressions? Can the team check outputs against the original spec instead of just checking that intermediate steps ran? Those questions apply equally to a suite and a custom stack. The durable standard is work that is verifiable, functions that are composable, and outcomes that are measurable.