What an "AI marketing platform" comparison hides from technical buyers: entry price, onboarding fees and per-hub AI add-ons versus metered primitives you can script
Entry prices hide onboarding, add-ons and operator time, so compare cost to a working workflow.
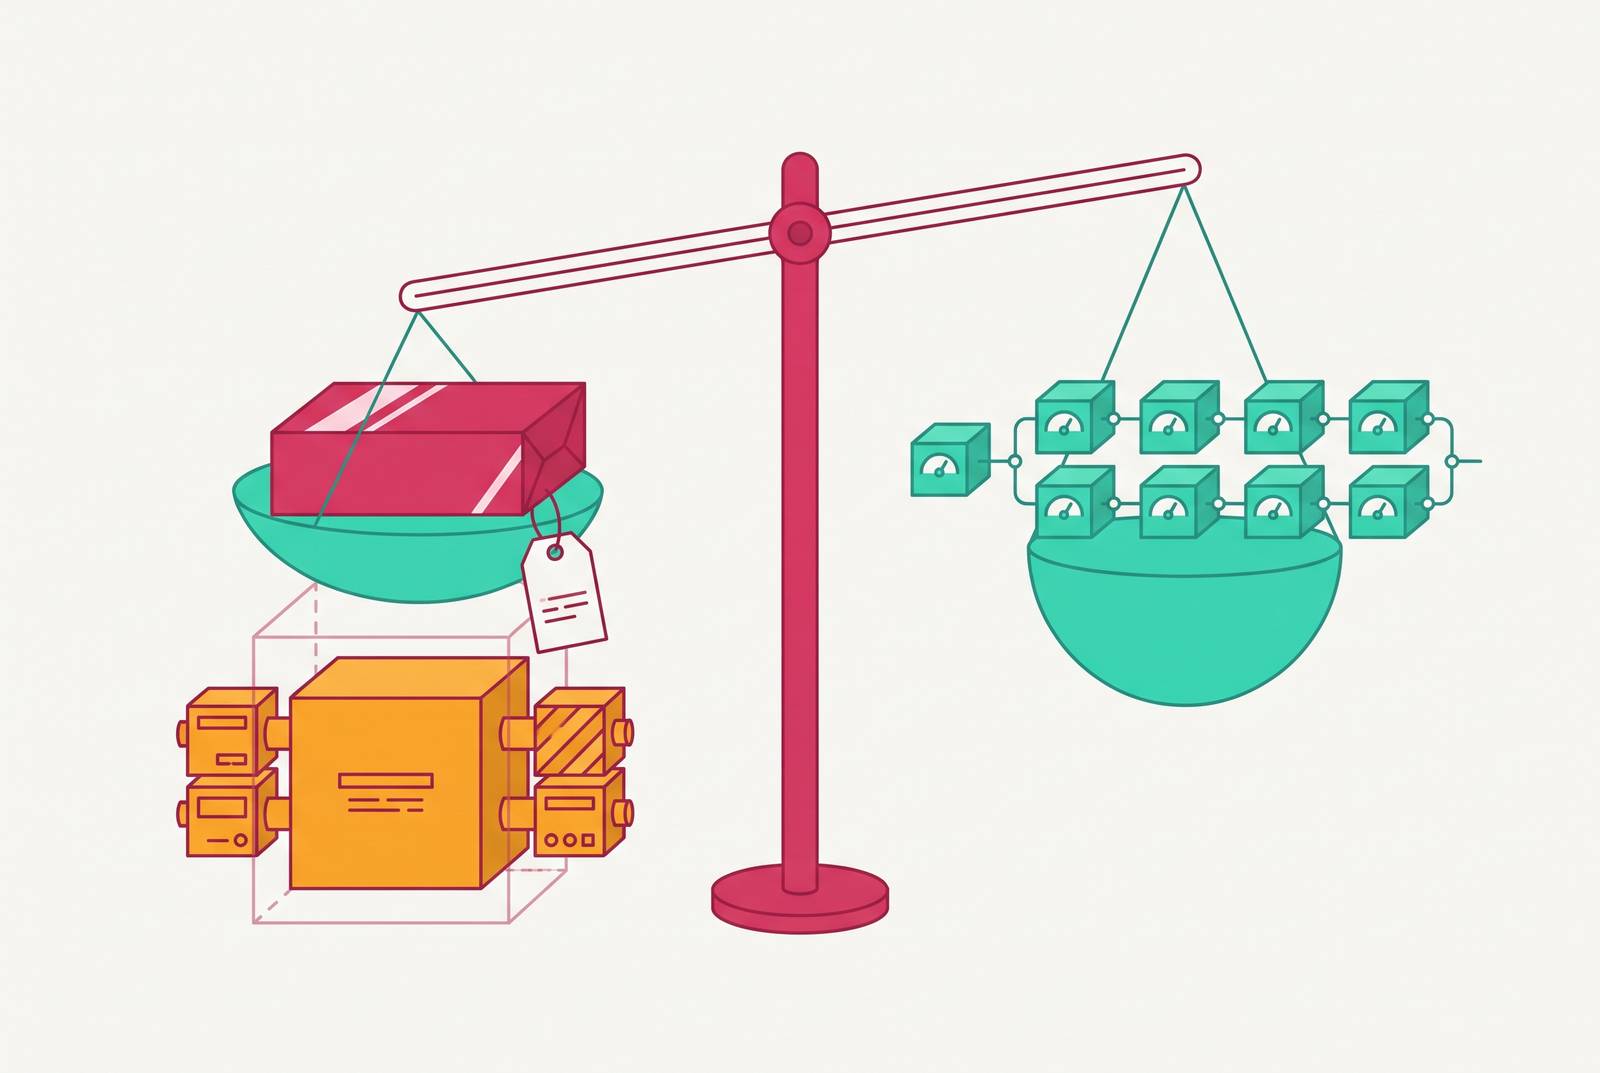
An AI marketing platform comparison is useful only if its price describes the workflow a team needs to run. Entry prices rarely do. For technical buyers, the better frame is total cost to a first working workflow, including implementation, usage and operator time, followed by a harder question about whether the capabilities can be automated through code and composed.
Why comparison tables quote the wrong number for technical buyers
A technical buyer opens a comparison tab and sees a tidy price table. Each platform has a monthly price and a column of features, so the next step seems straightforward. Find the features the team needs, then compare the prices. But the rows may show entry tiers while the automation and AI capabilities the team needs are in other plans or services. The table has supplied the wrong unit of comparison.
This is more than a missing fee. If the workflow needs a higher tier, another module or a separately metered AI service, the entry subscription cannot represent its cost. Two platforms with the same headline price can produce very different invoices as seats, contacts, credits or advertising spend grow. A feature checkmark does not reveal which of those meters applies.
The four costs behind every "starting at" figure
The missing costs fall into four layers. Layer one is the subscription sticker, which is the visible charge for access to a particular plan. It provides a starting point, but says little about the expense of getting the required workflow live. A low subscription is useful only if the necessary capabilities are included.
Layer two is mandatory onboarding and implementation. Enterprise advertising implementations can run into the tens of thousands of dollars, covering account mapping, pixel verification, creative library migration and training. These fees are non-negotiable on most contracts. They can also cost as much as many months of subscription payments, so leaving them out makes the costs look different before usage even begins.
Layer three is the add-on and credit layer. AI capabilities may need a higher tier or separate usage payments, and even with a clear per-unit rate, a team needs to estimate volume to work out a monthly budget. A 2026 ad platform pricing breakdown puts real all-in cost at a mid-market spend level at typically two to four times the published price after onboarding, integration and overage fees. Layer four is operator time, including campaign decisions, review, handoffs and troubleshooting. That last layer deserves its own calculation because faster drafts do not remove the work of running the system.
How the hub model moves the seams inside one bill
The four layers are harder to tell apart when a suite puts several modules under one product name. One bill can make the suite easier to buy while leaving the workflow just as complex. A team may still need a separate license for a module that adds a related capability, even when both are in the same suite. The seam has moved inside the bill. The team encounters this licensing seam when it tries to expand beyond its original purchase.
The same structure can expose a buyer to more than one growth meter. Seats and marketing contacts, for example, can increase independently, so a larger team serving a larger audience encounters two sources of price growth. Braze illustrates the broader pattern by layering “Action Credits” on top of monthly-active-user pricing. Both dimensions need a forecast. The expected total needs to account for the base subscription and both variable charges.
At enterprise scale, quote-only pricing makes comparison harder because public entry prices cannot tell the buyer what the total will be. The purchasing unit and the working unit are different. A single vendor may sell the whole arrangement, while the team still has to understand the licenses, meters and handoffs for each capability the workflow uses.
What billing meters actually punish, matched to how B2B SaaS teams grow
The practical correction is to read a pricing page against the team’s growth pattern. Which activity makes the bill rise? Per-seat licensing charges for hiring when each new team member needs access. It may fit a stable two-person team well, while becoming a different proposition for a team growing from three to twelve. The plan name does not reveal that change.
Per-contact billing ties cost to pipeline growth, just as a growth-stage B2B SaaS team is investing in acquisition. Per-credit and outcome-based billing instead tie it to volume, including messages, agent invocations or AI queries. Without historical usage or a credible projection, the buyer knows the price of a unit but not how many units the workflow will consume.
The ad platform breakdown describes Smartly’s model as ranging from 1 to 3 percent of spend, so the tool fee rises when successful campaigns lead to larger budgets. Hybrid models add a base fee and activate a spend-based charge above a threshold. For a technical buyer, the lesson is to map each required capability to its meter, then model it against the 12-month growth projection. The inflection point, where expansion changes the cost curve, is more useful for approval than the entry price.
The operator cost that never appears on a pricing page
Even a well-modeled invoice leaves out the person operating the software. For most lean B2B marketing teams, that person costs more than the platform itself. Someone still decides campaigns, builds audiences, reviews output, manages module handoffs and diagnoses integration failures. AI can shorten drafting without removing those responsibilities. The 2026 pricing analysis puts it directly, “The expensive part is the person who operates the software, and most businesses discover that only after they have paid for it”.
Architecture changes how much of that work accumulates. Each module has its own interface, configuration surface and failure modes, so a team that manages five hubs has five sets of these to work with. One bill does not unify that work. More contexts create more handoffs to manage and more places to investigate when the workflow fails. This is why operator load can distinguish total cost more sharply than a subscription discount.
Implementation also consumes time before the workflow produces output. A 2026 buyer’s guide gives a range from days to a few weeks for simple tools to 6–9 months for a full contract-to-revenue lifecycle with revenue recognition. Time to a first working workflow makes the comparison more useful by tying implementation effort to the actual job being purchased. The team can then price those hours at its internal cost rate or use published agency rates as a planning reference.
What "scriptable primitives" actually means and why it changes the cost equation
A scriptable primitive is a capability a machine can call through an API. A technical team can connect such capabilities to its own stack, automate their execution and version-control the configuration. The workflow becomes something the team can compose. Instead of configuring only what a vendor has pre-assembled, it builds the sequence it needs and skips capabilities it does not use.
When a team knows its call volumes, it can work out per-resolution, per-lead or per-data-answer charges from how much it expects the workflow to do. Demand can still be unknown when a team uses the API. Human effort shifts from manually invoking each step to building and supervising the workflow.
Gartner’s 2025 survey found that marketers actively use only 49% of their martech stack’s capabilities. That finding challenges the assumption that a larger bundle provides more practical value. The relevant test is narrower. Can an agent reach every capability needed for this workflow through an API, or does a required step still depend on a person using the interface?
Human review as a workflow primitive, not a platform feature
Scriptable execution still leaves a role for human judgment when making content. Review is a separate architectural decision, with two distinct modes. Human-in-the-loop review requires a person to adjudicate before an action takes effect, making it appropriate for high-severity, legally exposed or brand-critical content. Human-on-the-loop review lets the model act while a person monitors a sample afterward. That mode works for high-volume, low-severity content where checking a sample can catch systematic errors without holding up every output.
The choice should follow content risk. Social posts need a brand-voice check, while blog content needs fact-checking and a review of how well it fits the strategy. Thought leadership and regulated content need a subject-matter expert to review them and legal sign-off. These are different demands on human attention.
A scriptable pipeline allows the gate to sit at the point where judgment is needed, with automated checks such as PII detection, toxicity scoring and factual consistency running before and after it. That placement is the important distinction. A review preference in a UI may not govern every integration, allowing “shadow content” to reach production because approval was bypassed or never enforced in the pipeline.
The evaluation frame technical buyers should use instead of a comparison table
The replacement is a decision protocol built around four questions. The first asks what it costs to reach a first working workflow. The team needs to add up the subscription, mandatory onboarding, required add-ons and the hours it expects implementation to take. A 2026 B2B agency pricing guide provides published U.S. digital marketing agency rates as a planning reference when the work is not in-house. Implementation time belongs in the estimate too, because the team incurs costs before the workflow starts producing output.
The second question asks which meter applies to each required capability and where that meter bends against expected growth. Model the next 12 months with flat, doubled and fivefold growth before approving a plan based only on today’s volume. A meter that looks attractive at the starting point may become expensive in precisely the scenario the team hopes to reach. Looking at each meter on its own also shows whether the cost is changing because of audience growth, hiring or usage.
Third, establish whether every required capability is reachable through an API. Request the documentation for the specific workflow before signing, because absent or incomplete documentation leaves scriptability unproven in practice. The fourth asks where human review is enforced. A pipeline-level gate can govern integrations in a way that a UI preference cannot. For regulated content or brand-critical output, the team needs to weigh that difference when checking compliance as well as when discussing the workflow.
Composable API primitives give technical teams a way to answer these questions through published rates, usage estimates, callable capabilities and review gates enforced in code. They still require implementation and sound estimates. A comparison table asks which platform offers more features at a lower sticker price. A technical buyer needs to establish what it costs to get a working workflow live, and whether the team can script it.