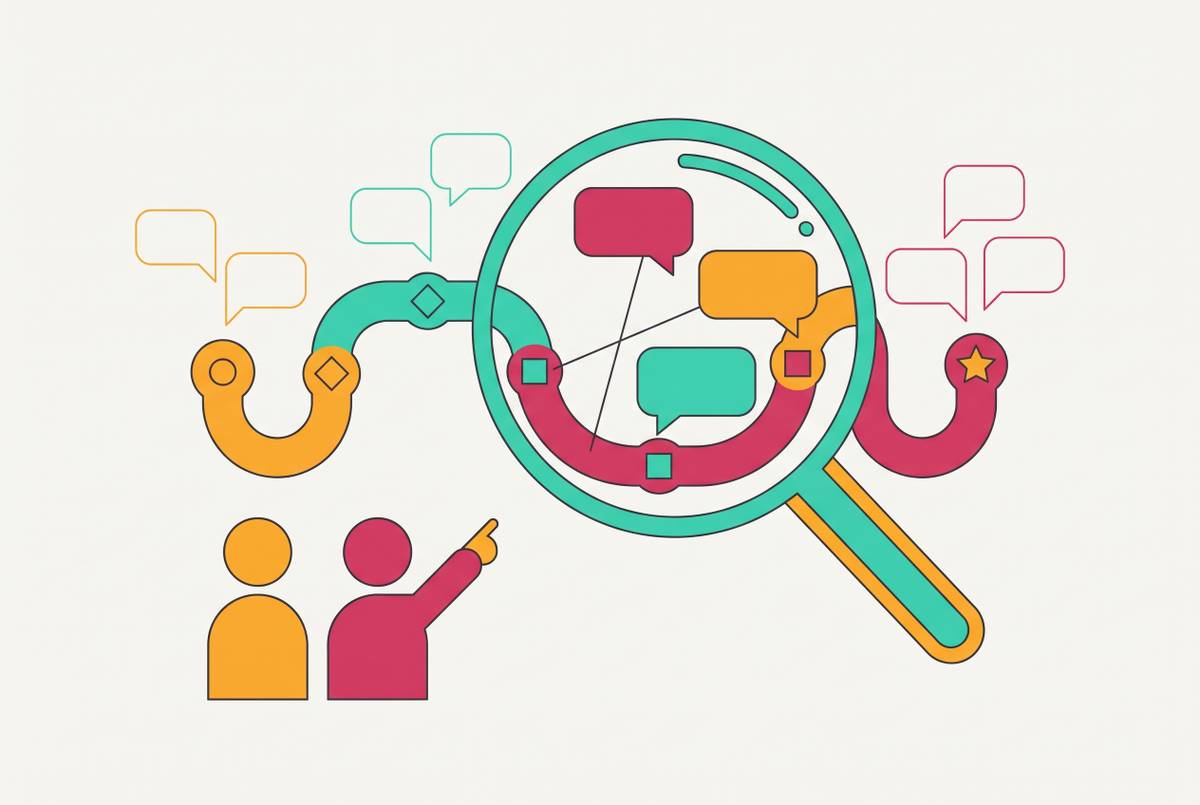
A service page about AI search says it traces the stage where an assistant drops you: what a buyer should ask a vendor to show, and which of those stages can be instrumented rather than called on a weekly call
Ask vendors to show stored answer logs, not weekly call summaries.
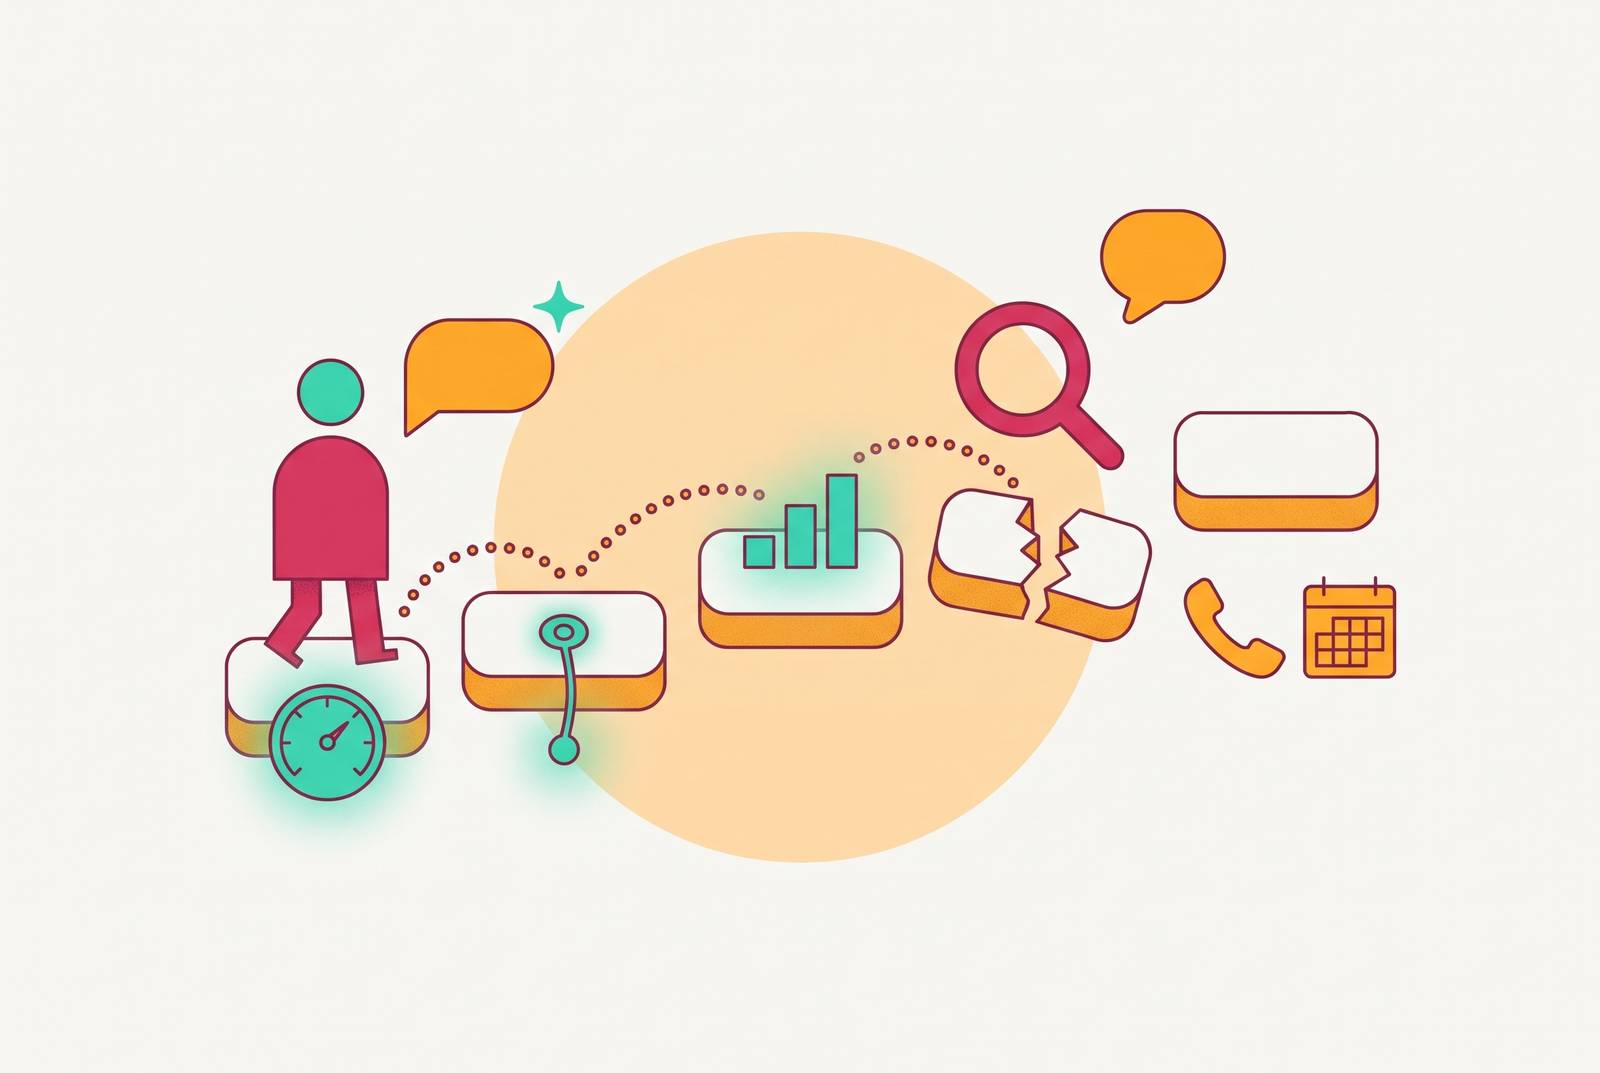
AI search visibility vendors should be able to show where an assistant stops naming your brand and back up promises that more buyers will see it. The buying decision turns on whether that diagnosis comes from stored, inspectable measurements or a person reading answers on a weekly call. A useful service needs both instrumentation and judgment, with clear proof of what each contributes.
Why AI answer engines decide vendor shortlists before your sales team knows an evaluation started
AI answer engines compress awareness, category exploration, and shortlisting into a research sequence your sales team may never see. A buyer can move from learning about a problem to choosing vendors to contact without revealing any of those steps. In B2B SaaS, that means a buyer’s “day one” list can be effectively fixed before first contact, leaving absent brands with a low chance of winning regardless of later outreach quality.
The loss itself is hard to detect. When an assistant leaves a brand out of its shortlist, the sales team does not receive a rejected proposal or a reason for losing. Consider the example behind the service-page framing, in which a startup appeared in a small fraction of AI answers while its direct competitor dominated the same prompt set. That gap describes exclusion from consideration. To address it, a vendor must locate where the assistant stopped naming the brand rather than treating every absence as a general visibility problem.
What the AI citation funnel actually looks like, stage by stage
The funnel begins with awareness, when the assistant must know the brand exists. Exploration comes next, when it includes the brand while describing the category. Shortlisting requires the assistant to name it among the options worth considering, while recommendation means treating it as a preferred choice. These are separate tests of a brand’s presence. An assistant can recognize a company perfectly well and still leave it out when a buyer asks which vendor to choose.
The terms used to sell this work need only a brief explanation. SEO means search engine optimization, while GEO and AEO mean generative engine optimization and answer engine optimization. Here, the useful distinction is between appearing as a cited source and having the brand absorbed into the answer the buyer reads. A trailing reference is not a recommendation. A vendor saying “you’re being cited” may therefore be describing a much weaker result than a brand named in the answer body as a suitable option.
The overlap between domains cited by ChatGPT and Perplexity is very small, so a single-engine report cannot stand in for the whole journey. The startup example becomes useful when the prompt set and engine attribution show where its presence falls away relative to its competitor. Without those details, the gap has no clear location. With them, a buyer can distinguish a brand that rarely enters category answers from one that appears there but disappears at shortlisting.
Why most vendors cannot tell you which stage you are failing at
A report can look comprehensive while testing only the end of the journey. A prompt library full of decision-stage questions may show which brands get recommended, but it cannot show whether the missing brand passed the earlier stages. Coverage is not the same as volume. A reasonable portfolio spans awareness, consideration, and decision, with awareness and consideration together taking the larger share. Within those broad layers, the prompts need to distinguish exploration from shortlisting so that the diagnosis has a precise meaning.
This helps explain why some reports feel slippery. They offer a broad conclusion about visibility without showing whether the assistant failed to recognize the brand, include it in the category, or recommend it. A weekly call that reads selected prompt results aloud shows only what happened in those answers, leaving the trend, the variance across engines, and the relationship between a content change and citation movement unexamined.
The decisive evidence is a per-engine answer log. It records the query, the time, the returned answer, whether the brand was named, its context, and its sentiment. A buyer can inspect that record rather than depend on the vendor’s selection of examples. A vendor may have useful editorial skills yet lack the instrumentation needed to support a claim about the exact stage where a brand drops out.
What instrumented AI visibility measurement actually looks like
Instrumented measurement begins with a prompt library that runs automatically, at a fixed cadence, across multiple engines. The results remain available in an inspectable log, including mention rate, citation rate, share of answers, cited URL, and answer sentiment. Measure how often each engine named a brand against named competitors across repeated runs of the prompt set over four weeks. Query-level records then show which prompts produced citations, which produced nothing, and where the brand appeared.
Those records must preserve the differences between engines. A brand that appears often in Perplexity and rarely in ChatGPT has a different problem from one with the reverse pattern, even if their combined scores look much the same. The answer body also needs to remain distinguishable from trailing references. Otherwise, the metric can reward presence without recommendation. A buyer should be able to move from the reported rate back to the answers behind it, rather than accept a human summary as the only available evidence.
The site’s accessibility is a separate prerequisite. GPTBot, ClaudeBot, and PerplexityBot do not execute client-side JavaScript, so content that depends on that rendering can be invisible to them. A crawler-access and server-rendering audit therefore belongs before content optimization. Access policy needs deliberate choices as well. Allowing OAI-SearchBot for real-time citation while blocking GPTBot for model training is one such choice, and the vendor should establish whether it has been made and documented.
Machine readability also extends to the proof on each page. Structured data, named entities, verifiable statistics with attributed sources, and an llms.txt file are signals the vendor should examine. Microsoft’s Bing Webmaster Tools added an AI Performance Report in public preview covering Total Citations, Average Cited Pages, Grounding Queries, Page-Level Citation Activity, and Visibility Trends. The report expanded in June 2026 with Intents, Topics, Citation Share, and Compare. That first-party dataset gives buyers a concrete reporting question, namely whether the vendor incorporates it or leaves it out.
The specific questions to put to any vendor before signing
How much of the buyer journey does the prompt library cover? Ask how many prompts it contains and what share belongs to awareness, consideration, and decision. Request the split in writing, together with the actual prompts. The wording itself needs to be inspectable.
Are raw answers stored, or summarized before delivery? Ask for an example showing the actual text returned by ChatGPT, Perplexity, and Gemini for a specific prompt on a specific date. If the vendor summarizes first, ask what is lost. Then ask how often the library runs, whether daily, weekly, or on demand, and what minimum cadence the vendor considers sufficient to detect meaningful change. The schedule should be clear before work starts.
Can a content intervention be tied to citation movement? Ask for a before-and-after example showing the change, the prompt it was designed to affect, and the named or cited rate across engines afterward. Ask how long the vendor expects an effect to take and how attribution is documented. Timing alone does not explain a change. If the vendor cannot show this evidence, the practical follow-up is how it decides which work is succeeding.
What can AI crawlers retrieve from the site? Ask whether robots.txt has been audited for GPTBot, ClaudeBot, and PerplexityBot, and what the audit found. Ask whether the content is server-rendered or client-side rendered and whether crawler retrieval has been examined. The audit should reach the proposed pages. What structured data, named customer evidence, and verifiable statistics are present, and can a machine confirm that those elements are there?
Which outputs come from the system, and which require judgment? Ask which tasks are automated, what machine-readable output they produce, and whether the underlying data is available through an API. For work requiring a judgment call, ask who makes it. A vendor with a defined workflow can explain its boundaries, while deflection leaves the buyer unable to judge what the service actually delivers.
Where a human call still belongs in the loop, and where it does not
Automation should handle repeatable observation and make the results available before a meeting. That includes scheduled prompt runs across engines, stored answers, and tracking of mentions, citations, share of voice, cited URLs, and sentiment. Crawler-access checks, server-rendering checks, and structured data validation also belong in machine-readable outputs. Alerts should flag sharp drops in citations or big gains by competitors. The purpose is to make changes visible without requiring someone to discover and narrate each one.
Choosing the buyer’s own words for a prompt library takes someone who understands how buyers make their choices, since keyword proxies alone will not do. Editorial choices need human review as well. Reviewing an outline before drafting is the highest-leverage checkpoint because it can catch a weak angle before resources turn it into a finished page. Before scheduling, an editor must still check accuracy, original insight, and brand voice, even after an automated pass.
Interpretation belongs with people when the data flags a persistent gap without explaining it. A drop in Perplexity citation rate after a site change is a signal, but diagnosing crawler access, content structure, or entity clarity requires someone who understands the system. That is a useful weekly call. People on the call can weigh what might explain the gaps and decide which ones to work on because the evidence is already there outside the meeting. Calling that discussion “monitoring” confuses interpretation with collection, just as calling raw output “strategy” gives automation work it has not done.
What the vendor page gets right, and what proof standard it still leaves out
The service-page framing gets an important point right. Locating the stage where an assistant drops a brand is more useful than offering generic GEO advice, because it makes the brand’s absence diagnosable. Its worked example also uses the right form of evidence, connecting a startup’s limited presence and a competitor’s dominance to engines and prompts. Proof on the page is more persuasive than a technical checklist alone. A prospective vendor should be able to produce equivalent evidence for the buyer’s brand.
Establishing ongoing monitoring requires evidence beyond a snapshot that the measurement runs again, that answers remain stored, and that content interventions are tied to later citation movement. The missing standard is continuity, with enough detail for the buyer to inspect what changed independently of the vendor’s account.
For a buying decision, the full standard calls for a diagnosis that names the stage, per-engine logs, and a full-funnel prompt split that the buyer can see. It also requires scheduled reruns with queryable results, a documented before-and-after intervention, and an audit of what AI crawlers can retrieve. The system supplies the record, while the human call interprets gaps and guides editorial choices. Before signing, the buyer should be able to inspect that record without needing a meeting to make it exist.