Before you judge a growth experiment, audit what your analytics counted: bots, agents, consent banners and test leads
Bots, consent gaps and test leads can skew your results before any buyer converts.
A growth experiment can only explain the behavior of the population it actually counted. In 2026, bots, AI agents, consent-banner dropouts and test leads can distort that population before a human converts. Before a traffic spike or conversion shift changes where effort goes, the counts need an audit. Even then, clean analytics cannot show everything that led buyers to the site.
Why your experiment denominator is broken before the first human converts
An experiment usually starts with an assumption that traffic and conversion counts faithfully record human behavior. That assumption fails when automated visits enter the count, human visits disappear from it, or a test submission passes for a buyer. The fraction still gives a conversion rate that looks precise. But what population does that rate describe? Without knowing who entered the denominator and what qualified for the numerator, a comparison between experiment periods can confuse a measurement change with a behavioral one.
Cloudflare Radar shows that automated traffic accounts for a substantial share of web requests and that its share has risen substantially over the past year. Yet automation is only one fault to diagnose. Bots can inflate recorded traffic, while AI crawlers that execute no JavaScript remain invisible to client-side analytics. Consent rejection selects which humans remain measurable, and internal or test leads pollute conversions. These faults need separate checks because they affect different parts of the calculation, sometimes in opposite directions.
How bot and AI crawler volume inflates traffic without touching conversions
Cloudflare measures HTTP requests, while Thales measures traffic at the application layer. The higher bot figure from the latter is consistent with the former because they count different populations at different parts of the stack. That distinction also applies inside an experiment, where server requests and analytics sessions are not interchangeable. Before asking how much traffic was automated, the reader needs to ask which traffic the measurement could see.
Cloudflare’s May 2026 data shows training-purpose requests outnumbering search-purpose requests by more than five to one. Most of that crawling returns essentially no referral visits. The same data shows ClaudeBot crawling tens of thousands of pages per referral, Perplexity in the low hundreds, and traditional Google search near five pages per referral. When a content experiment is judged by request volume, more crawling can look like more demand.
Standard training crawlers such as GPTBot, ClaudeBot and PerplexityBot fetch HTML without executing JavaScript. They do not fire client-side analytics tags. GA4 therefore sees less of this bot load than server logs do, but these crawlers do not directly inflate its session count through those tags. Browser-based AI agents create a different problem because they execute scripts, fire tag managers and appear as sessions. Treating both populations as one kind of bot obscures which metric is at risk.
DataDome’s Q3 2026 AI Traffic Report documents agentic browser requests rising from millions in August to tens of millions in September on one network. Identification is not consistent across these agents. Meta’s Muse has no agent identifier in its user-agent string, but Google-Agent has a dedicated token. So a check that looks only for an explicit agent label can miss automated activity. For an experiment, checks need to establish whether script-running automation changed the measured audience.
Automation can inflate pageviews, shorten average session duration, raise bounce rates and dilute conversion rates. A channel that looks weak may perform well with humans. To diagnose that possibility, compare server-log requests with GA4 sessions for the same pages and period, using the gap as an estimate of bot load rather than treating requests and sessions as equivalent units. High-frequency hits from data-center ASNs such as AWS, DigitalOcean and OVH, without corresponding engaged sessions, are a strong signal. The comparison exposes traffic client-side analytics misses, while JavaScript-running agents require attention within the recorded sessions themselves.
Why consent-banner dropouts make your surviving data systematically biased, not just smaller
Consent rejection removes a non-random share of real visitors from the count. The remaining audience is not necessarily representative. People who accept tracking can differ from those who reject it in ways related to conversion behavior. An A/B test on the consenting population therefore does not, by itself, support projecting the result to every visitor.
Rejection rates vary by geography and banner design, so the composition of the measured audience can shift even when the underlying audience does not. What happens if one experiment period records a larger share of visitors from a market with higher acceptance? The result now reflects both the experiment and a change in who was observable. A larger surviving dataset does not remove that confound.
Google made the Consent Mode ad_storage parameter the sole mechanism for routing the relevant consent signal to Google Ads on June 15, 2026. Google Signals now controls only the behavioral reporting in GA4. A broken signal can disrupt measurement in a linked ad account as well as create compliance problems. A drop in measured conversions during such a failure is not evidence that visitors suddenly became less willing to buy.
Stopping the collection of personally identifiable or re-identifiable data is different from stopping every form of aggregate measurement. Where a separate legal basis permits anonymous collection, aggregate pageviews, session duration, traffic source, device type and country need not be discarded merely because tracking was rejected. That is a conditional distinction. It separates unavoidable limits on measurement from additional losses caused by how the banner and analytics were configured.
For the audit, the question is whether consent changed who entered the experiment’s measured population. Pull acceptance rates by geography and traffic source for the experiment window, then compare control and treatment periods. Signal integrity needs its own check, because stable-looking totals do not establish that the banner transmitted consent correctly throughout the window. Consent bias and consent failure are related, but they are not the same fault.
How internal traffic, test leads, and QA sessions corrupt the conversion numerator
The numerator can be contaminated while the denominator is already distorted. In B2B experiments, forms submitted by developers and QA, visits by staff through ads, sales demo accounts and integration tests can all count as conversions. A webhook test may fire the event without bringing in a prospect. These activities serve legitimate operational purposes, but counting them as buyer responses gives them the wrong role. Their upward pressure on conversions can coexist with bot traffic’s downward pressure on the conversion rate.
Google and Meta use conversion signals to train bid algorithms to find users who are likely to convert. When test leads enter that training signal, the platforms learn from internal testers in place of buyers. Growth Room’s analysis of B2B advertising accounts found that optimizing on qualified conversions, including MQL, SQL and opportunities, systematically improved lead quality compared with optimizing on raw leads.
To isolate this fault, cross-reference conversion-event email domains and IP ranges with employee and contractor rosters, known QA environments and partner test accounts. Remove test and internal events that match before drawing conclusions from the results. Then compare time-to-lead-qualification distributions during the experiment with the baseline. A spike in leads that never progress past first contact signals possible noise in the numerator.
What to audit before reading any experiment result
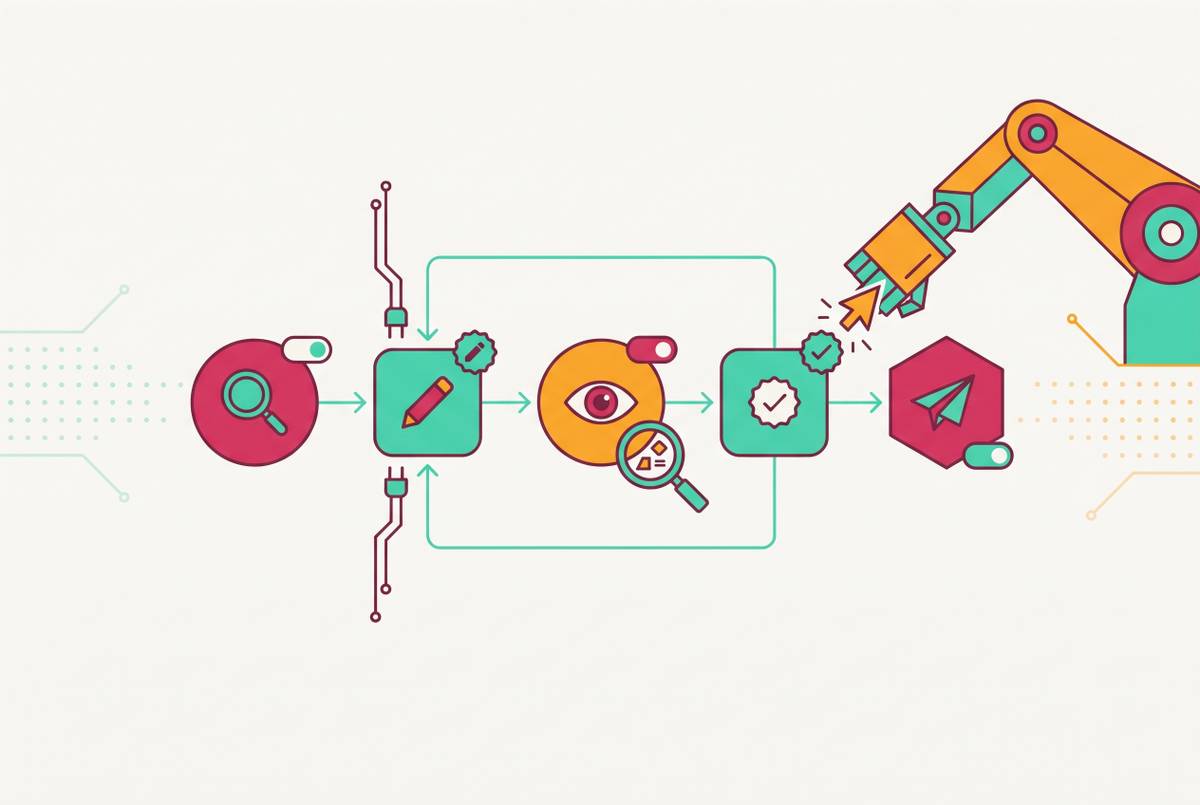
These checks should be a reusable pre-read procedure for routine and suspicious results alike. The order is deliberate. First quantify automated traffic, then verify consent signals, remove internal and test conversions, and examine whether the optimized metric connects to the business outcome. Each check answers a different question about the experiment. Passing one check does not make up for failing another.
The first check compares server-log request volumes with GA4 sessions on the specific experiment pages during the experiment period. Data-center ASN clusters need to be checked, along with any change in the bot-to-human ratio between control and treatment windows. A change in the mix of automated and human traffic is a confound because the conversion-rate comparison then contains something other than the treatment’s effect.
Confirm that the consent management platform sent valid consent strings to GA4 and linked ad platforms throughout the experiment window. Then inspect acceptance rates by day and geography, with traffic-source differences in view. A sudden drop or spike warrants investigation for a banner malfunction before it is read as a behavioral change. This separates a change in visitors’ choices from a break in how those choices were recorded.
The third check removes identifiable internal and test activity from conversions. Match event email domains and IP ranges against the internal and test list, and check that QA and staging environments are excluded from the production data stream. Integration and webhook test events also need to be tagged and excluded. Comparing qualification patterns with the baseline also helps check whether the conversions left in the count came from people who might buy.
GrowthSpree’s closed-loop study found negligible correlation between click-through rate and pipeline, while cost per SQL was a strong predictor. More clicks are not automatically a commercial win. A form-fill count likewise needs an account-level connection to pipeline before it can stand in for success. The audit’s purpose is not a simple go/no-go verdict, but a cleaned numerator and denominator attached to an outcome with defensible meaning.
The measurement gap that sits upstream of analytics entirely: AI-driven discovery you cannot see in GA4
A clean on-site population still leaves an upstream blind spot. Similarweb’s 2026 Generative AI Brand Visibility Index reports that a substantial share of US consumers use AI tools for product discovery, more than use traditional search for that purpose. A shortlist can form before any site visit. That influence never enters the experiment’s traffic denominator as an exposure, even if it helps shape who later comes to the site. Cleaning the session data cannot recover a decision that happened outside it.
Consider a brand cited in a ChatGPT or Claude answer. That mention can shape consideration, but a later visit may appear in GA4 as direct traffic or branded search. The AI touchpoint disappears from the attribution path. Measurement needs to establish both whether the session was counted correctly and whether the measurement frame includes the channel that shaped the visitor’s choice.
AI visibility also differs from engine to engine. A brand’s chance of being named for a relevant prompt varies across ChatGPT, Claude, Gemini and Perplexity, and visibility on one does not predict visibility on another. Ahrefs’ analysis found that web mentions had the strongest correlation with AI Overview brand visibility, while site page count had the weakest. Producing more pages therefore cannot be treated as an equivalent route to greater citation share, and that correlation does not establish a causal recipe.
Repeated sampling is necessary because citations are volatile. Models rebalance answers for diversity and freshness, so a brand present one day may be absent the next. For tracking to be reliable, the same prompt set needs to be sampled across engines again and again, with results kept separate by engine and prompt type. For a content or positioning experiment, that adds a separate view of influence. The downstream traffic result can be clean and still capture only the aftermath of a choice made inside an AI answer.