Developer marketing isn't a content problem — it's a systems problem
Integrating developer feedback, product, and measurement closes the loop marketing keeps missing.
Developer marketing is primarily a systems problem. Good writing cannot make up for broken links between developer questions, production, distribution, and measurement. The fix is to build marketing like infrastructure, with a closed feedback loop, automation for repeatable work, and people responsible for its direction and quality.
Why developer marketing keeps failing despite good content
A team puts out useful tutorials, ships product announcements, and keeps its content calendar full, but starts each quarter searching for ideas again. The work goes live without feeding the next decision. That is the failure pattern to examine. Content is produced in isolation from the questions that prompted it, the places developers encounter it, and the evidence of whether it helped.
The gap starts with how developers evaluate brands. They look at code and docs first, community second, and brand last. Even well-written content may never enter that sequence if it has no link to product friction. Meanwhile, DevRel hears the questions, product knows the limits, and content is in charge of what gets published. Each team holds part of the feedback loop, but no one necessarily owns the whole path from a developer’s problem to a useful answer.
What about teams that publish heavily and still grow? Volume can mask the gap during a growth market. It becomes harder to ignore when the market tightens or a competitor builds a loop that learns from each round of work. Without that feedback, content decays instead of earning a compounding return, and the next quarter demands another batch made from scratch.
How developers actually research tools in 2026
AI assistants change where a developer encounters an answer. Someone asking “best error tracking for a Node API” or “alternatives to Postman” can receive an assembled recommendation. A brand absent from that answer starts behind. The evaluation can begin before a developer reaches the vendor’s website, which makes website traffic an incomplete account of discovery.
Search has not disappeared from that process. The Stack Overflow 2026 Developer Survey places online search ahead of asking an AI agent among the ways developers find answers. The change adds a discovery surface alongside search. Documentation now serves two audiences, humans who read it themselves and assistants that use it to build answers. A page may help one audience while failing to give the other usable evidence.
The people doing the research have also widened. AI coding tools have brought designers, analysts, product managers, and founders into building software. Professional engineers and AI-native builders do not necessarily research in the same way or trust the same proof. Is the program speaking to engineers, these newer builders, or both? An undefined audience makes it harder to connect a real question with the answer that earns trust.
Why two discovery surfaces demand two separate systems
Google rankings and AI citations are different outputs. A page that never ranked in traditional search may be cited regularly by ChatGPT, while a page built for Google click-through may offer no clean answer an assistant can extract. Success on one surface does not establish success on the other. Trying to optimize both in the same way conflates bringing someone to a page with being used as evidence in an answer.
The architectural response is two distinct systems for discovery within one shared feedback loop. They can draw on the same product knowledge, but they need different content structures and measurement. One queue of content to publish cannot cover both jobs. Nor does “AI visibility” describe one uniform destination, since a brand can earn citations on Perplexity and remain nearly invisible on Gemini. Coverage of one engine is not evidence of coverage across engines.
This distinction also changes how performance should be read. AI referral traffic can convert at a materially higher rate than Google organic traffic, so fewer visits need not mean less commercial value. At the same time, a piece can lose Google clicks while gaining AI citations. Those are distinct performance signals. A system that records only one may optimize away work that is succeeding on the other, or mistake success in a narrow channel for broad discovery.
What content actually earns AI citations — and what wastes the effort
In the assistant’s search, retrieval has to happen before citation. If content never enters the material available to an answer engine, polishing its wording cannot solve that upstream problem. The SIGIR 2026 paper and the GEO literature survey identify topical relevance and position in context as the most reproducible citation drivers. The evidence still needs careful boundaries. The controlled-experiment base rests mainly on one large factorial study.
The September 2026 re-test sharpens that caution. Statistics rewrites, added quotes, and decorative citations had no positive pooled effect across ten current model families and did not change citation rates on any of them. These tactics made the work look more authoritative without delivering a citation gain. Statistics and sources can help readers, but adding them for their own sake has no established benefit for AI visibility and can consume production time without improving the intended result.
The distinction is between evidence and decoration. A fact-dense, encyclopaedic grounding page gives a model material it can reason from. An /ai-instructions/ file instead asks it to behave a certain way, which it may read as marketing and discount. An llms.txt file has no proven effect yet. These formats should not be treated as interchangeable shortcuts simply because each is aimed at an AI audience.
Where evidence appears also affects its reach. Brands with profiles on trusted review sites, Q&A forums, and community spaces have a higher citation probability than brands publishing only on their own domains. Sharing content through earned media can bring far more citations than publishing on an owned site alone. Connecting useful product evidence in first-party content with the third-party places developers already trust gives a technically polished page the distribution it needs.
The closed loop: from pain-point capture to published content to measurement
The loop begins where developers describe friction. GitHub issues, Discord threads, Stack Overflow questions, and conference hallway conversations supply the raw signal. DevRel and community channels become an instrumentation layer when that signal reaches content briefs. Without that route, the question stays in the conversation where it came up. A publishing calendar cannot recover a problem it was never given.
Those questions should also keep positioning open to revision. Supabase’s “open source Firebase alternative” positioning is sustained through weekly product updates and extensive tutorials. The content keeps the promise connected to the product. In this model, positioning helps the team choose which problems to explain, while real friction tests whether the positioning still helps.
Specific scenarios, working code, and clear answers determine what gets made, with the calendar recording those decisions. Vercel’s documentation-as-growth-engine and Next.js Learn interactive tutorial show why the form of the answer belongs in that decision. The tutorial solves a specific problem in a form developers use, earning discovery through that usefulness. Content is part of the product evaluation.
Publication is therefore a midpoint. The content must be shaped for both discovery surfaces and distributed through trusted forums, open-source repositories, developer newsletters, and review platforms as appropriate. Citations, activation rates, and AI referral conversion then feed the next brief. What questions found an audience, and which answers helped someone take the next step? Sending those results back into pain-point capture lets the next round build on the last, instead of starting another batch of content from scratch.
Why a governed AI pipeline is the only way to run this loop at the speed it requires
Research, drafting, review, distribution, and performance feedback must keep moving together. A traditional content team cannot sustain the required cadence merely by expanding its publication queue. Yet unreviewed AI output is no answer either. Developers can recognize filler, and faster production does not compensate for a tutorial or explanation that fails their evaluation.
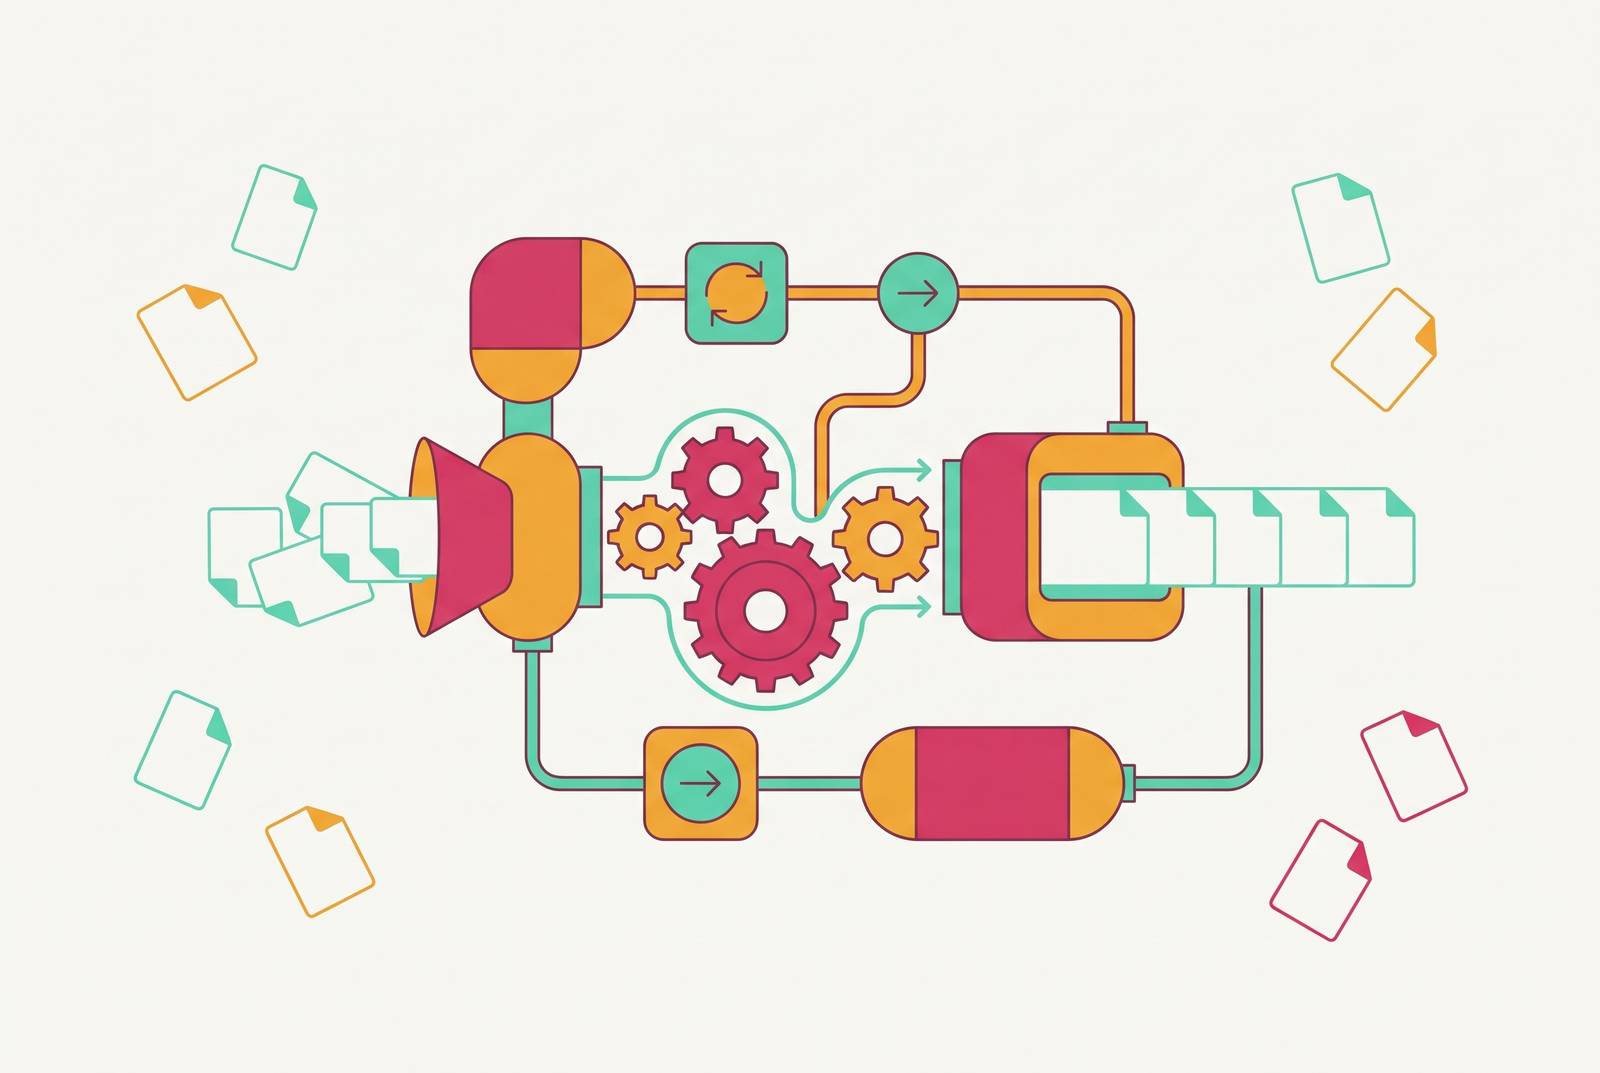
The production layer therefore needs a governed, multi-stage pipeline. Agents for research, drafting, critique, and publication operate against a shared content system that serves as the source of truth. Each stage has a distinct job to perform. This is different from giving a single AI tool a topic and accepting whatever comes back, because the architecture separates the work that gathers evidence from the work that drafts, challenges, and publishes it.
Human review belongs at the meaningful decision boundaries. Those gates include brief approval, post-research outline review, a pre-publish check, and a post-publish performance trigger. The repeatable middle can run through agents, while people retain control over direction and quality. Review is part of the pipeline itself. Leaving it outside the process would separate production from the judgment the system needs to produce something worth trusting.
Autonomy therefore requires control. Can the team decide which actions require approval and which agents may run unsupervised? A working pipeline makes those boundaries explicit rather than selling “set-and-forget” operation as an advantage. That governance also keeps responsibility attached to the full loop, so production speed does not become a goal detached from developer usefulness. More output is valuable only when the system can judge what it is producing and learn from the result.
Measuring the system, not just the content
Measurement has to reach beyond the published page. Brand Mention Rate, Citation Share of Voice, and Sentiment Polarity across AI platforms belong beside organic traffic and conversion rates. Traditional SEO dashboards do not cover this whole surface. A program can know how many people visited its site while knowing little about whether assistants mention it, cite its evidence, or describe its product accurately. Those blind spots sit upstream of many visits.
At a minimum, teams need to start by tracking conversions separately. AI referrals and Google organic traffic have different conversion profiles, so blending them obscures how each channel performs. An aggregate number may be arithmetically correct while describing neither channel well enough to guide a decision. Keeping them separate shows how discovery leads to business results. It also makes room for the possibility that lower traffic and better conversion can occur together.
Monitoring must be platform-specific for the same reason. Citation overlap between AI platforms is low, with analyses of tens of millions of citations finding that only a small minority of domains cited by one major assistant also appear in another’s citations. One engine cannot stand in for the rest. Treating its results as universal would reproduce the original mistake of assuming that success on one discovery surface transfers automatically to another.
The useful output is a set of questions for the next production cycle. Which questions about the product are being answered, which remain unanswered, and which answers are inaccurate? Those findings need to reach the people capturing pain points and approving briefs. A production service would not be run without observability, and a developer marketing program without AI citation monitoring makes the same class of mistake. Build the loop, instrument it, and keep its operation owned end-to-end.