The B2B Funnel Is a State Machine, Not a Journey
State machines replace the funnel's false flow with conditional buyer transitions.
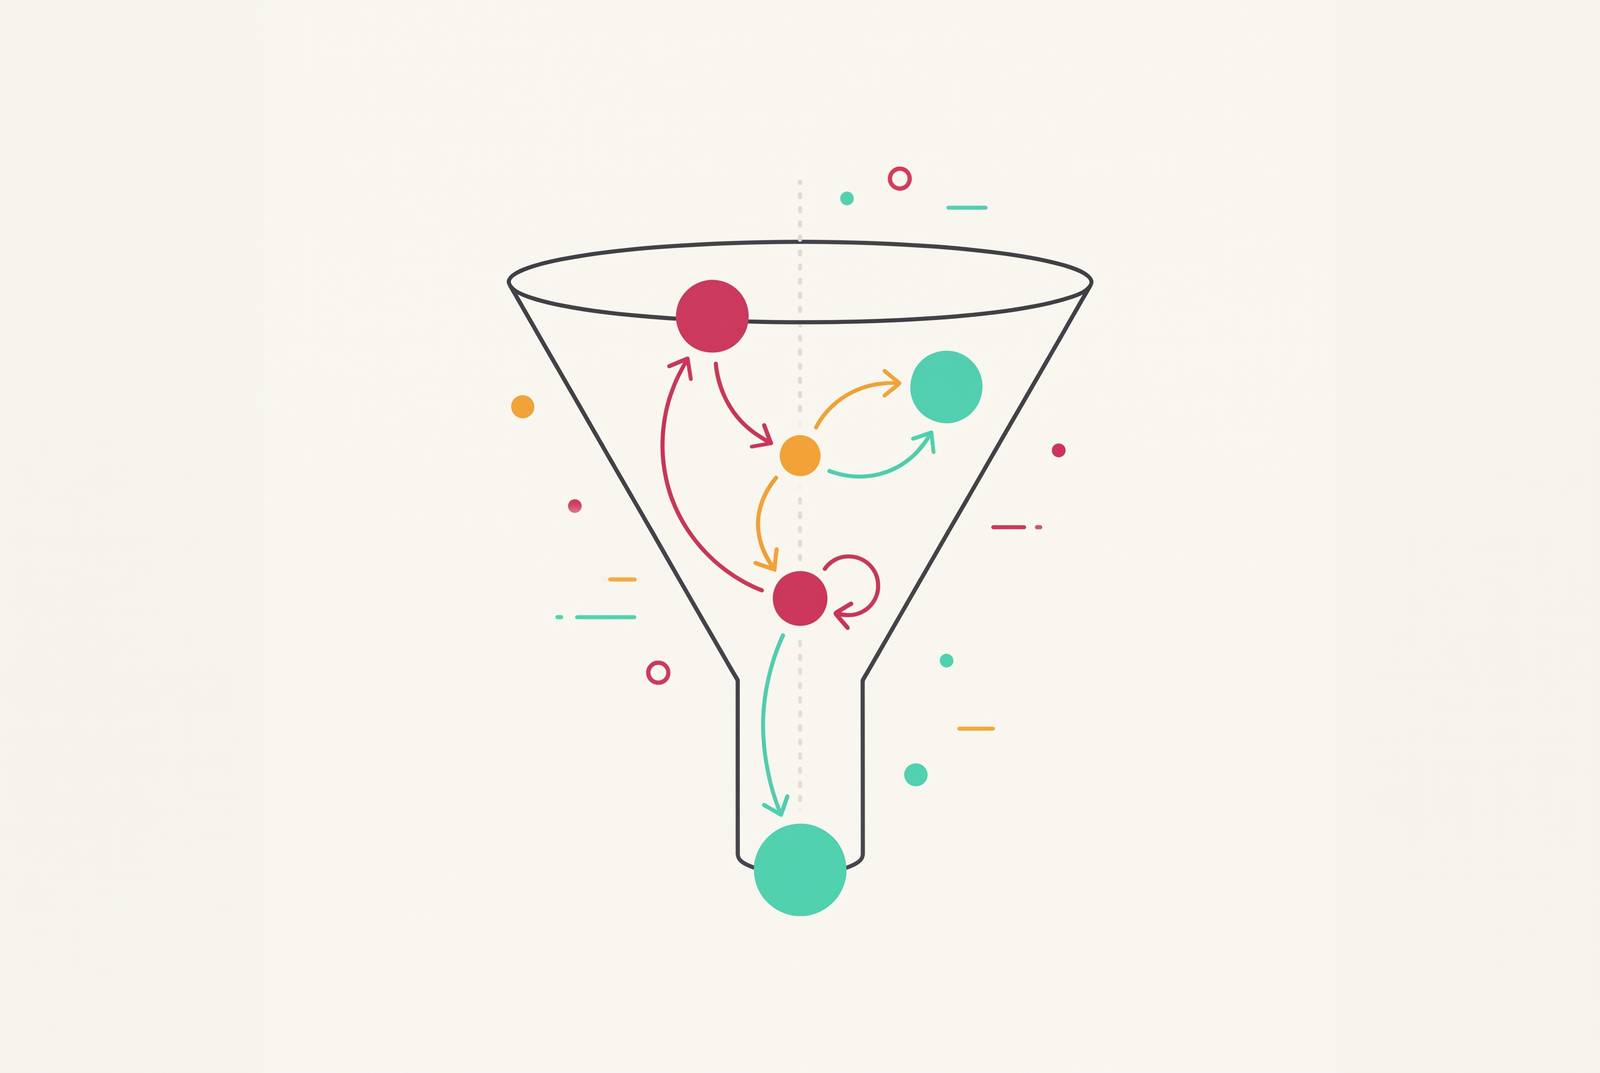
B2B buying is better modeled as a state machine than a journey. Buyers are in distinct states, and events move them between those states in more than one direction. For technical founders and developers building a marketing stack, that distinction changes the implementation. It replaces assumptions about where buyers should go next with defined conditions, evidence that can move them, and measurements that help explain why a transition failed.
Why the funnel metaphor breaks down as a model, not just as a strategy
A marketer keeps producing awareness content for buyers who already have a shortlist. The funnel says those buyers are at the top because they have not filled out a form or spoken to sales. But their research has already narrowed the field. The content answers a question they have finished asking. This is not simply a targeting mistake. It exposes a model that confuses what the vendor can see with what the buyer has done.
The funnel is useful as a measurement convenience. It groups visible activity into stages, but its narrowing shape implies an irreversible flow that buying does not follow. Buyers reconsider vendors, bring in new stakeholders, pause for months, and change priorities. A directed acyclic graph cannot show those loops. Adding “re-entry” and “nurture loops” acknowledges the problem without replacing the assumption underneath it.
Gartner describes buying as overlapping “buying jobs”. That framing leaves room for work to happen in parallel and for completed questions to reopen. The problem, then, is a category error. A position in a vendor’s pipeline is not a sufficient description of a buyer’s condition.
What a state machine actually is and why it fits B2B buying precisely
A state machine sets out discrete states, the legal transitions between them, and the triggers that move buyers from one state to another. Each part has a practical buying equivalent. A buyer might be “category-aware but vendor-agnostic,” have a “shortlist formed,” be “validation-seeking,” or be “stalled at legal.” Each needs entry conditions that establish what is true and exit triggers that specify what can change it.
For a given state definition, a buyer occupies exactly one state at a time. “Shortlist formed,” for example, means something different from general interest in a category. The distinction makes the model testable. If the entry condition has not been established, a website visit alone cannot justify assigning that state. Equally, a buyer can satisfy the condition without ever visiting the vendor’s website, leaving the state real but unobserved.
Legal transitions are the changes the model allows. Movement can be forward, backward, or sideways without becoming an exception. A new stakeholder can reopen vendor evaluation, while a lifted budget freeze can release a stalled purchase. The trigger is the event that changes the condition. Time passing or a lead score crossing a threshold does not, by itself, establish that the buyer has changed state.
Buying committees make this distinction more important still. IT, operations, finance, legal, and end users do not share a single mind. Each person can be in a different state, while a group-level transition needs a set of conditions to be met across those people. A state machine can define the conditions deterministically without claiming that people behave predictably or that vendors can observe every condition.
How the shortlist state forms before vendors have any data on it
The transition from “vendor-agnostic” to “shortlist formed” can happen before a vendor knows a deal exists. Buyers read case studies, check reviews, and ask peers in Slack and Discord groups before they get in touch. None of that requires a vendor conversation. When the first visible interaction arrives, the buyer may already be testing a preferred set of options.
What buyers do out of sight is often called the dark funnel. Peer communities, private LinkedIn groups, AI-assisted research, and review platforms help assemble the shortlist outside conventional attribution. Calling it dark identifies a visibility problem, but does not specify what happened there. A state definition goes further. It separates the question of whether a shortlist exists from the question of whether the vendor has evidence that it exists.
AI-assisted research widens that gap because buyers can ask ChatGPT or Perplexity to summarize capabilities and help draft RFPs. A generated answer can replace a series of visits to vendor sites. Whether a brand appears depends on its representation across public sources. The vendor’s session analytics do not reveal the resulting change in the buyer’s evaluation.
How can a team work on a transition it cannot see? Naming the state makes the missing evidence explicit. The team can distinguish buyer research from its own record of that research. It can then ask an engineerable question. What evidence does an AI answer engine need to support a transition from “vendor-agnostic” to a shortlist that includes the vendor?
Engineering the AI-mediated state transitions your analytics cannot see
Generative engine optimization, or GEO, addresses that question by placing evidence where AI-mediated research can use it. In state machine terms, the work targets the conditions that support a transition. It is not a separate discipline bolted onto the model. When an answer engine serves as the buyer’s research interface, its synthesis becomes part of the evidence through which buyers define a category, compare vendors, and check claims.
Different states need different kinds of evidence. For a category-aware, vendor-agnostic buyer, a comprehensive and authoritative category definition explains the problem domain or architecture pattern. For a comparison-seeking buyer, structured comparison content with tables that spell out the criteria makes it easier to weigh the differences. For a validation-seeking buyer, third-party coverage from trusted sources, including unlinked mentions, does more to help check vendor claims than links on low-authority sites.
The distinction changes what a piece of content is trying to accomplish. A category definition can explain a problem without establishing why a particular vendor belongs on a shortlist. A comparison can make differences clear without giving the buyer independent validation. Neither failure is solved by calling the page “mid-funnel.” Teams can usefully ask whether the evidence satisfies the condition needed for the next allowed transition.
There is an important limit to this framing. AI citations are not deterministic, and strong content does not guarantee inclusion in an answer. A vendor cannot make a buyer change state just by publishing a page. The model defines the conditions to investigate. Teams therefore need controlled experiments on trigger content, citation-rate measurement across models, and iteration based on the results. Before that measurement can be useful, however, the content itself must have a clear state-specific purpose.
Building content that serves specific states, not an undifferentiated funnel
A small technical team cannot meet every evidentiary requirement by producing more of the same article. A commercial comparison has a different job from a self-contained definition, even when both discuss the same product category. Treating them as variations of one template erases that distinction. A practical content architecture separates the jobs before it scales production.
On the owned site, one part serves Google organic search with commercial category pages and high-intent comparisons. Another serves LLM citation through definitional content, entity relationship pages, and brand authority signals. Both belong to the same business, but they are different editorial products. The transitions these pages are meant to support decide what evidence each needs. That gives a small team a clearer production target than an undifferentiated publishing quota.
Grounding pages also require a different writing discipline. The recommended pattern is no adjectives, one fact per sentence, and visible Created, Updated, and Verified timestamps. An LLM may cite a passage or a single sentence. A sentence that relies on surrounding paragraphs for its meaning is less useful than a self-contained alternative that states the same fact clearly.
Multi-stage AI pipelines can make this range of content economically viable for small founding teams. Human review gates are essential to that approach and need to be quality checkpoints within production. The highest-leverage intervention is outline review. Before the system writes thousands of words, an editor can check whether the planned evidence meets the needs of the intended state.
For a team adopting this architecture, the lesson is to review the plan against the state’s evidentiary requirement before approving generation. Does the outline define a category, support a comparison, or validate a claim? Those purposes can overlap, but they should not be interchangeable by accident. This makes human review a targeting control. It catches a mismatch while the team can still change how the content is built as well as improve its sentences.
Observing and instrumenting the state machine once it is built
Standard analytics record clicks, form fills, and session paths. Those signals can be useful, but they do not directly describe state entries, dwell times, or transition triggers. The gap is especially clear in AI-assisted research. Only a small fraction of AI brand mentions include clickable citation links that appear in conventional analytics. A buyer can find and weigh up a vendor without leaving the referral a journey-era dashboard expects to count.
Citation rates vary across ChatGPT, Perplexity, Gemini, and Claude, so visibility on one does not establish visibility on the others. Microsoft’s Bing AI Performance Dashboard, public since February 10, 2026, provides data on citations and grounding queries. Microsoft notes that the Grounding Queries metric shows only a sample of overall citation activity, which limits what that signal can establish.
To instrument these hidden transitions, teams should conduct monthly manual audits of top commercial prompts across ChatGPT, Perplexity, Gemini, and Google AI Overviews. The record should capture whether the brand appears and in what context. These audits are proxies. A prompt can suggest a comparison-seeking or validation-seeking state, while the answer shows whether the vendor appears in the evidence available at that condition. It cannot prove that a particular buying committee changed state.
Entity presence tracking adds another view of the evidence available to answer engines. This includes Wikidata, Wikipedia where it applies, and coverage on more than one third-party platform. LLMs can be used to check entity coherence across sources, but that requires deliberately engineered grounding pipelines. Tracking the sources therefore complements answer audits without replacing them.
Comparison-content measurement should likewise follow the transition it is meant to support. Teams should track which comparison pages generate AI citations, at what citation depth, and for which query clusters. This connects a content input to an observable result. Together with the audits, it supports controlled changes to trigger content instead of changes based on where a buyer supposedly belongs in the funnel. Each state needs a clear signal that teams can observe, with uncertainty made clear when they cannot observe the state itself.
That uncertainty sharpens the distinction between a failed transition and a failure to observe one. When a deal is lost, the question becomes which condition was not satisfied and what evidence was missing at the exit. Did the vendor fail to enter the shortlist, or did its claims fail validation? A state machine makes those different failures legible, so the next change can address the missing evidence.