Programmatic SEO Is Now a Commodity Layer. Here's What Comes After.
Proprietary data, not page generation, now determines programmatic SEO success.
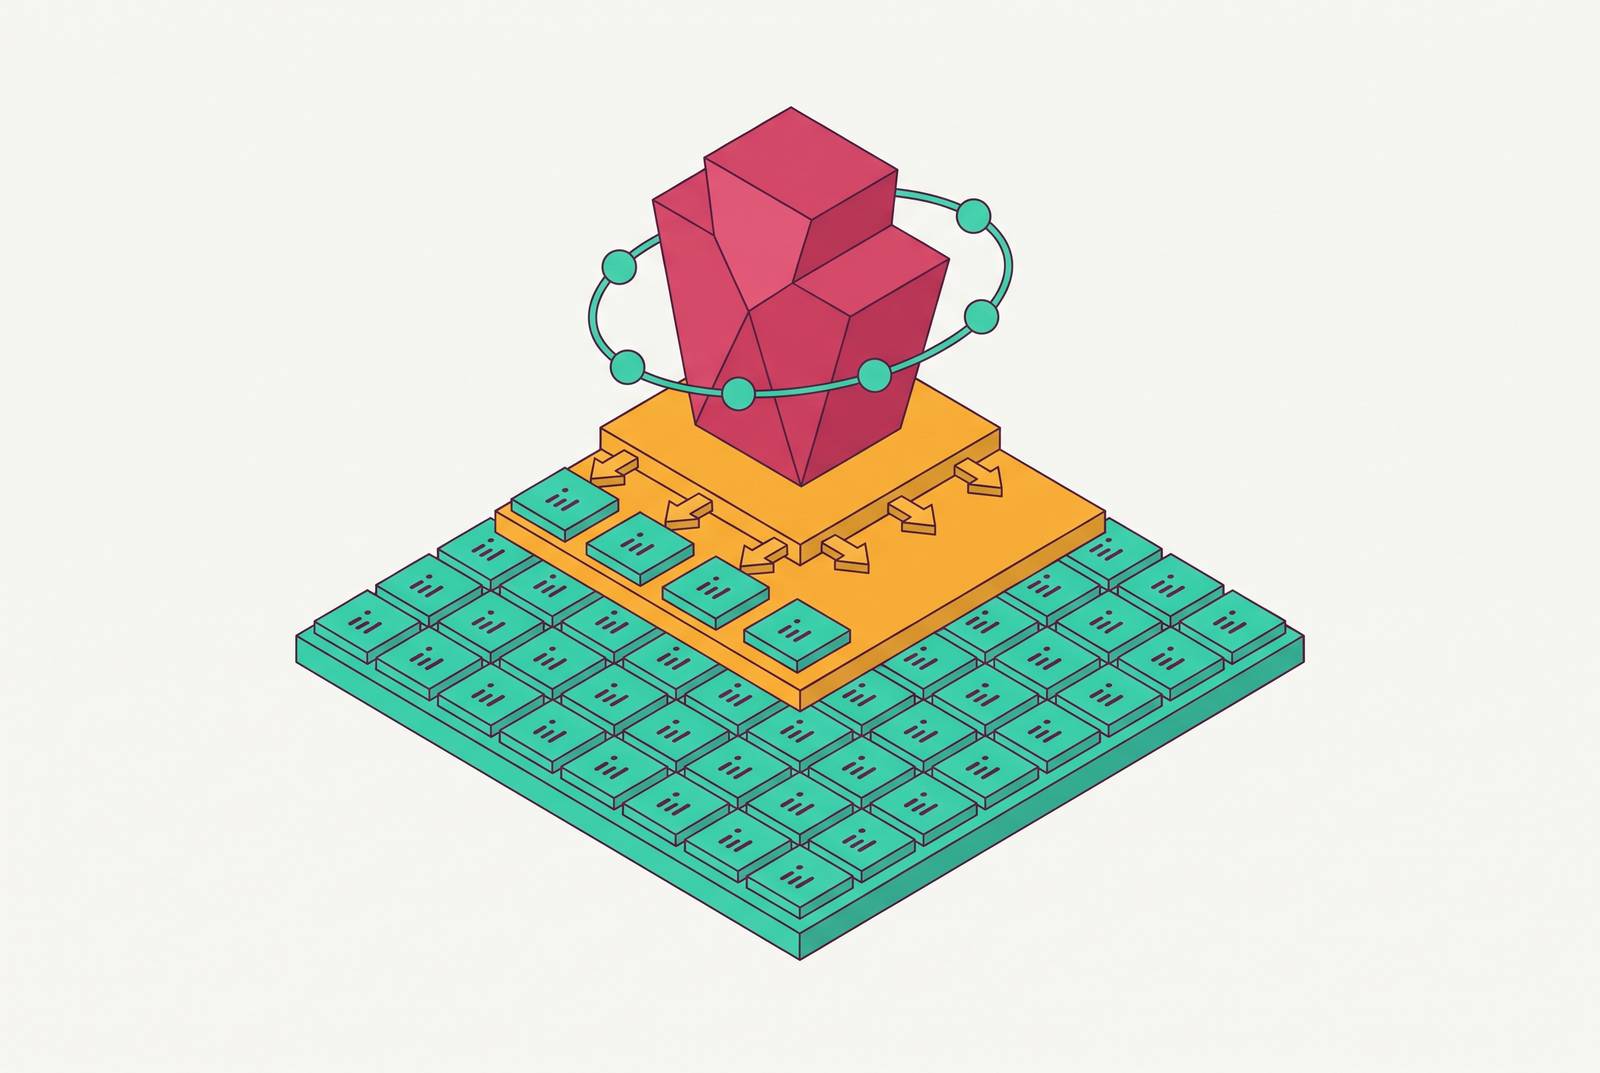
Programmatic SEO has become easier to build and harder to defend. Its page-generation machinery is now a commodity, so the advantage has moved to the facts that feed it, the judgment that shapes them, and the ability to earn citations in AI answers. What comes after is a system that makes owned knowledge useful, identifiable, and measurable across search and AI.
How programmatic SEO's page-generation layer became a commodity
Programmatic SEO originally gave small teams a way to reach search territory that manual publishing could not cover at comparable cost. A structured data source supplied the facts, a template arranged them, and a rendering engine produced pages for long-tail queries. Execution speed was the edge. A team that could connect those parts could publish useful pages while competitors were still assembling them by hand.
WordPress bulk-automation stacks, CSV-to-template pipelines, and LLM generation layers put the same basic capabilities within reach of any growth team. When competitors can build the same pipeline with off-the-shelf tools, the pipeline alone gives one site little edge over another.
Google’s scaled content abuse policy increased the risk of confusing production capacity with usefulness. With the March 2024 spam update, the policy made thin content produced at scale a risk, even if it was cheap to try. Google’s May 15, 2026 spam-policy clarification extended its application to AI Overviews and AI Mode. The distinction is between scaling evidence and scaling repetition. Automation can do either, so its presence alone says little about a program’s value.
What the four-layer stack looks like now that it has stabilized
A mature programmatic stack contains four layers with different jobs. The data layer holds raw, verifiable facts, including product names, live pricing, integration specifics, and entity attributes. The AI layer turns those facts into contextual content for each page. The template layer renders the result into HTML with schema markup, internal links, and meta tags. Finally, the quality layer checks uniqueness, readability, and schema compliance before publication.
Structured data supplies the facts, while templates give the pages a consistent layout. AI enriches selected fields. Human review sets publication thresholds and rules for edge cases, because passing a validation script is not the same as answering a useful question.
Zapier illustrates the distinction between filling a template and documenting something real. Its programmatic pages describe specific integrations, including the triggers, actions, and use cases available for a particular combination. The integration is the reason the page exists. A language model cannot reconstruct those underlying facts from a prompt alone, even if it can produce convincing prose about connecting applications.
Where, then, does the stack differ between teams? The template and automated quality layers are now table stakes, while the data and its use in AI-generated analysis vary substantially. A better generation layer can make facts easier to understand, but it cannot substitute for facts the program does not have.
Why proprietary data, not page generation, is now the actual moat
The shift toward proprietary data is here to stay because cheaper generation helps every team that can buy the same tools. It does not give every team access to the same information. A defensible dataset has two linked properties. It cannot be reconstructed from a prompt, and it supports answers that another site cannot fully supply.
A city-name swap fails that test when nothing else on the page changes in a meaningful way. A competitor can reproduce the content without learning anything new about the city or the reader’s need. The same goes for keyword variations with explanations that could fit any page. More pages may create more indexable addresses, but they do not create an exclusive reason to consult the site.
Does that leave companies without vast integration databases at a disadvantage? Even a small dataset can be proprietary. Original research with specific, verifiable findings qualifies, as does real customer outcome data. Structured product attributes that exist nowhere else on the open web can also provide the raw material for distinctive pages. The test is reconstructability.
That test changes the role of editorial judgment. Instead of asking how many variations a topic can support, a content team asks which questions its evidence can answer better than publicly available material. This makes page generation a delivery mechanism for knowledge. Yet exclusive evidence is only the starting point. It must now work on a visibility surface that does not simply reward a position in search results.
How AI answer engines created a parallel surface that search rank doesn't reach
ChatGPT, Perplexity, Google AI Mode, Claude, and Gemini give readers a synthesized answer. That changes what it means for content to be visible. A search result competes for a position and a click, while a source in an AI answer competes to support a statement. Winning one does not automatically win the other.
A page can be indexed and rank without supplying the clear, reusable evidence an answer engine needs for a particular response. Search rank therefore cannot stand in as proof of AI visibility.
The economic consequence follows from that change in delivery. Many informational AI sessions end without an external click because the answer itself satisfies the immediate need. Citation and referral traffic can therefore diverge. A brand may be named or its research used without a visit appearing in its analytics, which makes click volume an incomplete account of its presence.
The old measurement lens covers only part of the new surface, with traffic still relevant and the commercial value of citations varying. Evaluating a page now involves checking whether it attracts visitors and whether an answer engine uses the page’s evidence and connects that evidence to the right brand.
What content needs to do differently to earn citation in an AI answer
Content earns a place in an AI answer by providing statements that are extractable, consistent, and grounded in named, verifiable facts. Mere availability is not enough. An indexed page may contain plenty of prose but few clean statements that a model can reuse with confidence. Weak or contradictory evidence can leave an aspect of the question unanswered.
For a content team, the practical response is to publish original research as a “Data Node,” a page containing specific evidence about a defined topic. Its role is to ground an answer that generic coverage cannot fully support. If a question depends on findings available only there, that page becomes the necessary source for those findings. This creates a citation dependency, although it does not guarantee that every model will retrieve or cite it.
The distinction is between owning a topic and owning evidence. A generic article about a shared subject competes with every other explanation of that subject. Original data gives the page a different function, because it supplies something the answer cannot obtain from interchangeable summaries. Editorial work then makes that evidence clear enough to extract without stripping away the context needed to understand it.
Owned content is not the whole picture. Ahrefs’ brand-correlation study found that branded web mentions correlate more strongly with AI visibility than backlinks do. That is a correlation that leaves unproven whether a mention causes citation, but it supports treating off-site presence as part of the system. The relevant opportunity is a mention in publications an answer engine treats as trusted sources within the field.
Entity consistency connects those mentions to the right organization. A brand without a Wikidata entry risks confusion with similarly named entities, though absence does not make it invisible. Conflicting claims across schema, LinkedIn, and a homepage create another identification problem. If those signals do not describe one coherent entity, even strong evidence can be harder to attribute confidently.
How to measure whether AI answer engines are actually citing and naming you
Citation needs its own instruments because a traffic report cannot record an appearance that produces no visit. Teams can track citation rate per tracked query, share of voice in answers across engines, and branded search volume lift. Each answers a different question. Citation rate shows whether the source appears, share of voice compares that presence with competitors, and branded search lift hints at what people want to do next.
An answer can name a company without linking to its evidence, so treating the two as identical obscures what the content program is achieving. The same distinction applies across ChatGPT, Claude, Gemini, and Perplexity. An aggregate result is useful, but it should not imply that visibility on one engine establishes visibility on all of them.
Several tools now address this measurement gap. SE Visible from SE Ranking tracks brand footprint across ChatGPT, Gemini, AI Mode, and AI Overviews, with sentiment monitoring and competitive benchmarking. CrunchJunkie’s homepage and comparison pages say every plan has brand-mention and source-citation tracking across ten engines, including the €14/month entry tier. Its FAQ lists nine, however, so the advertised scope is not consistent across its product materials.
First-party reporting offers another view, though not a complete one. Microsoft’s Bing AI Performance Dashboard has been public since February 10, 2026 and provides signals on citations and grounding queries. Microsoft explicitly describes the data shown as a sample of overall citation activity. That qualification limits what can be concluded from the dashboard, particularly when an absence might otherwise be read as evidence that no citation occurred.
For teams building a free traffic baseline, GA4 can segment sessions whose source contains “perplexity.ai,” “chatgpt.com,” “claude.ai,” or “you.com.” This shows when AI referrals produce visits. It cannot count the citations that never turn into clicks, so it systematically captures only part of the activity. The recommended complement is regular querying of answer engines, recording whether the brand is named and whether its sources are cited.
Direct citation tracking shows where sources appear in answers, while traffic data shows the visits that follow. Branded search volume adds a further signal with uncertain attribution. Share of voice in AI answers is therefore the measure of competitive visibility on this surface, while referral traffic remains a measure of one downstream response.
What the intelligence layer looks like when it is built to compound
The differentiated system connects proprietary data, publishing cadence, editorial judgment, and citation measurement in a closed loop. Its next publishing decision depends on what the previous cycle revealed. Citation-rate data informs which data nodes to publish next, which entity signals need cleanup, and which off-site placements to pursue. Without that feedback, AI-focused publishing can fall back into chasing volume, even with a new metric.
Human review belongs throughout the loop. Editors decide which pages are ready to publish, which claims need checking, and which signals call for a change of course. Automated checks can enforce rules, but people use judgment to set those rules and deal with cases the rules do not cover. Multi-stage AI pipelines that pair generation with human review, while remaining reversible before publication, make room for that distinction.
The same shift changes what a defensible service offering looks like. Content volume alone is easy to compare with what a client can generate from a prompt and a template. Systems work addresses the harder parts, including programmatic content audits, editorial QA workflows, dataset cleanup and enrichment, and citation monitoring. Its value lies in connecting those functions so that evidence can change the publishing process.
The site must also serve three audiences with different needs. Human readers need explanations that answer their questions, search crawlers need pages they can access, and AI agents need evidence they can retrieve, identify, and tie to a source. Those needs overlap around clarity and factual specificity, but they are not the same job. A publishing system that treats them as interchangeable can miss what each surface requires.
New evidence gives the site something distinctive to say, editorial judgment makes it usable, and citation tracking shows where that usefulness is recognized. Page generation remains essential machinery, but it no longer has to bear the weight of being the advantage.