Programmatic SEO Is a Growth Engineering Problem, Not a Content Problem
Success depends on data quality and indexation monitoring, not just page templates.
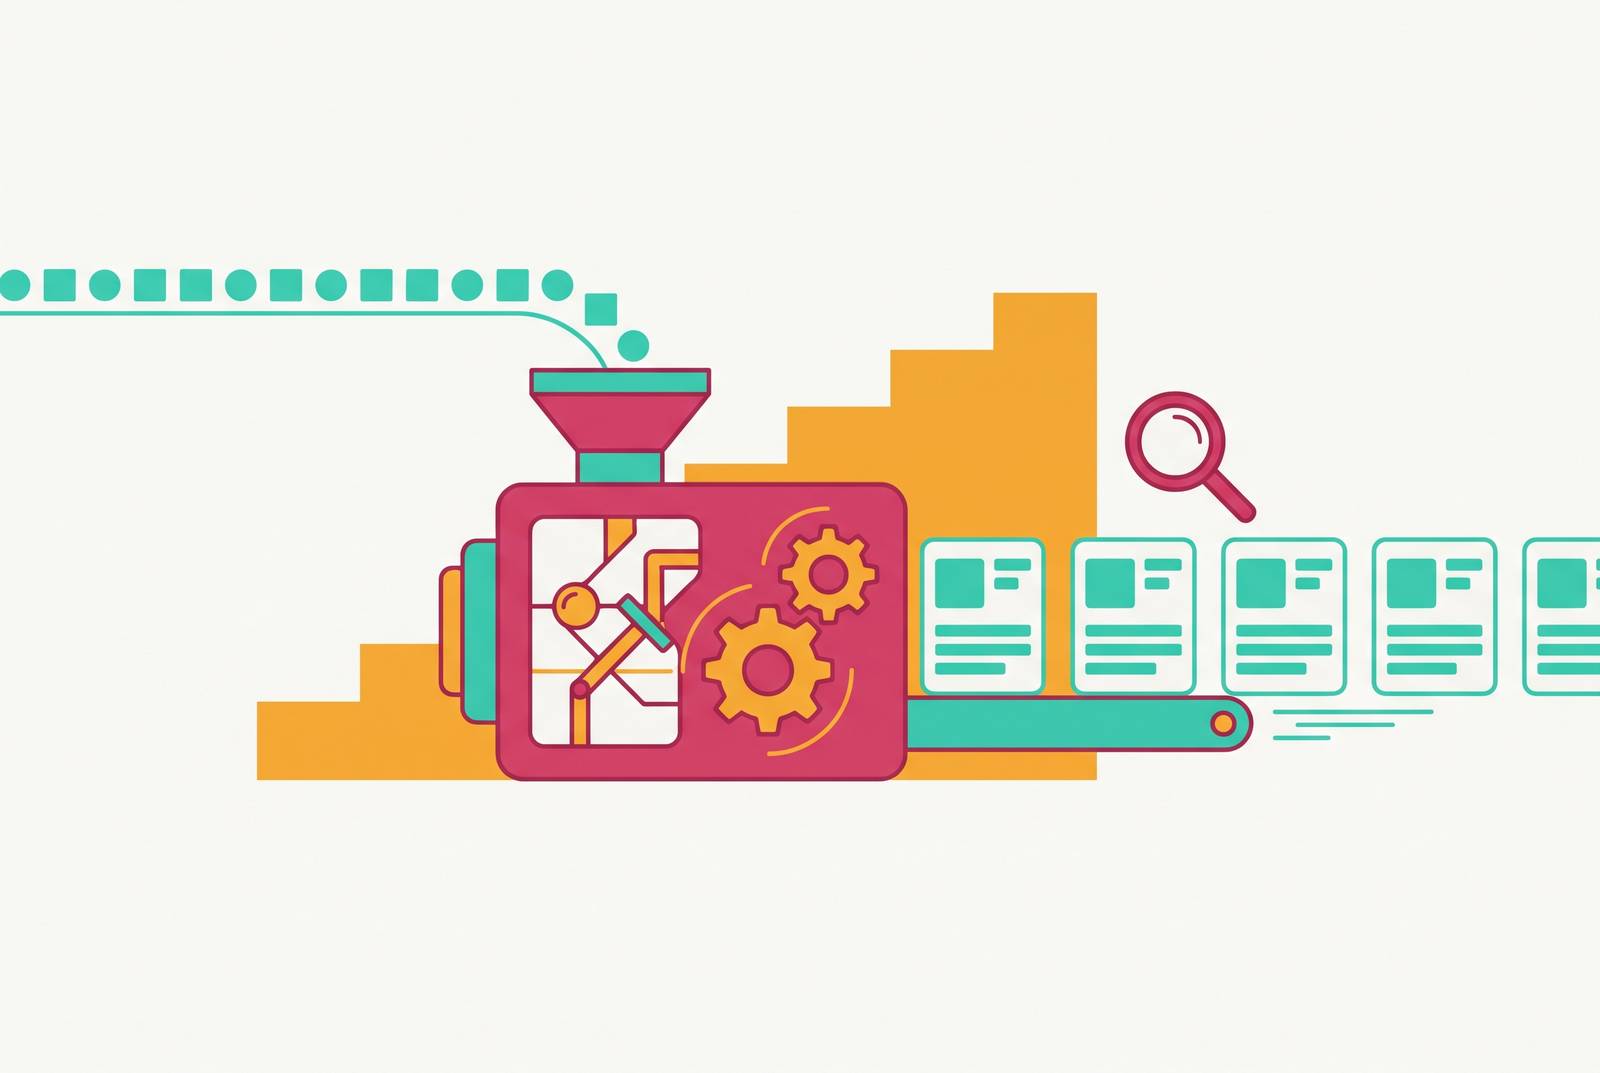
Programmatic SEO is a growth engineering problem because its results depend on the data, indexation, and measurement layers as well as the page template. A system that publishes thousands of pages has demonstrated only that it can publish at scale. To turn those pages into growth, teams need to measure what search engines accept, what AI engines cite, and which records need enrichment or removal.
Why programmatic SEO belongs to engineering, not content
A content team might describe a programmatic SEO program as a template that produces pages for a keyword pattern. An engineering team would describe the same program as a dataset, a rendering system, and an indexation monitor. The difference changes what gets built and maintained. In the first view, the finished page is the product. In the second, the product is the system that turns useful records into discoverable answers.
One keyword pattern maps to a structured dataset, each row maps to a URL, and a template renders those rows into pages. A quality gate decides which records are ready to ship, while indexation monitoring shows what search engines accept. That makes data acquisition, schema design, template architecture, internal linking, dynamic CMS integration, and index management central skills.
High-quality pages can be made programmatically when each record has something useful to offer. Automation still leaves a wait for discovery and ranking. It shortens the publishing process. Output volume alone says little about whether the program works.
Where the data layer wins or loses the program before a single page ships
A template is easy for a competitor to copy. A proprietary dataset is much harder to reproduce, so the strongest advantage sits beneath the page. A program built on a commodity list has little protection from another team using the same inputs. Better wording cannot make records different when they contain the same information.
Zapier’s app-integration pages show how this works, with actual triggers, actions, and pre-built Zaps for a pair of apps. Wise’s currency-conversion pages have a live mid-market rate, a calculator, fee comparisons, and a historical chart. Neither page’s usefulness depends chiefly on an introductory paragraph. The data and functionality give the visitor a reason to come to the page, while the template makes that information easy to use.
If two rows lost their keyword swaps, would they still produce meaningfully different pages? If not, the dataset is not ready. More variations in phrasing in the template cannot resolve the underlying records’ failure to justify separate URLs.
A minimum data-density gate makes that judgement operational. A record can be required to have at least six populated attributes and sufficient unique content before publication. Populated fields alone are not proof of usefulness. The gate also needs to test whether those fields give the page substance that its neighbouring pages do not already provide.
What Google's scaled content abuse policy actually tests, and what it doesn't
Under Google’s scaled content abuse policy, pages need to give people useful information, even when automation helped make them. Authorship is not a substitute for usefulness. Google’s Helpful Content system operates as an always-on classifier, so thin templated pages face an ongoing quality test.
For a 2026 program, the proposed shipping standard has five parts. Each page needs a first-party data point unique to it, a unique narrative section not generated from the template, genuine internal linking, structured data markup, and a reason to exist beyond SEO. These are engineering acceptance criteria as well as goals for editors. A page must meet them before it enters the crawl queue.
The last condition is the most probing one. What would the page help someone do if search traffic were not available? A useful comparison, a calculation, or a distinct answer gives the record a purpose. If the only answer is “target another keyword,” the missing ingredient is per-page utility, and neither manual authorship nor fluent generated text repairs it.
The indexation gate: the engineering chokepoint that content thinking misses entirely
Page count shows how many pages a team has made, while indexation rate shows how much of that work reaches the search index. Many programs publish more pages than their indexation health can support. Their templates may render correctly and their URLs may be live, but much of that work is still outside search. Publication is therefore the wrong finishing line.
“Crawled, currently not indexed” deserves particular attention. Google has seen the page and declined to index it, so treating that status as merely a crawl-budget problem misses the quality signal. “Discovered, currently not indexed” is a different state and needs to remain distinct in reporting. An aggregate total can hide those differences, leaving a team unable to tell which URLs need attention or how their status changes over time.
The engineering response is continuous URL-level monitoring through Search Console’s page indexing report. Releases should arrive in crawlable batches rather than all at once, with indexation tracked as a time-series. That makes the gate observable after publication. Without it, a team cannot connect a weak batch to its records or template pattern, and publishing more pages only expands the unmeasured part of the system.
Discovery also needs its own infrastructure at scale. Once a site exceeds about 50,000 URLs, a sitemap-index file should point to multiple sub-sitemaps, each below the per-sitemap URL limit. Material dataset changes should trigger regeneration because stale URLs waste crawl budget and missing ones delay discovery. Before discovery begins, though, thin records should be kept from being rendered into pages. For pages already live, enrichment or noindexing belongs in the maintenance loop.
Schema markup as infrastructure for both ranking systems and AI answer engines
Once a page is available to retrieval systems, those systems still need to understand what it describes. Schema markup makes entity relationships explicit rather than leaving them entirely to inference from prose. It can identify a tool, its category, and its properties.
At programmatic scale, the schema should come from the same dataset that generates the page. Manually maintaining markup across thousands of URLs creates a separate upkeep burden. The page and its structured description need a common source. Otherwise, the program has automated publishing while leaving a key part of its machine-readable output dependent on manual work.
FAQ schema provides a direct connection to AI answers because answer engines frequently draw on structured question-and-answer content. A template that generates it from dataset fields feeds that channel systematically. The questions still need useful answers grounded in the record. Markup can make information clearer, but it cannot add information that the dataset does not have.
For a GEO-aware template, the recommended page structure includes a direct factual answer near the top, at least two cited statistics with named sources, FAQ schema, and “last updated” timestamps tied to data refresh cycles. These elements connect the visible answer to its evidence and freshness. The same engineering layer that describes a page for search can therefore feed structured knowledge to AI retrieval. A separate measurement system is needed to check whether those engines use it.
Why AI citation and search ranking are different engineering problems that require different instrumentation
A strong search ranking does not automatically produce an AI citation. Conversely, AI engines can cite URLs that do not rank prominently for the original query. The two channels overlap without being interchangeable. A program measured only through Google rankings leaves part of its potential distribution unexamined, even if its search reporting is otherwise thorough.
Source preferences also differ between AI platforms. ChatGPT favours encyclopedic sources, while Perplexity gives more weight to community platforms including Reddit. A competitor’s visibility in one engine cannot stand in for its visibility everywhere, and a single successful citation cannot establish a stable pattern.
What would a useful test look like? The tests should start with a standing prompt set that covers branded, category, and competitor queries. Those prompts run across platforms through an API or manual logging, so the program has a repeatable basis for comparison. The unit being tested is the answer produced for a query.
The scoring needs to capture citation frequency, mention position, sentiment, factual accuracy, and share of voice against competitors. These describe different aspects of the result. A mention can be prominent without being accurate, just as a citation can appear without giving the brand much visibility. Monthly tracking makes those distinctions part of an ongoing record. That is the practical difference between adding an AI visibility label to SEO reporting and instrumenting a separate channel.
The AI content generation layer inside a pSEO pipeline and where human review is non-negotiable
AI generation belongs at the prose layer of a programmatic SEO pipeline, writing surrounding explanations, transitions, and formatting while the record supplies the page’s substance. Fluency does not create a defensible asset. If removing everything the AI wrote would remove most of the page’s usefulness, the program has placed its value in text that a competitor could reproduce with a similar prompt.
The pipeline should have separate stages for data sourcing, AI generation, human review and enrichment, and quality monitoring. Each stage needs a clear input and output. That separation makes review a required step before a page is published, including more than a check of its wording. It also keeps the question of factual substance distinct from the question of readable presentation.
Human review adds the experience layer, checks claims against primary sources, assesses E-E-A-T requirements, and applies the final edit. It also catches defects that are easy to overlook when reading only for style, including undefined fields, broken pluralisation, and empty sections. A broken field expression can affect every page in a batch, so sampling can help find template faults that repeat across pages.
The review gate cannot be replaced by a judgement that the prose sounds convincing. AI text should supply a minority of each page’s unique value, with proprietary data providing its defensibility. Review then checks whether the generated explanation stays true to that value and whether the template renders it correctly. The human gate is an engineering control that keeps the pipeline’s output auditable.
Measuring the program as a live system, not a completed project
After launch, teams need at least URL-level indexing data, AI referral traffic, and citation tests that run again over time. Google Search Console has the page indexing report, and Google Analytics 4 tracks referrals from AI platforms. Those referral sources include chatgpt.com, perplexity.ai, gemini.google.com, claude.ai, and copilot.microsoft.com for Copilot. Referrals and citations answer different questions. The standing prompt set is still needed to observe answers that traffic reporting alone does not describe.
Pages left in “Crawled, currently not indexed” beyond a defined period should be enriched with additional data or noindexed. A large rejected tail should not remain untouched simply because the pages cost effort to produce. When a template pattern has a low indexation rate across a batch, the useful response is to audit that batch’s data density.
The AI loop needs the same operating discipline. Citation frequency, mention position, sentiment, factual accuracy, and share of voice should be benchmarked at launch across ChatGPT, Claude, Gemini, and Perplexity, then tracked monthly. A drop in citation frequency is a signal to examine structured data or authority signals, just as falling Search Console impressions call for investigation of indexation or ranking.
Volume is a lagging indicator, while indexation rate and citation frequency are leading ones. Teams that use those signals to prune, refresh, and revise are running a growth system. Teams that stop at publication have only made more pages.