Programmatic SEO Is a Data Pipeline Problem, Not a Template Problem
Success depends on rich data sources, not better templates.
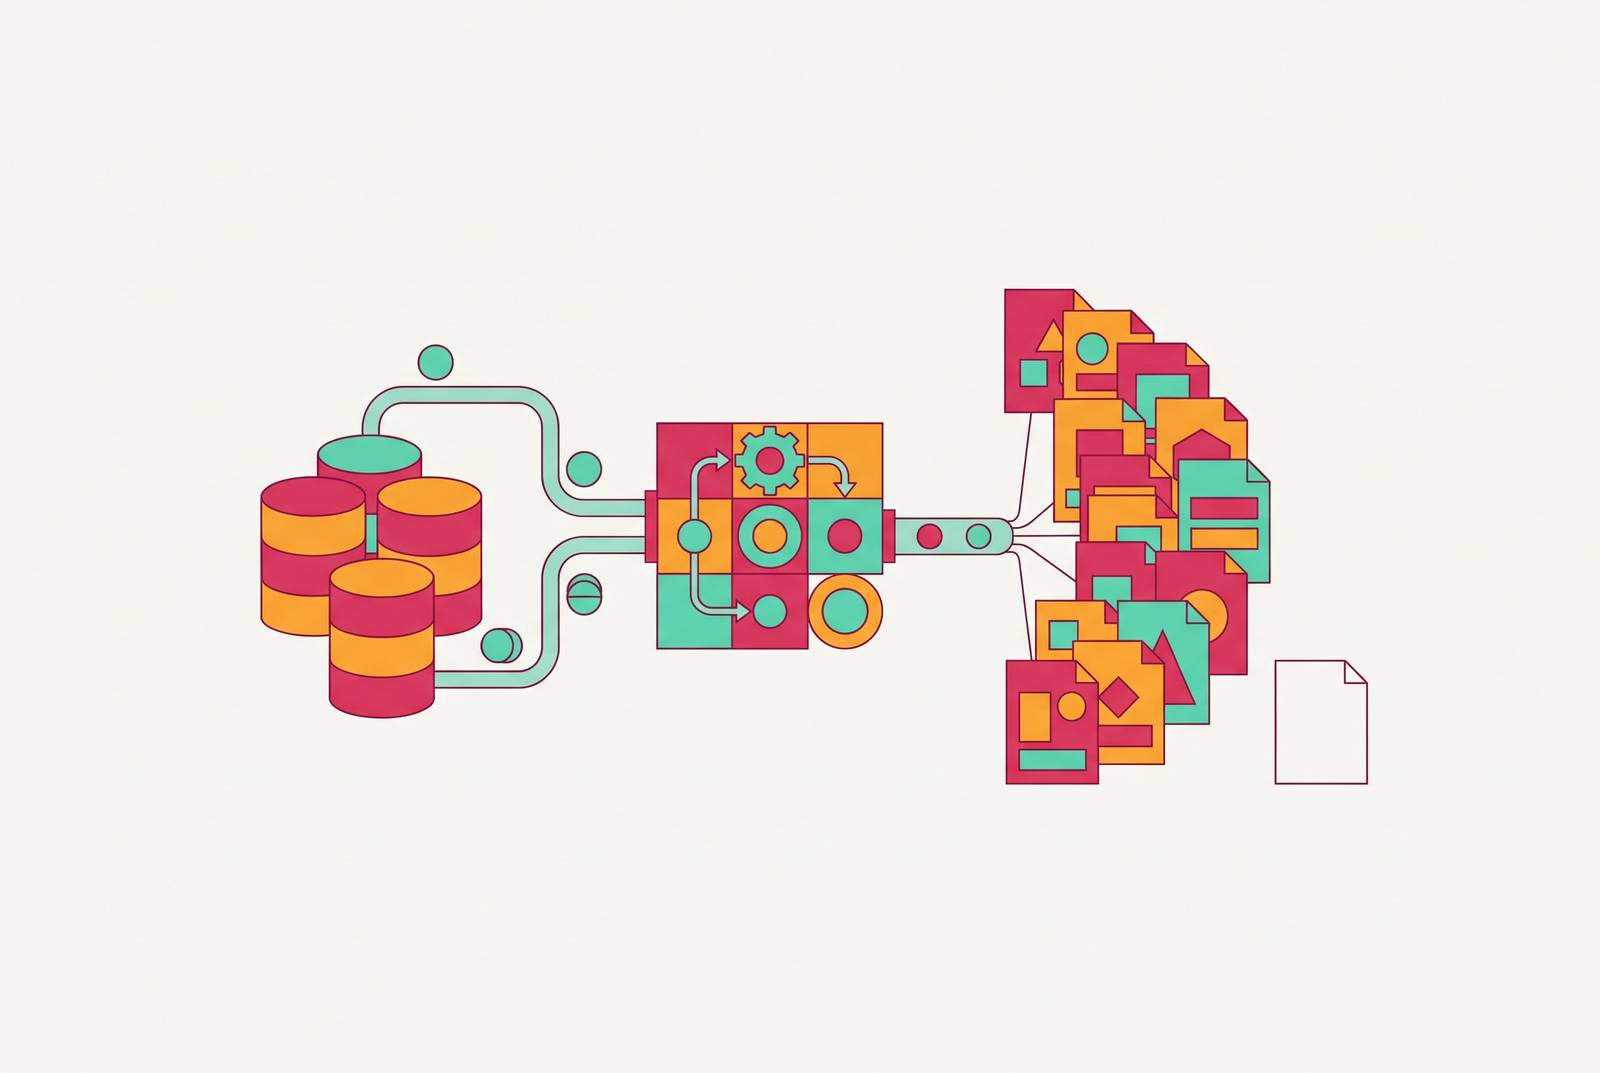
Programmatic SEO is a data pipeline problem before it is a template problem. Programs survive when their records contain enough distinct, current, verifiable information to justify the pages they generate. That shifts the main work upstream, toward sourcing, validation, enrichment, and refresh.
Why most programmatic SEO programs die at the data layer, not the template
Deindexation and traffic collapse can make a programmatic SEO team question every choice in its page design. Were the headings too similar? Did the pages share too much wording? If the records contain little beyond an entity name and a few common attributes, the resulting pages have little reason to exist separately.
The dominant weakness is not template architecture but thin source material. A record needs enough depth, uniqueness, and verifiable attributes to support a useful page. Differences in wording may make sibling pages look less alike, but they cannot give a reader information that was missing from the source. The distinction is between a page that looks different and one that answers a different need.
Google’s scaled content abuse policy makes that distinction consequential. It treats content created at scale primarily to manipulate rankings rather than help users as spam, regardless of how it was produced. Human-written thin content is not exempt from that rule. Nor does AI assistance alone establish that a page is abusive.
What the three-layer architecture actually tells you about where to invest
Every programmatic SEO system has three layers, which are data, template, and page. The data supplies the facts, the template arranges them, and the page presents the result at a URL. That order establishes a dependency. The output cannot be more informative than the records allow, even when the template presents those records clearly. Yet teams often spend most of their time on the middle layer.
The investment priority follows from what each layer contributes. A scraped list of city names may give the template different labels while leaving the information unchanged. A proprietary dataset with added attributes that the common source lacks gives each page something of its own to say. Templates are easy to copy. That dataset is not. The lasting edge comes from the work it takes to gather, clean, and keep those facts up to date.
The page layer still has a defined job. It produces one URL per real query pattern, organised in a crawlable hierarchy. But that organisation does not rescue records that cannot support separate answers. The practical implication is to establish what the data can support before deciding how many pages the template can generate.
What a dataset needs to clear the quality bar — and the four ways records come up short
A suitable dataset is a structured record set. Each row needs enough unique, verifiable facts to distinguish its page from its siblings. The test is comparative as well as individual. A record can look complete in isolation while producing almost the same answer as every neighbouring record. What would a reader learn on this page that the next one cannot tell them?
Missing fields are the first way records fail that test. Required attributes are blank, so the renderer produces empty sections or placeholder text. A required-field check can identify the gap before publication.
Duplicate slugs create a different failure. Two records map to the same URL, producing a collision or a near-duplicate page pair. Checking the text alone would miss that relationship between the record and its URL.
Attribute poverty is harder to spot because the record may have no blank fields at all. It has a unique identifier but only two or three comparable attributes, leaving too little substance to separate its page from others. Completeness is not the same as richness. Enrichment must add facts that change what the page can answer, rather than simply adding columns that repeat information already present.
Staleness is the fourth failure, and even records that passed every other check at first can grow stale. The facts were accurate at ingestion, but no refresh mechanism keeps them aligned with changes in the underlying subject. Quality therefore has a time dimension. An audit needs to distinguish missing fields, duplicate slugs, attribute poverty, and staleness because each calls for a different repair. Treating all four as “thin content” hides where the pipeline needs work.
Data sourcing and enrichment as pipeline engineering, not a one-time collection task
Data sourcing becomes an operating responsibility as soon as the records describe things that change. The data can come from internal databases, third-party APIs, public government or industry datasets, and licensed feeds. The source varies with the project. The discipline remains to validate incoming data before admitting it to the record set that feeds publication, then enrich and refresh it on a schedule.
A legal directory that scaled to 200,000 pages illustrates the shape of that work. A Python ETL script ran weekly, pulling from state bar association databases, public court records APIs, and user-submitted reviews. It validated addresses, checked for duplicates, and excluded attorneys with disciplinary actions. The output was structured JSON, with one object per attorney.
TripAdvisor provides a different example of where the underlying asset sits. Its review database, rather than its page structure, supplies the depth that interchangeable templates cannot reproduce. The distinction is useful for travel comparison pages because their value depends on the information available for comparison. A common public source may show which entities exist. It does not necessarily supply the review depth or other attributes that make a comparison useful.
Enrichment is the work that separates those commodity records from defensible ones. Depending on the project, it can add compatibility data, pricing history, operational statistics, or review scores. The added facts need to contribute something distinct. If every competitor can reproduce a record from the same public source, rearranging that record offers little protection.
This also changes how build time should be allocated. Sourcing, cleaning, enrichment, and required-field gates form the variable-length phase, while template construction is comparatively fixed. Giving both equal time risks underfunding the less predictable work. Freshness belongs in that work from the start through scheduled dataset re-pulls, webhook-triggered updates on key fields, and last-updated timestamps in structured data markup. Otherwise, publication ends the process just when maintenance needs to begin.
The quality gate that replaces manual review at scale
A data-level quality gate checks records before they reach the renderer. Its checks include missing required fields, duplicate slugs, character-length violations, and attribute-count thresholds. A record can pass a length check and still lack useful attributes. Keeping those conditions distinct makes it possible to identify why a record is not ready for publication.
A missing field or empty section can recur wherever the same template encounters the same condition. Fixing the source of that defect addresses a whole class of pages. Sampling then helps check how validated records look when rendered, including language problems that keep coming up, such as a broken plural. The system replaces page-by-page review with validation and targeted inspection.
AI-generated opening paragraphs, FAQ answers, and comparison cells need a check of their own. Human review of the first batch of rows is necessary before scaling that generation. Data validation cannot perform every editorial function. The pipeline supplies distinctiveness, while human review examines the accuracy and experience layer relevant to E-E-A-T compliance. A populated field and a trustworthy answer are not interchangeable.
Publication also does not end quality control. Search Console’s page indexing report shows whether the generated pages are entering the index. A large set marked “Crawled — currently not indexed” is a data-quality signal that warrants investigation. Underperforming pages may need to be noindexed. If that signal goes unchecked, weak pages may drag down the rest of the domain.
Why programmatic pages now compete for AI citation slots, not just ranking positions
AI answer engines add a second selection test to Google’s ranking index. A page can be indexed yet offer few clean, verifiable statements that an answer engine can extract and cite. Indexation alone is not enough for citation. Data richness must therefore be paired with structural extractability, while contradictory or weak evidence can lead an AI system to abstain from answering. Using structured data markup and disambiguation to identify each entity the same way across the site also helps systems tell which entity a fact belongs to. Without that grounding, a page may be clear to a person but difficult for an entity recognition system to use. Freshness adds another requirement because current information is valuable to answer engines, making last-updated timestamps and field updates relevant beyond ordinary page maintenance. Those properties, along with the off-site authority signals that also help make a brand visible, have to come from more than changes to the template. The same investment in sound records can support both indexation and citation, but success on the first surface does not establish success on the second.
Measuring whether the data pipeline is working — on both surfaces
Indexation rates, ranking signals, and AI citation rates answer different questions about whether the records are doing their job. Article counts show how much was produced, while traffic snapshots show only how it did at one point in time. Neither identifies the defect on its own. Measurement helps when it shows which part of the pipeline needs to be fixed.
On Google, Search Console’s page indexing report is the primary signal. Indexation rates by batch can expose data-quality problems sooner than ranking reports do, because they show whether the output has entered the index at all. A sustained gap between submitted and indexed URLs directs attention back to the underlying records. That gap calls for a data-layer diagnosis. The four record-level failure modes give the investigation more precision than a general judgment that the pages need better copy.
On the AI surface, Share of Model measures the percentage of AI-generated responses that include a brand across a defined query set. Citation rates add evidence about whether pages are being used as sources. These measures need to remain distinct from indexation because a page can be available in search without supplying extractable facts or clear entity grounding for an AI answer.
Low indexation in a batch points back toward record quality, while strong indexation with no AI citations points toward extractability or entity grounding. Measurement then needs to show whether the changed records do better or worse on the surface where the problem arose. Publication becomes one step in a feedback loop in which evidence determines what gets enriched, refreshed, or corrected next.