The Blog List Is Not the Strategy: What Computer Science Content Actually Signals About a Brand
Publishing quality alone won't secure your brand's presence in AI-generated answers.
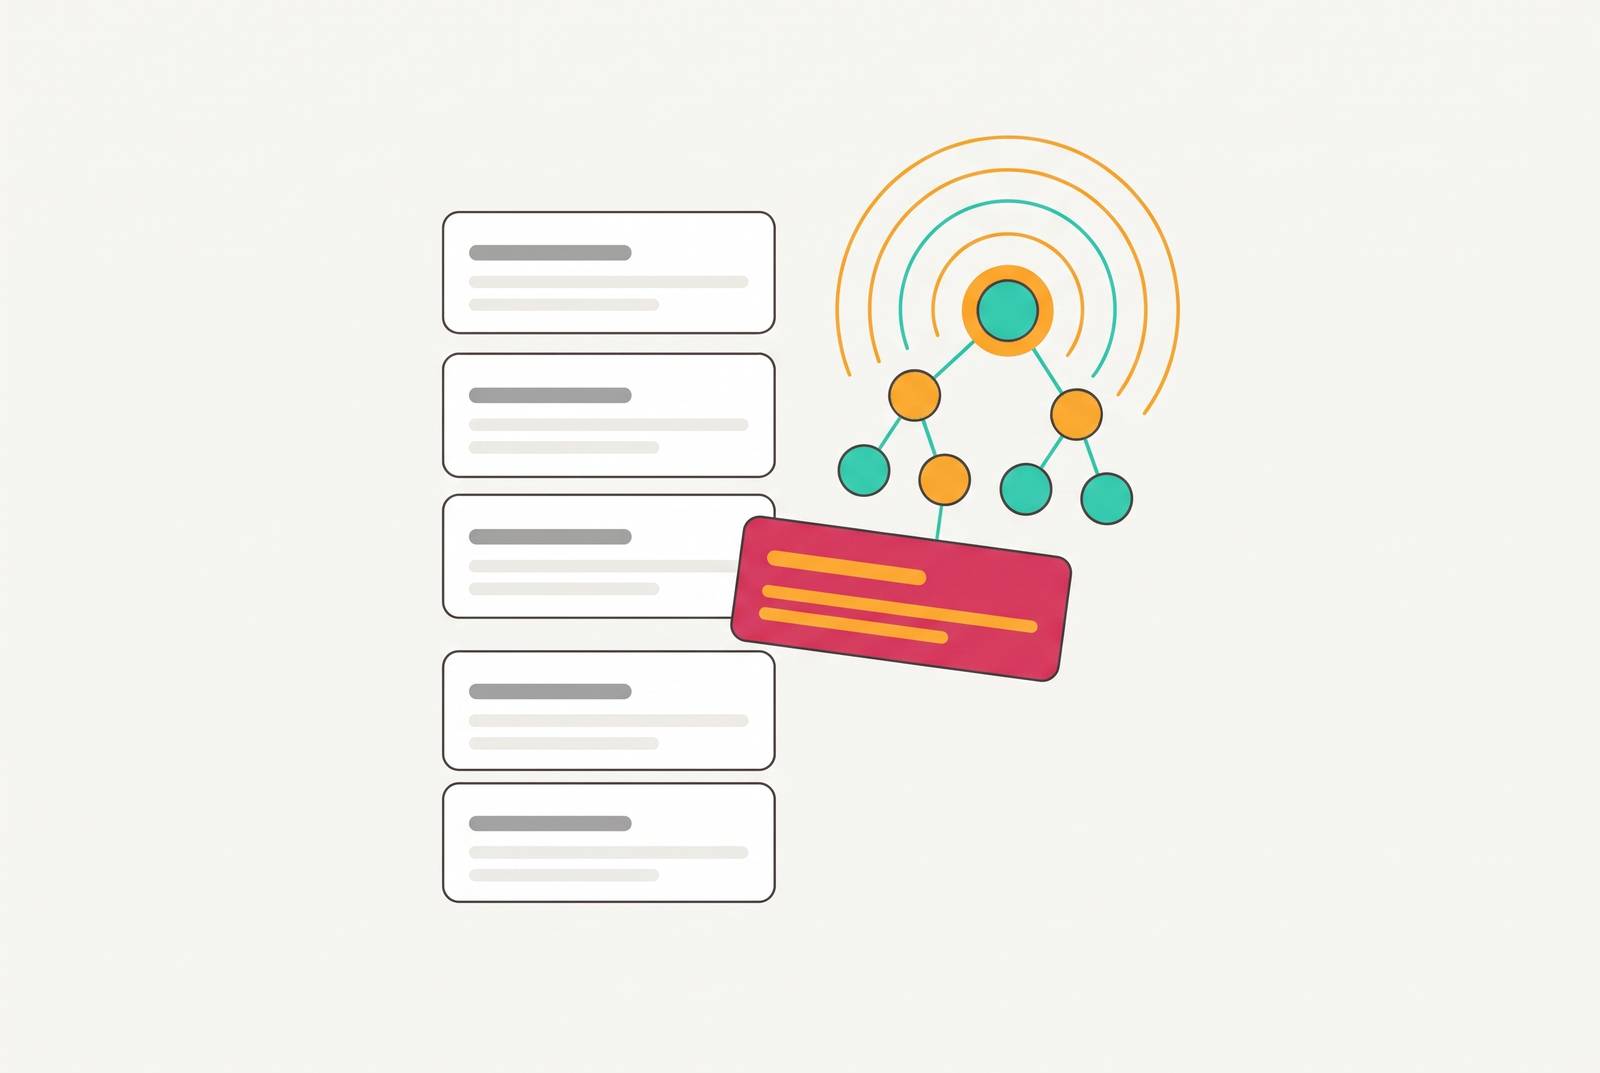
A computer science blog list can identify good reading without identifying an influential technical brand. The distinction is the subject of this piece. Writing quality and longevity describe a publication’s record, but they do not establish whether AI platforms name the brand when answering questions about its category. A content strategy needs to measure that presence.
How blog lists score computer science content — and what they don't see
Reading a “best CS blogs” list offers a familiar way to find thoughtful technical writing. The entries reward clear explanations, consistent publication and a record that stretches back over time. But does an AI platform cite those blogs when a developer asks a question about their field? The list cannot answer that question. Its evidence concerns what a publication has produced.
The scoring follows a model in which publishing good writing over time builds a reputation that readers find through the ranked links they click. Within that model, a long publication history is a useful signal. Yet a ranked search result and a citation inside an AI answer are different outcomes, produced by different mechanisms. Using the first model to judge the second leaves a technical brand measuring its publication record while assuming it has measured its authority.
Where brand authority is actually decided now — inside the AI-generated answer
When an AI platform answers a category question, it composes the response rather than simply presenting pages for the reader to inspect. That changes where a brand competes for attention. The immediate contest is whether the answer names it, cites its content or leaves it out. Generative engine optimization, or GEO, addresses that contest by structuring content and building brand authority so that AI platforms select and cite it.
Most AI search engines use Retrieval-Augmented Generation, or RAG. They retrieve candidate documents, then synthesize material into a composed answer. Indexing gets content into consideration, but does not secure a citation. The content must also be structurally clear and authoritative enough for the language model to use and cite. For brand inclusion, the outcome is binary within a given response. The brand is named or it is not, rather than occupying a search-result position that a reader might eventually reach.
Similarweb’s 2026 Generative AI Brand Visibility Index finds that a substantial share of US consumers use AI at the product discovery stage, ahead of those using traditional search. That finding concerns the broader consumer population. A shortlist can form before someone opens a search bar. By the time a user searches for a brand, the earlier answer may already have shaped which brand seemed worth investigating.
Why writing quality and longevity — the list's two core signals — are weak predictors of AI citation
Good writing helps a person understand an idea. A citation system poses a different test. It must find material, extract it and select it for a particular answer under the platform’s own preferences. A blog list’s score for the writing does not measure those steps. Consequently, a highly ranked blog can be absent from generated answers while a lower-ranked one is cited consistently, without either result contradicting the list’s assessment of writing quality.
Perplexity weights recency heavily, while ChatGPT browse mode puts less aggressive weight on freshness and favors established authority signals. A 2023 post with strong backlinks can therefore lose to a 2026 post on the same topic with fewer links. Age is not a transferable advantage. A publication’s long history may explain its standing on a curated list while saying little about the suitability of a particular page for a current answer.
Missing elements such as llm.txt and FAQ schema, or reliance on script-rendered content, can leave significant citation gaps regardless of writing quality. Researchers at Princeton, Georgia Tech, the Allen Institute for AI, and IIT Delhi formalized GEO research at KDD 2024 and showed that keyword-stuffing performed below baseline, while structured, extractable formats earned citations. This does not turn keyword-stuffing into a measure of good writing. The list and the answer system are evaluating different things.
The off-site majority problem — why a brand's own blog is structurally a minority citation source
Even a blog built for extraction addresses only part of the problem. Third-party sources outweigh a brand’s owned content in AI citations, making the blog itself a minority source of authority. The most-cited content format is the ranked “best-of” listicle. How can blog lists be inadequate measures if lists themselves are prominent citation sources?
A third-party roundup can help an AI platform form an answer about a category. Its editorial scoring still does not reveal whether a particular brand appears across the relevant answers, on which platforms or with what framing. Its citation role does not validate its scoring model.
Brands with citations from several types of sources get much more AI coverage than those that rely on owned content alone. That makes exclusive investment in the blog a structural constraint. Better posts cannot, by themselves, supply a presence across third-party sources. A brand judging its strategy only through the publication it controls is looking at the narrowest part of the evidence.
The attribution gap that makes the blog list look like it's working when it isn't
Standard attribution can conceal this mismatch because it records a step in discovery that follows the initial AI interaction. Consider the pattern in which someone asks ChatGPT which platform to use and receives a brand name. Two days later, that person Googles the brand and converts through branded search. The attribution model credits branded search for the conversion. The model leaves out the AI mention that started the journey.
Branded search conversions do not establish that a blog’s standing is driving discovery, even when the two appear together in a report. Nor do they show whether a brand is losing ground in AI answers while channels later in the journey still get the credit. The measurement boundary hides the upstream influence. Without an instrument for that earlier stage, the familiar explanation can survive simply because the competing explanation is not recorded.
Similarweb identifies four measurable GEO outcomes, which are citation with a source link, brand mention, positive sentiment and high share of voice across relevant prompts. Google Analytics does not provide those answer-level measures. A source link and a favorable mention are also distinct outcomes, so recording one does not settle the other. To see this layer, a brand needs to keep measuring it on each platform outside standard web analytics. Otherwise, a brand can count visits and conversions correctly and still miss how the buyer came to consider it.
The platform divergence problem — AI visibility isn't one number
ChatGPT, Perplexity, Gemini and Claude cite different sources and weight different signals, so the same brand can have sharply different visibility across them. Only a small fraction of domains are cited by both ChatGPT and Perplexity. A content strategy suited to one engine does not automatically earn inclusion on the others.
A platform that favors fresher material and one that gives more weight to established authority can choose different sources for the same subject. The brand has not necessarily changed its content between those answers. The selection rules differ. Citation volume can consequently be strong on one engine while the brand is nearly invisible on another, making a combined figure hard to interpret without its platform breakdown.
What would a single visibility number actually establish? It could describe an aggregate, but it would not show where the brand is missing or which platform’s preferences its content meets. The same problem comes up when one engine is used to stand for all AI discovery. A platform-specific result is evidence about that platform. Treating it as evidence about the whole category repeats the blog list’s original error of letting one observable surface stand for a larger system.
What the right content infrastructure actually looks like for a technical brand
The practical response is to build around citation signals, entity clarity and platform-specific measurement. The foundational sequence begins with allowing AI crawlers to access and parse the content, followed by conventional indexing. Off-site brand mentions come next, then topic clusters that cover sub-questions in depth, a structure that makes extraction easy and content that is up to date. The order puts access before refinement. An excellent explanation cannot compete for retrieval if the system cannot reach or parse it.
For content that is accessible, extraction depends on how its claims are presented. Paragraphs that stand on their own, clear facts, FAQ schema, comparison tables and named sources give the answer system material it can use. The KDD research supports the value of structured, extractable formats for citation. This is a reason to keep prose readable and make each passage clear enough to stand on its own, rather than depending on context that may not accompany it into a synthesized answer.
Off-site work addresses the authority that owned pages cannot supply alone. The reverse-citation approach gets brand mentions onto the third-party pages that AI platforms already cite for queries about the category. Recency needs its own discipline as well. Publishing on a steady schedule helps a brand show up on recency-sensitive platforms, while more and more AI Overview citations come from pages outside the traditional top-10 organic results. Conventional ranking therefore cannot serve as the only test of whether that work is reaching the answer surface.
Publication controls are part of this infrastructure, too. Google’s 2026 ranking system penalizes low-quality, mass-produced content created primarily to manipulate rankings, whether AI-generated or human-written. Multi-stage review and human approval before publication address that risk. Strategized.ai’s September 2026 case study tells how an industrial B2B supplier used an AI content pipeline to produce dozens of articles over roughly eight months. Each article passed automated accuracy, AI-extraction and schema-graph checks before a human approved it, and the articles then earned citations in Google’s AI Overviews with no retractions required. The case supports a concrete lesson about process based on this pipeline’s citation results.
For a technical brand, the lesson is to treat publication as an engineered system. Its inputs need review, its content needs to be retrievable and its outcomes need measurement on the platforms where discovery happens. Pipeline provenance shows how material got published, while citation tracking shows whether it made it into answers. Neither substitutes for the other. Together, they provide a basis for changing the system on evidence rather than inferring success from the quality of its visible output.
The question a technical brand should actually be asking about its content
A blog list is an artifact audit of what a brand has published and how well. AI visibility requires an ecosystem audit that includes entity clarity, off-site presence, platform-specific citation rates and pipeline provenance. Instead of asking “are we on the list?”, a technical brand should ask “are we being named when an AI synthesizes an answer about our category?”