Why "quality editing" is the wrong frame for technical content — and what computational marketing does instead
AI answers now reward modular, measurable content over polished prose alone.
Technical content needs a better way to learn what works. As discovery moves from search results to AI answers, “quality editing” becomes an incomplete frame for success. The real bottleneck is the missing feedback loop between publication and performance. Computational marketing closes that loop by treating content as a versioned, measured artifact.
How technical content used to succeed — and why that model is breaking down
A well-crafted article earned a blue-link rank, that rank delivered a click, and the click brought someone to the page. Polished prose signaled expertise, expertise helped earn trust, and trust could turn into pipeline. Editing was a reasonable place to invest. It improved the thing a prospective buyer would actually read.
Rankings changed, traffic came or did not, and teams could see which articles drew readers. The editorial review cycle was the quality gate before an article went live, and search performance showed how it did afterward. Neither instrument was perfect, but they addressed the same journey. The article was both the published product and the reader’s destination.
10Fold’s 2026 research found that more than half of B2B technology marketers ranked AI search above traditional web search as their top content distribution channel. Still, it identifies a consequential change in the route to readers. AI answer engines extract passages and synthesize answers, so the reader may never open the source article. The old link between article-level polish and discoverability no longer works in the same way.
Why AI answer engines read content differently than readers or crawlers do
Consider a section beneath an H2 heading. In a heading-based retrieval system, that section can become its own embedding, a representation used to retrieve it separately from the surrounding article. Its introduction may be somewhere else entirely. A retrieval-augmented generation pipeline, or RAG pipeline, selects chunks to help construct an answer rather than reading the article as a continuous argument. The section has to earn its place on its own.
Headings are not the only possible boundaries. Depending on the strategy, chunks may follow H2, H3 or H4 headings, token limits, sentence boundaries or shifts in meaning. The H2 makes the mismatch visible because an editor can admire the flow of a whole article while overlooking whether a section works independently. A well-written introduction cannot make up for a passage elsewhere that is poorly structured.
Retrieval also depends on access and indexing, which differ across engines. A strong Google ranking does not show that content can be found on every engine. The relevant controls include GPTBot, ClaudeBot, PerplexityBot and Bingbot, as well as Google-Extended and Applebot-Extended. Those last two are training opt-out tokens, so treating all six as interchangeable would obscure their different roles. Access decisions belong to engineering as well as publishing, because prose cannot rescue content that never enters the retrieval pool.
What the success metric actually becomes when discovery moves to AI answers
If an engine supplies a synthesized answer instead of a page of links, what counts as visibility? Ranking position still describes one channel, but it cannot show whether a brand appears in the answer itself. Share of Answer addresses that question directly. Across a tracked prompt set, it measures the percentage of AI responses that name the brand. The prompt set gives the measurement its scope.
A mention is not the same as a citation. Share of Answer shows whether the brand appears, while citation frequency shows how often the content is used as a source. Both help describe a discovery path that may produce no visit to the owned site. They also need to be measured across engines, because a brand can appear in one and be absent from another. Google Search Console and organic sessions alone do not show those differences.
Ahrefs’ Brand Radar monitors brand mentions across AI Overviews, AI Mode, ChatGPT, Perplexity, Gemini and Copilot, and reports AI share of voice. It draws on a large database of monthly search-backed prompts. Measurement is no longer only a theoretical possibility. That changes the nature of the gap, because teams can now observe a channel that editorial judgment alone cannot assess. What teams do with those observations will shape the next content decision.
Why the bottleneck is the missing feedback loop, not editing quality
The central constraint is the absence of that connection. An editorial review happens before a piece goes live, when the team can check accuracy, clarity and tone but cannot yet see how the published piece performs. A workflow that ends there never brings the result back into production. It has no automatic flag when a section stops appearing in Perplexity answers. Nor does it trigger a response when a competitor’s framing displaces the brand’s in ChatGPT.
A pre-release review does not tell a software team how a deployed system behaves. Logs, alerts, dashboards and regression tests show how the system behaves after deployment. Publication needs an equivalent change in status. Rather than marking completion, it marks the point at which performance can begin to inform the next revision.
Treating content as a code artifact therefore means more than storing drafts. Versioning makes changes attributable, instrumentation makes performance observable, and iteration connects the signal to the next change. Without that connection, revisions can still happen, but their direction depends on guesswork or familiar preferences. Craft becomes the default target because it is visible inside the team. The review process does not check whether that craft helps the content get cited.
The cost grows with each publishing cycle. A team can get better at making work its editors approve without learning why engines choose or ignore it.
How the content source distribution problem makes owned-site editing even less sufficient
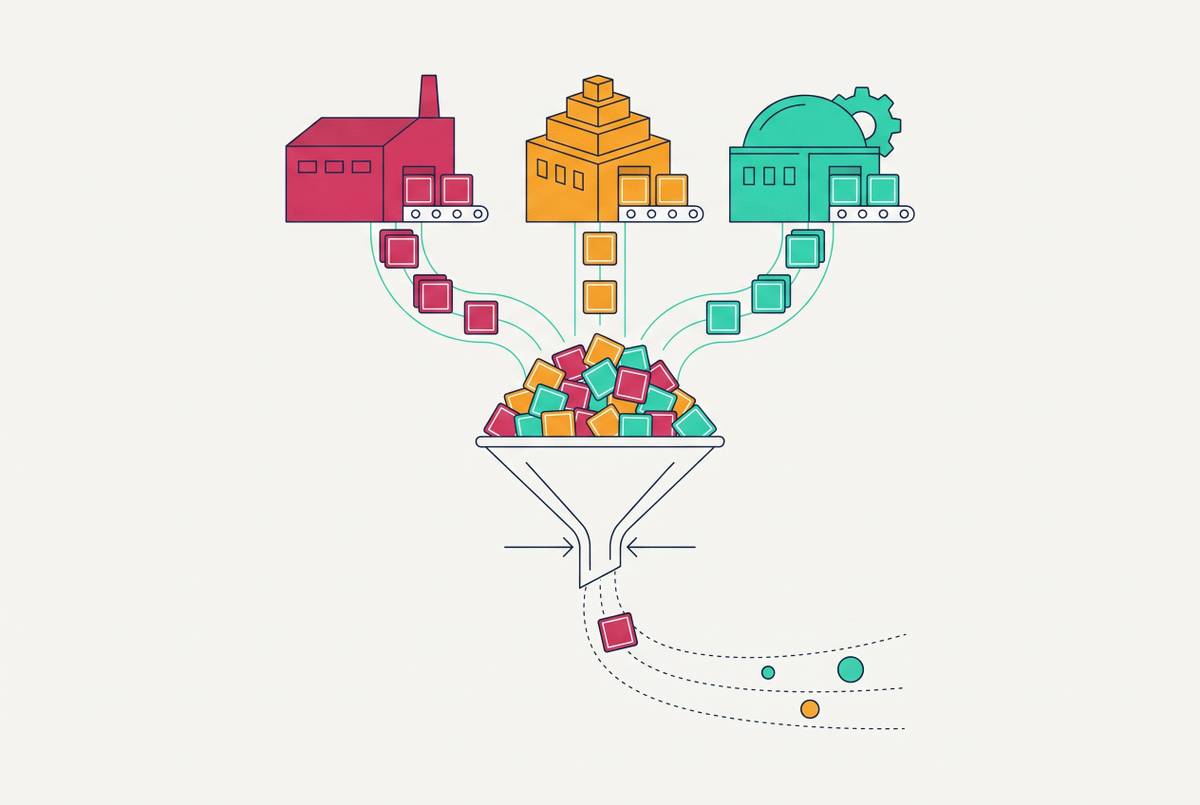
Even perfect measurement of an owned site covers only some of the sources engines use. ABI Research’s 2026 citation sourcing analysis found that brand websites made up just 8% of AI citation source distribution. Earned media came first, followed by peer sites and affiliate sites. Most of the landscape sits beyond the brand’s domain. An editorial strategy centered on improving the company blog therefore targets a minority of the surfaces engines cite.
Being included in someone else’s roundup can offer a citation opportunity that publishing a brand’s own roundup does not. More review rounds on an owned article cannot create third-party presence.
The resulting model has two connected layers. Owned content gives the brand a primary domain built for machine readability, while third-party presence puts it on high-authority surfaces that engines already trust. An owned-site quality gate cannot account for both. A broader pipeline has to connect content production with where that content, or the brand it describes, becomes visible.
What a feedback loop actually looks like when content is treated as a pipeline artifact
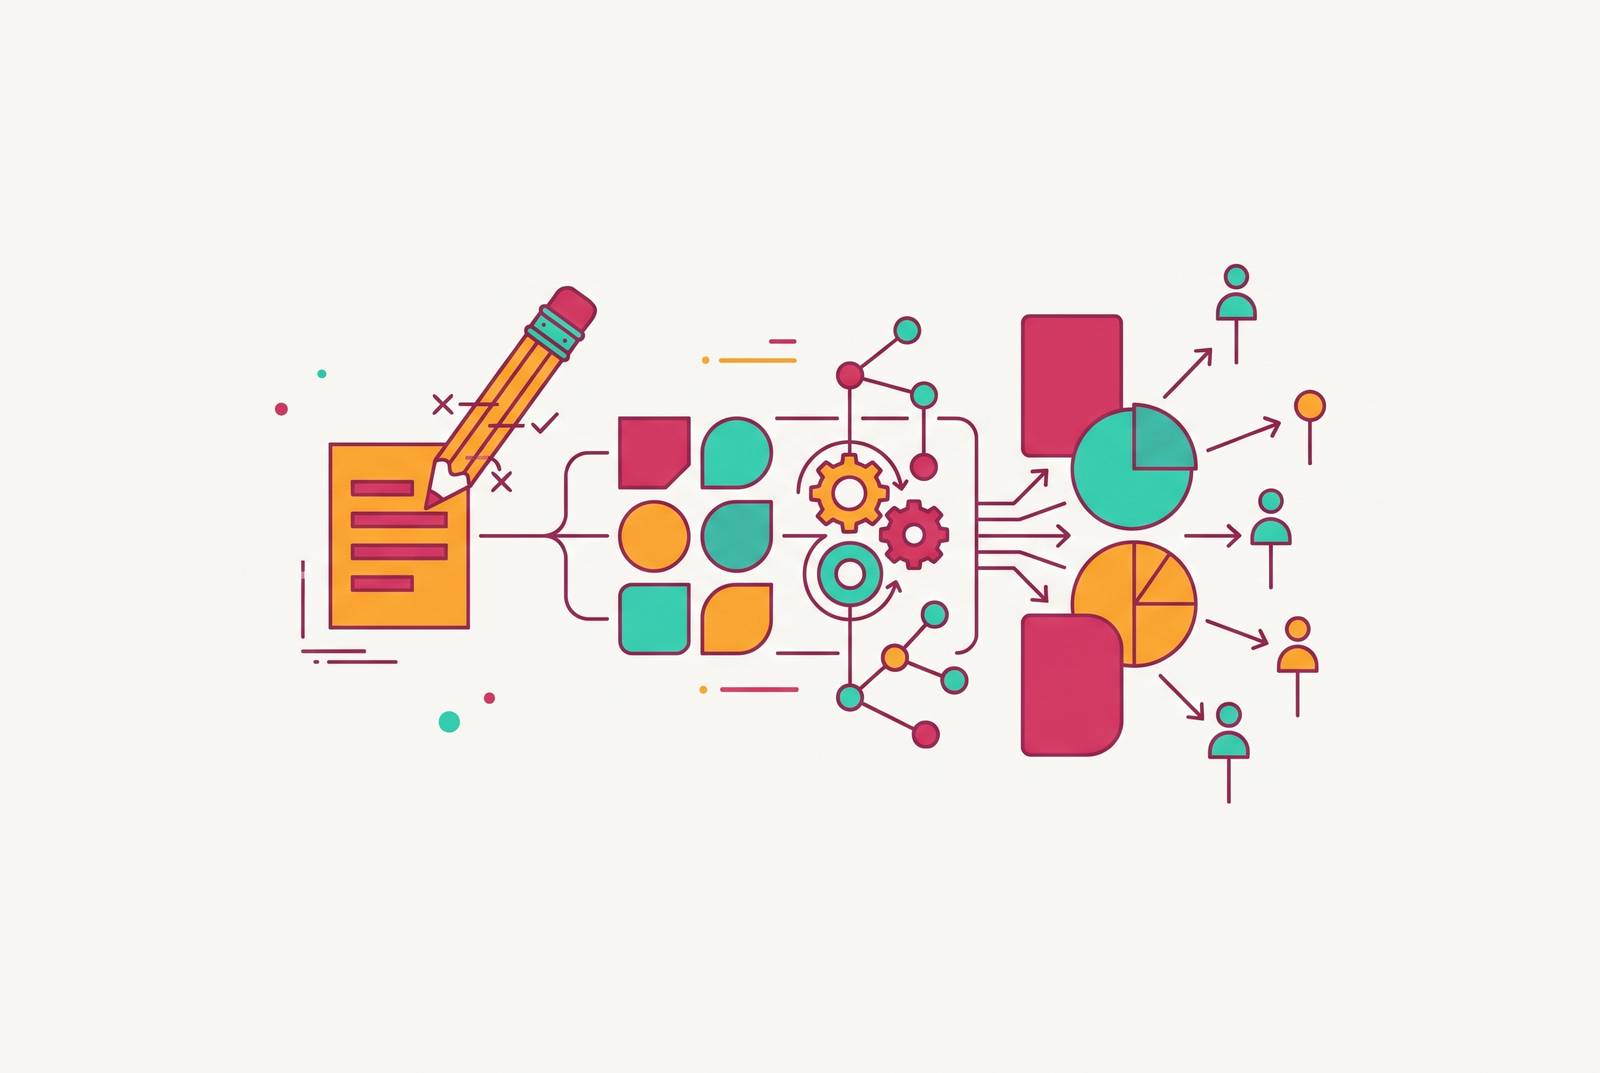
A content pipeline closes the gap by making measurement feed planning. Production no longer consists of a series of handoffs that stops at publication. Each stage has checks, and human approval gates sit throughout the process. The final stage, Measure, returns evidence to Plan. That return path is what makes the workflow a loop.
Automated quality gates give the review function a defined role within it. Before content goes live, they can flag it if it falls short of thresholds for readability, fact-checking confidence, brand voice consistency and citation accuracy. When a piece fails a gate, automatic publication pauses for human review. Human judgment handles the exception. It is not removed, but reserved for places where the automated checks do not justify proceeding.
After publication, the measurement layer tracks brand mentions and citation frequency in responses from engines such as ChatGPT, Claude and Perplexity. Share of voice relative to competitors becomes a leading indicator, while primary-source citations and secondary references provide different signals about how content is used. These observations generate refresh recommendations for the next planning cycle. The system has something concrete to respond to. A revision is no longer justified only by the claim that the article could read better.
Versioning then connects each revision to the artifact that changed. It gives the team a record for interpreting performance changes and assessing evidence of causation. That distinction keeps the loop honest. What the team sees guides a decision that leads to a new version, and the next measurement checks whether performance changed as intended.
Where the objection to this frame has merit — and where it runs out
Does this argument draw too sharp a line between good editing and useful content? Accuracy, specificity and structure are legitimate editorial concerns, and they also help make content usable by AI engines. Vague or hyperbolic language can lead an engine to ignore a passage or produce a summary that misrepresents the brand. Editorial judgment has a real role here. The dispute turns on whether a review cycle alone can show which traits make content visible.
Verifiability, modular structure and empirical grounding turn that broad idea of quality into more exact requirements. A passage needs claims that can be supported, enough context to stand independently, and evidence. An editor can help create those conditions. But their presence still needs to be distinguished from evidence that a particular intervention improves citation performance. Otherwise, “quality” becomes an explanation broad enough to resist testing.
Ahrefs’ May 2026 tracking compared pages with added JSON-LD against matched controls. Adding the markup alone did not lead to statistically significant citation gains in AI Mode or ChatGPT, and AI Overviews showed a small but statistically significant decline. Cited pages being more likely to contain JSON-LD therefore did not establish that adding it would help. Correlation did not identify a reliable intervention. The same caution applies when well-edited pages appear more often among cited sources.
Polish cannot be assumed to be the cause when original data, specific claims and verifiable evidence may explain the result. The practical trade-off is budget allocation: more review is one possible use of resources, while better evidence, instrumentation and distribution are others. A feedback loop helps distinguish those choices instead of treating every performance problem as a request for another editorial pass.
What computational marketing does in practice that editorial review cannot
Computational marketing organizes those choices into an operating model. Publishing cadence follows editorial bandwidth and signals such as prompt clusters with citation gaps and sections where competitors are being retrieved. Watchers track AI responses in a systematic way and prompt work on content when they spot changes that matter. Human attention goes to exceptions and strategic decisions. First-pass editing of every draft no longer defines the system’s capacity.
The owned and off-site layers operate within that same model. A pipeline can publish to the primary domain and to third-party surfaces that engines already trust, while third-party presence is actively managed. Distribution becomes part of production. The team can respond to a visibility gap with work on the appropriate surface, instead of assuming the answer must be another article on its own site.
Share of Answer across tracked prompts is the north-star metric, backed by citation measurements that show how sources are being used. When a section stops appearing in answers, that signal triggers a refresh rather than a debate about whether the prose was polished enough. Every capability is reachable by an agent through an API and by a person through a user interface. The loop can run at machine speed. Human review remains inside it, governing exceptions and consequential decisions while measurement determines what needs attention next.