What "agentic" marketing assistants actually do: three questions to ask any vendor before you buy (knows, acts, is allowed to change)
Three vendor questions reveal whether an AI agent's autonomy is real.
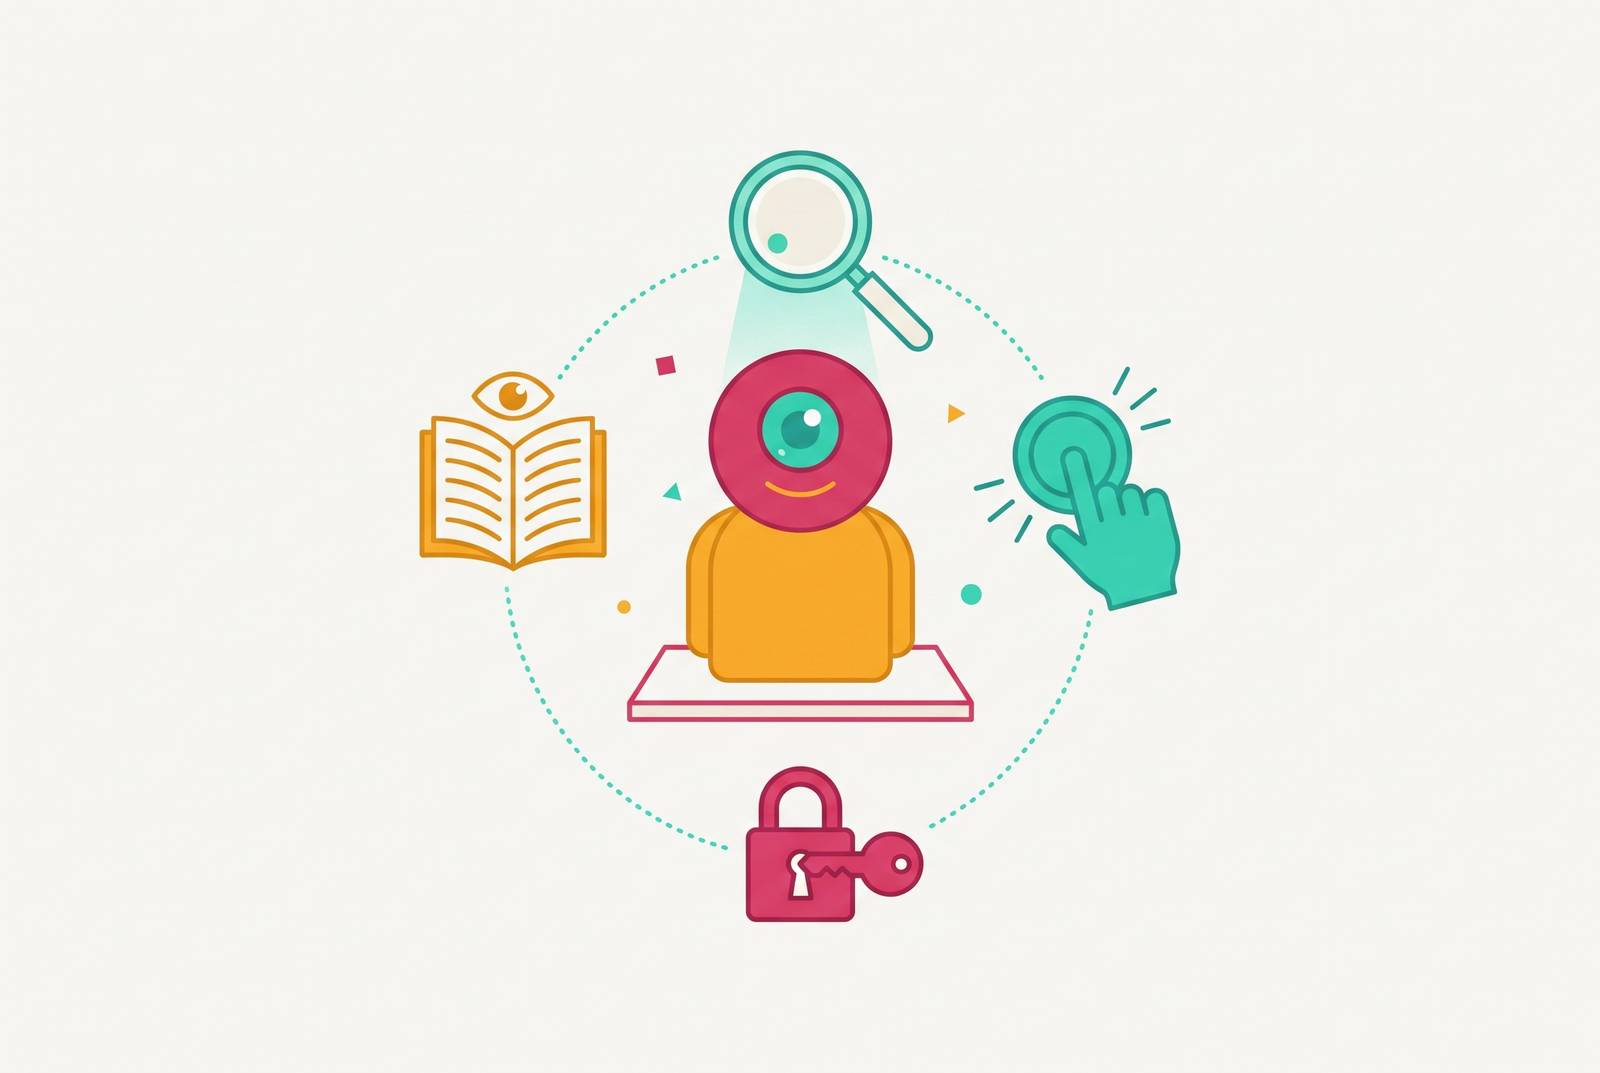
“Agentic” marketing assistants should be judged by what they can prove. For growth engineers and technical marketing leads, three questions show whether autonomy is useful or just looks good in a demo. What does the system know, what does it do unprompted, and what is it allowed to change? The buying decision depends on concrete answers to all three, tested together.
Why "agentic" has become a meaningless word in vendor pitches
On a video call, a vendor asks an assistant to analyse performance, draft copy, and recommend a campaign change. The output arrives quickly and looks useful. But who chose each next step, the system or the presenter? If the presenter supplied the path through a series of prompts, the demo showed assisted generation.
The label now covers tools with little meaningful autonomy simply because they use a large language model. Gartner estimates that only a small fraction of the thousands of vendors claiming agentic features are genuine, naming the practice “agent washing.” A buyer cannot infer how a product behaves from the category its vendor puts it in.
Rule-based automation follows fixed if-then rules, while generative AI makes output when asked. A genuine agent receives a goal, determines its own path, acts across multiple tools, observes results, and adjusts. It does not wait for another prompt at every step. Each type can be useful, but a recommendation engine and a system that changes a live campaign create different benefits and risks.
Why three questions — knows, acts, is allowed to change — form a complete diagnostic
The three questions separate access, initiative, and authority. A tool with broad knowledge but no ability to act may be an expensive analyst, regardless of how convincingly it explains its findings. A tool that acts without a governance layer creates a different problem, because its capability exceeds the buyer’s control. Yet governance can also define permission so narrowly that autonomous action never happens. That leaves autonomy in name only.
Knowledge establishes what the system can base a decision on, action establishes whether it can pursue that decision, and permission establishes the boundary of its authority. None substitutes for another. Together, they test whether a claim that is technically true describes a tool the business can use and control. A precise answer on one axis paired with a vague answer on another is itself a signal.
What it knows: how to pressure-test a vendor's data-access claim
“Connected to your data” can describe very different arrangements. An assistant that reads a report export has information, but it may not be able to query live performance. It may know only last week’s results. Genuine cross-system access means a single agent can connect to CRM, analytics, email, ad platforms, and CMS together, without people manually syncing information between them.
Freshness adds another boundary, even when every connector exists. A live connection alone does not reveal how long a signal takes to travel from the source system into the agent’s context. For each named source, ask the vendor to show the API or connector making a live pull. Then ask for the latency between a change at the source and the agent’s awareness of it.
Access also needs coherence across customer touchpoints. The CMO Survey 2026 found that a majority of companies have not consolidated customer intelligence across all touchpoints. An agent working with partial context must reason from that partial view, even if the data it receives is fresh. More connectors do not automatically resolve this gap. The evaluation needs to distinguish information that exists somewhere in the organisation from information the agent can actually use together.
For GEO and AI-visibility work, the same test must cover which platforms the agent can reach. Citation volumes for the same brand can differ by orders of magnitude between AI answer platforms, so monitoring only one can give a dangerously incomplete picture. Repeated observation is necessary too. Only a minority of brands maintain consistent presence across repeated runs of the same query, which makes a single snapshot insufficient. Ask which platforms the vendor monitors, how often it refreshes, and whether it tracks drift over time.
If a source goes offline or returns bad data, does the agent halt, flag the problem, or continue silently with stale context? A buyer needs to know which of these the agent does before trusting the actions it takes next. Otherwise, the output can sound sure even when the inputs give it little to go on.
What it does unprompted: separating genuine autonomy from assisted generation
A tool that drafts a recommendation for a person to execute has not taken the recommended action. Likewise, a ranked menu of options followed by a human selection is decision support, even if the tool then executes the selection. The useful distinction is not whether the output sounds intelligent, but whether the system initiates and completes work within an agreed scope.
In paid media, that scope might include adjusting bids, pausing creatives, or reallocating budget across campaigns in real time. Permission still applies, so autonomous execution means acting within defined parameters. The vendor should enumerate every action type that needs no human approval. Broad categories such as “campaign optimisation” leave too much hidden.
A researcher agent can gather context, a drafting agent can draft, and a critic agent can check against brand and factual rules. The test is the handoff between those stages. If each agent passes its output to the next as input without a person re-prompting, the system does more than offer separate generation tools. Anthropic’s orchestrator-workers pattern similarly describes an orchestrator delegating work to specialists, which in campaign work can cover audience building, copywriting, and scheduling.
Delegation alone does not establish the limits of action. Ask for an explicit range from the smallest action the agent can take to the largest, narrow by default. Then examine the consequential boundary. Can it initiate a payment, contact a customer, or modify a live campaign? For each permitted action, the vendor needs to identify both the trigger that starts it and the condition or control that stops it.
What it is allowed to change: the governance layer most vendors underspecify
“You set the guardrails” leaves the central technical questions unanswered. It says nothing about the mechanism, who can alter it, or what happens when a boundary is breached. Jasper’s State of AI Marketing survey found that brand, legal, and compliance review had become the leading obstacle to scaling marketing agents, ahead of lack of output quality and data/privacy risks. Governance is therefore not a final compliance check. Useful capabilities depend on governance to move into routine operation.
A testable model separates permissions by risk. Low-risk work, including scheduling, reporting, and minor copy edits, can run autonomously. Medium-risk work, including changes to campaign structure and publishing content, has to pass through a human review gate. High-risk work, including budget reallocation above a threshold and customer-facing communications, needs explicit approval. The configuration must make these boundaries concrete rather than leave the agent or operator to interpret a general instruction.
The audit trail needs equal precision. A report available on request is not the same as a machine-readable record that the agent writes as it works. That record should capture every decision, action, and the reasoning that produced it, so a person can trace and reverse a step. Timing is part of the test. Ask whether the reasoning is surfaced when the action happens or appears only in a retrospective report.
Control must also survive an interrupted workflow. A buyer should be able to halt the agent mid-workflow and inspect its state without losing data or causing partial execution. Pausing is different from simply stopping a process. As API and MCP access expand from reading information to writing into a CRM, publishing to a CMS, or moving ad spend, the potential blast radius grows. Every write permission should have a named person who owns its approval.
To test that model, ask to see the actual configuration UI or API spec. The vendor should also demonstrate the rollback mechanism for an action a human later decides was wrong. Rule changes need their own accountability. Establish who in the organisation can change the governance rules and whether those changes are logged. Otherwise, a system with carefully set limits can end up with different permissions and no clear record of what changed.
How to run a vendor evaluation session using the three questions
To use these tests to decide what to buy, run a 60-minute evaluation with live tasks that the buyer chooses. Begin with knowledge because access constrains everything that follows. If the agent cannot reach the information the use case needs, its action and governance capabilities cannot make that use case work. Recorded walkthroughs do not resolve this uncertainty. Each axis needs a real-time attempt using your data or a reasonable proxy.
For the knowledge test, ask the agent to pull last week’s performance data from your analytics tool and explain why conversion dropped. Follow the pull through to its source. The vendor’s response should make clear what information the agent reached, how fresh it was, and where the explanation exceeds the available context.
Next, ask it to stage a bid adjustment for a named campaign and show exactly which approval gate fires before execution. Then ask to see the audit log for the last action the agent took and how that action would be rolled back. The sequence connects permission to an actual operation. It keeps the vendor from moving the governance discussion into a separate slide presentation.
A refusal or deflection leaves the capability unproven. If the vendor cannot demonstrate it live with your data or a reasonable proxy, it either does not exist or depends on conditions the vendor has not disclosed. Record a yes, partial, or no against each verification question. Partial answers across all three axes represent a different risk from strong answers on two and a clear failure on one.
What to do when no vendor passes all three tests cleanly
A vendor that passes every test rigorously is rare, so the decision turns on which gaps the use case can tolerate. Weak ad-platform integration may be acceptable for now when the team does not run paid social. If that channel is part of the intended deployment, however, verify the roadmap and the contractual obligation to add support. When deciding what to buy, a team should keep track of what is promised for later and what the tool can do now.
Limited autonomy can also be a deliberate starting point. A system that begins in “recommend only” mode and graduates to execution after a trust-building period can have a sound architecture. The graduation criteria need to be defined and contractual. Without them, the buyer cannot distinguish a controlled rollout from a product that will remain decision support. Restraint is useful when it has an explicit purpose and an agreed path forward.
Other gaps are disqualifying regardless of the use case. No audit log or rollback leaves the buyer unable to explain and undo what the agent did. Undefined action scope makes the blast radius unknown. A pipeline with no point where a person can interrupt it cannot safely scale if pausing it loses state or causes partial execution while content goes live and budgets move.
If every shortlisted vendor has such gaps, a composable stack of narrow tools connected through APIs can be a better option than a single platform. Each tool can do a job with clear limits, and each part can be swapped out without rebuilding the whole system. That can give the buyer better governance without depending on one vendor for everything the system needs to do. The buying decision should depend on whether the system makes it easier or harder to say no after something has already happened. If it makes that harder, the autonomy is theirs.