What "cheap SEO tools" actually costs a B2B startup: subscription, service, or your own Search Console data
Compare what each SEO option really costs and what you keep.
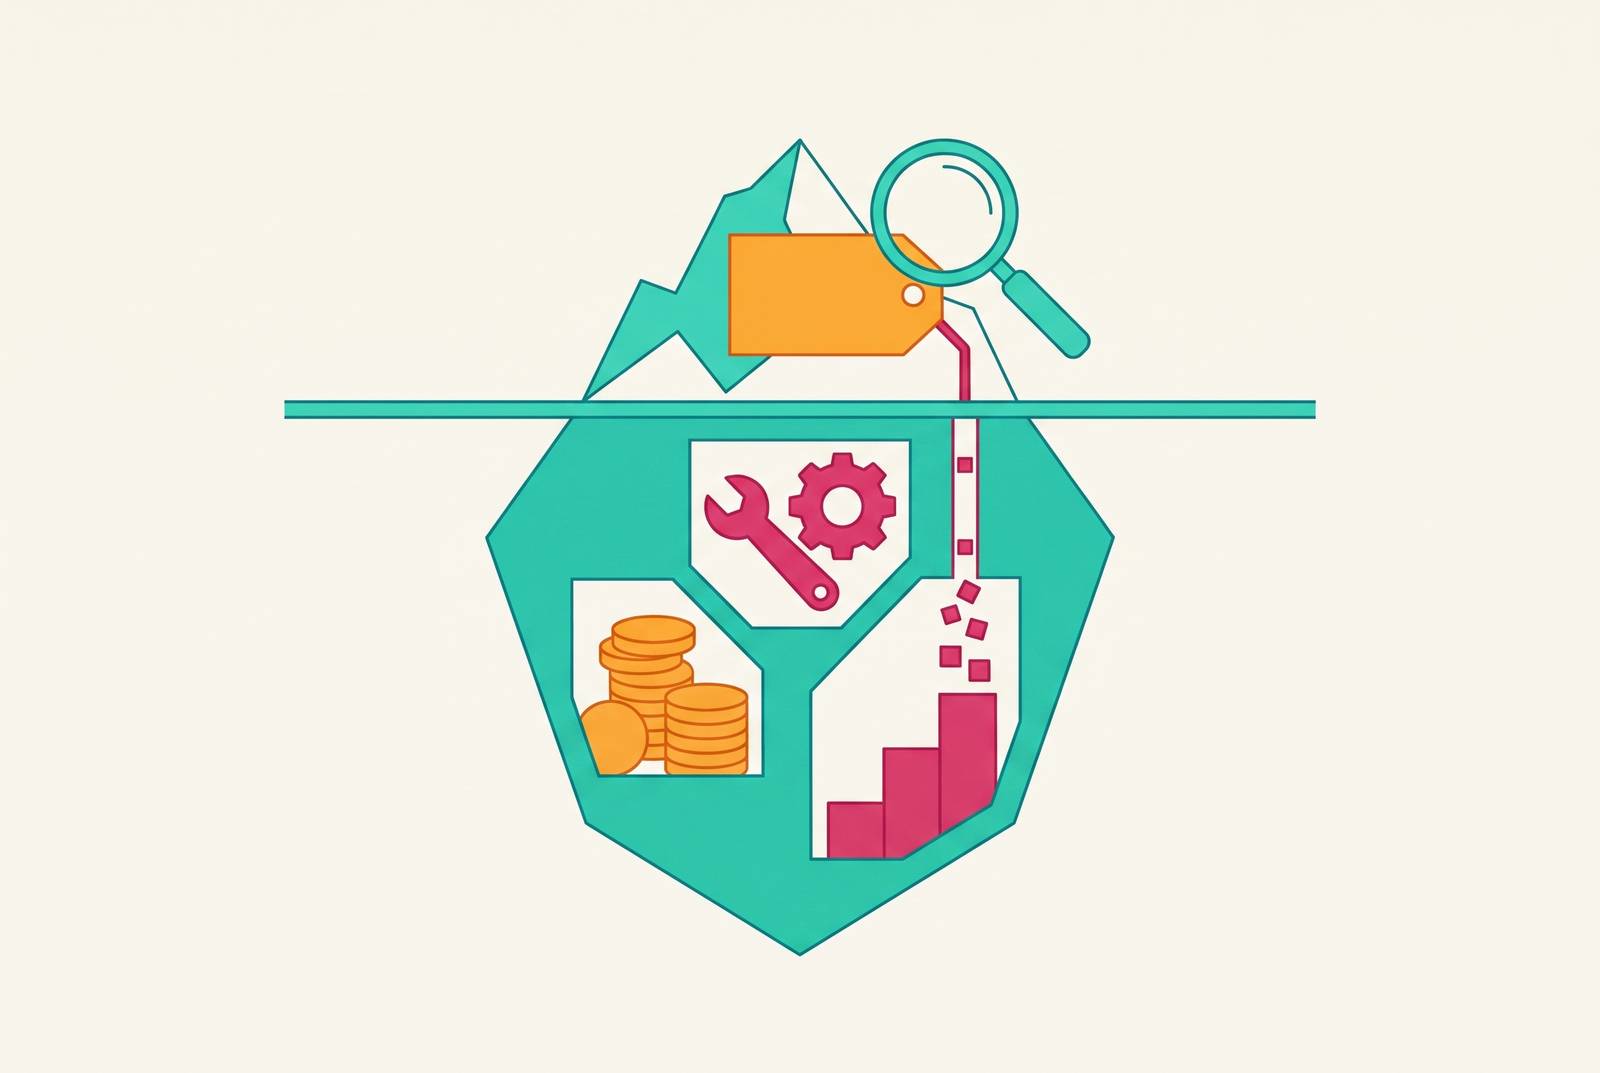
For a B2B startup, “cheap SEO tools” is the wrong category for a buying decision. A self-serve subscription, a scoped service, and Search Console data the startup owns each give it different things and leave it with different work to do. The startup can compare how much each costs in full, which assets it keeps, and what signals each can measure, including whether buyers see the brand in AI answers.
Why "cheap" is the wrong question for a B2B startup shopping for SEO tools
A founder chooses the budget plan, then discovers that someone still has to turn its reports into published work. Another team buys an expensive suite and uses only a fraction of it. Neither outcome is explained by price alone. The mistake comes earlier, when unlike purchases are treated as interchangeable ways to “do SEO.” A subscription supplies tools, a service supplies scoped execution, and first-party data supplies evidence about the startup’s own site.
Those purchases carry different obligations. Which fits depends on who can do the work, who owns the resulting assets, and what evidence the business needs. A low monthly fee can leave an execution gap that the team cannot close, while a larger fee can pay for capabilities it never uses. That is how a startup can underspend on outcomes while overspending on subscriptions.
What the self-serve subscription model actually costs when you count all of it
The published entry price is only the starting point. Adding users can put a five-person team’s bill well above the advertised rate for one user, especially on higher-tier plans. The team may have to pay extra for each of the specialized AI visibility features, additional domains, and API access. Annual billing typically lowers the monthly rate but commits cash for a full year, while renewal pricing tends to rise over time.
Even that total excludes the largest hidden expense. A self-serve tool assumes the buyer will supply keyword strategy, content production, editorial review, backlink outreach, and CMS publishing. It can surface information without doing the work that information calls for. A report therefore represents an input to an SEO program.
What if the startup only needs the data? That is a reasonable position when someone already has the time and skill to act on it. Without that capacity, however, the subscription pays for information that does not become execution. Most early-stage B2B teams lack the headcount to close that loop. The cost comparison must therefore include the labor the subscription leaves with the buyer, which is precisely the gap a service offers to absorb.
What the done-for-you service model costs and what it actually transfers to the client
A scoped service costs more cash but leaves the team with less work to do itself. Keyword strategy, content production, link building, and reporting can be bundled into a retainer or project fee. The startup does not need an in-house SEO practitioner to perform every task. But outsourcing the work introduces a separate question. What does the client own, and what can it still access when the engagement ends?
An agency may keep the Search Console property, keyword exports, and content assets in accounts the client cannot access on its own. If access ends with the engagement, the startup may lose its search performance history, including its baseline and query data.
Reputable agencies may hand over access during offboarding. Ambiguity about custody and ownership can create risk even without malice, before anyone needs to resolve it. Search history is a company asset in the same sense as a customer database or trademark, so uncertain contractual reversion creates an intellectual-property risk as well as an operational problem.
What Google Search Console actually gives you and where it structurally cannot go
Google Search Console provides first-party evidence of how Google sees the startup’s site. Google’s Search Central guidance warns that third-party tools “don't have access to our internal ranking data” and that their predictions “may not happen.” That makes Search Console a foundation.
The evidence includes verified clicks and impressions, reports of crawl errors, Core Web Vitals diagnostics, and the queries shown to have led to impressions. Those query strings are raw material for a first-party keyword strategy. Yet they are not a complete record. Google anonymizes rare queries for privacy, leaving some clicks without a visible query. For a B2B startup trying to reach niche buyers, those missing queries may be the searches with the highest buying intent.
History has a boundary too. The Performance report retains roughly a year and a half of data, so a startup that has never exported older records may have lost the baseline needed for year-over-year comparisons. Search Console also shows only the startup’s own performance. Competitive research therefore requires a supplementary paid tool.
These limits define what the foundation can support. They do not make third-party estimates equivalent to first-party evidence, nor can an inexpensive stack remove Google’s query anonymization. The property the brand owns stays with it when tools and service providers change. Its value comes from keeping custody of the evidence while recognizing what that evidence cannot show.
The risk a startup takes when it connects a cheap tool to its Search Console property
When the startup connects a third-party tool, it gives the vendor permissions to access data through an OAuth grant. Those permissions may let the vendor read query data, have write access, or access multiple properties. The startup may also have little ability to audit what the vendor stores or how long it keeps it.
That makes a free tier a risk decision. Query rows kept on a vendor’s servers face risks from breaches, changes to who owns the vendor, and changes to its policies, but the monthly fee shows none of these risks. Control of the original property does not provide control over every vendor-held copy.
Client properties add another layer of responsibility. A startup with contractual data-handling obligations may need explicit consent before connecting a client’s Search Console property to another tool. The practical test, before making a connection, is whether the team can explain the OAuth scope, storage location, retention period, and permitted uses of the data. The team also needs to know whether the vendor’s terms allow aggregated client data to be used for model training or benchmarking.
Why all three models miss the same thing: AI answer engines are not reading ranked pages
A page can appear on Google’s first page and receive no citations from AI answer engines. Those engines retrieve passages and compose answers from them. A ranked page’s sentences remain eligible for selection, but its rank does not establish whether they will be selected for an answer.
Traditional rank tracking cannot measure that selection. Neither a service retainer nor Search Console data, by itself, reveals how ChatGPT, Claude, or Perplexity discusses a brand. A VP of Marketing asking for agency recommendations and a procurement officer comparing software vendors are conducting supplier research without starting from a conventional results page. Their questions can show a strong intent to buy even when the startup’s ranking reports show nothing about the exchange.
B2B buyers have moved meaningfully toward AI-first research, so a startup can fund a subscription, a service, and a well-maintained Search Console property while remaining absent from those answers. Paying for all three does not close the gap automatically. The response has two parts, namely content that can earn passage-level citations and instruments that show whether the brand actually appears. Both require a different test of success from ranking alone.
What content actually has to do to earn AI citations, and why volume without review fails
AI systems check claims against review sites, forums, publisher coverage, and company pages to judge whether they can trust them. More published pages do not resolve a contradiction between those sources. A content pipeline thus has to back up claims that readers can still trust when they see them outside the context in which they were written.
The company’s identity also needs to be consistent. Answer engines understand companies as entities with attributes, including what they do, whom they serve, and what they are known for. Inconsistent naming or descriptions across LinkedIn, Crunchbase, Wikipedia, and the homepage create attribution ambiguity. Conflicting descriptions make it harder to connect a claim confidently to the right company.
Draft review, editorial review, and scheduled content audits are required brand-safety gates. A subject-matter reviewer can bring first-hand examples, check primary sources, add original data, and supply an author’s credentials that automation alone cannot provide.
A July 2026 Microsoft preprint audited tens of thousands of accepted academic papers and found hallucinated references in the permanent scholarly record. The references looked valid and passed peer review while pointing to no real work. Brand content faces the same kind of failure when it cites sources that cannot be verified. Publishing more of it would multiply the exposure while leaving the evidence unimproved.
Independent coverage, listings on major review platforms in the brand’s category, and participation in forums that AI engines frequently cite contribute to the company’s entity signal. That work proceeds alongside sound on-site content. The operative variable is the pipeline’s ability to produce and support trustworthy claims, rather than the subscription tier that generates the most drafts.
How to measure whether any of this is working, across all three models
To measure results in 2026, the team needs Search Console evidence and must also track AI answers. The two systems expose different parts of discovery. Search Console records how the startup does in Google search, while prompt-based monitoring shows whether AI engines name the brand in the answers being tracked. Neither instrument can stand in for the other, regardless of whether a tool or service operates it.
Share of Answer measures the percentage of answers that name the brand across a tracked prompt set. It is a primary AI visibility metric because it observes presence where AI-first buyers are researching suppliers. Its scope still needs to remain clear. A mention is a lead-generation signal, and the metric’s scope is limited to the prompts being monitored.
Dedicated AI visibility tracking extends that observation across ChatGPT, Claude, Perplexity, Gemini, and other engines, with sentiment analysis to capture how the brand is discussed. Most tools built for traditional rank tracking do not yet cover that need, though specialist platforms are beginning to address it. The useful addition is an instrument that reveals a signal missing from the evidence the team already has.
For a startup choosing among these models, the practical starting point is to own the Search Console property and export its data on a schedule so the baseline is not lost. The team should then track AI referral sources in analytics and add prompt-based brand monitoring before it buys another SEO subscription. That sequence grounds spending in evidence the business can keep and use. The comparison then turns on what each model measures, what the startup owns, and what can compound over time.
Measure it before spending more on it.