Why Content Quality Gates Belong in Your Growth Pipeline, Not Your SEO Checklist
Quality gates catch weak pages before publication, making AI-generated content safe to scale.
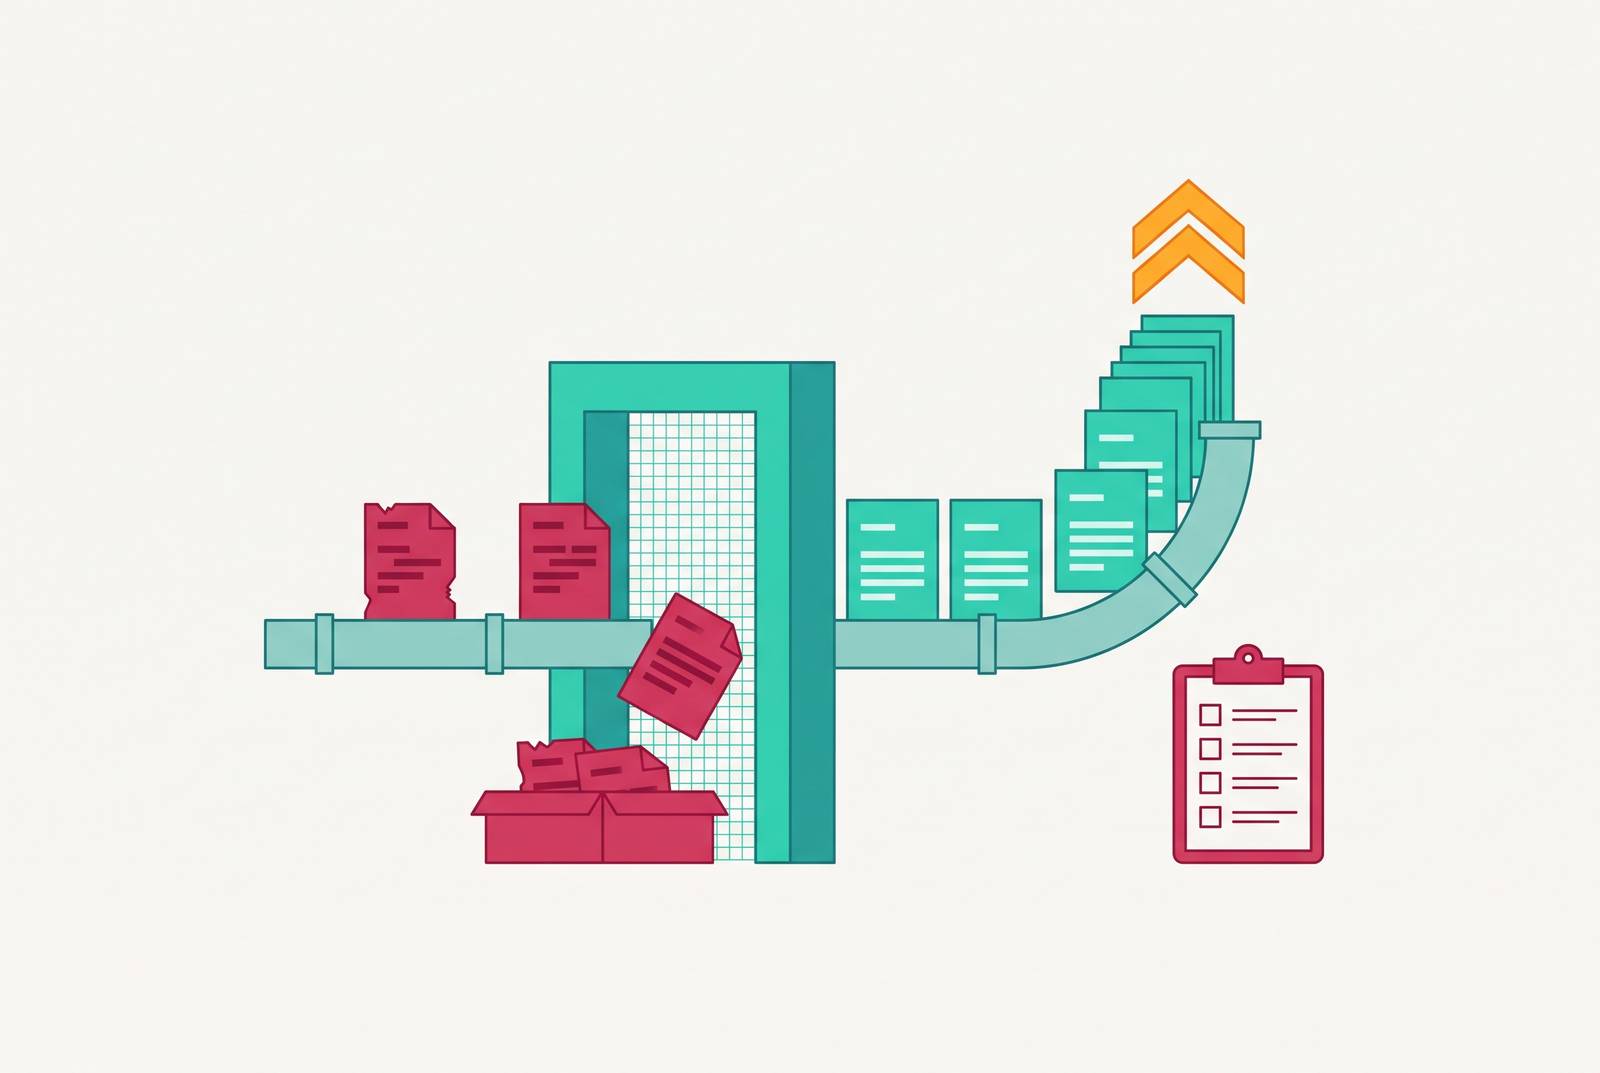
Content quality gates belong in the growth pipeline because they make fast publication safe to scale. Their job is to keep weak pages out of search results and produce evidence that AI systems can cite. For technical founders and growth engineers, that makes quality an enforcement layer in the publishing system.
Why the BrowserStack collapse is an engineering failure, not an SEO story
BrowserStack’s publication of 2,000 AI-generated pages in 24 hours, followed by a 70% organic traffic collapse, is a systems story before it is an SEO story. The key boundary was between generating a page and publishing it. Treating those as one step let pages reach production without an enforcement layer that could stop weak pages. At that velocity, post-publication repair cannot substitute for a release condition.
Would a software team describe the damage from pushing 2,000 commits without CI checks as a “deployment penalty”? It would identify the missing checks instead. The same reasoning applies to content, without requiring a claim about a particular Google penalty. AI generation was not, by itself, the failure mode. The engineering failure was that nothing stopped bad pages from shipping, so increasing throughput also increased the reach of every unchecked defect.
What a quality gate actually is, borrowed from the discipline that invented it
A quality gate is a rule that must pass before a pipeline advances. Failure stops promotion to the next stage. Adobe Cloud Manager’s CI/CD documentation applies that rule by evaluating code quality before staging and running automated tests before a production trigger fires.
Applied to content, automated checks come before human review. A draft earns access to the next stage by passing defined tests, and a human decision opens the final publication boundary. These are different kinds of control. Code can enforce uniqueness, factual density, and structural variance consistently, while a reviewer supplies judgment the checks cannot express. The resulting system can be composable, token-metered, and auditable because its conditions live in the pipeline.
The three automated checks that belong before a human ever sees the draft
Data sufficiency is the first check, and it belongs before generation. When most source records contain the same fields with the same values, better prompts cannot supply missing distinctions. A density gate counts how many unique data fields are filled in for each template. In the example given in the notes, a template has 14 data fields, and a row filling only 6 fails, preventing publication of a thin page padded with prose.
Uniqueness scoring runs after generation to catch internal near-duplicates. Python and sentence-transformers can provide similarity scoring using cosine similarity, but the test needs a clear purpose. Shuffled sentences do not make a page distinct. A distinct page answers something specific to its entity, using data that differentiates the subjects rather than a boilerplate introduction with swapped nouns. Internal duplication is also directly controllable because the publishing team controls the corpus against which each draft is compared.
Entity coverage checks whether the page’s stated subject shows up in named mentions, semantic associations, and structured data. A spaCy NLP pass can check for the primary entity early in the draft. The gate also needs at least one fact unique to that entity, drawn from source data. That last requirement is harder to automate reliably. Detecting an entity’s name is not the same as establishing that a claim about it is supported, so coverage alone cannot stand in for factual validation.
Why the gate must also check how the rendered page reads to an AI retrieval system
Quality now has to support citation. AI systems can decline to answer when evidence is weak or contradictory, so an indexed page with few extractable, contradiction-free statements may never enter an answer.
Both its accuracy suite and its AI-extraction gate had missed the problem. Passing both did not establish that the rendered schema was sound. The pipeline therefore gained a third gate, a 22-check schema graph audit of the rendered page.
Checks need to cover different failure surfaces. Heading structure belongs in this work because AI-generated drafts tend to overuse H2s, flattening relationships that need depth. H2s should name the main subtopics, and H3s should break them down where needed. A structural check therefore tests how the page organizes its evidence, rather than treating hierarchy as a cosmetic preference.
What the Strategized.ai pipeline actually produced, and why the gate sequence was the operative mechanism
Each passed three automated gates before human review. These were an accuracy suite of 96 to 109 assertions, a 22-check AI-extraction gate on the body, and a 22-check schema graph audit of the rendered page.
Zero factual retractions mattered most. One positioning update was owed after a competitor acquisition, which is a different class of change from correcting a fabricated technical claim. The client’s technical lead could not read every article line by line, while the accuracy suite could run on every draft. The gates replaced attention while leaving judgment to people. Their value lay in making repeatable checks independent of whether a specialist had time to perform them.
AI-generated images had previously passed with fabricated values embedded in the pixels, so every diagram and chart was generated with plotting code from the same verified reference data. That removed the image model as a source of invented values, without making the reference data infallible. The client approved every post before publication, but two posts published after a day and a half of silence exposed an approval-control problem. A standing weekly review slot followed, and the pipeline now stops at draft until a person publishes.
A replacement-guide article also appeared in Google AI Overviews on the morning it was published, August 14, 2026. Ranking places a page in a list, while grounding lets a model select evidence and fold it into an answer. Owned content that serves as the primary record has a different role from a page summarizing secondary sources, particularly when the model prefers the original evidence.
But what if an AI citation produces no click? That objection concerns traffic acquisition, whereas this architecture also serves brand infrastructure by earning a place in the answer itself. It does not establish a conversion outcome. A place in the answer helps explain why budgets need to account for more than click rate, and why the system needs entity consistency. Names, descriptions, founding years, and services must match across the website, LinkedIn, industry directories, and Wikipedia or Wikidata, because conflicting records weaken the evidence available for grounding.
How AI citation is currently distributed, and what the gap means for teams building ground-site and phantom-site strategies
Semrush calls the separation between brand mentions and source citations the “Mention-Source Divide.” Fewer than one in five brands are both mentioned often and cited consistently across AI platforms. Being named and being used as evidence are different outcomes. AI answer engines also disagree about brands more often than they agree, so visibility on one platform cannot establish coverage across the others. A single hero page is therefore an incomplete architecture.
Ground-site logic gives the brand an authoritative owned grounding page that serves as the primary record on a topic. Phantom-site logic distributes its presence across off-site sources that AI treats as axiomatic within the vertical. The two roles are complementary. The owned page anchors the record, while the distributed presence places consistent information on other trusted surfaces. The practical goal is to identify those vertical publications and secure mentions there.
Distribution also expands the number of places where information can drift. That makes gate enforcement a condition of the strategy’s execution. Source sufficiency, distinct claims, entity coverage, and consistent facts still need checking when production spans multiple surfaces. Without those controls, greater cadence puts citation quality under pressure. With them, the architecture can scale without treating each new piece as a fresh exception to the publication rules.
Measuring whether the gates are working: Share of Model as the operative metric
A pipeline needs outcome instrumentation as well as passing tests. Otherwise, it can become very good at enforcing rules that no longer serve its purpose. Share of Model, or SoM, measures a brand’s mentions divided by total brand mentions across all competitors in the tracked set. The denominator is brand mentions, not AI answers. The ratio can be tracked independently across ChatGPT, Claude, Gemini, and Perplexity to preserve the differences between platforms.
SoM tracks the share of mentions, but that share does not show whether those mentions come with citations. The Mention-Source Divide makes that distinction essential. A measurement layer must therefore observe AI citations as well as track the share ratio, rather than assuming that greater mention frequency establishes stronger grounding. GEO platforms instrument this layer separately from, and in addition to, traditional SEO analytics. Web traffic alone cannot show when a brand appears in an answer but gets no visit.
Teams need to set the baseline for that feedback loop before the content program begins. Gates then run on every published piece, while SoM measurement follows a cadence that matches publication velocity. Stagnation is a reason to investigate missing checks. Every check needs to remain version-controlled, auditable, and open to revision on evidence. A rule written six months ago for a different content type has no automatic claim to continued usefulness.
How to wire quality gates into an existing content pipeline as code, not as a process step
The implementation starts by making advancement conditional on a return value. Each check is a function with a threshold, a pass/fail return, and a log entry, and the pipeline cannot advance without a pass. The check itself belongs in version control with a commit history. A spreadsheet row behaves differently under pressure. Someone must remember to execute it, and neither a deadline nor team turnover preserves that memory.
For teams building this into an existing stack, the available primitives are straightforward. Python can run assertion suites and similarity scoring, sentence-transformers can supply cosine similarity, and spaCy can support entity coverage. n8n or an equivalent can orchestrate the sequence, with a custom schema endpoint for the graph audit. The checks need not share one implementation. They do need to test the appropriate artifact, including the rendered page wherever database values or templates cannot establish what was actually published.
Human review then occupies a defined chokepoint after automated checks and before publication. A person publishes from the draft state. That boundary preserves judgment without asking a reviewer to perform every repeatable test, while version control makes changes to the tests visible. A cosine similarity threshold of 0.82 that suited one content type may need recalibration as the corpus grows. Treating that threshold as permanent would turn executable code into another stale checklist.
The long-term asset is a publishing system that can learn from its outcomes without surrendering its release conditions under pressure. Each evidenced improvement can become a condition applied to later work, rather than advice that must be taught and remembered again. That is how quality compounds through a growth pipeline, while a checklist decays into a record of what the team once intended to do.