Why customer chat tools are a computational marketing problem, not a content one
Vendors need to shape AI answers before buyers arrive, not just optimize chat widgets for visitors.
Customer chat tools require computational marketing and content work. Good answers inside a chat widget help people who have already arrived. Getting the vendor into the AI answers that shape a buyer’s shortlist needs a different system, with machine-readable information, a plan for signal routing, and regular checks of whether the brand gets cited.
How customer chat tools are actually being evaluated today
Buyers increasingly start and finish product research inside ChatGPT, Perplexity, Gemini, or Claude. They ask for a recommendation suited to their business and receive a narrative that selects, compares, and explains options. The shortlist can form before a site visit. For a chat tool vendor, inclusion in that answer is therefore a distribution question, separate from how well the product would perform for the buyer.
AI chatbots, live handover, CRM integrations, and multi-channel routing recur across chat-tool feature sets, making a feature list less useful as a clear dividing line. A query such as “best chat tool for B2B SaaS” asks the engine to make that distinction instead. A vendor named in the answer gets compared before the buyer reaches a product page, while one left out may never get compared at all.
Why the content-first framing of chat tool marketing leaves the real problem untouched
The familiar approach treats a chat widget as a content asset. A team loads FAQs, writes the greeting flow, keeps the knowledge base up to date, and expects those changes to help the tool sell itself. Those are useful tasks with a specific boundary. They improve the experience for people who have already reached the tool, but they do not establish how its vendor gets named in an answer that precedes arrival.
That gap becomes clear when a buyer asks ChatGPT “what's the best live chat tool for a dev-tool company”. The response is a ranked narrative rather than a list of links that leaves all comparison work to the buyer. Better greeting copy cannot affect that earlier encounter by itself. A vendor missing from the narrative has a positioning problem that cannot be diagnosed solely by inspecting its product features or documentation.
Help-document page views, chat CSAT scores, and ticket deflection rates describe parts of the experience after someone engages. They cannot reveal an omission in an AI answer. A team can therefore improve all three while leaving the upstream distribution problem unexamined. Its instruments cover only part of the buying journey.
What computational marketing actually means for a chat tool vendor
The alternative treats marketing as a system with observable inputs and outputs. Its work includes instrumenting how engines retrieve and cite the vendor, routing signals to the platforms those engines draw from, and measuring brand presence across a defined set of relevant questions. Measurement shows where coverage is weak, and work on routing and retrieval gives the team ways to fill the gap.
The useful unit is an entity fingerprint. This is the consistent pattern of brand information, citations, schema, and structured content that makes a vendor legible across its retrievable surface. An engine may synthesize information from several places. Mismatched name, address, and phone data, missing schema, or pages blocked from AI crawlers can weaken that surface. Some problems concern ambiguity, while others prevent access altogether.
Token economics matters here because these pages are both something a person might browse and inputs that an AI system has to process. Yet token use alone cannot explain citation performance. The retrievable material needs to present a coherent brand and useful evidence. Structured information helps make the brand and its evidence clear without using length as a measure of quality.
Signal routing then concerns where that evidence appears. Different engines draw on different source patterns, so distributing the same material everywhere is not equivalent to covering those patterns deliberately. Visibility can be measured as Share of Model, or SoM, using brand mentions as a proportion of relevant answers across a defined prompt set. Keeping the distinction clear makes attribution more useful while keeping its claims within what the evidence allows.
How each major AI engine actually sources answers about chat tools — and what that means for signal routing
ChatGPT and Perplexity do not offer interchangeable citation environments. Their sourcing patterns overlap, but coverage of one does not establish coverage of the other. The directional pattern for ChatGPT includes Reddit, Wikipedia, Forbes, Amazon, Business Insider, TechRadar, and Reuters, with G2 also relevant to product comparisons. A presence on one source does not establish that a particular chat-tool query will cite it.
Perplexity draws especially on Reddit and YouTube, with G2 also among its sources. This gives walkthrough videos and substantive tool-comparison threads a role beyond sending visitors directly to a vendor’s website. They can become sources for an answer. The supplied sourcing detail does not establish an equivalent hierarchy for Gemini or Claude, so those engines need their own observation independent of ChatGPT’s pattern.
When an engine provides few citations, appearing on a small number of sources it selects can have disproportionate value. A more citation-heavy answer creates more opportunities for breadth. This distinction concerns the shape of the answer, and engine rankings and platform-specific citation counts require their own supporting evidence.
A vendor needs a distributed presence across relevant comparison pages, reviews, videos, and discussions alongside its owned blog. G2, TechRadar, YouTube, and Reddit are different parts of that surface. None substitutes automatically for the others. Because sourcing patterns can shift over weeks, the routing decision also needs monitoring. A configuration that once matched an engine’s sources is not evidence that it still does.
The two-layer architecture that turns chat tool marketing into a repeatable system
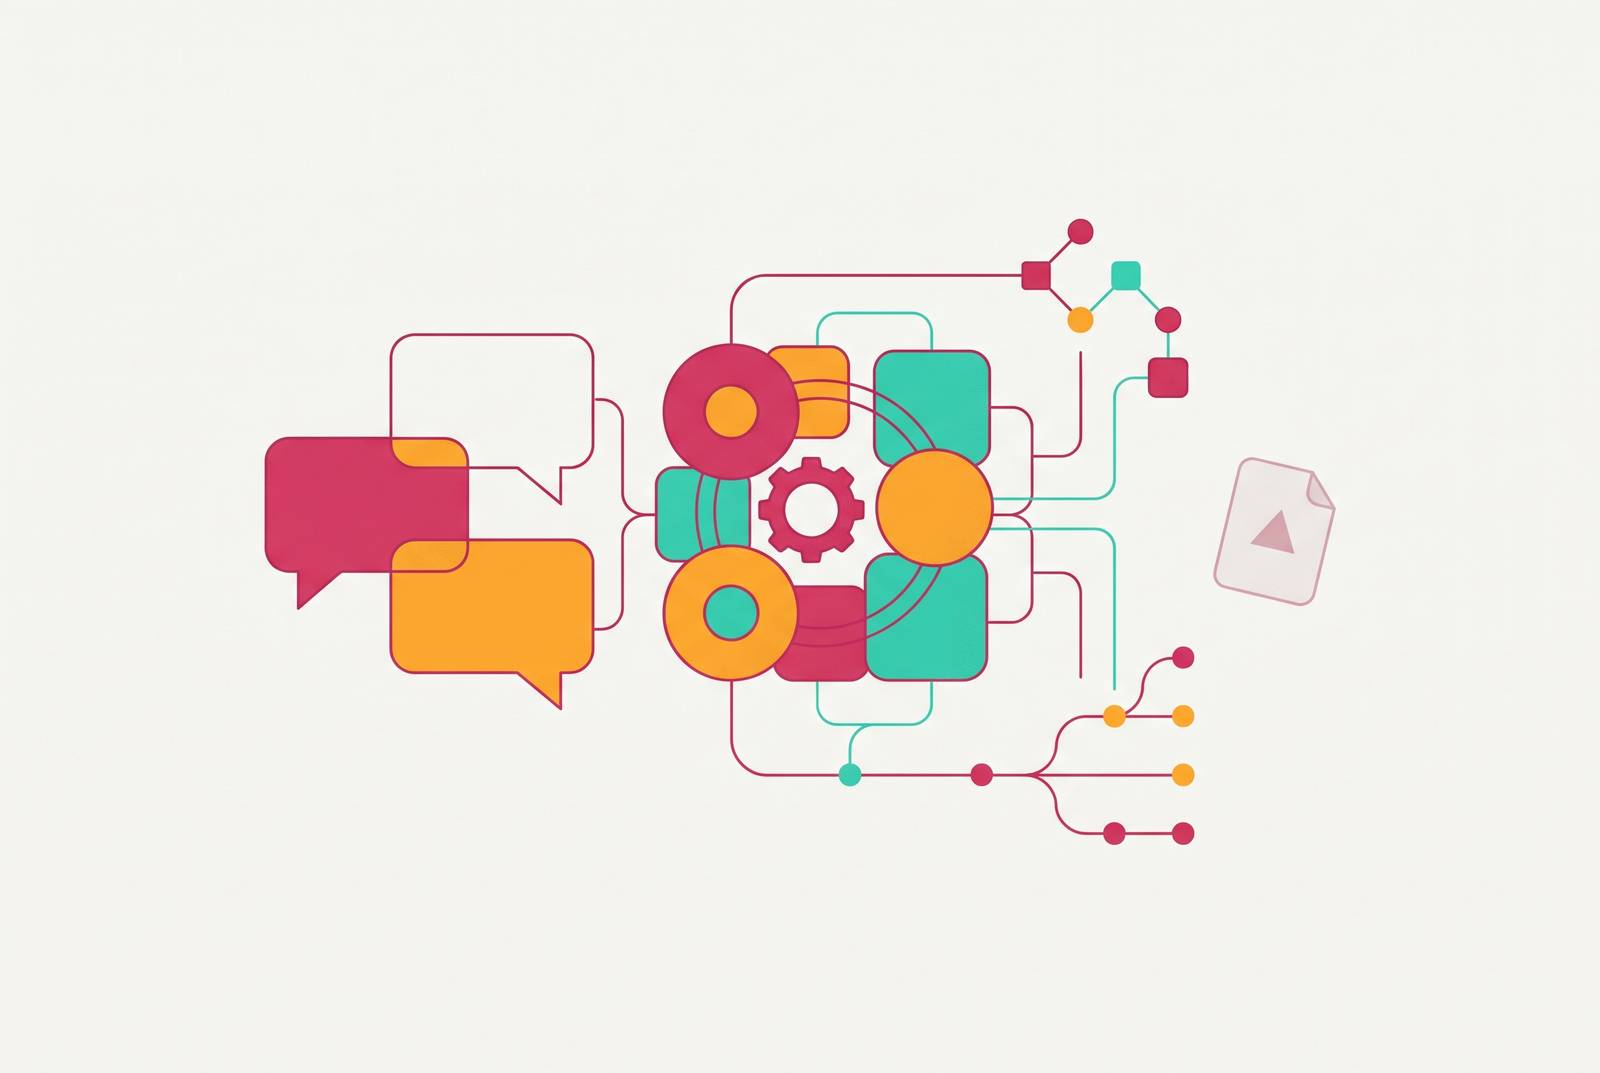
Layer 1 is the ground site, the site the brand owns that gives it a clear, machine-readable identity. Its job is to present consistent information that can be reconciled with directory listings, social profiles, and review sentiment elsewhere. The interface is the shared entity fingerprint. A third-party mention and an owned page should give matching identity details so it is clear that both describe the same vendor.
Schema markup belongs in this layer, using the appropriate page types, including Organization, Article, FAQPage, HowTo, and ItemList. Content also needs a form from which an engine can extract the relevant answer without relying on an unstructured block of prose. A live llms.txt file can point AI systems toward intended material, but it should not be treated as proof that an engine will retrieve or cite those pages.
Layer 2 is the distributed citation signal layer. It consists of third-party platforms that engines use as sources, including Reddit, Wikipedia, YouTube, LinkedIn, and Forbes, where relevant to the vendor and the question. This layer adds evidence from outside the vendor’s own claims. Its purpose is not simply to multiply mentions, but to place useful, consistent information within the source environments that the monitored engines actually draw on.
The layers depend on their connection. When a third-party signal points to a ground site with little information or details that clash, the engine has less solid material to draw on. At the same time, a clear owned site with little presence elsewhere has little reach into third-party citation sources. Both need to be managed as components of one system. Their shared interface is the consistency of the brand information and evidence, rather than a publishing calendar that happens to include both.
Why producing citation-worthy content at speed requires a pipeline, not a content farm
This architecture still needs strong content to function. It changes the production requirement from publishing more pages to producing structured, sourced, factually reviewed material that can support extraction and comparison. Speed is useful only within that requirement. A faster process that introduces doubtful claims weakens the evidence the rest of the system is intended to distribute.
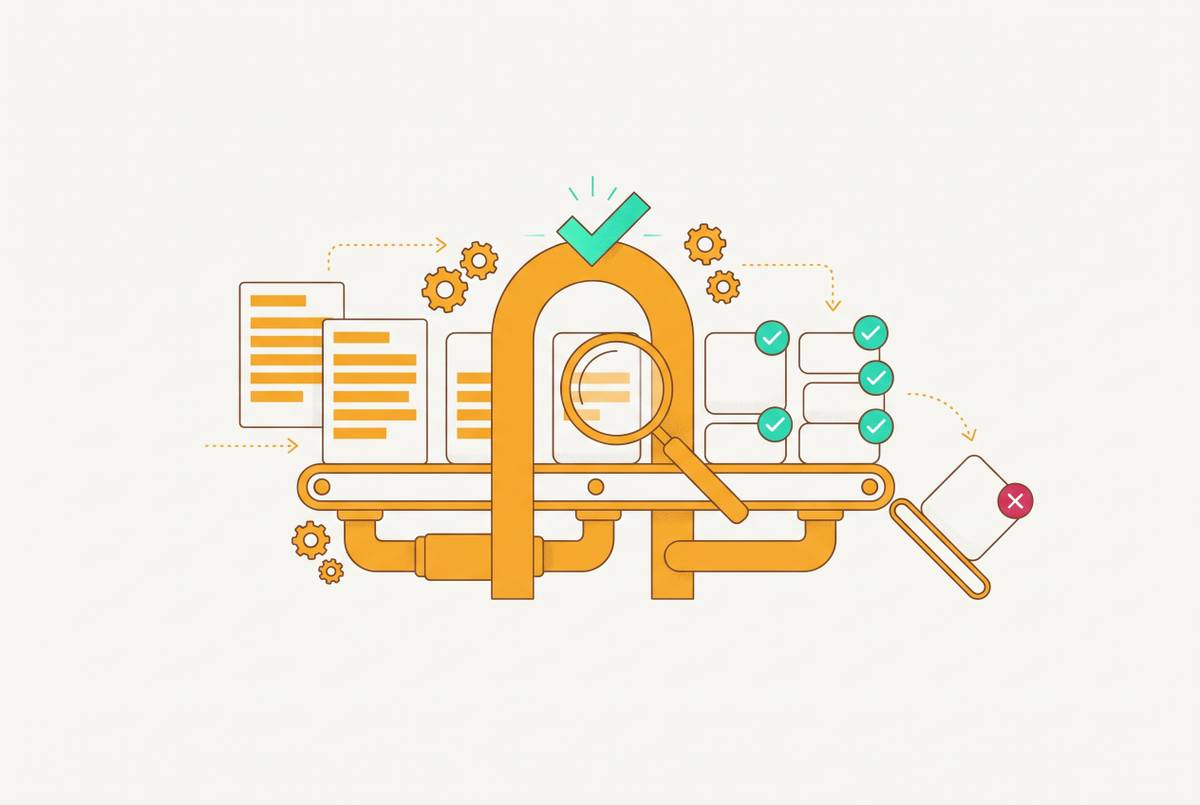
The proposed pipeline uses AI to speed up the work, with human review at every step. AI can draft a structure from brand voice parameters, while people contribute first-hand industry knowledge, check sources, and supply insights that a model cannot legitimately invent. These are different roles within one workflow. Human expertise is not a finishing touch applied after the draft has already set the factual direction of the page.
That division is necessary because fluent drafting does not establish accuracy. The same model that produces a useful outline can produce a confident, incorrect statement in the next stage. A content farm optimizes how much text exits the process, while this pipeline also controls what evidence enters it and which claims survive.
At moderate output, one content strategist can oversee the pipeline, while higher volume calls for specialized work from topic strategists, quality analysts, optimization specialists, and technical operators. The constraint is not drafting alone. Research, factual review, formatting, and system maintenance all require attention, so increasing model output without increasing oversight can simply move the bottleneck downstream.
The pipeline also needs an instrumented trigger for relevant change. A standing watcher can initiate a draft when a competitor earns a citation, an engine’s sourcing pattern shifts, or a new roundup appears. That trigger connects observation to production. Human review still governs what gets published, but the operation no longer depends entirely on someone noticing a change and remembering to put it on a calendar.
Measuring AI citation share rather than keyword rank — the metric shift that makes the argument stick
Keyword rank cannot describe the full result of an AI recommendation. Answers do not have fixed positions equivalent to a conventional search-results page, and a brand can be mentioned without being cited or recommended. The measurement unit has to reflect that difference. Citation Share of Voice asks what proportion of relevant answers mention or cite the vendor in relation to competitors.
To establish a manual baseline, a team runs a defined set of business-relevant prompts across ChatGPT, Perplexity, Gemini, and Claude, then records mention rate, citation rate, sentiment, and competitor positioning. These observations should remain distinct. A critical mention is not a recommendation, and a citation is not necessarily an endorsement. Keeping track of those differences makes it easier to tell what has changed later.
Bot-log analytics supplies a separate diagnostic view. Logs can show whether search crawlers such as OAI-SearchBot and Claude-SearchBot, and training crawlers such as GPTBot and ClaudeBot, are accessing site pages. The value of access is in diagnosing retrieval barriers before a team assumes that an absent brand needs more content. Classic page-traffic and SEO reporting cannot, by itself, explain whether an AI answer selected the vendor or a competitor.
The strongest objection remains that excellent content is the prerequisite. That objection is correct. Schema and distributed mentions cannot rescue material with nothing useful or credible to say, because the computational layer amplifies existing evidence. The reverse is also important, though. An excellent resource can remain difficult to retrieve or absent from the sources an engine selects, which makes editorial quality and distribution engineering complementary.
Volatility raises a second reasonable objection. If source preferences shift, does the system become an endless pursuit of a moving target? Citation share needs recurring, metered observation, much as a growth team measures conversion rate or CAC. Changes then become inputs to routing and production decisions. Without that feedback, a vendor has a publishing operation, but no reliable way to tell whether it reaches the AI-mediated comparison where the buyer is choosing.