Google's October 2026 AI content guidance: fact-checking is now a build step, not an editorial afterthought
Google now expects human fact-checking of AI content, metadata included.
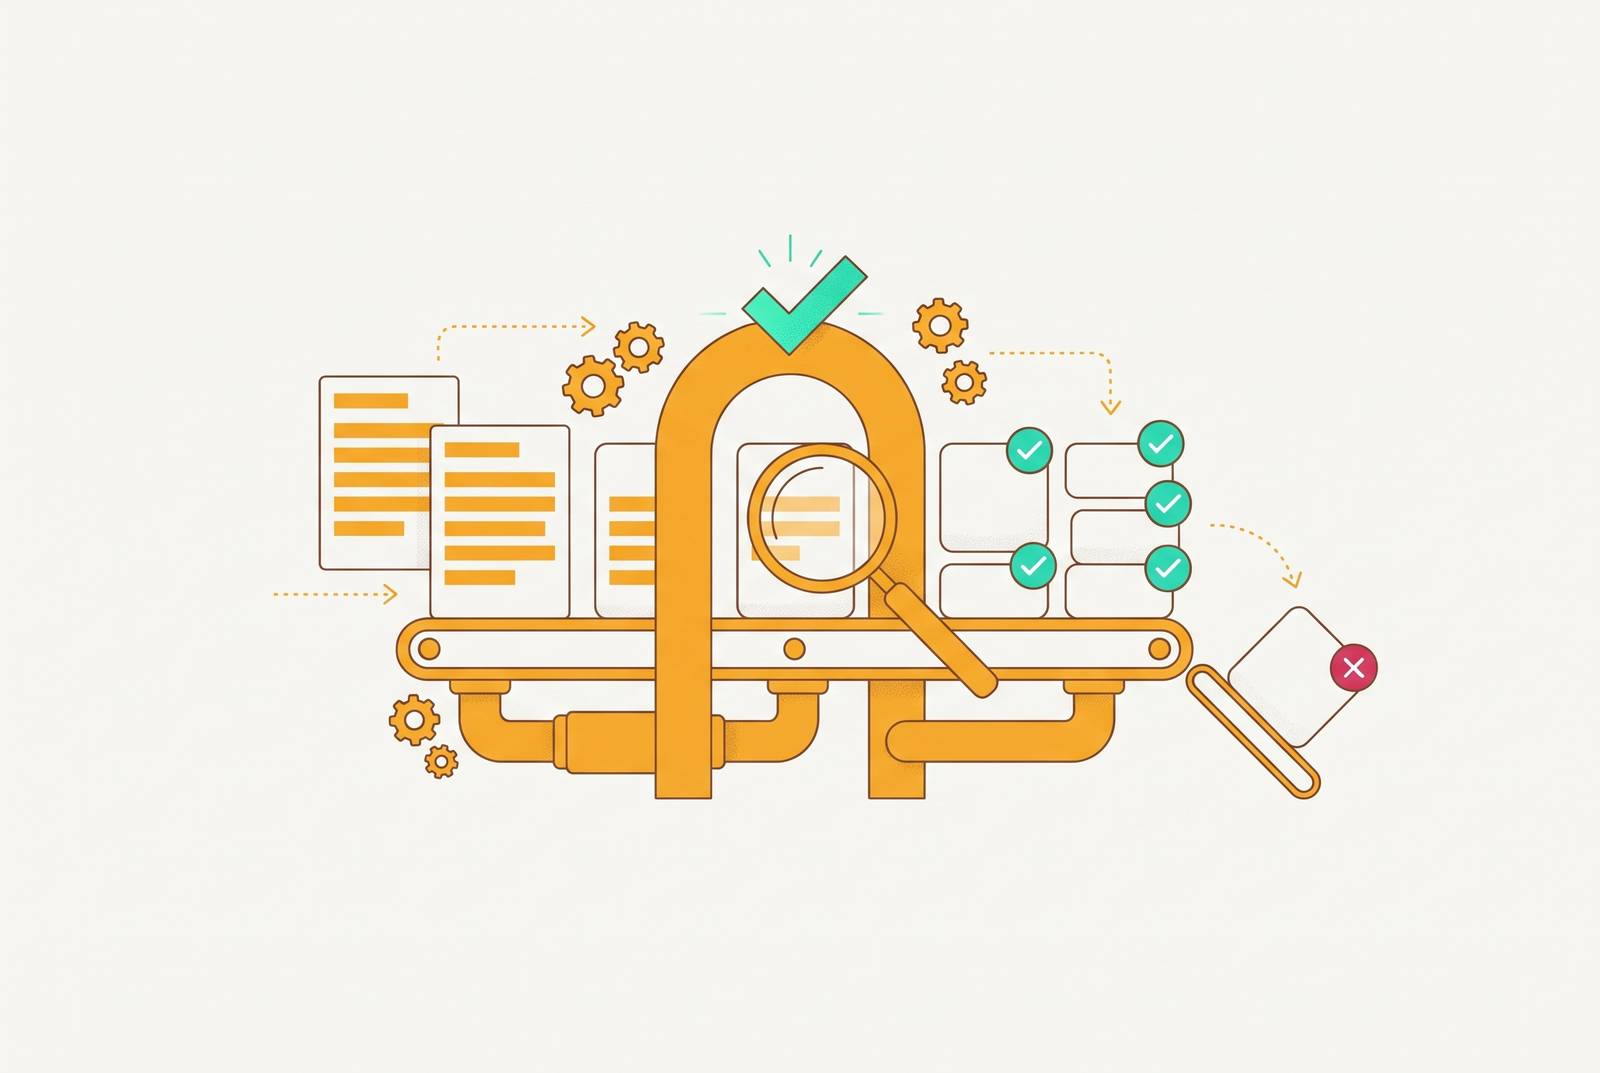
Google’s October 2026 AI content guidance makes fact-checking part of how teams design the pipeline as well as an editor’s final task. For technical marketers and agent-driven teams, the practical response is a distinct verification stage that covers body copy, metadata, structured data, and alt text, with human review before publication. The change announces no new penalty. It makes explicit an obligation that an automated publishing workflow must now account for.
What Google actually changed on October 1, 2026
Google’s October 1, 2026 update added three sentences to the Search Central section headed “Focus on accuracy, quality, and relevance” and reworded a connecting phrase. The rest of the page is unchanged. The new text explains that generative models predict likely sequences of words from training data rather than retrieve facts, so their output may contain inaccuracies, or hallucinations. Google then says it is “critical to manually factcheck and review all AI-generated content for accuracy and trustworthiness before publishing.”
The connecting phrase says that instruction also applies to title elements, meta descriptions, structured data, and image alt text. Those elements were already listed on the page. The change attached these elements to the explicit manual-review instruction. The scope is therefore broader than the article an editor reads, even though the list itself is not new.
Google’s helpful content page changed at the same time. It now names four attributes quality raters assess in main content, namely effort, originality, talent or skill, and accuracy. Automatically generating pages from feeds or producing large amounts of AI text without manual oversight or curation “represents little to no effort.” The page also identifies fabricated creator profiles, including fake names, AI headshots, and invented credentials, as deception.
Google did not announce a new ranking factor, AI-specific penalty, or enforcement action. Its changelog says the edit brings the documentation into sync with presentations used at developer events. The pivot is the word Google chose for the review obligation, “critical.”
Why writing "critical" into documentation changes the obligation, even without a new penalty
Written guidance gives teams a standard against which their publishing process can be judged. Before the update, fact-checking was implied good practice. Now, publishing AI-generated material without that review plainly conflicts with Google’s stated guidance. That distinction could become relevant if a manual action is ever reviewed, but it does not mean the edit itself introduced a new route to punishment.
Is that really a change if low-quality bulk content was already covered by Google’s spam policies? It is a fair objection to claims of new enforcement. Google has named unsupervised AI output as a specific failure mode, leaving less room to treat fluent text as sufficient evidence of quality. A team can no longer point to the absence of an explicit instruction as a reason for omitting review.
Quality raters do not directly decide a page’s rankings. Their assessments help Google evaluate its ranking systems, while the attributes they assess describe the qualities those systems are built to reward. This makes effort and originality relevant even when no rater inspects a particular page. Review is not simply preparation for an individual inspection.
For teams publishing at volume, the updated page also cross-references the scaled content abuse policy. That policy covers making many pages with the main aim of manipulating rankings instead of helping users, however those pages are made. The documentation update landed during the September 2026 spam update rollout, but timing alone does not establish a new enforcement connection. Does the workflow include the oversight that the written guidance now explicitly calls for?
Why metadata is the gap most AI pipelines leave open
Body copy is the obvious place to look for invented claims because it is the part an editor usually reads. Metadata is easier to overlook. These fields are often generated in bulk or written when someone closes a publishing ticket, after the main article has received attention. As a result, a reviewed article can still ship with unreviewed claims attached to it.
A title element, for example, can promise a figure, date, or verdict that the page never supports. That promise appears in the result headline before a reader reaches the supporting text. A meta description can introduce a different error by rounding a statistic carelessly or inventing a number altogether. Both fields make claims of their own. An accurate paragraph does not validate a number that exists only in the description.
Structured data creates a related gap between visible content and machine-readable statements. Dates, authors, prices, and ratings in schema markup must match the page. A wrong product price in schema is not merely an awkward summary, because it presents Google with a factual value that conflicts with the visible information. The new wording makes clear that this field must be reviewed.
Image alt text has a different audience and the same need for accuracy. Generated text, which is indexed and read aloud by assistive technology, can describe an absent image or assert a product detail unsupported by the image. A plausible description is therefore not enough if it describes something other than the image.
For B2B teams that make comparison pages, integration pages, or industry use-case pages, each new page adds more fields to check. The gap occurs wherever the workflow treats these fields as blanks to fill in without checking their claims. Automation without review is precisely what makes them risky.
Treating fact-checking as a discrete, designed pipeline stage rather than a final-pass habit
The response is to separate creation from verification. For a team redesigning its pipeline, that means making human review a named gate that cannot be skipped, rather than a habit that depends on who finishes the ticket. The purpose is to stop production speed from determining whether a claim receives scrutiny.
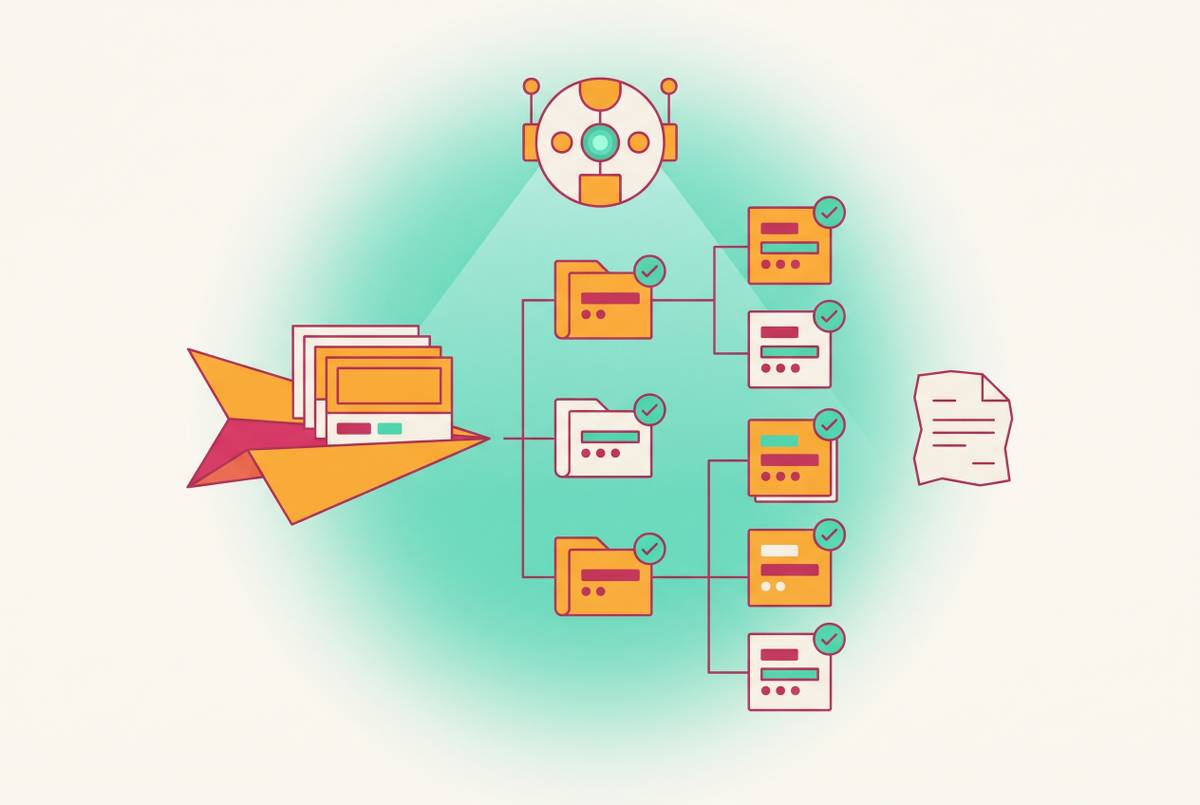
The workflow starts with a draft, goes through automated claim flagging and a human review gate, then moves to metadata review before the content is published. Agentic execution can operate across those stages. However, it does not remove the human checkpoint. The reviewer inspects flagged claims and decides how to resolve them, while the overall review still covers the accuracy and trustworthiness of the content. An absence of automated flags is not the same thing as completed manual review.
Claim flagging can point to statements that need a check, while a person must decide whether the evidence is strong enough to publish them. AI drafting compresses production time while leaving the time needed for accountability unchanged. A real edit still includes verifying statistics, adding proprietary examples, refining voice, and tightening structure.
For metadata, the practical choices are to review every generated field or constrain generation to facts the system already holds. A product price can come from the product record. That constraint reduces the model’s freedom to introduce an unsupported value, but it does not make the published field irrelevant to review. The final title, description, structured data, and alt text still need to fit what the page and image actually support.
There is also a difference between correcting a draft and contributing something worth publishing. Google’s effort test asks what a person added that the model could not have produced. Testing a product, gathering original figures, building a tool, or taking a stand worth defending gives the piece more to say. Just rewriting AI sentences adds little under that test.
Treat verification like a CI gate, with the permanence of a linting or deployment check. A polish step treats the content as almost ready, with a need for a few improvements. A gate decides whether it is ready at all. When review is incomplete, publication is blocked rather than allowed to proceed on the expectation that someone will return later.
What the same content must now satisfy in AI answer engines, not just Google
Visibility increasingly includes being selected, cited, and summarized inside answers from ChatGPT, Perplexity, Gemini, and Claude, alongside occupying a place on a results page. This changes the role of a published claim. It must be accurate on the original page and useful as evidence when an answer engine draws on it.
Practitioners distinguish two related jobs in this environment. AEO focuses on becoming the direct answer in featured snippets, knowledge panels, AI Overviews, voice search, and People Also Ask boxes. GEO aims to get a brand into generated answers when AI systems cite, quote, or recommend a source. The distinction is useful, but neither job is served by making unsupported statements easier to extract.
Why does accuracy affect which pages get picked as well as whether readers trust them? AI answer engines check E-E-A-T consistency, mentions, and credibility signals across a site as well as backlinks. A hallucinated statistic therefore weakens the basis on which a page can serve as a grounding source. It is not only a conflict with Google’s publishing guidance. It gives an answer system unreliable material to use.
Consistency between pages is part of that problem. Two pages on the same domain can each sound authoritative while making contradictory claims about the same topic. A grounding system can interpret the conflict as a quality signal and cite neither source. Reviewing a claim only within the boundaries of its own draft can therefore leave a wider inconsistency unresolved.
Microsoft’s Bing Webmaster Guidelines express a similar expectation of oversight. Large-scale content generated without quality control or editorial review may be excluded from indexing, and removal from the index also removes it from Copilot answers. This is a different mechanism from an answer engine choosing between possible sources. Both mechanisms, however, show why fact-checking is not merely a Google-specific compliance task. Content must meet the rules for discovery and be trustworthy enough to serve as evidence in an answer.
How to know whether the pipeline changes are working by measuring AI citation and brand presence
Passing the review gate shows that content made it through the publishing process. It does not show that an AI answer engine selected it. A brand can rank well in Google while remaining absent from generated answers, or appear regularly in one engine and rarely in another. Search rankings alone cannot resolve that difference.
The measurement response is to track brand mentions across ChatGPT, Claude, Gemini, and Perplexity, log which pages receive citations and in what context, and monitor whether generated answers repeat the brand’s published claims accurately. Otherwise, strong results on one platform can conceal an absence on another. The same distinction applies to mentions and citations, since seeing a brand name does not by itself explain which page supplied the answer.
Clear, accurate passages with original information and cited sources give an answer engine material it can use. Generic AI text that repeats what others already agree on gives it little reason to choose that page over another.
What should a team conclude when a reviewed page is never cited? The team should ask about the page’s originality, structure, or credibility markers as well as whether it follows the rules. Non-citation identifies a page whose discovery performance needs examination despite having passed the publication gate.
The measurement loop therefore has two distinct jobs. It observes whether reviewed content earns citations, and it checks whether AI systems repeat the content consistently with what the brand publishes. Those findings make the verification stage more than a record of completed checks. They connect the discipline of publishing trustworthy material with evidence of whether that material becomes a source for AI-generated answers.