An AI CMO needs a supervisor, but a person re-reading drafts doesn't scale: how a technical founder instruments the review instead
Risk-tiered routing and logged decisions replace the human proofreader.
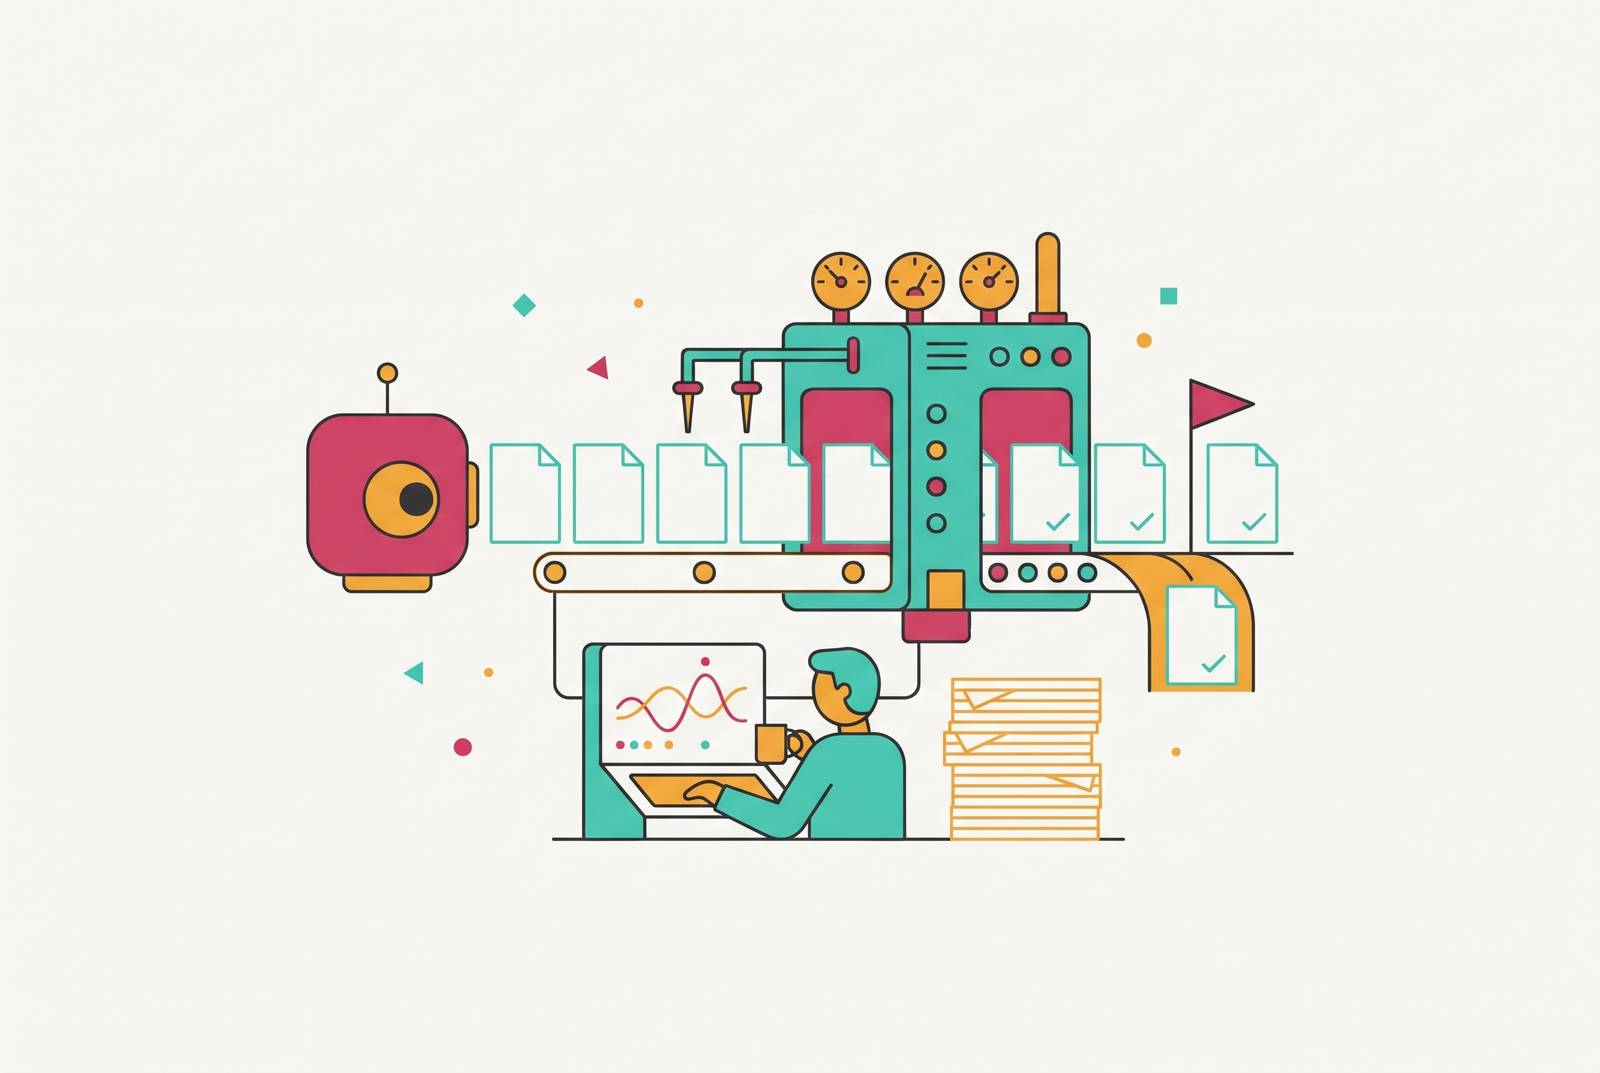
An AI CMO needs supervision, but having a person re-read every draft turns that supervision into a bottleneck. For a technical founder, the better approach is to instrument the review itself. Checkpoints that people can observe, risk-based routing, and a record of decisions can keep people in control without relying on a human reader to catch everything before generated text is published.
Why technical founders are buying "AI CMO" systems and what they are actually getting
An AI CMO is an integrated system of specialized AI components. An orchestration layer ties together the work of budget allocation, creative drafting, performance optimization, and cross-channel execution. The appeal to a lean founding team is straightforward. The team buys software that promises to keep working across the marketing loop in place of a senior hire who would cost more. That promise covers much more than writing copy.
But coordinating tasks is not the same as owning their consequences. The system does not own brand positioning, answer to the board, make reputational calls, or reliably recognize when its output is wrong. Those responsibilities stay with people, even when the software takes over execution. What, then, has the founder actually bought? A system that can perform marketing work, but still needs a governance layer that determines when its work is safe to use.
BCG's 2026 CMO survey found that the vast majority of CMOs report significant AI transformation of their function. BCG's June 2026 research nevertheless found that only 8% are running campaigns where multiple AI agents act autonomously. The gap is governance and data. For a technical founder, that makes the missing layer an engineering problem dressed as an editorial one.
Why the gap between AI marketing ambition and autonomous execution is a governance problem, not a capability one
The mismatch between ambition and reliable execution has four structural sources, including talent, organization, governance, and measurement. Talent and organizational gaps affect who can operate the system and who owns its decisions. But governance and measurement offer a more direct lever for a technical founder. Both can be addressed through instrumentation.
Governance deficiency means the system has no defined mechanism for recognizing that something has gone wrong. There may be no confidence threshold that pauses output and no audit trail recording why a decision was made. A draft that reads well can then move ahead even when there is no clear reason to trust it. Better writing does not fill that gap. The missing component is a rule that connects a detectable condition to a controlled response.
Measurement infrastructure lag creates a related problem. If feedback arrives weekly or monthly while the system publishes continuously, a person may discover an error only after it has shipped repeatedly. A team in that position should apply familiar production API practices, including instrumentation, thresholds, alerts, and exception routing. The purpose is not to make the model infallible, but to stop uncertainty from passing through the system without anyone having to resolve it.
What breaks when a person becomes the quality gate for machine-scale output
Either that person becomes the slowest part of the system, or the team starts bypassing review to preserve speed. Neither outcome fixes the underlying design. Fully autonomous pipelines can miss voice drift or misinterpret internal data, while a final catch-all review discovers problems only after they have compounded. The person has to check everything, with no clear decision to make.
Moffatt v. Air Canada shows why bypassing oversight is not a harmless shortcut. The British Columbia Civil Resolution Tribunal decided the case in February 2024 after a passenger relied on wrong advice from a chatbot about bereavement fares. The tribunal held Air Canada liable for negligent misrepresentation by its chatbot. It rejected the airline's argument, characterized as treating the chatbot as “a separate legal entity.” Delegating the answer did not delegate responsibility for it.
A company allows AI-generated content to publish with minimal oversight, public errors accumulate, and the entire program has to pause. That is the failure mode a review system must prevent. The technology need not differ from that of a well-governed program for the outcome to differ sharply. Yet assigning every draft to one person merely relocates the weakness, because sustaining machine-scale review invites shortcuts or burnout. The system needs a way to hold back risky output while letting the rest of the work go ahead.
Replacing the human reader with observable, automatable checkpoints
The practical alternative is to make the human a decision point. To build that arrangement, a founder should define conditions that stop publication and route the output to someone equipped to resolve them. This works much like a circuit breaker in a distributed system. Work goes ahead until a condition trips and the system asks a person to decide what to do, so a failure does not pass unnoticed.
Start by wiring three kinds of trigger into the review path. When a confidence score falls below a set threshold, the draft goes to a subject matter expert before it can be published. A match for regulatory or legally sensitive terms routes it to a compliance reviewer. A brand voice deviation above a defined threshold sends it to a brand editor for tonal correction. These are different decisions, so they should not disappear into a generic request to “review the draft.”
Next, make the evidence available with the output. Retrieval-augmented generation, or RAG, grounds drafts in a curated corpus and attaches source snippets, so a reviewer does not have to reconstruct the basis for every claim. Traceability becomes part of the output itself. After generation, automated checks compare numbers, dates, and named entities with canonical internal sources, including the CRM, product catalog, and pricing sheets. Unresolved mismatches go to subject matter experts before anything ships.
Wayfair used AI to enrich product-attribute data across millions of legacy listings, with human-in-the-loop auditing before changes went live. The example illustrates the production pattern rather than a promise that automation needs no supervision. Auditing sat before propagation, where it could constrain what reached the public.
Classifying content by risk before it enters the pipeline
Output checks become more useful when the system first decides what kind of work it is handling. Risk classification at intake sets how much people need to be involved before generation begins. Not every draft deserves the same path. A headline drawn from approved copy and a security representation have different consequences if they are wrong, so treating them alike either wastes review effort or leaves serious claims under-supervised.
The three-tier model makes that distinction explicit. Low-risk work includes internal brainstorms and headlines derived from approved source copy, which can move with minimal or no human review. Medium-risk work includes thought leadership, product messaging, and positioning, which must go through editorial and subject matter review at a set gate before they can be published. High-risk work includes legal claims, pricing statements, financial projections, security representations, and public-policy content. It requires a named approval path, and some of it may be inappropriate for generative AI drafting altogether.
A classification prompt can evaluate the brief against that taxonomy before the content agent runs. Its result determines which checkpoints activate. Low-risk work bypasses most gates, while high-risk work triggers all of them and may need approval of the brief before generation. Once that routing is in place, the next question is what the governed pipeline is publishing toward.
Why the quality of what ships determines whether the brand gets cited in AI-driven answers
For a B2B founder, the destination is increasingly an answer. Generative engine optimization, or GEO, means structuring content so platforms including ChatGPT, Perplexity, Google AI Overviews, Gemini, and Claude can select, cite, and surface a brand in synthesized answers. That is distinct from ranking in search results. The review system therefore has a growth role as well as a protective one, because it governs the source material those answers may use.
The platforms do not all favor the same material. Perplexity rewards specific, experiential content, with community discussion disproportionately represented in its citations. Claude favors fewer citations of higher quality and content that goes into depth. Gemini leans on Google's Knowledge Graph, making structured entity data useful. These differences affect what earns attention, but they do not remove the shared need for credible material that an answer engine can extract and substantiate.
For B2B citations, long-form content outperforms short content because models need depth from which to extract authoritative passages, while buyers expect rigor. Depth alone is not enough, however. Content that buries its conclusion under a preamble is difficult for an answer engine to use. The Aggarwal et al. GEO study found that adding credible quotations, statistics, and citations meaningfully raised a source's share of the generated answer. It also found that restructuring content alone raised citation rates across six generative engines.
This connects publishing discipline to the chance of citation. Hallucinated claims and factual errors undermine the credibility and verifiability that answer engines weigh, while voice drift weakens the brand's control over what it says. More output cannot repair an unreliable foundation. The checkpoints that catch these problems before content is published also help make it a source that others can trust.
What the governed pipeline publishes toward: ground sites and content designed to be retrieved
A governed pipeline needs a publishing target built for retrieval. A “ground site” is a canonical, crawlable, human-readable property whose primary purpose is to give AI retrievers clean, authoritative, source-citable content. It provides the retrievable foundation from which answer engines can draw, while remaining readable to a person who wants to inspect the source.
That purpose changes how a passage should be written. A clear question should lead to a direct answer in the first two or three sentences, with supporting detail following. The answer comes before the elaboration. This structure gives a model composing a response a passage it can lift with confidence, without making a human reader work through a long introduction.
An llms.txt file is worth adding because it is cheap, but it is not an established citation lever. It has been shown to make documentation easy to load into AI coding assistants and developer tools. The choice of sources can also help, because the citation hierarchy favors established analyst and research sources first, then major consultancies, then industry trade publications. Citing up into that hierarchy can increase the probability of being cited back, provided those sources actually support the claims being published.
How to measure whether the instrumented pipeline is actually working
AI visibility is directly observable. The measurement layer should track whether ChatGPT, Claude, Gemini, and Perplexity name and cite the brand in responses to relevant queries. Traffic and rankings cannot substitute for that signal, because neither shows what an answer engine actually included in its response.
Search performance needs its own measurement path. Content built to rank on Google does not always earn AI citations, and content built for citation does not always rank. The two jobs should be tracked separately. Otherwise, success in one can hide weakness in the other, leaving the founder without a clear view of what the publishing system is accomplishing.
Confidence scores, risk classifications, human intervention events, and routing decisions form an audit trail that can inform an assessment of where the pipeline produces citable output and where it produces noise. Citation rate by content type, topic cluster, and platform then shows which outputs are worth producing at scale and which risk classifications need recalibration. Human judgment governs not just the exceptions that stop publication, but the rules that determine what the system should attempt next.