Analyzing a competitor's website is a research task until you turn the findings into a change: how technical B2B teams close the gap between a competitor teardown and a shipped page
Four defined handoffs carry competitor research through to a live page.
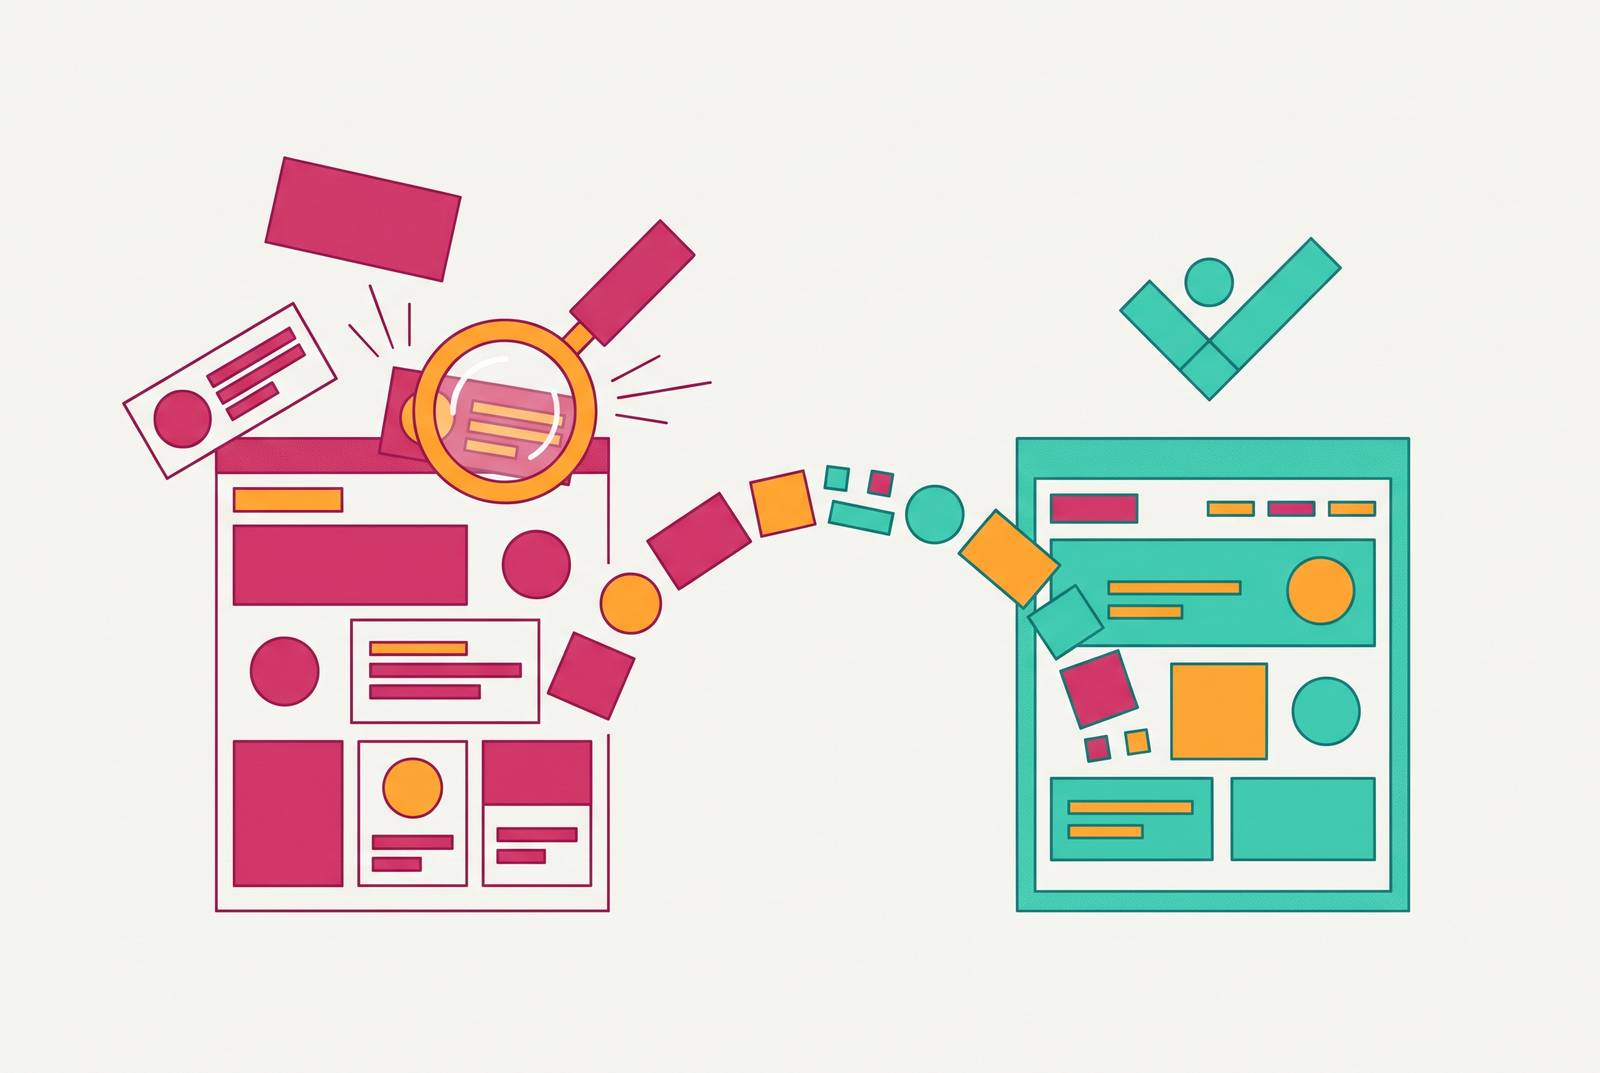
A competitor website teardown is a research task until its findings change a live page or a live deal. For technical B2B teams, closing that gap means managing four handoffs, namely gather, judge, translate, and ship. Each needs a defined output and someone responsible for moving it forward. Monitoring and AI citation measurement then make the work repeatable and keep the findings current.
Why a competitor teardown almost never ends in a shipped page
A team can spend hours collecting screenshots, comparing features, and recording pricing without changing anything a buyer sees. A shared-drive slide deck is not a comparison page, an updated battlecard, or a shipped landing page. Activation failure is the central problem. More research cannot fix a workflow that has no way to turn evidence into action.
Where, then, does the work stop moving? The work usually stops moving at a boundary between jobs. Gathering establishes what is known, judging decides what it means, translating makes it usable for production, and shipping puts it in front of buyers. Each handoff asks for a different kind of work, so completing one does not automatically start the next. Treating the teardown as a single research assignment hides those boundaries and leaves the next person to work out what to do.
What a competitor's website actually contains and what most teams miss
The homepage is a billboard. Specific assets reveal where a competitor commits to claims, including comparison pages, pricing pages, feature pages, case studies, and docs. A capability with a dedicated page has a different place in the sales story from one buried in a bullet. Public pricing, partial pricing, and “contact sales” also expose different choices about what buyers can learn before speaking to someone.
The useful reading goes deeper than a feature count. Which rivals earn comparison pages, and which customer profile keeps appearing? Changelog cadence and docs depth provide further signals, though docs depth is only a proxy for customer volume. Repeated category terms in the navigation, hero, and footer deserve more attention than a one-off campaign slogan or a generic brand adjective.
Time adds another dimension to that reading. A pricing edit, a retired feature page, or a new comparison target records a decision someone approved. The Wayback Machine provides dated snapshots going back years, allowing a team to compare those decisions over time to infer strategy.
The gather handoff — scoping the teardown so it can finish
The Flares competitor teardown template, updated 4 Aug 2026, starts with “Teardown scope” before asking for findings. It requires one specific product or tier and one question, such as “why do buyers say their setup is fast?” That constraint gives the research a stopping point. Without it, every interesting page can become another branch of the investigation, producing more screenshots without getting closer to an answer.
The tier also sets the limits of the evidence. A trial usually exposes only the entry tier, so its findings cannot quietly stand in for an enterprise offering. The template records the “version or date of the build” and a “next teardown” date because software changes weekly. It also separates observed facts from a “not verified” column. An inference can help the team decide where to look next without counting as a finding.
The question determines which sources belong in scope. A live deal calls for pricing pages, comparison pages, and recent reviews, while a positioning decision calls for the homepage and customer stories at two points in time. A build-vs.-buy decision needs release notes, help docs, and reviews that cover specific features.
The judge handoff — distilling forty observations into one win line
The distinction is useful because observations do not decide their own significance. Someone must write the sentence that changes what a rep says or what a page claims. A one-page account of reasons for winning, reasons for losing, and traps to set forces that judgment more directly than a 40-slide teardown.
What makes the sentence more than a confident guess? The Flares template gives the judgment layer its own section, “What it reveals about their strategy,” asking what product decisions suggest about priorities and what might come next. Giving the analyst’s name also helps readers judge how that person has read the evidence. A product manager and a sales engineer can notice different things, and their roles make potential blind spots easier to recognize.
Good analysts may already compress findings naturally. That is a fair objection to adding another formal step, but compression alone does not assign the work. A strong insight can still sit untouched when nobody owns its consequence. The judgment output therefore needs “decisions, owners, and dates,” with three to five rows separating what sales says now from what product does later.
The translate handoff — turning a finding into a brief a writer can ship
A win line tells the team what to argue. It does not yet tell an author what page to produce. The missing translation often appears as a vague task to update a comparison page, with the author left to reconstruct the research and choose the angle. A structured brief removes that extra interpretation by turning the competitive decision into a defined writing assignment.
The critical output is a one-sentence article angle that positions the new page differently from the competitor’s H1. If that sentence cannot be written, the page has no thesis yet. The brief also identifies which part of the competitor’s site prompted the response and connects the angle to the dated evidence. A comparison page naming the team’s product as a rival calls for a different response from a pricing change that undercuts its entry tier.
That distinction becomes especially important in an AI-assisted content pipeline. The research brief is the input to Stage 1, so its quality shapes the first draft and the amount of editor rework downstream. Even a better drafting model cannot make up for a competitive judgment left out of the brief. Translation is where the team resolves that judgment into an argument the production workflow can use.
The ship handoff — what gets in the way between a finished brief and a live page
A finished brief can stall just as completely as an unfinished teardown. The blockers are structural rather than motivational, including no page owner, no review gate, no publish queue, and no separation between reviewed and unreviewed AI drafts. The publish path needs to be defined. Otherwise, the research has merely moved from one waiting place to another.
In an AI-assisted pipeline, automated checks test whether the facts agree and the writing follows the brand voice, and a human must sign off on high-risk content. The artifact enters the publish queue only after the required checks and approvals pass. The template’s decisions section connects findings to that path through an owner, deadline, and success criterion, such as “alert relevance appears in more competitive win reasons.”
Comparison pages and category pages are common outputs because they respond directly to the competitor’s page decisions. Timing affects how useful that response can be. A defined publish path lets a team act on a pricing alert within hours, while an undefined one can leave the same finding for the next quarterly review.
Keeping the teardown current — monitoring as the trigger for the next cycle
The River analysis framework treats “when to check it again” as a first-class column in the competitor grid. A date records when something was true, leaving its continued validity to be checked. Monitoring supplies the next trigger. Pricing and comparison pages need the most frequent checks because changes can come without notice and affect deals directly, while feature pages and the changelog need a review each quarter. Homepage positioning needs a review at six- and twelve-month intervals.
Looking back at earlier pages helps the team see how the edits behind those alerts fit together. For pricing-page archaeology, the recommended approach is to open one Wayback capture per quarter for the past two years and note each change. A dropped free plan, an entry price raised twice, or listed prices replaced by “contact sales” can reveal a direction that the current page alone conceals.
A material change should not wait for another full teardown. A pricing restructure, new comparison target, or retired feature page reopens the judgment and translation work immediately. The team starts with the scope and evidence it already has, which saves it from doing the research again. The template’s required “next teardown” date keeps this return path attached to the original artifact.
The AI visibility gap that a shipped page alone cannot close
The loop still has a blind spot if it watches only websites and search rankings. In many B2B categories, buyers can begin with a generative AI question about which vendors to shortlist. ChatGPT or Perplexity can return named options with reasons before the buyer visits a website. A competitor included there gains an upstream advantage that a comparison page cannot address if the buyer never reaches it.
Does the teardown show that advantage at all? If it does not, the team may be judging the competitor’s pages without seeing how buyers first encounter the brand. Appearing as the default citation for a category query belongs in the competitive scorecard with keyword rankings and pricing. The win line must account for that presence rather than assume every buyer starts with a page comparison.
This expands the scope of the four handoffs, and the page still needs evidence, an angle, review, and publication. But shipping it establishes only that the content is available. It does not establish that an AI answer engine will retrieve, mention, or cite it.
What determines whether AI answer engines cite a brand
Many AI systems use retrieval-augmented generation to base answers on outside sources as well as training data. Some systems do not use RAG, and RAG can retrieve sources from curated databases as well as live web pages. The competition is for inclusion in the evidence set. Content that is structured, machine-readable, and authoritative helps make a brand’s claims usable in that set, though publishing it alone does not ensure it gets in.
The owned content layer, or “ground site,” needs to support machine extraction. That includes structured data, FAQ depth, specific named claims with verifiable sources, and answers to the exact questions buyers ask AI engines. The off-site “phantom site” footprint has a separate role. Third-party mentions, earned industry citations, and community presence provide corroboration beyond what the brand says about itself. Branded web mentions correlate more strongly with AI visibility than backlinks alone, but correlation is not a promise of citation.
The team needs to measure that presence before trying to improve it. The recommended baseline uses relevant category prompts across ChatGPT, Perplexity, Gemini, and Claude. It records mention rate, citation rate, sentiment, and where competitors appear in the same answers. Those measures distinguish being named from being used as a source and extend the teardown into a channel the website audit cannot reveal.
Running the full sequence — from competitor change to shipped page to measured citation
For a technical B2B team, the sequence begins with one product and one question, with AI-answer competitors included in the scope. Gathering produces dated observations with source citations and clear limits on what was observed. Judgment compresses those findings into a win line and assigns decisions, owners, and dates. Translation turns that decision into a one-sentence article angle and structured brief.
Consider a pricing-page restructure that monitoring picks up. The alert returns the work to judgment rather than restarting the entire investigation, and the resulting decision moves into translation without waiting for the next teardown cycle. In an AI-assisted pipeline, that brief becomes the Stage 1 input. The draft then passes the defined review gate before entering the publish queue, with an owner and success criterion attached to the work.
Publication does not end the measurement cycle. Pricing-page alerts continue to track the conventional web, while standing measurement follows brand mention rate and citation share across the AI answer engines. Those results show what has been published and give the team evidence for its next decision.