B2B demand generation, reframed: why the tactics list era is over and what computational marketing replaces it with
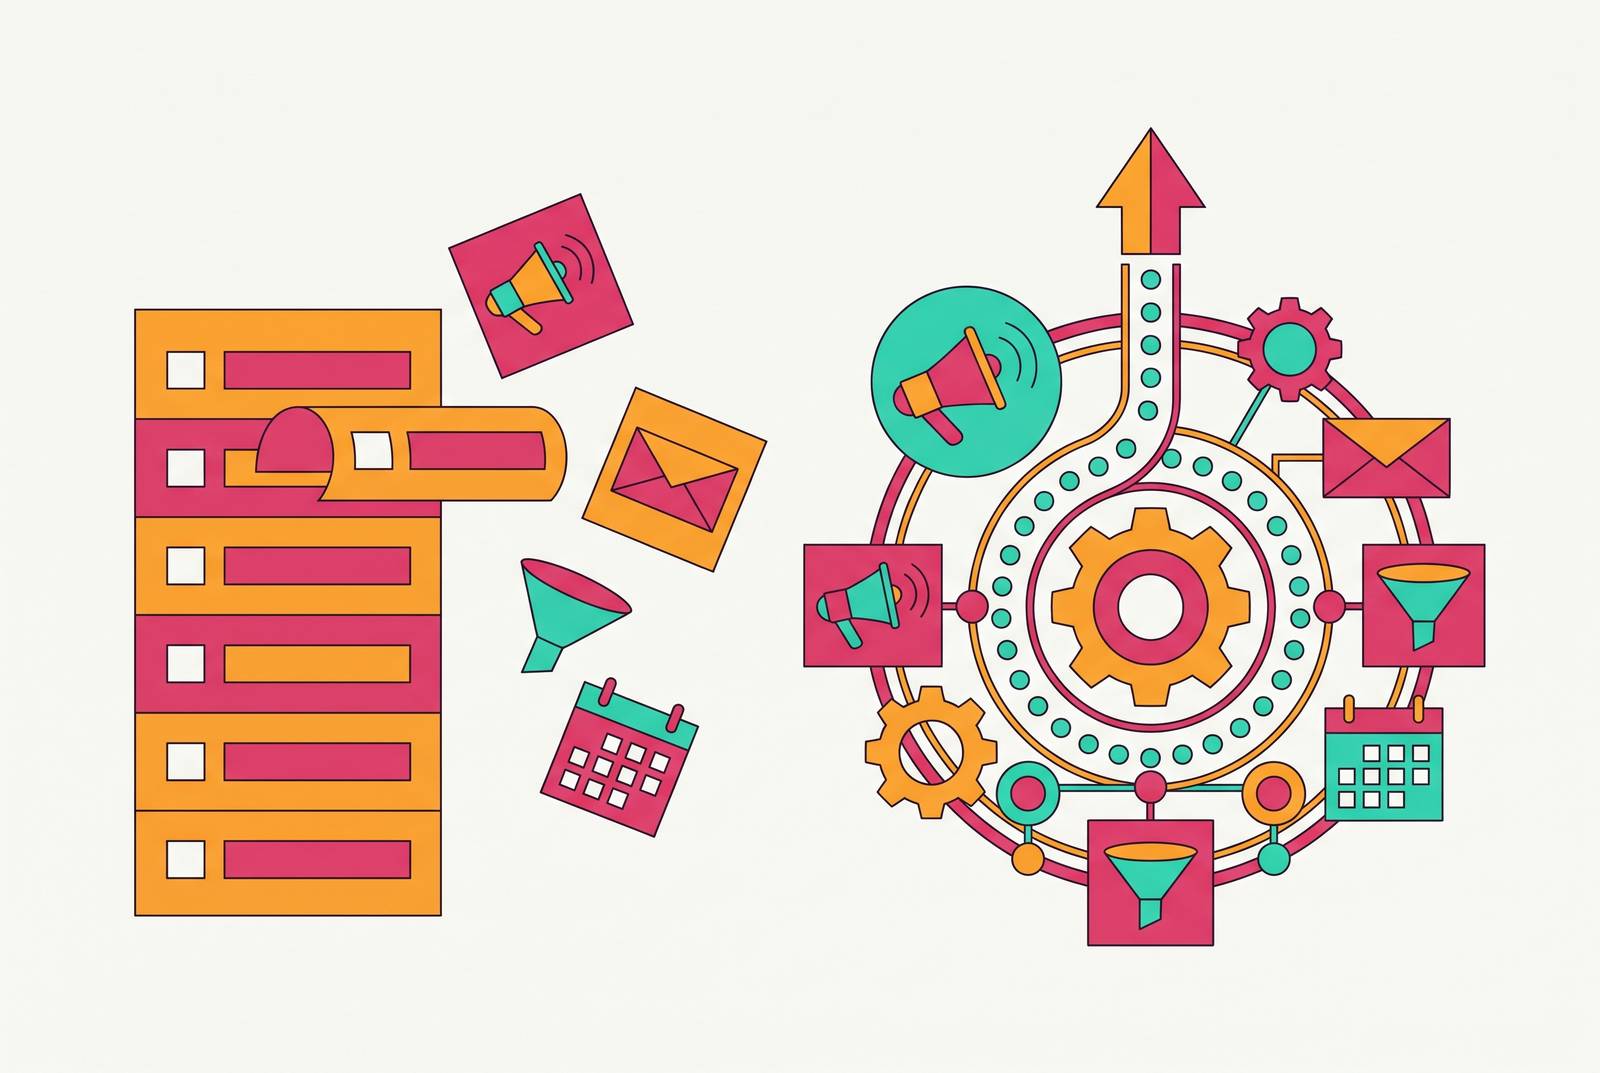
B2B demand generation needs a different operating model. The old model counted what teams published and which leads they captured without showing whether either had shaped what buyers preferred. Computational marketing replaces that blind spot with a measurable loop, connecting continuous publishing, visibility in AI answers, and downstream demand signals so that each content action can inform the next.
Why the tactics-list model was structurally broken before AI arrived
The old demand-generation model could not see the part of the buying journey where preferences formed. B2B buying journeys are largely complete before a buyer contacts a vendor, yet the familiar scoreboard began with that contact. Marketing-qualified leads, gated-asset downloads, and email open rates made activity visible without establishing whether the brand had influenced the decision. The measurement started too late in the journey. A form fill could capture preference that already existed while revealing little about how it developed.
That gap explains how teams could publish regularly, run automation, and still struggle to defend their pipeline contribution. Buyers were learning through LinkedIn, Slack, and podcasts, where last-touch attribution could not follow their path. Demanding a tracked form before granting access made content harder to consume in those settings, while decaying contact data weakened the capture process itself. Any tactics list operating inside that model would face the same problem, because choosing a channel was never equivalent to knowing whether it shaped demand.
How AI-mediated discovery turned a measurement problem into an existential one
AI answer engines now sit at the point where buyers begin vendor research and form consideration sets, sometimes before a traditional search query. A brand absent from those answers can miss the shortlist before its lead-capture machinery has anything to record. That makes the measurement failure more urgent.
This is an acceleration of dark social. A buyer can develop a shortlist inside a ChatGPT or Perplexity session without leaving the trail that conventional attribution expects. Being named gives a brand a place in that evaluation, but the mention itself need not produce a click. By the time the buyer reaches a vendor website, preferences may already be sticky. Showing up then means competing against a ranking formed elsewhere, rather than helping the buyer decide what belongs in it.
What if the brand already ranks on page one for its category terms? That is useful evidence about search. Google rankings and AI citations have decoupled, so a strong organic position does not guarantee inclusion in an answer. These are separate visibility problems to measure.
What "computational marketing" actually means as an operating model
Computational marketing treats each content action as an instrument to tune against observable signals. A piece becomes an instrument when the team can examine whether it changed AI citation rate, branded search volume, or direct traffic, adjust it, and observe what follows. Without that feedback, publishing remains a guess. The distinction is not whether software helped create the page, but whether the team can use evidence from its performance to make the next decision.
A tactics list ends with a publishing decision. A demand operating system connects a trigger to a segment, a message, a channel, a measurement, and a next action. Content, brand, and automation thus work as parts of one system instead of as departments that each have their own targets for how much work they do. The loop extends from lead counts to revenue signals. Its logic is closer to a flywheel than a linear funnel, because one action is meant to strengthen the conditions under which the next action works.
That model has three interdependent layers, beginning with continuous publishing infrastructure that keeps useful material available to the indexes AI engines draw from. AI-answer visibility becomes a first-class signal, with citation rate in ChatGPT, Claude, Gemini, and Perplexity tracked as well as organic rank. The measurement layer then tracks branded search lift, AI citation share of voice, and direct traffic as well as form fills. Publishing supplies material, visibility shows whether engines select it, and downstream signals help establish whether that presence connects to demand.
Why open, crawlable content is the prerequisite, not the strategy
Answer engines can only cite content they can retrieve. If a brand’s strongest explanation sits behind a form, that explanation is unavailable to the engine at the moment it could help answer a buyer’s question. The content may exist, but it cannot perform that role. For AI citation, gating is therefore not simply a conservative distribution choice with a different conversion rate. It blocks access to the material the brand wants considered.
LLMs do not execute JavaScript, so content that depends on client-side rendering can be invisible to the crawlers feeding ChatGPT and Perplexity. Server-side or static rendering makes the explanatory content retrievable. This is an admission condition. Passing it does not establish authority or earn a citation, but failing it prevents the content from competing on its merits.
The objection that open content sacrifices lead capture assumes the form is the only worthwhile measurement point. Branded search lift, AI citation rate, and traffic from named AI referrers give teams other signals they can track without a gate. Answer-first writing places a direct response immediately after the question, rather than making the reader or engine work through a long introduction. That structure is cited more often, and the first portion of a page generates a disproportionate share of citations. The questions should address what buyers need, including devices and local needs where they matter, instead of coming from keyword clusters picked just because they fit a publishing plan.
How the citation footprint works: owned content and the third-party layer
An accessible owned site is necessary, but much of a brand’s AI citation authority develops on properties it does not control. The owned property, or “ground site,” provides a crawlable, server-rendered home base with answer-first content and schema markup. The “phantom layer” consists of editorial coverage, review platforms, community discussions, and syndicated publications. Those external properties supply much of the citation footprint. Distribution is therefore part of the operating model.
This changes the relationship between authority and links. Brand mentions correlate more strongly with AI citation probability than backlinks, challenging the assumption that link equity alone is the best guide to visibility. That correlation does not make every mention equally useful. The relevant mechanism is that engines preferentially draw from sources they already treat as authoritative. Distributing content across third-party news and editorial sites can produce measurable citation lift because it places the brand within that source layer, rather than relying entirely on what the brand says about itself.
There is also a compounding effect, though not a guarantee. When a brand appears for a prompt, it is somewhat more likely to appear again in the next same-day observation of that prompt. A missed brand is likely to be missed again. Early presence can reinforce itself, while an unobserved gap can persist without triggering anything in a lead report. Citation presence needs deliberate cultivation across both the owned site and third-party ground.
The publishing infrastructure that makes compounding possible
AI answer engines respond to freshness and signals that a brand remains relevant and is evolving. Publishing on cadence gives them those signals more consistently than a campaign followed by silence. Continuous presence therefore requires a continuous production process. The workload spans the ground site, the phantom layer, and multiple external properties. Most B2B teams have not yet moved from experimental AI workflows to systematic production, leaving a gap between teams with a functioning pipeline and those using AI for individual drafts.
A pipeline assigns repeatable work to AI and reserves decisions that require judgment for people. AI handles research aggregation, outline generation, draft production, and variants for different formats and channels. Human review begins before a full draft consumes resources. The brief sign-off includes scrutiny of the outline, the draft sign-off includes a skeptical fact-check that tries to disprove claims, and final approval governs publication. These named gates make review part of the production architecture rather than an informal promise to check the work later.
The alternative is not simply to hire more writers. At the cadence needed to maintain freshness across this footprint, human-only production cannot sustain the same scope without a pipeline. Yet removing human review defeats the purpose. Publishing lots of content that is wrong or unhelpful can weaken citation authority by giving engines reason to distrust the source. AI production therefore requires governance alongside efforts to increase output. A pipeline creates compounding value only when its throughput preserves the usefulness and accuracy that make the content worth retrieving.
Measuring AI citation as a demand signal, not a vanity metric
The measurement layer starts with a fixed set of buying-intent prompts based on questions customers actually ask. Running those prompts on a schedule against ChatGPT, Copilot, Gemini, and Perplexity makes changes observable over time. For each answer, the minimum record includes whether the brand appears, its position, the sentiment of the mention, and whether the engine cites a link. A mention and a referral are different events. Logging both keeps teams from assuming that no one saw the brand just because no one clicked.
Google AI Mode cites a source in the vast majority of B2B answers, while ChatGPT does so in a substantially lower share, with the gap varying further by citation-rate metric. ChatGPT and Perplexity also draw from domain sets with little overlap. Presence in one does not establish presence elsewhere. Position is volatile too, and a brand cited today has only a moderate chance of appearing for the same prompt tomorrow. Repeated observations distinguish a persistent gap from a single missed answer.
Dedicated tools make that observation practical. Semrush’s AI Toolkit tracks across ChatGPT, Perplexity, Google AI Overviews, Google AI Mode, and Gemini. Ahrefs Brand Radar covers AI Overviews, AI Mode, ChatGPT, Perplexity, Gemini, Copilot, and Grok, with measures including mentions, citations, AI share of voice, and estimated impressions. Coverage is only the starting point, however. Those measurements become useful when teams use them to decide what to publish and where to share it, instead of keeping a separate score of where the brand appears.
Downstream analytics then test whether some of that presence produces visits. GA4 can isolate sessions whose source contains “perplexity.ai,” “chatgpt.com,” “chat.openai.com,” “claude.ai,” or “you.com,” allowing teams to examine traffic from named AI referrers. Ahrefs found that AI-referred visitors at one B2B property converted at a much higher rate than organic visitors, even though they made up a small share of traffic. That concrete demand signal supports examining what AI-referred visitors do after arriving, while recognizing that referral analytics cannot capture every answer a buyer consumed.
This changes what a team does next. Instead of treating publication as completion, it observes citation gaps, adjusts content or distribution, and reads subsequent visibility together with branded search, direct traffic, and pipeline outcomes. Citation rate is the upstream signal that shows whether the brand is being named before buyers raise their hand, though it does not prove that every mention led to revenue. The measurement layer closes the loop the tactics-list model never could.