Content types and deliverables: why the agency taxonomy doesn't map to how technical buyers actually think about marketing output
Technical buyers care about discovery, evaluation, and internal selling—not format labels.
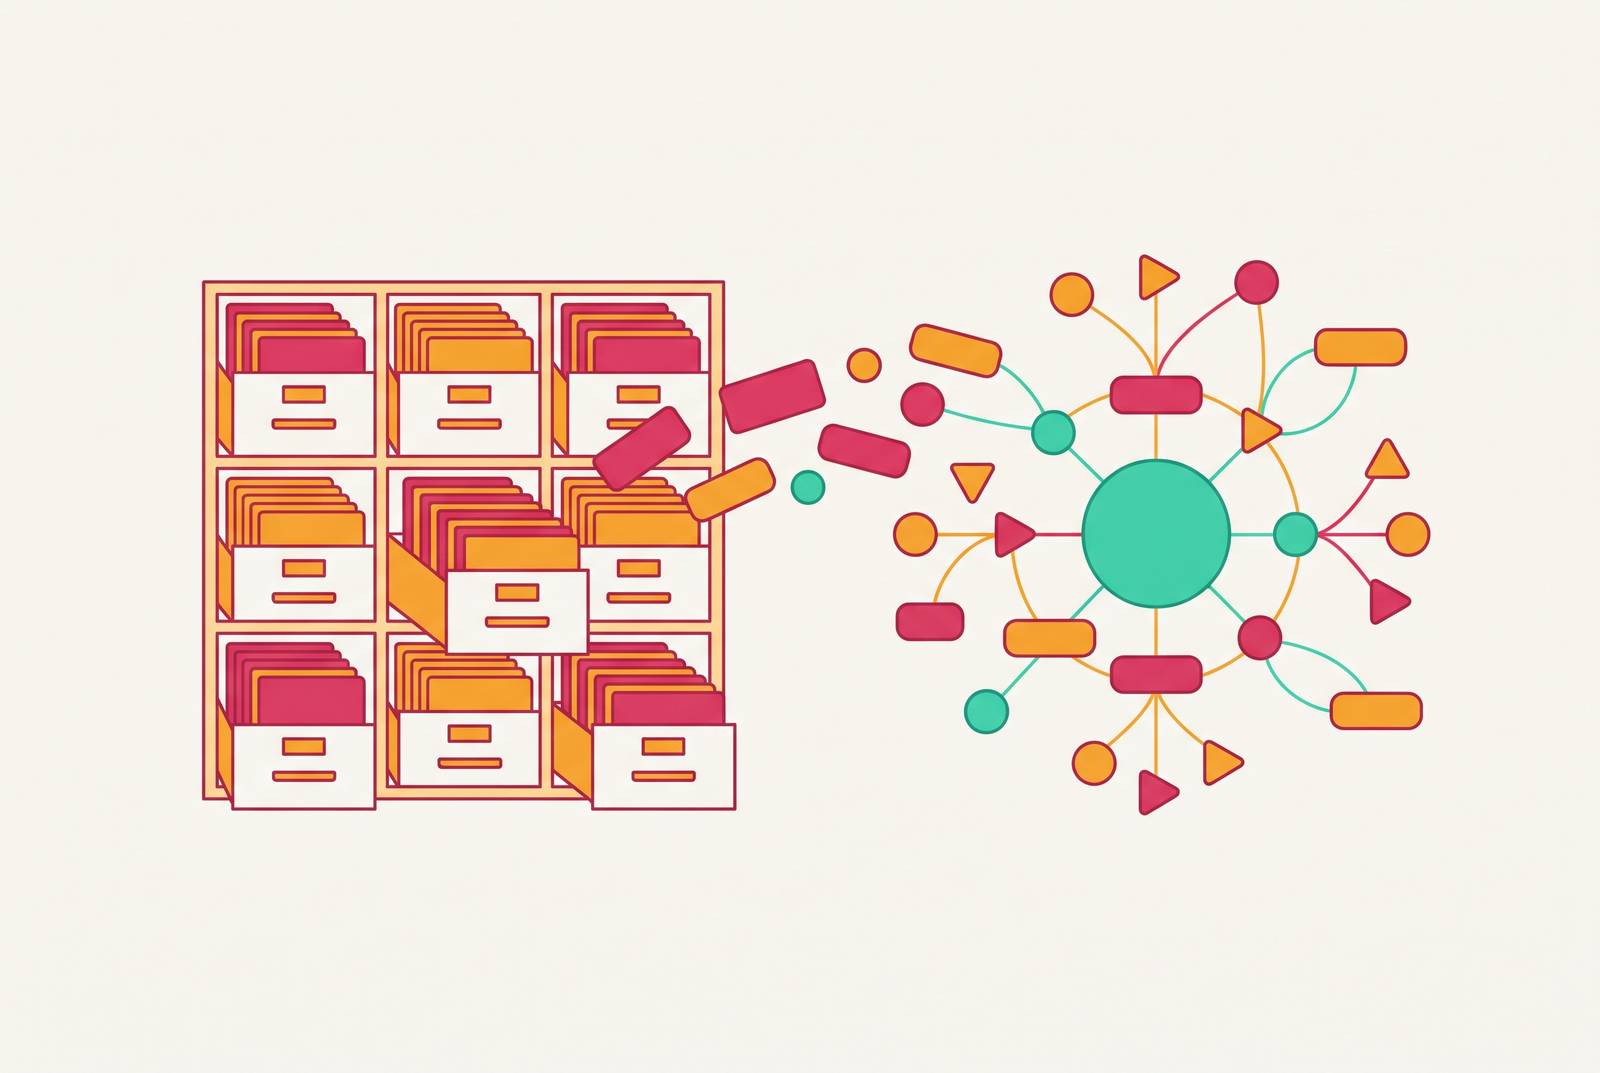
Agencies classify content as blog posts, whitepapers, case studies, and other deliverables because those labels make work easy to scope and buy. For technical buyers, the useful distinction is what helps them discover a vendor, evaluate it, or sell the choice internally.
How agencies classify content and why that classification exists
A deliverable gives procurement a defined piece of work to compare. A proposal for blog posts, tutorials, landing pages, whitepapers, and case studies names recognizable units of work. Those units can go into a statement of work, receive a price, and move through an approval process. Their boundaries help both sides agree on what is being bought. That is a legitimate function, but it is not a model of buyer behavior.
The categories also reflect different costs of production. A blog post takes time to write, a whitepaper takes a different amount of work to review, and a case study requires a round of customer interviews. Each label helps an agency work out how much effort the job will take and plan the work. The problem begins when that production logic becomes the basis for deciding what a marketing team needs. Knowing how to price a whitepaper does not establish whether a buyer needs one.
Why technical buyers experience content by moment of encounter, not by format
A technical decision-maker starts with a problem. Does this type of tool solve the problem, and which vendors should go on the shortlist? Those questions lead to a discovery moment in which the buyer forms an initial shortlist, often before visiting a vendor’s website. What counts then is whether the vendor appears in a place the buyer trusts, with enough relevant evidence to earn consideration.
The buyer stress-tests its claims against architecture, integration complexity, and edge cases, drawing on documentation, comparison pages, and peer accounts. Recognition alone is no longer enough to proceed. The content must show whether the product fits the actual implementation and whether the vendor understands the hard parts.
Internal selling follows a confident technical verdict, but it is a separate job. The buyer has to reassemble evidence for a committee whose members may not share that technical background. Discovery, evaluation, and internal selling give teams a better way to plan content than document types do. A blog post, whitepaper, or case study could serve any of these moments. Its usefulness depends on its substance and where the buyer encounters it.
The discovery moment has moved, and the agency taxonomy has no category for where it now happens
A significant and growing share of technical buyers now form initial shortlists through AI assistants. In that encounter, the answer is the entry point. The buyer receives a selection of vendors without necessarily seeing the pages that informed it, much less clicking through a ranked list of links. A content plan built to win those clicks can miss the moment when buyers start choosing vendors for their shortlist.
This changes what success in discovery looks like. A guide may be optimized for search, but that work does not give the brand visibility in a chatbot answer unless the brand appears there. The agency hierarchy of long-form guides, tutorials, and pillar pages assumes a discovery layer where ranked links bring buyers to content. For a meaningful portion of technical buyers, that assumption no longer holds.
AI answer engines also draw on a different mix of signals. Brand mentions across credible sources, entity authority, structured factual claims, and freshness all influence presence in ways that search-ranking logic does not capture. Search-optimized content still has value, and treating it as the primary discovery lever can direct investment toward an encounter the buyer never has.
Could an agency solve this by adding another deliverable? Not without changing the underlying planning logic. An additional format label would still describe a thing to produce, while discovery depends on how a brand is represented across sources. This is a structural mismatch.
What content actually drives brand presence in AI-generated shortlists
Brand presence in AI-generated answers depends on mentions across credible third-party sources. Off-site sources account for a majority of AI citations. Review platforms, community forums, and third-party editorial are thus a large part of where discovery happens. A strategy confined to the owned site is working on the minority of that surface.
The standing of comparison content illustrates the difference. Ranked “best-of” pieces are the format most frequently cited by AI engines among non-corporate source categories. A conventional agency taxonomy may treat them as mid-tier SEO work, below an extensive guide or whitepaper. Yet their role in AI answers can make them a primary strategic asset.
Freshness creates a second break with the deliverable model. Material that has not been updated recently loses citation share relative to fresher pages, so publication cannot mark the end of the work. A completed piece and a useful discovery asset are not always the same thing.
The resulting strategy has two parallel tracks. The owned site needs clear factual claims, schema signals, and a coherent account of the brand and product so AI systems can extract useful information. The brand needs to build and keep up its off-site presence through discussion threads, G2 reviews, third-party editorial placements, and community forums. These activities constitute “ground-site” and “phantom-site” strategy, with the latter building the brand’s presence beyond its own domain.
Neither track fits neatly into a conventional deliverable label. Entity authority and third-party mention share describe conditions a program is trying to build. That distinction changes both the work commissioned and the definition of completion.
How planning from the format taxonomy produces the wrong content decisions at the evaluation stage too
Once a buyer reaches a shortlisted vendor, the content has a different test to pass. It must provide verifiable, specific evidence about implementation. A case study can describe an impressive business outcome yet fail this test because it never explains the technical work. Its status as a recognized deliverable does not fill the gap between a customer’s result and the evaluator’s unanswered questions.
A working tutorial can offer much stronger evidence. When the code compiles, the architecture is accurate, and the edge cases are acknowledged, the piece demonstrates an understanding of the problem. Honest comparisons and clear limits on product fit also show that the vendor understands the problem. But a team counting deliverables may count that tutorial as just another blog post.
AppSignal’s engineer-written articles converted at a materially higher rate than its existing content catalog. That outcome illustrates why authorship and technical substance deserve attention beyond the format label. That outcome shows why counting articles cannot explain their usefulness to a buyer deciding whether to proceed, with the performance advantage established only for the articles measured.
A completion target of six blog posts, two whitepapers, and one case study per quarter has no built-in test for that usefulness. Each piece can be finished and approved without answering a difficult implementation question. The result can be polished content that a technical buyer closes after two paragraphs because it reveals nothing a competitor’s documentation does not also say.
The internal-selling stage and why it requires different content properties than the evaluation stage
Technical confidence does not automatically become committee approval. The buyer now needs evidence for people who did not conduct the evaluation and may distrust AI-assisted research, vendor-produced content, or both. A named practitioner’s review on a trusted platform, a bylined analysis in a respected publication, or an independent comparison can serve this purpose. The source must be recognizable without a lengthy defense from the buyer.
This is primarily a demand for evidence that travels credibly beyond the evaluator. A case study written for that evaluator may focus on architecture and implementation, while one written for procurement may need to show business outcomes, risk mitigation, and a client profile like the buyer’s. Calling both “case studies” hides the distinction that should guide their substance.
Is source trustworthiness the real issue, then? At this moment, that objection supports the buyer-side framework. Trust comes from the source’s identity and standing. The deliverable list collapses a third distinct content job into the same set of labels.
What a buyer-side framework actually changes about content planning decisions
For a team adopting this framework, planning starts with the encounter it needs to serve. Where does a buyer in the category form an initial shortlist? Where buyers form that shortlist guides how much to spend on off-site presence, entity authority, and structured factual content, or on search-ranked tutorials. It is not a contest between fashionable channels.
Evaluation planning then asks what would make a technically skeptical buyer trust the product enough to retain it on the shortlist. That question favors implementation accuracy, honest comparison pages, and specificity about fit over content volume or format variety. Internal-selling planning prioritizes evidence the buyer can forward to people who did not do the research, which can make a placement in a third-party publication or a credible review more useful than another owned-domain asset.
Measurement has to follow the same division of jobs. AI citation share and brand mention frequency address discovery, while engagement depth and conversion rate help assess evaluation content. Third-party source authority and committee-stage conversion address internal selling. These signals are not interchangeable with a production count.
The discovery component is now measurable with available tools. A team can run commercial prompts across ChatGPT, Perplexity, Gemini, and Claude, log citation frequency by platform, and track AI-referral traffic separately from organic search. That provides a concrete measure of AI visibility, with attribution to revenue still unresolved.
Literally.dev’s approach offers one operational example in technical content. It establishes a baseline of AI surface presence before writing begins and runs the measurement again at a defined endpoint, day 85.
The strongest case for keeping the format taxonomy and why it doesn't survive the discovery-layer shift
Teams need work they can scope, produce, review, and approve, and familiar deliverables make those tasks manageable. AI citation share, by contrast, is a low-volume, indirect signal that resists clean attribution to revenue. A planning framework that ignored this uncertainty would replace one blind spot with another.
Similarweb’s 2026 Generative AI Brand Visibility Index found that 35% of US consumers use AI at the product discovery stage. That finding concerns consumers, with the share of technical buyers left unmeasured. It still supports the broader shift toward AI-assisted discovery, without proving that AI controls the whole buying process. Many buying committees still reach final approval through human-led deliberation. A pure AI-visibility strategy would leave evaluation and internal selling underserved.
The format taxonomy remains useful in a subordinate role for procurement and production after the team has decided which buyer moment needs support. Reversing that order forces buyer needs into a list already chosen for ease of delivery. The shift in discovery makes that order especially costly because some of the work now needed takes place beyond the owned site.
Most brands lack clear visibility into whether their content is gaining or losing AI citation share, leaving room for earlier movers to establish presence before the channel becomes as contested as organic search. The case is for reorienting existing agency planning while the discovery layer is still taking shape, before other brands have become its familiar answers.