Why a spreadsheet content calendar is a symptom, not a system — and what computational marketing replaces it with
Computational marketing replaces scheduling with a pipeline that executes, measures, and adapts.
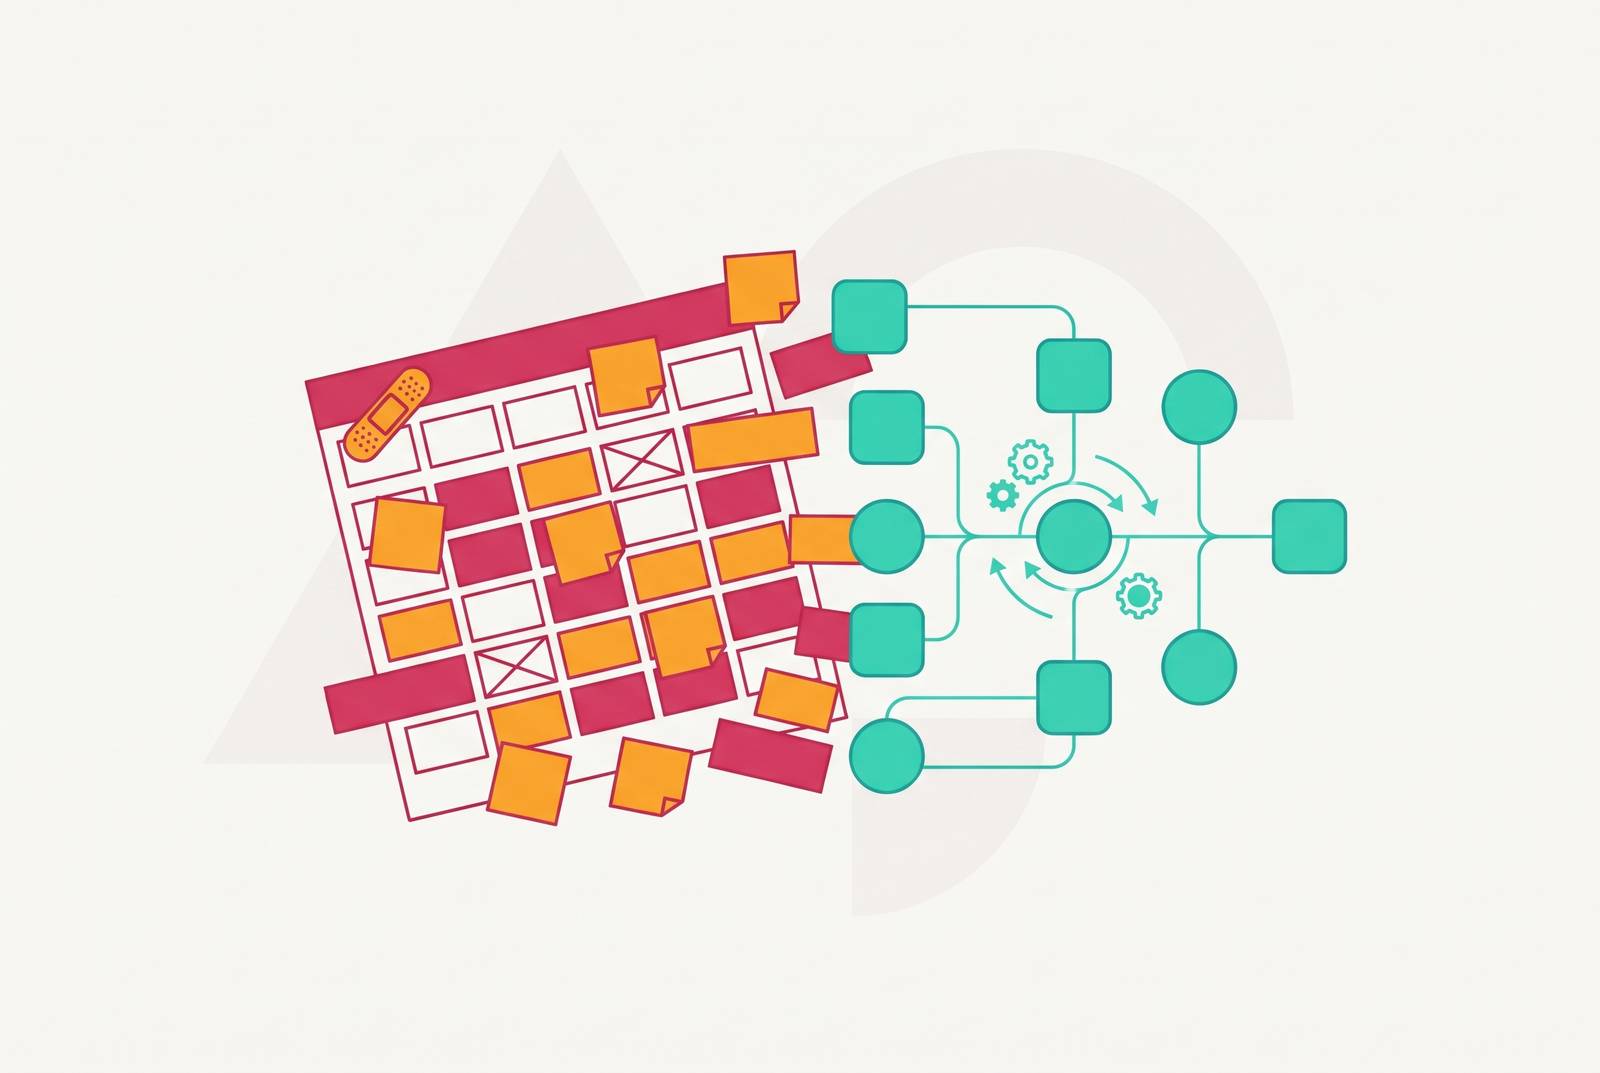
A spreadsheet content calendar is useful, but dependence on it is often a symptom of a manual production process mistaken for a system. Whether it lives in Google Sheets, Excel, or another spreadsheet tool, it records intentions. Computational marketing replaces that scheduling model with a pipeline that executes, observes, and adjusts, with editorial judgment built into its checkpoints.
What a content calendar actually does — and doesn't do
A well-built spreadsheet gives a content team something genuinely useful. It brings publish dates, owners, channels, status, and asset links into one place, often in a single row for each piece. That shared view helps the team spot bottlenecks before they become emergencies and work together without much extra software to manage. Its appeal is easy to understand. Spreadsheets became the default planning layer because they are free, familiar, and flexible.
The limit appears when recording work is confused with doing it. A spreadsheet cannot independently plan, draft, enforce a review, publish, measure results, or adapt the next piece. Without manual intervention or outside scripts, it cannot send overdue reminders, manage recurring evergreen posts, bulk-reschedule across channels, or connect natively to publishing and distribution platforms. Those jobs remain outside the sheet. The calendar coordinates a process, while people and other systems still have to perform it.
Why the calendar became a proxy for strategy
Columns, status dropdowns, and publish dates make a plan easy to see. That visibility can also make it feel complete, even when the handoffs beneath it remain fragile. A draft is done, but nobody changes its status. An approved social post lacks its asset link, or a meeting changes a publish date while the calendar still says “scheduled.” These are breaks between the work and the record of the work.
Can the team answer “what's publishing this week?” in under a minute without opening three different tools? If not, the calendar is not doing the job attributed to it. At dozens of pieces per month across multiple channels, that distance becomes harder to manage because clutter accumulates, status labels drift, and filtering becomes unreliable. The work of keeping everyone in step grows faster than the amount of content, so a bigger plan takes more effort to keep accurate.
Database views can relieve some of that pressure. Kanban, Gantt, and linked records give teams different ways to look at work and link items that belong together. They extend the useful life of the planning layer without necessarily changing the process beneath it. Each item is still a plan that someone has to carry out. The format therefore creates a structural problem by treating content chiefly as a scheduling problem, regardless of the tool.
The structural shift that made the scheduling model obsolete
The scheduling model suited a world in which publication could serve as the terminal success state of production. A team published consistently, then expected that cadence to compound into traffic over time. AI answer engines interrupt that connection. ChatGPT, Perplexity, Google AI Overviews, Claude, and Gemini can answer a question without sending the reader to the pages that informed the response. A piece can arrive on schedule and still produce no brand impression if the answer omits its source.
That changes the question a content operation must answer. “Did it publish?” says nothing about whether an engine retrieved the piece, used it, or attributed the answer to the brand. In a zero-click session, the reader receives the answer without visiting any page, so even useful source material may go uncredited. Publication remains necessary, but it is not enough. Content also needs to be structured so that an engine can extract and cite it.
This shift has a particular effect on B2B SaaS and developer-facing brands because buyers do more of their research through AI answers before they visit vendor sites. The first impression may now happen inside an answer. A calendar has no way to show that impression through a publication status alone. Its measurement gap is therefore as fundamental as its production gap. The replacement must close both gaps as well as automate the work of taking a draft through to publication.
What computational marketing means in practice
Computational marketing treats content as an engineering problem that can be instrumented, measured, and changed on evidence. In this model, the calendar becomes an output of the system. The pipeline begins with planning, where AI identifies keyword gaps, builds topic clusters, and generates briefs. Those briefs then become outlines and first drafts in the drafting stage. Review checks the work against a style guide and flags factual claims that need attention.
The next layers prepare and move the content. Optimization handles titles, metadata, and headings, while publishing posts the material to a CMS with schema. Distribution creates social variants and email segments so a person no longer has to handle every channel handoff. Measurement then reports on how the content performed and recommends what to refresh. Each layer has a distinct job, but the architecture connects them so that progress does not depend on someone updating a status cell.
Where does human judgment enter that process? It belongs at set checkpoints where people decide on brand voice, check claims, and make strategic pivots, while routine actions proceed on their own. The goal is for AI to run the workflow while humans review exceptions, going beyond helping people with one task at a time. Agents take a goal and coordinate across channels and platforms to reach it. To make that coordination possible, every capability in a well-built pipeline should be reachable through an API. That access allows the pipeline to connect to a broader stack and be measured as a whole.
The content structures that actually get cited by AI answer engines
A connected pipeline still needs to produce the right kind of material. An AI engine composing an answer needs a passage it can extract with confidence. The practical editorial change is to make each section answer a clear question, stated or implied by its heading. The direct answer belongs in the first two or three sentences, followed by supporting detail. Six paragraphs of preamble make that extraction much harder.
This favors depth over a full publishing calendar. Generative Engine Optimization, or GEO, rewards comprehensive treatment because an engine needs enough authority and specificity to form a confident answer. An in-depth guide can meet that need better than many thin posts that cover the same ground. The original GEO research found that trustworthy quotations and clear statistics that named their sources helped a piece rank higher in AI-generated responses, while fluency optimization brought little to no gain in citations. Smooth prose alone is not sufficient evidence.
That does not make traditional search optimization obsolete. SEO establishes baseline visibility in search, Answer Engine Optimization, or AEO, supports access through answer-driven features, and GEO positions material as a trusted reference for generative outputs. These are complementary layers. Google’s guidance favors original content that stands apart from generic material and draws on real first-hand expertise and sound SEO fundamentals. For an editorial team, the lesson is to improve the substance and answer structure of the content itself, rather than create a separate stream of supposedly AI-friendly posts.
Where content lives and how it is structured for retrieval
The content’s home also shapes whether an engine can find, parse, and retrieve it. Choosing a primary domain, a purpose-built resource site, or structured landing pages shapes how the content is housed as well as where it goes in a channel column. Answer engines read across a site. A content plan that stops at an asset link leaves out the choice of where the content should live.
The same principle applies within each page. Passages that begin with a direct, self-contained answer to the heading’s implied question are extracted at higher rates than passages that gradually build toward their point. Self-contained is the important distinction here. A passage needs to make sense when an engine pulls it into an answer, rather than depend entirely on the paragraphs around it. That requirement connects editorial structure to retrieval architecture without making either a substitute for the other.
Ranking on Google and being cited by an answer engine remain different jobs, so success at one does not automatically establish success at the other. The route back to the source can differ too. Perplexity crawls the web in real time and includes clickable inline citations, allowing citations to produce trackable referral traffic. In a zero-click session elsewhere, seeing the brand may be the only impression a reader gets. These differences make the destination and format of published content inseparable from how its results are observed.
Measuring AI visibility the way a pipeline requires
A pipeline becomes self-correcting only when it observes what happens after publication. Without that layer, automation simply publishes into a black box faster than a manual team can. The measurement framework must distinguish citations, which link to the content, from mentions, which name the brand without a link. Both provide evidence of presence in an AI answer. A calendar entry that shows an article went live records neither of these.
That distinction needs consistent tracking across ChatGPT, Perplexity, Google AI Overviews, Claude, Gemini, and Copilot. Otherwise, a team cannot tell which engines name the brand and which cite its material. Referral traffic offers one useful signal, but it cannot account for every impression in an environment where readers may never click. Publishing regularly and hoping to appear in answers relies on the same faith that made the calendar seem enough.
Measurement earns its place in the architecture through what it changes next. Its outputs feed refresh recommendations, reveal gaps, and inform topic priorities, connecting observed retrieval to future production. The pipeline can therefore adjust on its own cadence, independently of a quarterly review. This is a different role from reporting how much content shipped.
What the transition from calendar to pipeline actually requires
The strongest objection to this model is about control. If AI executes the workflow, how does an editor stop a weak claim, an off-brand passage, or a poor strategic choice? Better pipeline design makes every AI-generated suggestion reviewable and reversible before it ships. Defined checkpoints preserve the ability to say no while removing the need for a person to supervise every routine transition.
Multi-stage generation paired with human review can improve quality and cycle time compared with slow agency production or unreviewed AI output. Aumcore reported how a B2B software client went from roughly eight articles per month to forty without adding much to its headcount or budget. The time spent on research fell from several hours to 30 minutes per article. Editors maintained brand consistency, strategic positioning, SEO quality, and conversion alignment throughout, showing why increased output need not require removing editorial oversight.
For a team beginning the transition, the starting point is instrumenting the content already being published, tracking which pieces earn AI citations, and identifying the structural gaps in those that do not. The pipeline can then develop around content types that already earn retrieval. Brand presence should come from real content the company publishes and owns that engines can retrieve, rather than from gaming a single prompt or optimizing one page on its own. That requires sustained publishing on a site AI systems can read and index.
The calendar had a useful role in coordinating manual work. What replaces it is not a loss of order, but a system whose execution, observation, and adjustment are connected. Teams that instrument those connections now can build on each round of evidence while competitors are still debating whether to begin.