What an "online marketing platform" comparison for B2B startups doesn't price: seats, onboarding fees and the contact record, versus metered primitives an agent can call
Seats, contacts and onboarding inflate year-one costs that agent-friendly metering avoids.
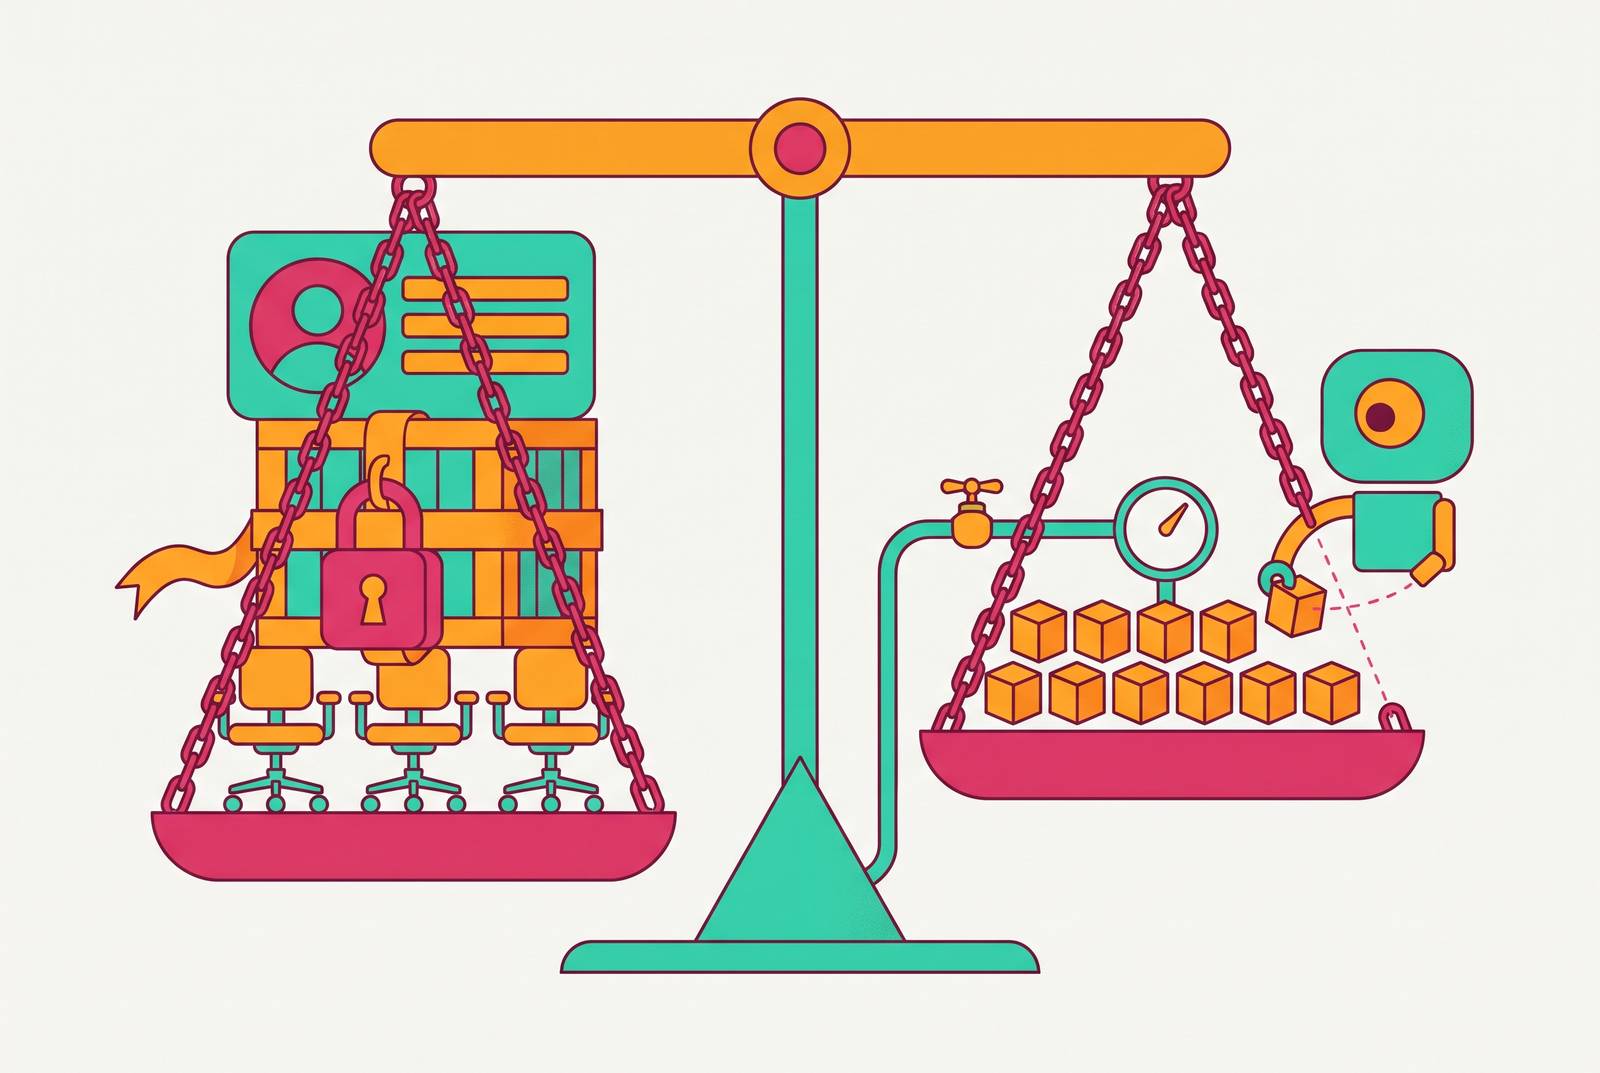
An online marketing platform comparison for a B2B startup often compares the wrong number and the wrong unit of work. The displayed tier price leaves out the combined effect of seats, contact records, and onboarding. For a startup building agent-run workflows, the deeper question is what the bill measures. Metered, API-callable primitives price work done rather than people with access or records kept in a database.
Why the tier price on a comparison grid is not the year-one price
The comparison grid shows a monthly tier price, while the year-one invoice reflects the team, the growing contact list, and the cost of getting started. Those are different purchases. A founder scanning the grid can reasonably read its number as the cost of operating the platform, even though it describes only the starting package.
A tier name and a monthly figure are easy to scan, which makes them useful for arranging products side by side. A startup adding people and prospects can trigger several increases during the same period, precisely when its use of the platform is expanding. Growth changes the bill on more than one axis. To understand the resulting cost, each axis needs its own explanation, because seats, records, and onboarding charge for different things.
How per-seat, per-contact, and onboarding fees each work and why they stack
Per-seat fees charge for named users on top of the platform fee. Access itself is the unit being sold. A five-person team therefore needs to account for the base subscription and every paid seat beyond the package’s included allotment. Adding a sixth person, whether a contractor or a founder who wants dashboard access, adds another increment. How often that person opens the platform does not change the logic of the charge.
The billable unit is a marketing contact in the database. As outbound prospecting grows the list, crossing a contact-tier threshold raises the monthly fee, including partway through a contract. A dormant record can still incur a charge. Contacts imported for a one-time campaign count toward the tier even if the team never emails them again.
Professional-tier products often require an onboarding package before they give full access, and the fee is billed once at the start of the contract. It arrives before the first campaign runs. A comparison page may disclose this requirement in a footnote without including it in the headline monthly figure. Onboarding, seat charges, and contact charges all add to the year-one cost, so the displayed subscription alone cannot show the full bill.
What the real year-one number looks like for a five-person startup on a professional tier
Consider a five-person B2B startup buying a professional tier that has too few seats in its base allotment and needs extra paid seats for two or more team members. The grid supplies the starting subscription price. The seat overage then becomes a recurring expense from the beginning, while mandatory onboarding creates an immediate cash outlay before any usage. Even if the contact list stays within the starting allowance, the startup is already paying more than the monthly figure suggests. Nothing unusual has happened to its workload.
Now suppose outbound prospecting takes the list beyond the base contact allowance partway through the year. The contact fee goes up for the rest of the year, and the startup keeps paying the subscription and seat charges. The timing changes the annual total. A year-one calculation therefore has to reflect the base tier over the year, the additional seats, the period spent in the higher contact tier, and the upfront onboarding payment. It cannot simply multiply the comparison page’s number by the months in a year.
How large is the gap in this example? Without a specific contract, an exact total would be false precision, but the direction is clear. The combined cost is materially higher and can be large enough to change a vendor decision. Over time, onboarding is still a one-time cost, while a growing team and list keep pushing up the charges that the startup pays each month.
Why this pricing structure is architecturally mismatched to a startup running AI agents
An agent-run workflow exposes a different problem with these meters. The agent’s working interface is an API endpoint. Its reasoning loop can make parallel tool calls to fetch records, update statuses, and cross-reference endpoints within seconds. That activity does not resemble a person moving through sequential clicks in a browser. The number of people with access and the number of stored contacts say little about the work being done.
The distinction is between inventory and activity. A contact-record meter counts what the system holds, while an API-call meter counts interactions with it. Seat pricing, meanwhile, treats human access as the starting point for allocating cost. For agent workflows, recognizable units of work or completed outcomes provide a closer connection between the operation and its price. This is an engineering distinction even before it becomes a budget question.
It also changes which systems are easier to integrate. Clean, well-documented, composable APIs give agents a direct way to act, while UI-dependent workflows make that connection harder. But what if the startup is not running agents yet? The pricing and platform choice can become established before the workflow arrives, and switching during growth is expensive and disruptive. A year-one decision can therefore constrain what the team can build in years two and three.
What metered, API-callable primitives actually price — and what they don't
A metered primitive is a callable unit of functionality priced by recognizable work, including API calls, contacts processed, or resolutions completed. In the model described here, there are no seats, contact-record tiers, or mandatory onboarding fees. A larger list does not by itself trigger a pricing step, although doing more work on that list can increase usage.
For a startup running one campaign a month and an agent workflow, this makes actual activity the basis for cost. Some workloads can still cost as much or more. Instead, it changes what explains the bill. More operations or completed outcomes mean more metered work, rather than an increase caused by unused seats or inactive records. That distinction makes the unit of spend easier to connect to the purpose of the workflow.
Tokens per call are difficult for an application buyer to predict, because a founder may know the desired result without knowing how many tokens producing it will consume. Outcomes-based metering makes that relationship more legible. A resolved contact, a published asset, or a monitored mention names something the buyer can recognize. Transitional hybrid models may combine a base subscription covering fair-use volume with metered overages, while still removing the seat and onboarding axes.
For a founder evaluating an “AI-powered” tool, the practical test is therefore both commercial and technical. Does the tool have access to actual data, real integrations, and the ability to act through an API? Pricing alone cannot answer that question. A tool that only generates copy through a UI does not become interoperable with an agent workflow because its billing model changes.
What GEO and AEO actually require from a content and measurement stack — and why a checkbox on a comparison grid doesn't cover it
Generative Engine Optimization, or GEO, concerns how content is structured and formatted so AI platforms can extract and cite it at the passage level. The target is an authoritative citation. ChatGPT, Perplexity, Claude, Grok, and Gemini are among the platforms involved. Answer Engine Optimization, or AEO, is a distinct term. Either term on its own in a comparison grid tells little about the work a product can do.
That work starts beneath the text itself. Ground-site architecture, named authorship, schema implementation, and crawler access are structural requirements. A missing llms.txt file and blocked AI crawlers raise questions about readiness that a content-quality score cannot answer. Access comes before extraction and citation. A platform claiming GEO or AEO capability therefore needs to be understood in relation to both the site where the content lives and the interface where someone generates it.
The same distinction applies after publication. Measurement needs to track mention rate, citation rate, sentiment, and competitor positioning across ChatGPT, Perplexity, Gemini, Google AI Overviews, and Claude. One engine’s output is not a substitute. A mention shows something different from a citation, while sentiment and competitor positioning address how the brand appears in the answer. A single checkbox cannot show whether a stack tracks each of these measures or just makes content for AI search.
No single platform supplies this whole arrangement out of the box. Site structure, authorship, content production, and cross-engine measurement have to work together, even when individual tools support parts of the process. The connection is the real capability. Without it, a team can purchase a labeled feature yet still lack a way to establish whether its content is accessible, useful as a source, and cited in relevant answers.
How a metered content pipeline with human review handles what a platform comparison never models
A governed content pipeline divides that work into stages, with AI handling low-leverage tasks and humans retaining judgment over the angle, accuracy, and voice. Outline review comes before drafting because it is the point where a reviewer can make the most difference. An editor can reject an unhelpful angle before the system generates thousands of words.
Before publication, fact and citation review addresses a different risk. Models can make up statistics, quotations, and source URLs, so a reviewer needs to open every cited source even when a reference looks like sound evidence. Voice and positioning require their own judgment. Prompt libraries and voice guardrails reduce drift, but technical completeness does not establish that an article is worth publishing under a brand’s name. These gates belong inside the pipeline as required steps.
Structured prompts relevant to the business category provide a way to track whether AI engines name and cite the brand, with the distinct measures described above. Publication volume cannot answer that question. For this stack to be composable, each stage should be reachable through an API so work can run on its own between human review gates. Research, briefing, drafting, and measurement primitives can connect to the startup’s existing stack.
The publishing cadence also needs a purpose beyond throughput. Deep topic clusters, named authors, and real data points support citation in a way that thin coverage across many topics does not. The content engine should build topical depth. Outcome-based pricing can tie what the team pays to a published asset or monitored mention, while editors check quality and measurement shows how visible the content is. Paying for an asset is not the same as proving it worked.
Those in procurement may still prefer a per-seat or flat-annual-fee proposal because it is easier to get approved within the company. That preference makes sense, but even with a familiar format, spending can be hard to predict when seats and contact tiers can change. Metered usage can change too. Its advantage is that the unit can be legible and auditable, so the team can relate spend to work performed. For an engineering-minded marketing team, the useful comparison is not just between starting prices, but between what each price buys, what triggers the next charge, and what the workflow can actually do.