Why your brand shows up in Google AI Overviews but the citations go to someone else: an engineering diagnosis for technical marketing teams
A diagnostic for separating AI Overview citations from recommendations.
Google AI Overviews can use your content without pointing buyers to your brand. For technical marketing teams, the task is to separate citations, mentions, and recommendations, then diagnose why one fails to lead to another. The gap becomes actionable when teams measure each outcome and repair the on-site legibility and off-site corroboration that shape the verdict.
The gap between being cited and being recommended in Google AI Overviews
For “best LMS for selling courses,” Google cited an Oasis LMS listicle but recommended Kajabi, Thinkific, LearnWorlds, and Teachable. All four appeared inside the Oasis article. Oasis supplied the research material but was left out of the verdict. Its page had earned a place among the sources without earning its product a place among the suggested choices.
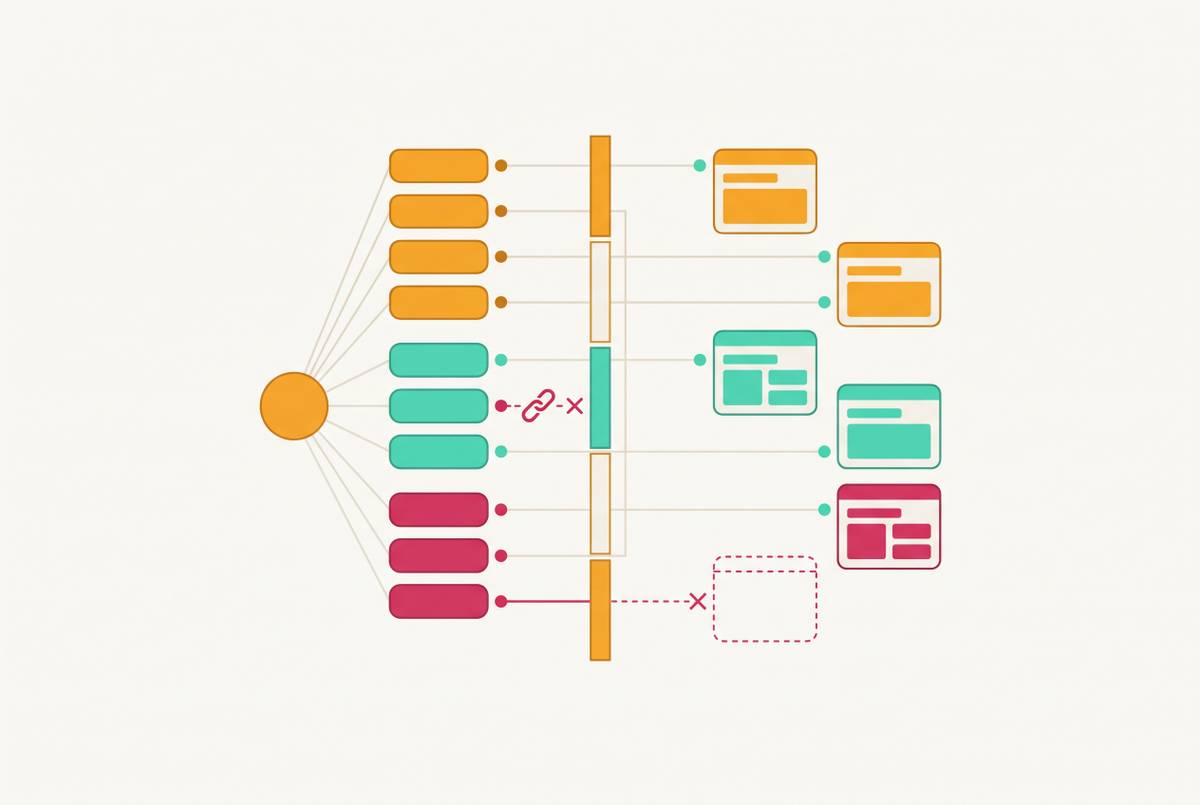
That example separates three outcomes that often get folded into “AI visibility.” A citation means the page appears as a source. A mention means the brand name appears in the generated text, while a recommendation presents the brand as a choice for the buyer’s need. Only the last outcome directly steers the buying decision toward the brand.
Why can a useful source lose that decision? Retrieval and recommendation are separate judgments. Relevant, well-structured content can supply material for an answer, while broader web support favors another product. A brand that ranks itself first speaks for itself, while support from reviews, forums, and independent publications looks more like agreement across sources.
How widespread the citation-without-recommendation pattern actually is across B2B buying queries
Lily Ray’s June 2026 analysis of 100 B2B “best [category] software” queries found that self-promotional listicles earned citations without recommendations for their publishing brands in the majority of those citation instances. Her September 2026 update found that the pattern had worsened. This was not just an isolated LMS result. It occurred across software categories in queries meant to help buyers build a shortlist.
Foundation’s analysis of 15,716 branded B2B buying searches found a similar risk even when buyers named a brand. In more than one in five AI Overviews, Google cited a direct competitor’s own site. In roughly one in nine, the competitor was cited and the named brand was absent entirely. The modifier changed the risk. Alternatives queries had the highest competitive citation rate, pricing queries were meaningfully lower, and reviews queries were lower still.
Even those lower-risk queries can matter a great deal to sales. The same analysis found that an AI Overview for “Kustomer annual contract pricing” opened by citing Gorgias, a direct competitor. Across the research, category leaders with third-party mentions from more sources and stronger link profiles were more likely to get recommendations as well as citations. If the pattern occurs in both category searches and branded buying queries, why do ordinary visibility reports miss it?
Why standard measurement tools cannot see the citation-versus-recommendation gap
Standard rank trackers show where a brand ranks in the organic index but miss the role it plays inside an AI Overview. A brand can hold the top organic position and still be absent from the generated answer above it. A lower-ranked competitor can become the cited source instead. Rank and recommendation are different signals. Improvement in one cannot establish improvement in the other.
Kevin Indig’s research found that the majority of AI engine citations did not name the source brand in the generated text. These “ghost citations” expose a second blind spot. Mention-based monitoring catches names but misses source-link-only citations, so a competitor can help shape an answer without triggering a brand alert. Citation monitoring has the reverse limitation when it records the link without reading the answer. It cannot tell whether the source brand was mentioned, recommended, or neither.
Engine differences add another measurement problem. Omnia’s data shows that visibility for the same domain can vary by a factor of twenty or more across engines. A competitor prominent in Google AI Overviews may be nearly invisible in ChatGPT for the same queries. The measurement design therefore needs three separate fields per query and engine, recording whether a source URL appears, whether the brand is named, and whether it is suggested as a choice. Without those distinctions, citation growth can conceal a loss of recommendation share.
Building the query set that makes the gap visible
To build that query set, start with queries that contain just the brand name. These provide a baseline for relatively uncontested citation behavior, where Google AI Overviews lean heavily on the brand’s own site and Wikipedia. The baseline serves a limited purpose. It shows how the brand is represented before a commercial modifier introduces a more contested buying question. It should not stand in for the queries buyers use to compare options.
Next, pair the brand name with “alternatives,” “pricing,” “reviews,” and “competitors.” Keep each modifier in a separate group rather than combining them into a single branded-query average. An average can smooth away the higher exposure on alternatives queries and make pricing or reviews performance look representative of the whole set. Include specific buying questions such as “Kustomer annual contract pricing” where they fit the brand being assessed.
Complete the set with unbranded category queries such as “best [category] software.” These reveal whether the brand’s content supplies a shortlist that excludes its own product. Run the set weekly, with results kept separate for Google AI Overviews and ChatGPT. A single manual check offers no trend. A recurring run makes it possible to see which competitors occupy citation slots over time and which modifier groups deserve closer diagnosis.
Diagnosing which structural gaps cause Google to research with your content but recommend someone else
Once the results reveal a gap, inspect the cited page for self-interest. Does it rank its own brand first, and does that ranking have support beyond the publishing domain? A self-promotional list can still be useful research material. Google can retrieve the options it names while favoring a different order based on broader web support.
Next, examine what an extractor can lift intact. AI models pull self-contained chunks, so thin sections, long unbroken prose, and buried answers can make useful passages harder to extract. Check whether the product description clearly identifies the brand, its category, and its distinguishing features. Inspect the schema and entity structure too. If those signals are missing or vague, the model has more to infer and more opportunity to omit or misrepresent the brand.
Then compare the brand’s independent support with that of the recommended competitors. Google’s Search Central documentation says AI Overviews and AI Mode may use “query fan-out,” issuing related searches across subtopics and sources. That broadens the evidence beyond the cited page. Review platforms, publications, forums, and YouTube can supply corroboration that a brand’s own site cannot.
Independence must be genuine. The FTC’s Consumer Review Rule prohibits businesses from misrepresenting controlled websites or entities as providers of independent reviews or opinions.
Fixing the on-site legibility gaps that cause recommendation failure
Turn each unclear signal on the site into a task for an editor or developer. Define the brand plainly on the relevant page, stating what it is, which category it belongs to, and what it does differently. Replace vague claims about the product with a structured description of it. The extractor should not have to guess.
Restructure buried answers into self-contained sections that can stand alone. Each section should identify its subject and provide the answer near the start. Review schema implementation so the markup identifies the content type and the claims being made. Treat that as a legibility task. A page that is easier to read still needs support from independent sources.
The technical work can also include an llms.txt configuration that presents an AI-readable index of the site’s authoritative pages. Its purpose is to clarify which pages express the brand’s current positions rather than leaving peripheral or outdated material to stand in for them. But navigation cannot replace distinctive evidence. Original survey data, proprietary case studies, and named expert statements from real conversations give the page something beyond an interchangeable list of products. AI-generated text that repeats what is already available adds nothing that sets the page apart.
These changes address different parts of the same failure.
Building the off-site corroboration layer that turns citations into recommendations
Even a clearly structured page can lose the verdict when independent support is thin. The next task is therefore to identify where recommended competitors receive that support. Start with the sources appearing in the query results. A particular Reddit thread or niche industry forum may explain more of a competitor’s strength than its own website. Finding that source gives the off-site work a specific target.
Foundation’s data shows that review platforms such as G2 and Capterra, Reddit, YouTube, and high-authority third-party publications show up often in AI Overviews for B2B buying queries. These are not merely places to raise awareness. They are places where the model can encounter evidence about whether a product fits a buyer’s need. Complete product profiles and responses to reviews affect the material available for extraction when related searches reach those pages.
For Reddit and YouTube, the appropriate response is active, authentic participation. Presence on those platforms can build corroboration where the model looks, but controlled promotion must not be presented as independent opinion. The FTC distinction still applies here.
Tie that work back to the query set. Track which publications, platforms, and forums appear as sources for each modifier group, then watch whether the brand’s recommendation outcomes change over time. This keeps off-site activity connected to an observed gap. It also gives teams a way to distinguish a useful presence on a specific source from distribution that has no visible relationship to the buying queries under review.
Closing the instrumentation loop: logging outcomes over time and acting on the signal
Record the cited URL, whether the brand name appears in the generated text, and whether the answer recommends it. Record which competitors are cited, mentioned, or recommended and which engine gave the result. Keep the weekly runs distinguishable. That history lets a team compare the state before a change with the outcomes that follow it.
When a page gets a citation without a mention, check entity clarity and schema because the answer uses the page without naming the brand. Mention without recommendation calls for an examination of independent corroboration. Neither signal should replace the page and source audit.
When a competitor is recommended on a branded query, trace the sources supporting that outcome for the specific modifier. Is its position supported broadly, or does a particular forum, publication, or review platform explain the advantage? That distinction helps direct the remediation toward the evidence buyers and models encounter. After the change, rerun the same query group and check citations, mentions, and recommendations.
Maintain this as a standing watcher cadence, checking more frequently than quarterly. Citation behavior shifts week over week, so an occasional snapshot can be stale before it informs a decision. The citation-versus-recommendation gap is an observable, measurable, fixable system failure in AI. Teams that instrument it can diagnose and act on it. Teams that count citations as the win can keep supplying the research while a competitor receives the recommendation.