An AI SEO analyzer score is a page inspection, not a measurement: what to check on the page, and what only answers and referred visits can tell a founder
A page score shows readiness, but only answers and visits show results.
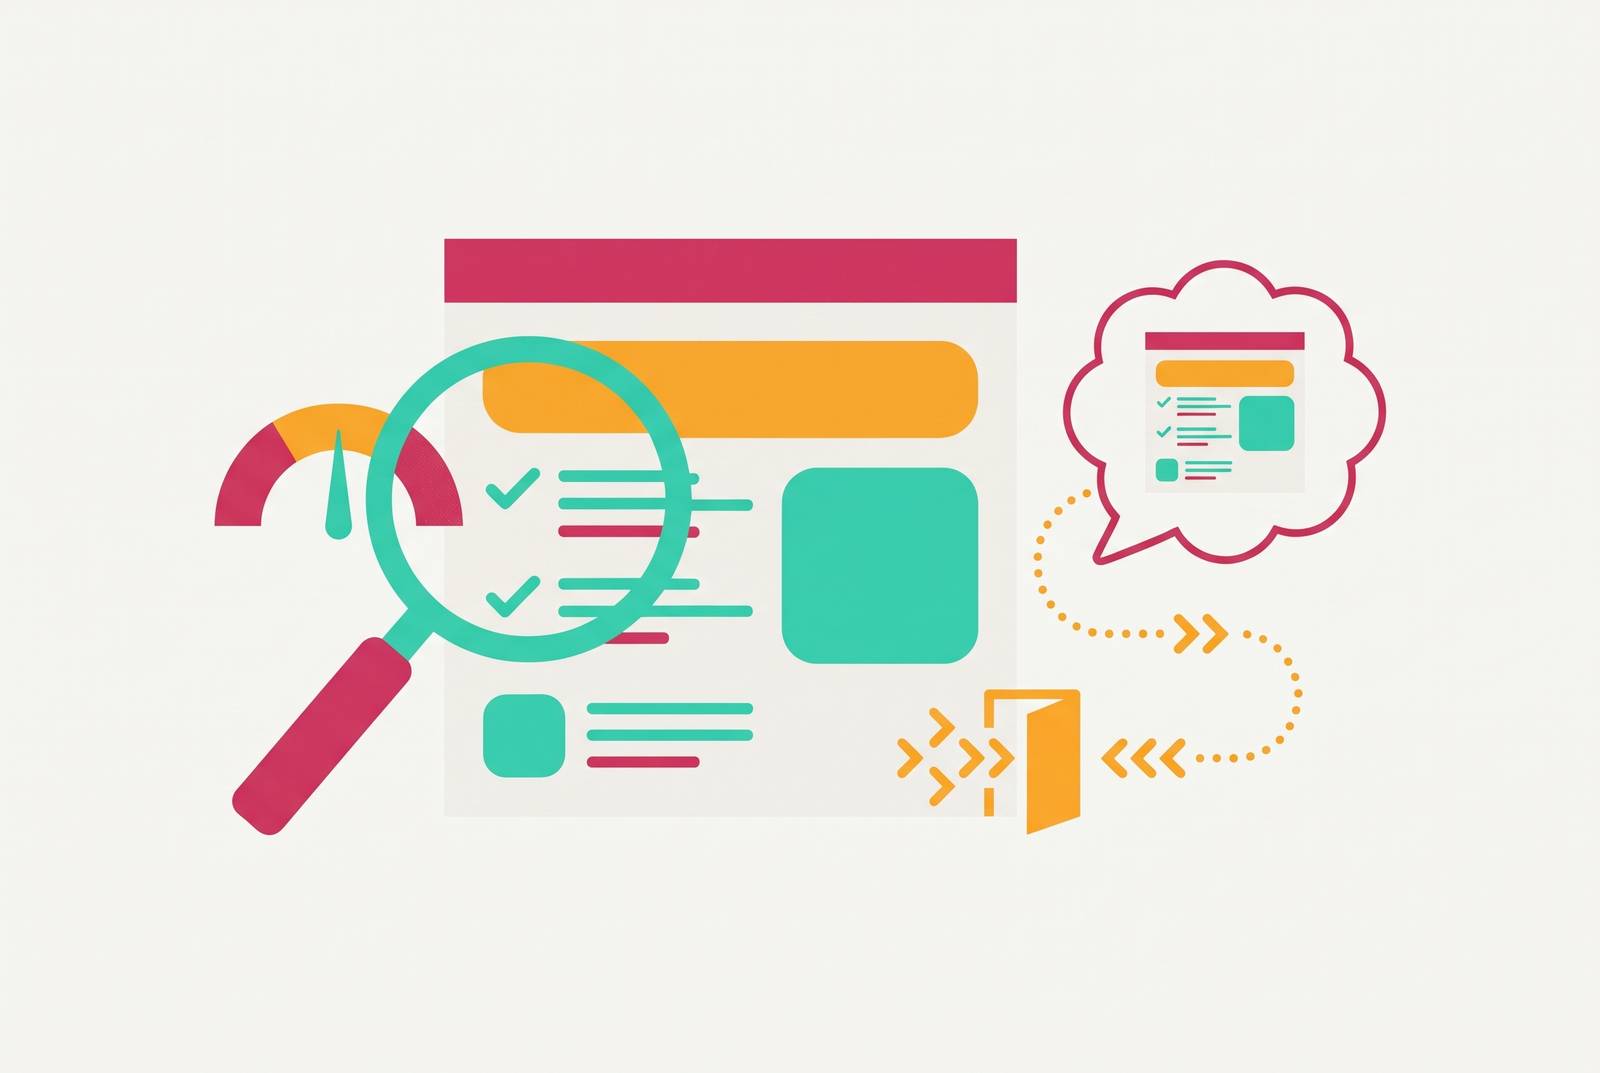
An AI SEO analyzer score is a page inspection. It can show whether a page is structurally ready to serve as a source, but not whether answer engines name it or send anyone to it. For a founder, the useful picture requires three separate records, which are page checks, live citation monitoring, and referred visits from AI surfaces.
Why an AI SEO analyzer score and an AI visibility measurement are answering different questions
A founder runs a checker, gets a strong score, and takes it as evidence that the brand’s AI visibility is healthy. The report looks reassuring, and the inference feels natural. Both inspection tools and visibility trackers use the AEO and GEO labels, and both give scores that look like verdicts. Yet the checker’s examination is limited to the page. That is the break in the logic.
SEO asks how a page performs in impressions, clicks, and positions. AEO asks whether content appears as an answer in a tested interface, while GEO asks how often a brand is mentioned, recommended, or cited across a defined prompt set. Astiva AI’s GEO/SEO/AEO guide describes these as fields that overlap but aim for different results. Their shared subject does not make their measurements interchangeable.
A page inspection can help with work in all these fields by finding problems with how the page is built. It cannot establish observed performance by itself. A report about the page’s suitability is evidence about its condition, whereas a report about its appearances requires observing answers. The checker remains useful once that boundary is clear.
What a page inspection actually checks, and what each check is for
Crawlability and indexability checks establish whether a page is accessible and whether barriers such as robots.txt restrictions or paywalls obstruct access. Google states that supporting links in AI Overviews and AI Mode must be indexed and eligible for normal search snippets. Google also states that there are no additional technical requirements. Crawl access, internal links, and visible text help establish the foundation on which retrieval depends.
Structured data can signal entity type, authorship, and factual claims in machine-readable form, with the markup matching the visible text. An inspector may also examine llms.txt and similar declarations about AI-agent use. Those declarations should not be confused with proof of selection. Citable-format checks instead ask whether answers are direct, claims are extractable, and authorship is visible.
Checks for experience, expertise, authoritativeness, and trustworthiness examine signals such as a named author, first-person experience, and verifiable facts. These help show whether the page has material that an engine can use as a source. Even when the result is a graduated score, its practical role is closer to a readiness assessment. It does not measure how frequently or prominently an engine uses the page.
The gates between a passing page-inspection score and an actual citation
A useful conceptual model places several gates between publication and attribution. The first is whether the page is crawlable and indexed, which the inspection can assess. The second is whether an engine retrieves it for a particular query. Passing the first does not establish the second. Retrieval depends on the prompt, the engine’s index, and its retrieval-augmented generation implementation, which varies by platform and mode.
The third gate is whether the page ranks above other pages that compete with it during retrieval. That competition is not visible to a page inspector. The fourth is whether the engine trusts the material enough to name it as a source. A page may be retrieved and used without receiving attribution, or its content may be summarized without a source link.
What happens if the page offers few extractable, contradiction-free statements? That weakness persists after indexing, and the answer may omit that aspect when the source is messy or contested. The gates are therefore useful as a model. A perfect inspection result can coexist with absence from answers.
How AI engines cite differently from one another — and why a single score cannot capture that
ChatGPT, Gemini, and Perplexity differ in citation volume and source preference, so they are not interchangeable surfaces. Gemini can cite far more pages per answer and draw heavily from third-party sites, while ChatGPT cites fewer pages and gives a larger share of its citations to providers’ own websites. Gemini also gives answers with no citations in many cases. Citation volume and the likelihood of citing at all are different dimensions.
These differences change what a strong page can achieve. Content suited to one engine’s source preferences may be disadvantaged on another, without a structural defect for the inspector to flag. A general readiness score cannot show that mismatch. The relevant evidence is whether the brand appears in the particular engines and answers being tested.
The engines also differ in the traffic they send. ChatGPT is the dominant driver of AI referral traffic to websites, so absence there can reduce referred visits disproportionately even when a brand appears elsewhere. Other engines remain relevant, and citation presence and traffic contribution must be assessed separately when evaluating whether a site is “AI-ready.
What only live citation monitoring can tell you — and what it still cannot
Live citation monitoring runs a defined prompt set through engines such as ChatGPT, Claude, Gemini, and Perplexity on a schedule, recording mentions, cited URLs, position, and competitor share. The tested prompt set supplies the denominator. Without it, a claim that a brand appears “often” has no clear scope.
Each metric then answers a narrower question. Mention rate tracks how often the brand appears, while share of voice compares how often it is mentioned with how often named competitors are mentioned. Citation rate records links to pages and domains. Sentiment and context distinguish a recommendation from a neutral mention or one qualified by caveats, while position distinguishes a leading recommendation from a secondary appearance.
Still, an appearance is not a commercial outcome. Monitoring can record a citation, but it cannot establish whether someone clicked it, whether it caused a visit, or whether that visit led to an action. The engine’s own rules for choosing sources also remain hidden. It is a necessary observation of brand presence, bounded by the prompts and conditions tested. The next question concerns what people do after encountering an answer.
What only referred visits from AI surfaces can tell you — and why GA4 alone does not close the loop
Sessions arriving from chatgpt.com, perplexity.ai, gemini.google.com, claude.ai, and similar origins show that someone reached the site from an AI surface. GA4 custom channel groups can separate these sessions from organic search and report engagement and conversion by source. This gives the traffic record its distinct role. It observes behavior beyond the answer itself.
That record is incomplete for two reasons. A user can read a recommendation without clicking, and some AI traffic arrives without a referrer that identifies its origin. Google states that AI Overviews and AI Mode traffic is included in Search Console under the “Web” search type. That reporting does not supply a complete, separate record of all AI influence. GA4 alone therefore cannot reconstruct everything citation monitoring observes.
A brand can pass inspection and have a high citation rate while getting few referred visits. The value may lie in brand presence and shortlist influence even with few referred visits. The records distinguish those possibilities without proving every unseen effect. Inspection establishes structural eligibility, monitoring observes naming and attribution, and referral data records audience contact. None can answer the other two questions.
The content and entity signals that move citation monitoring in the right direction
For a founder moving from diagnosis to action, the work extends beyond the inspected page. It includes the owned entity record that makes the brand identifiable and the distributed mentions that corroborate it. A structurally sound page can still belong to a brand whose wider record is empty or inconsistent. Technical readiness does not fill that gap. The task is to make the brand both identifiable and supported by evidence beyond its own claims.
On the owned-content side, crawlable, citable original data provides material that can earn attribution. A form wall or a non-extractable format obstructs that use. Before publication, AI drafts and other content need named authorship, first-person experience signals, verified factual claims, and attention to E-E-A-T. These are substantive checks. They give the page claims that can be extracted and assessed.
The distributed layer provides corroboration away from the site. Branded web mentions correlate more strongly with AI visibility than backlinks, though correlation does not make any placement a guaranteed citation. The practical actions include contributing expert commentary to industry roundups, engaging authentically in community discussions, appearing in independent comparison guides, and earning genuine user reviews. Citation monitoring is then the record in which to watch for a change.
How the measurement stack fits together in practice — inspection tools, citation trackers, and traffic attribution
The tools need separate jobs even when one product does several of them. Crawlers, structured-data validators, and AI-readiness auditors handle inspection. Traditional SEO tools such as Semrush, Ahrefs, Screaming Frog, Sitebulb, SE Ranking, and Google Search Console remain a base for crawlability, indexation, and technical health. Their role is not displaced by citation tracking. Accessible pages, clear entities, useful internal links, and crawlable site structures remain prerequisites.
Ansvisor is open source, MIT-licensed, and available in cloud or self-hosted form, with fixed-prompt tracking across engines including ChatGPT, AI Overviews, AI Mode, Gemini, Perplexity, Copilot, Claude, and Grok. Claude tracking is available on Enterprise plans. MaxAEO pairs monitoring with tips for optimization, while Search Party has tools to analyze share-of-voice, sentiment, and perception. The choice depends on the monitoring job required.
AI Rank Lab combines SEO, AEO, and GEO analysis in one reporting environment, while Conductor integrates AEO and GEO signals into enterprise SEO workflows. Amadora AI helps teams track results and act on them in monthly baseline-implement-measure-report cycles. Coverage still needs close attention. Engine access, refresh cadence, and plan differences can change what a team is actually observing.
For repeatable testing, visibility platforms should retain the full response, source links, model, and test conditions. Answers can change with the model versions, the location, the language, and the words used in the prompt. GA4 channel groups and search reporting have their own role in traffic attribution. The Bing AI Performance Dashboard, which has been public since February 10, 2026, adds first-party data on citations and grounding queries. Microsoft notes that the grounding-query data represents a sample of overall citation activity, so that caveat should not be extended to every reported count.
What a founder should actually do with an AI SEO analyzer score
The practical posture is to use the score as an entry check. A failing result calls for work on crawlability, structured data, llms.txt where relevant, citable formats, and entity consistency before investing in citation monitoring. A passing result calls for observation beyond the page. It is not evidence that the retrieval, ranking, or attribution gates have been cleared.
Each record then needs its own cadence. Page inspection belongs after major site changes and in a periodic structural audit, while citation monitoring needs a fixed prompt set repeated consistently across the same engines. A single snapshot cannot establish a trend. Traffic attribution should run continuously through configured AI channel groups in GA4, cross-referenced with citation data while recognizing that the connection is incomplete.
When inspection is strong but citation presence is weak, the next investigation belongs in the entity record and distributed mentions. When citations are strong but visits are scarce, the question shifts to audience contact and possible shortlist influence. The founder’s discipline is to define the metric, observe it on a schedule, change something, and measure again, treating AI visibility as a signal to watch.