Why AEO content strategy is an engineering problem, not a content calendar problem
Solving answer engine visibility requires engineering infrastructure.
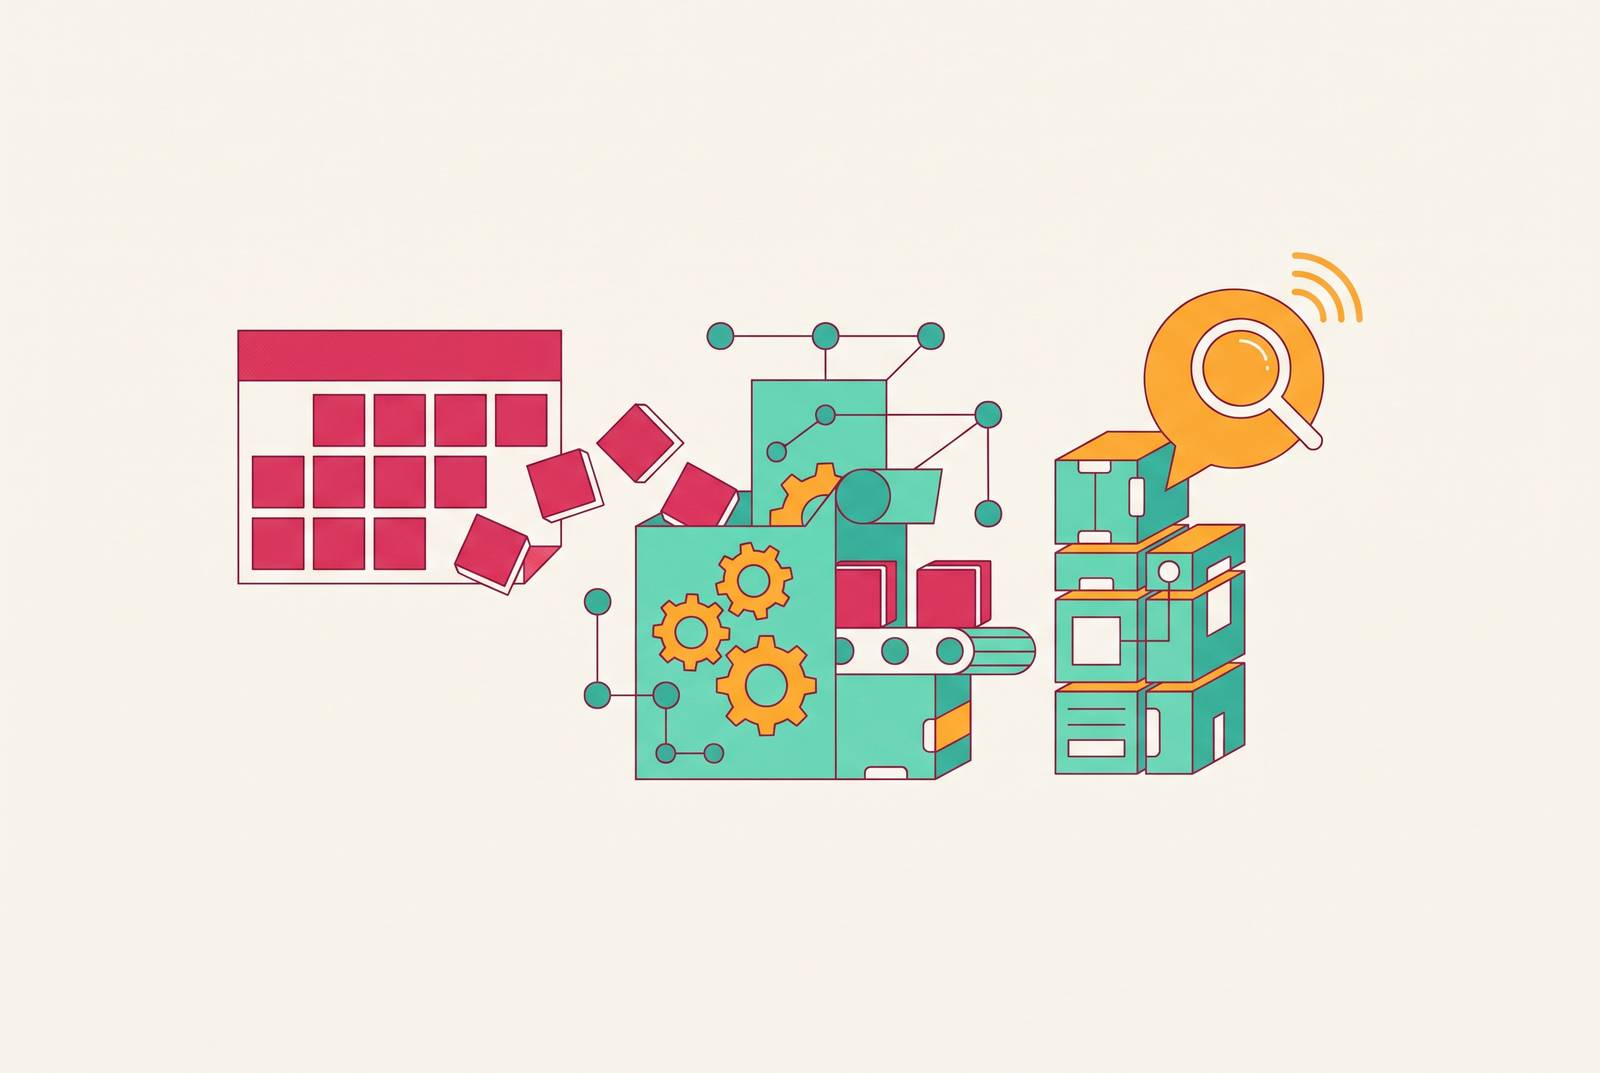
Answer engine optimization, or AEO, is a problem of retrieval, measurement, and publishing. A better content calendar cannot tell a brand whether AI engines can read its pages, cite its claims, or recommend it accurately. That requires an engineering system that instruments visibility, publishes retrievable content, and uses the results to decide what changes next.
Why AI answer engines are a different retrieval problem than search engines
The retrieval-augmented generation pipeline moves through query interpretation, retrieval, ranking, generation, and citation. Each stage is a separate technical gate. An answer engine must find material, select what it can use, build a response, and decide which sources receive credit. Unlike a search engine returning a ranked list of pages, it synthesizes an answer from retrieved documents and cites a small number of sources. The unit of competition is therefore a citation slot.
This changes what relevance means in practice. A page can surface for a semantically related question without containing the exact phrase the person used. Keyword optimization alone does not account for that mechanism, because the engine is looking for material that helps answer an interpreted question. A page can consequently rank well in traditional search yet never appear in an AI answer. A page can also earn citations without getting clicks.
Does that make search performance irrelevant to AEO? No, but search performance tells only part of the story. Ranking, retrieval, and citation describe different outcomes, so success at one does not establish success at another. Nor does citation on one engine establish visibility elsewhere. ChatGPT, Google AI Overviews, and Perplexity use different crawlers, indexes, and source-selection logic, which makes platform divergence part of the problem from the outset.
What a content calendar was designed to solve, and why that design fails here
A content calendar lays out topics, publication dates, and what the team plans to cover. It helps a team publish consistently and avoid leaving important subjects untouched. The calendar does not reveal whether a crawler can access a page, whether an engine can extract its answer, or whether a buyer’s question returns the brand in a positive light.
The calendar lacks a measurement loop. Rankings and traffic remain useful, while AEO adds citation frequency, mention rate, share of voice in AI responses, and assisted conversions. Publishing the planned article produces none of those measurements by itself. Without them, the team knows that work shipped but not whether it changed how answer engines use the site.
A careful editorial team might reasonably object that it already tracks performance and adjusts. The distinction is what tracking requires here. Reading a traffic dashboard cannot substitute for querying AI engines programmatically across a defined prompt set. The calendar also does not usually track access settings. Google’s June 2026 Search generative AI control, for example, is a site-level switch that can exclude content from AI Overviews and AI Mode. A publishing plan is not designed to detect that condition.
How AI engines actually decide to cite you — the signals content teams cannot see from a dashboard
Crawl access is the first concrete gate to examine. Before debating the strength of an answer, a team needs to know whether the relevant crawler can reach the material. Schema, freshness, and structural extractability add further considerations that traffic alone cannot explain. Clear direct answers, statistics with cited sources, logical headings, and semantic chunking make material easier to extract. These are choices about content architecture as well as writing.
Entity recognition is another kind of authority. This authority depends on how well an AI model recognizes a brand’s relationship to a topic, rather than simply how much backlink authority the site has. Off-site presence also contributes to the source stack, which includes verified data banks, high-trust user content on Reddit and review platforms, and brand-owned assets. A corporate site is therefore not the whole evidence environment. Improving it cannot stand in for understanding the other sources an engine uses.
How firmly are these signals understood? The June 2026 arXiv paper analyzing brand responses tracked from March to May 2026 describes its findings as “a first large-scale baseline.” It does not show that specific changes to content lead to better citation outcomes. The engineering framing remains sound because access, extraction, and outcomes need observation, but the precise tuning levers are still hypotheses. Instrumentation helps teams test advice that sounds right but has yet to be proved.
The same paper found that sentiment shifted far more often than mention status. A brand can remain present in answers while its framing turns negative. Monitoring whether it appears is therefore only part of the task. Monitoring how it appears is necessary to detect a change that a mention count would conceal.
The visibility gap between brands that instrument AEO and those that don't
The paper describes a three-tier visibility ladder with global household names, established mid-market brands, and niche or small brands. Those groups differ greatly in how often they appear in an answer on the first run. That pattern is not adequately explained by prose quality alone. Entity recognition, crawlable and extractable content, schema, and the depth of the publishing system all help explain why infrastructure belongs in the analysis. The tier gap does not, however, prove the effect of any single intervention.
This can affect business before anyone visits a website. The Similarweb 2026 Generative AI Brand Visibility Index found that a large share of US consumers use AI during product discovery. Brands absent from those answers can be absent from the resulting shortlist. Meanwhile, infrastructure can create a reinforcing advantage as citations support recognition and recognition supports future visibility. Teams that do not add AI-specific measurements lack the feedback needed to understand that gap, much less respond to it.
What "treating AEO as an engineering problem" actually means in practice
The practical response has three connected layers, namely instrumentation, a content pipeline, and a measurement loop. The instrumentation layer starts with a defined prompt set that covers the questions buyers ask during discovery, evaluation, and decision-making. That set establishes what the system is measuring. Without a stable query surface, a team cannot easily distinguish a change in visibility from a change in the questions it happened to ask.
The headline metric is Share of Model, or SoM, calculated as brand mentions divided by total AI answers in the tracked prompt set. Because this measures presence, teams must also track sentiment to assess the quality of the framing, which can become less favorable even as mention status stays the same. The recommended starting engines are ChatGPT, Google AI Overviews, and Perplexity, which account for the dominant share of answer-engine referral traffic for most B2B and B2C brands. Coverage can then extend to Claude and Gemini.
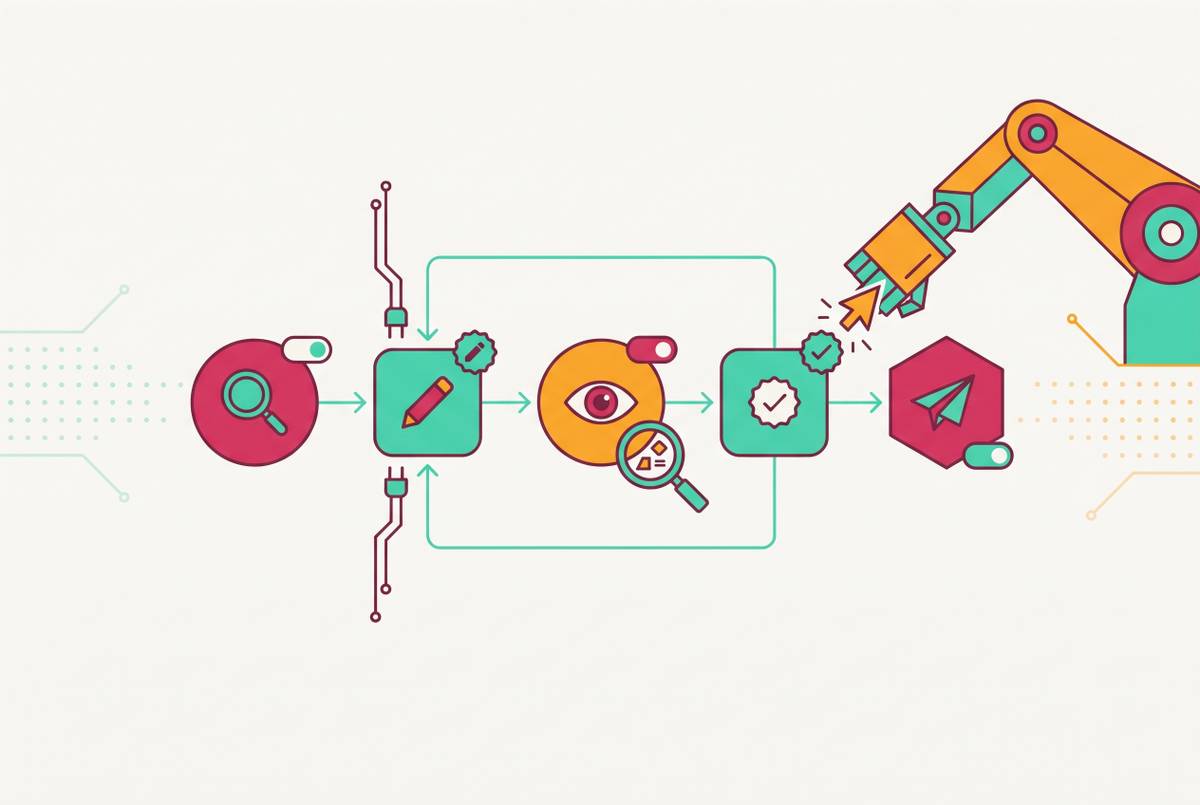
The content pipeline is the second layer. It moves through brief, draft, review, and audit, with each stage serving a distinct function. Generation shapes the page and what it covers, while human review checks its claims and voice. A scheduled audit catches stale or misframed content.
The publication gate is where that distinction becomes concrete. Whether a model drafted a page is less useful than whether the page is factually verifiable, structurally extractable, credibly authored, and topically complete. Generation can build the scaffolding quickly, but review must handle claims that the machine cannot verify. A hard gate blocks publication when the page fails. Speed comes from assigning the work correctly while retaining the check.
Freshness also changes how publication is triggered. A calendar sets dates, while a pipeline sets conditions. Claims aging or citation rates dropping can trigger an audit and republication rather than leaving the page untouched until its next editorial slot. That does not mean every decline calls for a rewrite. The condition starts a diagnosis, which must distinguish a content problem from an access or source-presence problem.
The pipeline also needs two content tracks. The paper found that citations concentrate heavily on corporate websites, while YouTube, Reddit, editorial media, and review platforms form a meaningful part of the citation pool. In a ground-site and off-site architecture, the owned site is optimized for extraction, while the off-site layer supplies corroborating presence across that pool. Ranked “best-of” listicles are a high-leverage format in this setting. Building and maintaining presence in those comparisons, on owned and third-party surfaces, is ongoing work for the system.
The measurement loop is the third layer. Its function is to connect observed outcomes to changes in the pipeline. A mention count alone cannot tell a team whether to fix crawl access, review an aging claim, or fill a gap in off-site sources. The loop turns those measurements into questions for the audit stage. It also preserves the distinction between evidence that something changed and evidence explaining why.
Why each AI engine needs to be instrumented separately, not managed as a unified channel
Platform differences make a single “AI visibility” score an unreliable operating view. A brand’s citation rate on ChatGPT is a poor proxy for its rate on Google AI Overviews or Perplexity because their retrieval and selection systems differ. Aggregation can hide the distinction the team needs to diagnose.
The instrumentation implication is straightforward but demanding. The defined prompt set must run against each engine on its own, and the team must record each engine’s citation rates separately. This lets the team measure and improve results for each platform while keeping the same editorial identity. What cannot remain unified is the assumption that one engine’s response proves the content works everywhere.
Closing the measurement loop: how to know whether AEO is working and what to change
Citation frequency, mention rate, and share of voice in AI responses show how often a brand appears in answers, while referral behavior and assisted conversions show what happens next. These signals answer different questions. A rise in citations does not by itself establish more visits or conversions, just as a traffic dashboard cannot reveal every citation.
Within the answer itself, retrieval, citation, recommendation, and sentiment are separate events. A brand can be retrieved without being cited, cited with negative framing, or recommended without being named. Each condition calls for a different investigation. Treating all of them as a single success measure would erase the distinction between being available to the engine and being presented favorably to the buyer.
The engine can also change the relationship between those events. Lily Ray’s August 2026 analysis found that ChatGPT’s retrieval set grew after a model update while citation credit went to a smaller number of unique cited domains. A measurement system must track changes in how the engine behaves as well as check whether the brand’s current score looks good. Otherwise, a team may mistake a platform change for the result of its own publishing decisions.
The audit stage closes that diagnostic loop. It runs as a scheduled job, investigating a drop in prompt-level citation rate for crawl access failures, schema issues, stale content, or gaps in off-site sources. The findings show which pipeline stage needs the fix, and the next round of measurement tests whether it worked. Given the unsettled causal evidence, the system should not assume that the first plausible explanation is the correct one.
Publication is not the finish line for AEO. The work becomes an engineering discipline when a measured outcome changes what the system does next.