Search Intent Is a SERP Heuristic — Machines Need Intent Signals, Not Categories
Search engines rank by signals, not intent categories.
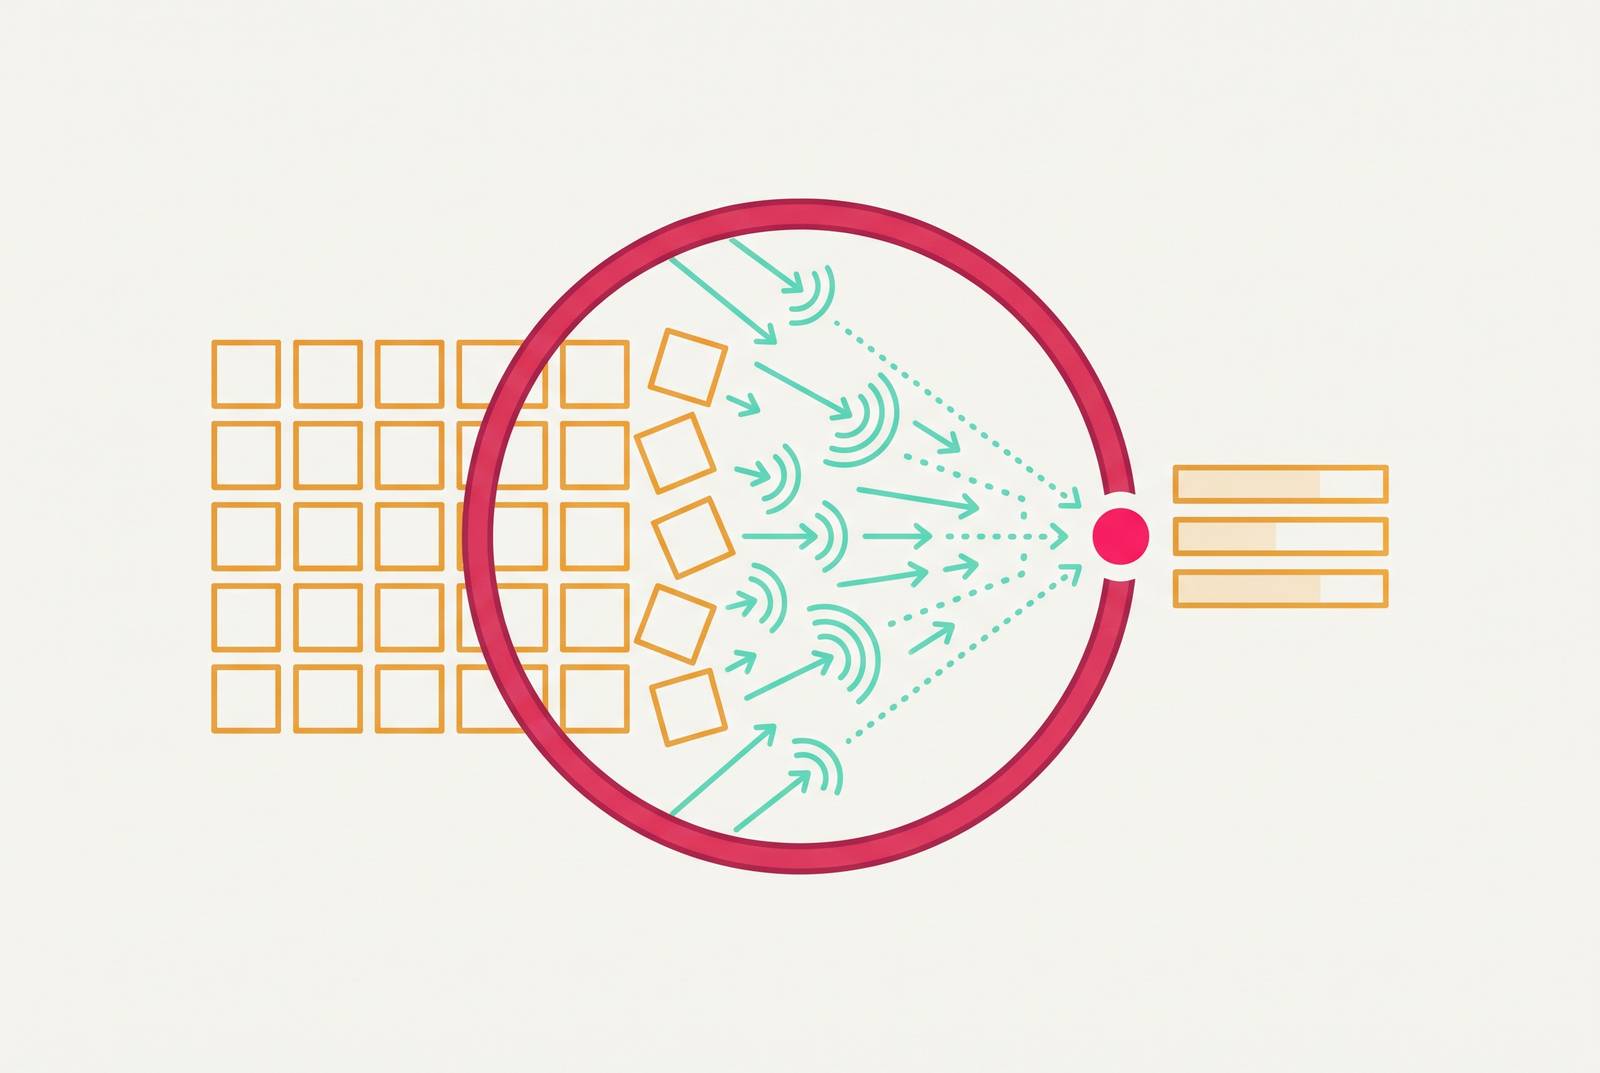
Search intent is a useful way to describe a search results page, but it is not a blueprint for how a search engine works. The familiar four categories summarize what people want. Machines need signals they can read and weight. When teams confuse those two things, they build the wrong content for both Google and AI answer engines.
Where the four-bucket taxonomy came from and what it was actually designed to do
Andrei Broder’s 2002 paper established informational, navigational, and transactional as ways to describe what people want from search. The SEO community later added commercial investigation so that comparing products and researching a purchase had a category of their own. That extension made the vocabulary more useful for planning. It did not turn the vocabulary into a description of machine computation.
The taxonomy belonged to a keyword-matching era, when intent labels helped people decide which words to target on a page. Its purpose was practical and human-readable. A team could distinguish someone seeking an explanation from someone trying to reach a website or complete a purchase. Those distinctions remain useful, provided the label is treated as shorthand.
What search engines actually operate on instead of categories
A keyword can score strongly on research and moderately on transactional intent at the same time. Content Harmony shows this through fractional scoring, which gives more detail than a single binary assignment. That is a useful illustration. It shows why “which bucket?” can be the wrong question when several purposes are present in different proportions.
Search engines work with behavioral, semantic, and contextual signals to produce a probabilistic ranking. Embeddings and entity mapping measure semantic relationships, while the device, location, and prior searches give the system context. Behavioral feedback, including click-through rate, dwell time, and repeat searches, helps refine the inference. Similar queries can also be grouped by behavioral patterns and semantic proximity. A novel query therefore need not have a preassigned category before a system can infer what might satisfy it.
Entity signals make this less abstract than “understanding intent” sounds. CONSUMER_GOOD entities and price information can push an interpretation toward a transaction, while organization and URL signals can point toward navigation. Google Cloud’s Natural Language API reference distinguishes CONSUMER_GOOD as an entity type and PRICE as typed metadata. These are not interchangeable technical labels. Entity salience and sentiment can further adjust the interpretation, so the presence of a product name alone does not settle the result.
What practitioners call “the intent” is the inferred outcome of these interacting signals. It is not a lookup in a four-row table. A category can describe the strongest pattern, but it discards the weaker signals that may still influence which page, format, or answer the system favors.
Why Google's own framework and the industry's four buckets are not the same thing
Google’s Search Quality Rater Guidelines use Know, Do, Website, and a category for in-person visits, with Know divided further into Know Simple and fuller Know needs. These are not the industry’s four buckets. A rater framework also leaves out parts of how the ranking system works. It is guidance for evaluating results, and its distinctions expose gaps in the shorthand practitioners often use.
Know Simple makes the gap concrete. A featured snippet or knowledge panel can satisfy such a query in seconds, leaving even a first-ranking page with almost no clicks. Calling the query “informational” does not reveal that constraint. If the team uses that broad label as a reason to write an article aimed at traffic, it may choose the wrong way to measure success before it starts writing.
The page may still have value as an authority and citation vehicle. But that is a different purpose from attracting sessions. Commercial investigation creates another mismatch because it occupies a hybrid Know/Do space. Page type, depth, and calls to action follow from these distinctions. A convenient label cannot substitute for examining what the result must actually provide.
How the SERP functions as a real-time signal classifier, not a stable reference
The search engine results page, or SERP, expresses the machine’s current inference through the results it presents. Its dominant content type is evidence about what the engine thinks will satisfy the query. Featured snippets, video carousels, shopping results, and local packs reveal more specific expectations. Reading them is reading the machine’s current output.
That output can change as behavioral signals change. A broad query such as “AI” makes the weakness of a fixed reference especially clear, because the same short wording can sit over a changing distribution of needs. Even when “informational” remains an acceptable description, the useful format and depth can shift beneath it.
This creates a practical distinction between a poor page and the wrong kind of page. A team that assigns intent from keyword modifiers alone may publish polished content in a format the live results do not favor. More polish does not resolve that mismatch. Ahrefs added a free tool to a landing page to match the live SERP’s dominant content type, and traffic grew a great deal.
Where the four-bucket model breaks entirely — mixed intent, modifier stacking, and Know Simple zero-click
Consider the decision to build one narrowly targeted page for “Canon cameras.” The query can express a wish to reach the brand site, compare models, or buy immediately. Google’s guidelines instruct evaluators to consider multiple reasonable intents for a single query. Choosing one category does not erase the others. A page built around that choice may address only part of the distribution the engine is evaluating.
Modifier stacking creates a different planning error. “Best cheap running shoes 2026 reddit” combines freshness, price sensitivity, format expectation, and source authenticity. Calling it commercial investigation tells the team little about how to meet all those needs at once. A comparison that overlooks price sensitivity or the kind of source people expect can fit the category but miss what the query asks for. The modifiers refine one another.
Know Simple causes a failure in measurement as well as format. Informational queries now cover both needs that a featured snippet, knowledge panel, or AI Overview meets on the SERP and deeper needs that still lead people to visit a page. For the former, the appropriate asset is an authority and citation vehicle.
Someone asking a tool to produce an output expects a synthesized, conversational answer. That expectation changes the required structure of the response and raises a harder question about what AI answer engines can retrieve and use.
How AI answer engines read intent signals differently from classical search — and differently from each other
An AI citation is not another name for a Google ranking. The overlap between top Google links and AI-cited sources has shifted substantially, so strong performance in one system does not establish strong performance in the other. A source can also appear in an AI answer without a top Google position.
That distinction makes “optimize for AI intent” too vague to guide a content decision. What does the answer need to explain, and which parts of the page can it use? A category such as commercial investigation answers neither question. It also gives no reason to expect different answer engines to select the same sources, so performance across them cannot safely be treated as one undifferentiated result.
The Princeton GEO study, published at KDD 2024, offers a more concrete starting point. Its large-scale benchmark found that adding citations, quotations from relevant sources, and statistics materially increased visibility, producing the biggest gains in the study. Those additions give an answer system usable evidence. They change what can be retrieved and attributed, rather than merely changing the label attached to the page.
The finding supports a shift toward structural retrievability while leaving citation by individual engines uncertain. An attributable quotation gives a system something different from an unsupported statement, even if both sit on pages assigned the same intent category. The operative distinction is the evidence available for synthesis. That is more precise than asking whether the page sounds “informational.”
What practitioners should measure and optimize instead of assigning intent categories
Intent should lead: understand the user’s problem first, confirm demand with keyword data, and validate the page type against the live SERP. This preserves the useful question behind intent research without treating a keyword label as the answer. It also separates a person’s need from the format a retrieval system currently favors.
For classical search, practitioners should query the actual wording and inspect the top results before assigning a label. They can see the evidence in the dominant content type, SERP features, modifier stack, and related searches. From there, the team can decide the dominant need, choose a page type, and validate the decision after publishing. The order is important. A category recorded at the end summarizes the investigation, while one assigned at the beginning can prematurely narrow it.
For AI answer engines, the work should focus on extractable structure. Clear headings should match the question, named entities should have stated relationships, and quotations and statistics should have attributable sources. Decision frameworks should offer more than a summary can replicate. These choices build on the GEO study’s support for evidence, though that does not mean every choice about structure has the same measured effect.
Measurement should also distinguish the two retrieval tracks. Classical search requires validation against the live result format, while AI performance requires explicit tracking of citation share and referral outcomes. The higher conversion rate reported for AI referrals compared with Google organic referrals ties citation share to revenue as well as visibility. Still, a citation and a visit are different outcomes. A Know Simple page should not be judged as though its only useful contribution were sessions, and a Google ranking should not stand in for evidence of AI citation.
Why the content that earns AI citation is also the content that survives intent drift on classical search
Teams can use much of the same content strategy for different retrieval systems. Named entities, attributable claims, extractable structure, and depth beyond a summary give both systems more to work with. Their source selections may diverge even when these foundations help both. That is the distinction between convergence in content quality and convergence in results.
Original data, decision frameworks, worked examples, and templates address the same weakness exposed by zero-click answers. They offer value beyond the short response while providing material a machine can extract and attribute. They also depend less on a fixed category. As the intent distribution changes, those signals remain readable, even though their weight and the preferred result format may change.
The question is not “which bucket does this keyword belong to?” but “what specific signals does the machine need to read this page correctly, weight it appropriately, and cite it in a synthesized answer?”