The Publisher AEO Playbook Is a Signal, Not a Strategy
Bustle's AEO playbook shows what works for publishers, not what brands should actually build.
The publisher AEO playbook shows what answer engine optimization requires, but not what a brand’s strategy should be. Bustle Digital Group’s program shows how the work gets done, from tracked prompts to citation reports. For B2B and dev-tool teams, its value is as a proof of concept. The useful next step is to rebuild those mechanics around the questions their buyers ask, on infrastructure they can own and measure.
Why publishers are selling AEO to advertisers right now
Organic search traffic to publisher sites has dropped sharply, while AI answer engines scrape far more content than they send back in referral visits. The mechanism is zero-click resolution. An engine draws on a publisher’s work, synthesizes an answer, and resolves the reader’s question without sending that reader to the source page. For an ad-supported publisher, that separates the value of its editorial work from the traffic that helps fund it.
That separation changes what a publisher can sell. A business that depends on branded content and affiliate commerce cannot treat the loss of referrals as simply a need for better articles. Its revenue model is under pressure. BDG’s AEO offering responds by selling access to an asset it still controls, namely an editorial surface that AI engines trust enough to cite. Advertisers want visibility in those answers, so the publisher can sell citation lift rather than rely only on readers arriving at its pages.
What BDG's AEO program actually does, step by step
BDG’s program begins with a defined corpus of 250 prompts per advertiser engagement. That set establishes the questions the workflow will monitor and the scope against which results will be reported. An agent then researches the prompt set and surfaces patterns in the answers. Rather than moving straight from a broad advertiser category to an article, the workflow passes through a research layer that informs content briefs.
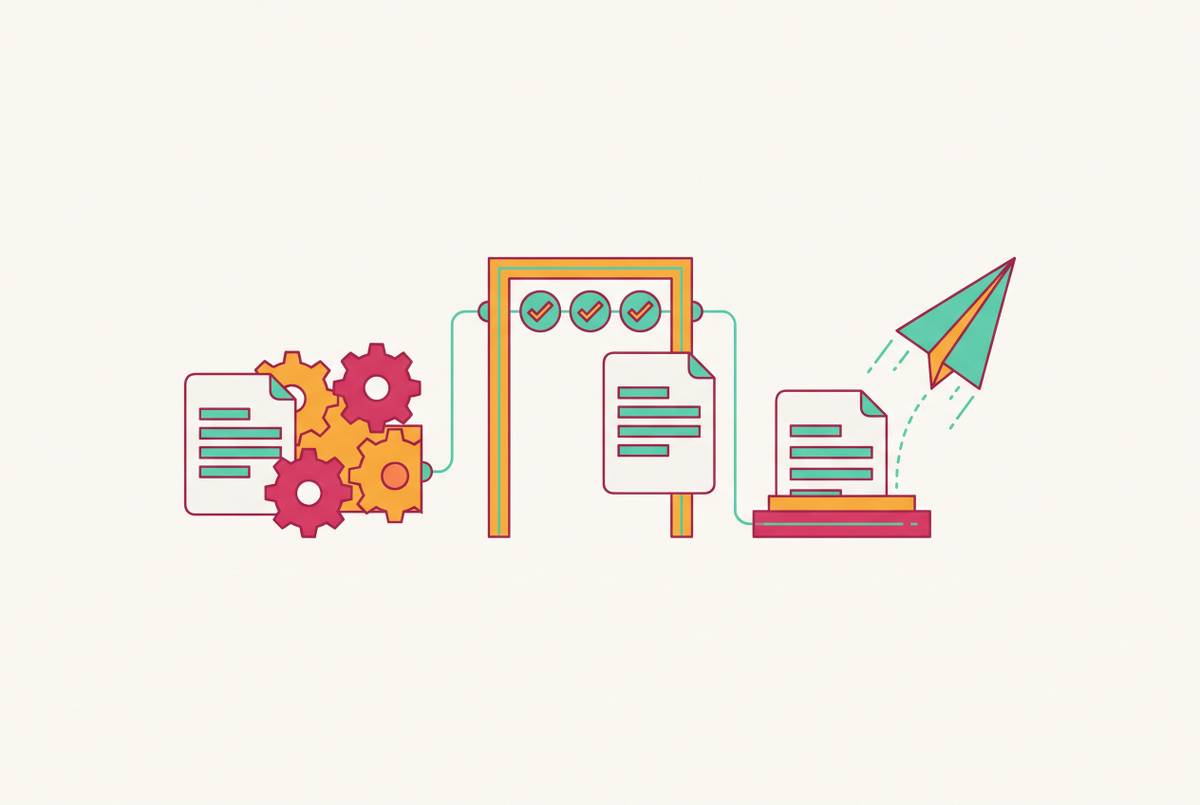
The briefs become the basis for AEO-optimized content. The team publishes content after briefing and measures it after publication, tying the work to the prompt set that started it. The final advertiser report gives citation share, a measure of how often the brand appears as a cited source across the tracked prompts. That is the program’s reported output. The pipeline therefore runs from prompt corpus to agent research, then to briefs, content, and citation measurement, with the publisher managing the workflow for the advertiser.
What the playbook reveals about what AEO requires operationally
Read as an implementation rather than an offering, this workflow exposes four requirements for a functioning AEO program. They are a defined prompt corpus, agent-assisted research and briefing, a publication cadence, and a citation measurement loop. Each has a distinct job. The corpus sets out what to research, the briefing layer turns what the team learns into choices about what to publish, and the cadence keeps that work going. Measurement then shows how the content performed so the team can plan the next cycle.
The prompt corpus comes first because an answer has little meaning outside the question that produced it. A brand can appear in one answer and be absent from another that looks similar at a glance. Five prompts do not provide an adequate baseline. BDG’s 250-prompt scope shows how much there is to monitor, though each brand need not track that same number. The set needs to be broad enough to show patterns, with more than a few answers picked because they look promising.
That breadth creates the need for an agent-assisted briefing layer. Research across a large prompt set has to happen too often for humans to do all of it. The agent links the research to the content brief. Its purpose is to shorten the distance between identifying the questions and identifying content that could shift citations on those questions. Without that bridge, monitoring produces observations that a team still has to translate into a publishing decision.
Publication must also recur because freshness and recency influence what answer engines select. Frase identifies both as signals in its AEO guidance. Citation measurement helps the team decide when and what to keep publishing by tracking whether the AI names the brand, rather than using page rank or click-through as the output metric. These components are separable primitives, even though BDG bundles them into a managed service. A technical team can build each part on its own without buying the service that bundles them.
Where a publisher's AEO stack diverges from what a brand needs
BDG serves an advertiser buying citation exposure on a publishing surface the advertiser does not own. A brand building its own program controls its domain and what it publishes there. Ownership changes the available decisions. The brand is not simply purchasing an outcome from an editorial partner, but deciding how its content, research, and measurement should develop together.
A brand’s site accounts for only a small fraction of citations in AI answers, regardless of how much content it publishes. This is a source-diversity constraint. An engine can draw on several sources for its answer, so even with more pages, one domain still has a limited role. A strategy confined to owned pages is therefore working on only a small part of the available citation surface. The publisher model was not designed to solve that whole problem for the advertiser.
Advertiser categories are not a substitute for the decision-making questions a B2B buyer asks when evaluating a dev tool or SaaS product. The brand needs its own research. Otherwise, it can gain visibility across the publisher’s measurement set without learning enough about the questions that shape its buyers’ choices. The same distinction applies to reporting, because a client deliverable tells the advertiser what happened within an engagement, while an owned measurement loop can inform the brand’s next decision.
The version of this stack a technical team can own and instrument
For a technical team, the constructive response is to rebuild the four components on infrastructure it controls, with usage metered and operations programmable from the start. The prompt corpus should begin with first-party research into questions buyers ask at each stage of a decision. Sales calls and support tickets give the team a place to start. Community forums and direct prompt-testing across ChatGPT, Perplexity, Gemini, and Claude take that research to places where people discuss questions or get answers. The goal is not to reproduce a publisher’s category coverage, but to define the decisions the brand needs to understand.
The owned site then needs to support machine retrieval as well as human reading. Frase describes AEO through a RAG pipeline involving retrieval, ranking, and synthesis. Machine readability therefore needs to be built in from the start. Clear headings, semantic chunking, and schema markup help structure the content the engine can retrieve. Grounded content and real domain expertise still supply the substance, while that structure makes the substance easier to use. This foundation gives the team an asset whose content and presentation it can control.
An agent briefing layer should use that buyer-specific corpus and the citations that engines return now. Its task is to surface gaps, including prompts where the brand is absent, competitors that appear, and content structures that earn citations. Human review remains the publishing gate. A reviewer checks whether a planned piece gets the brand right and decides whether to turn the brief into content.
The team should tie its publication cadence to continuous measurement across the same four engines. After each publication, the team should use citation gains and losses in the next briefing cycle instead of waiting to present them in a scheduled report. That connection is what makes the workflow cumulative. To support it, the measurement and publishing layers should be reachable through APIs, so the team can push and pull data within its existing workflows. A process that depends on a UI click to run each measurement or trigger each brief remains a manually operated tool.
What measurement changes when you run the loop yourself
Owning that loop changes the resolution at which a team can examine results. A citation-share report gives an outcome at a point in time, but the aggregate does not identify which prompts moved, which engine responded, or which content action preceded the change. Those distinctions guide the next brief. Query-level attribution and engine-level results let the team connect publishing work to specific citation shifts rather than infer a direction from one combined number. Keeping a record of what the team published and what happened gives it more evidence to compare over time.
Engine differences make this more than a reporting preference. Frase notes that ChatGPT, Perplexity, and Google AI Overviews have slightly different citation preferences. An aggregate can conceal those differences. A combined gain does not, by itself, show whether the brand improved on the engine its buyers actually use. Tracking results separately across ChatGPT, Perplexity, Gemini, and Claude lets a team see how citations changed in each engine without assuming that a gain in one will carry over to the others.
The prompt set also needs to change as buyers adopt AI tools and their questions evolve. Continuous monitoring makes shifts in the tracked results visible sooner, while ongoing buyer research helps the team decide what to add or revise. A corpus that stays the same cannot show every new question. Ownership gives the brand the ability to update that measurement surface rather than wait for the next reporting engagement to reconsider it. A brand that gets quarterly reports sees reported changes three months late, leaving more time for what it assumes to fall out of step with how buyers and engines now behave.
When a favorable report becomes a reason to slow the program, citation share can decline before the next report flags the loss. The practical standard is traceability. Every content action should be traceable to a citation outcome on a specific prompt set and engine, including cases where the expected improvement does not appear. A team should be able to identify which three prompts improved on Perplexity after the June brief. That record supports a better next decision, though it does not by itself prove why an engine changed its answer.
What to take from the BDG story and what to leave behind
The transferable part of BDG’s program is its operational structure. Renting a publishing surface and receiving a citation report can serve an engagement, but that arrangement is not a blueprint for owning a brand’s AEO program. The distinction is where the asset accumulates. For a brand, the opportunity is to develop grounded expertise on a trusted, machine-readable surface, extend it off-domain, and connect publication to evidence it can retain and use.
Of the prompt corpus, agent briefing, publication cadence, and citation measurement, which components does the team own and instrument today, which does it rent or receive as reports, and what would it take to instrument each one itself?