When your content has a build step, a test suite, and a deploy pipeline
Structure and validation turn content into reliable inputs for AI-powered answer engines.
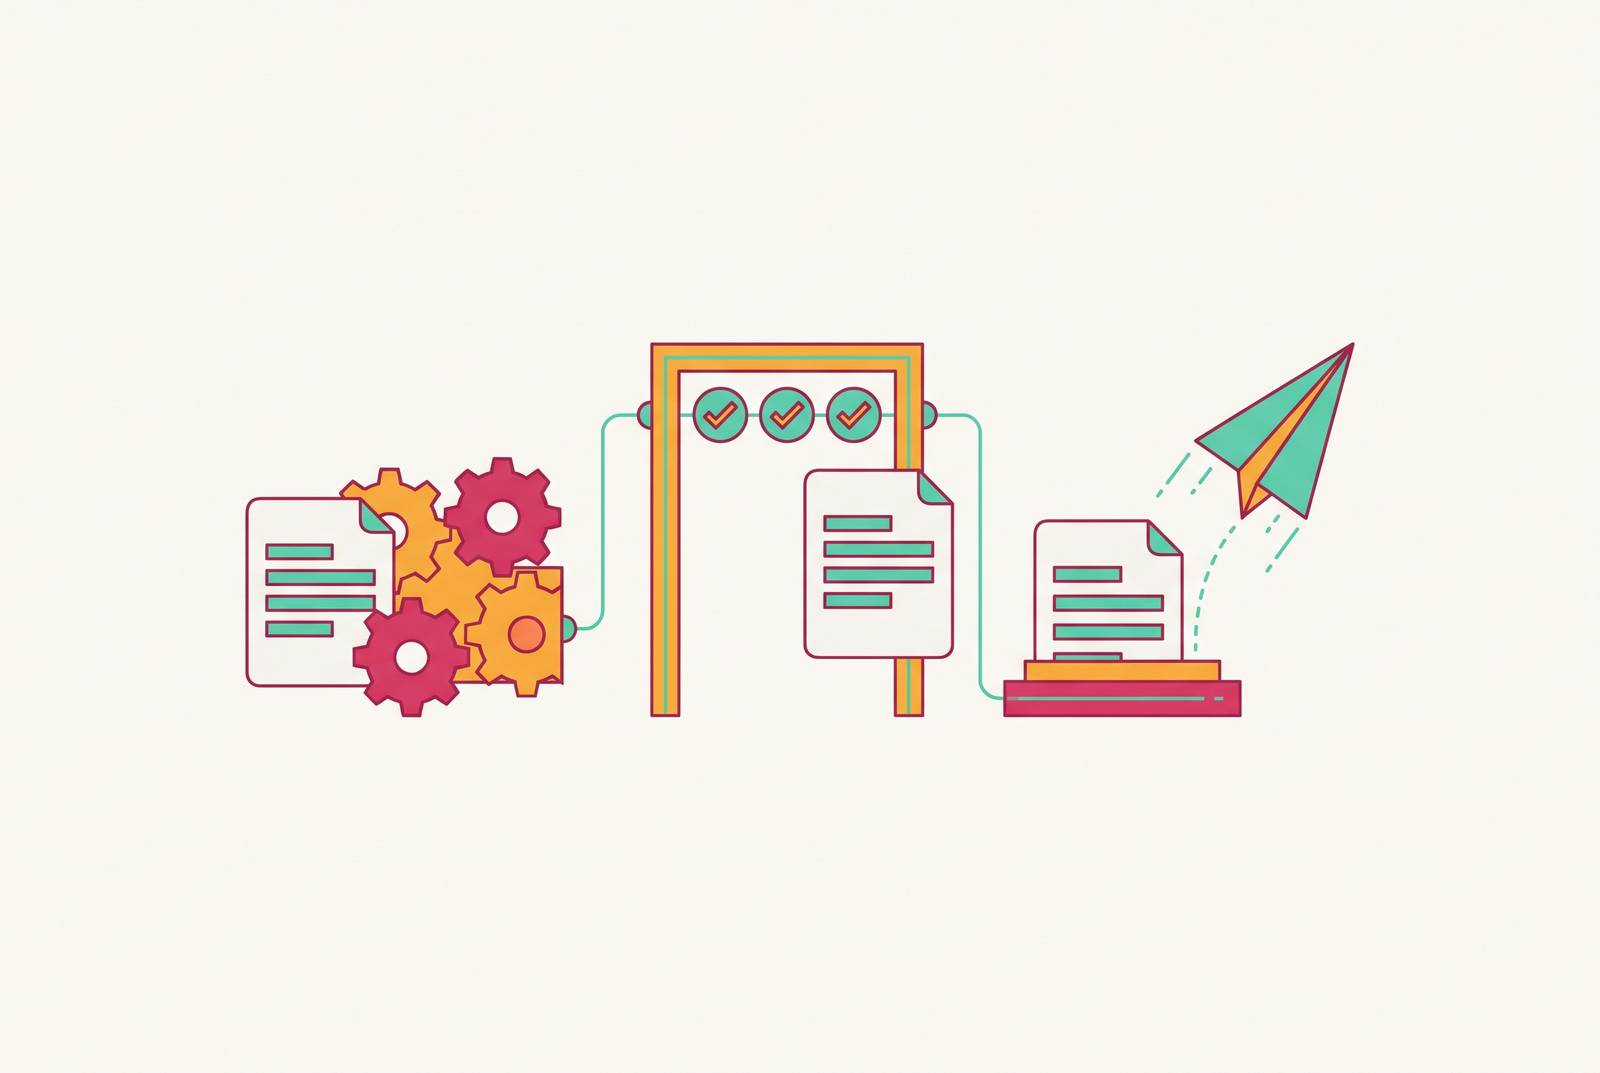
Content becomes reliable at scale when it is treated as a software artifact. A build step enforces structure, a test suite catches drift, and a deploy pipeline makes publication repeatable. With human review and AI citation measurement, those controls turn a growing library into marketing infrastructure that gets better with use and stays easy to maintain.
Why content at scale breaks when you treat it as writing
A page goes live with no canonical URL. Another has broken schema, while a third still has placeholder text from its template. Across the catalogue, variants use the same sentences with different names. These failures can happen even with a skilled author. They arise because the publishing process has no structural guarantee that a page is complete, distinct, and ready to ship.
Writing more drafts does not fix that weakness. Multiplying a template across thousands of variants can produce a “Mad Libs” library whose apparent breadth hides the same boilerplate. When each page lacks information of its own, adding more pages raises the risk of duplicate-content problems and deindexing and does less to help readers. The underlying data and rendering system can support expansion with useful pages or multiply defects.
A writing-led process usually leaves the final check to a person. As the catalogue grows, the human loop becomes the bottleneck, especially when reviewers must catch technical omissions as well as editorial mistakes. The necessary change is architectural.
What a build step actually does for content
A build step computes a publishable page from a source of truth. The source is no longer just a document someone edited. It is a typed content record containing the editorial and SEO fields the page needs, including slug, title, summary, body, metaTitle, metaDescription, canonical, and schema. The build turns that record into the outputs that readers and retrieval systems receive.
This creates a contract between source and output. Metadata, canonical URLs, and JSON-LD are derived from the same record that supplies the body. When the source changes, dependent outputs can be regenerated from it. That removes the need for a manual sweep to reconcile page copy with metadata, provided the pipeline updates the affected pages.
The architecture is concrete enough to implement. In a Next.js system, content goes from data storage through a validation layer before it reaches caching and rendering. These layers give the build a defined place to enforce its contract, rather than leaving “structured content” as an aspiration in an editorial handbook.
But does every page need to be generated in advance? Generating tens of thousands of static HTML files at build time can exhaust memory or cause timeouts. Pre-render the highest-traffic pages and generate the rest on demand through ISR fallback. The guarantee concerns how pages are produced.
Schema validation as the content equivalent of a type system
A content model says what should be in a record. Validation decides whether a record is allowed through. A content model marks a field “required” in a document, while a publishing system enforces that requirement by refusing an incomplete page. Like a type system rejecting code that violates a contract, the validation layer blocks records that fail defined rules.
In the Next.js architecture, a Server Action using Zod can sit between storage and the caching and rendering layers. Records that fail validation are rejected before reaching the CDN. The rules can require a canonical, well-formed structured data, and enough source information to support a useful page. Placeholder detection needs its own assertion, since text can be non-empty and still be a placeholder.
Editorial review serves a different purpose here. A reviewer can judge accuracy, voice, and whether an explanation makes sense, but cannot reliably inspect every canonical and JSON-LD object across a large catalogue. Structural checks belong in a gate that runs for every record.
A maximum template-overlap rule and a minimum number of unique data points can block variants that offer too little new information. Those checks can reject defined forms of repetition before rendering. Validation is what separates an enforceable content pipeline from a reusable content template.
What a test suite means when the artifact is a page, not a function
A page that passed validation can still deteriorate later. Dependencies change, internal links break, and metadata falls out of step with body copy. A test suite adds continuing assertions about how the system behaves, so the original publishing contract does not quietly decay.
Unit tests check the functions that make the SEO outputs. Does articleSchema() produce valid JSON-LD from an input record? Does the metadata generator produce a canonical that matches the slug? Integration tests check how the stages work together, including whether generation makes the expected sitemap artifacts and whether a change to the source triggers cache revalidation. Content assertions check minimum word counts for core sections, template overlap, and placeholder text in the output.
These checks run in a set order in CI. The validate stage runs tests for SEO builders and schema outputs, the generate stage computes metadata and sitemap artifacts, and the publish stage merges content, triggers revalidation, and pings search engines. A regression then fails a check before the next crawl can find the defect. The same tests help assess whether a rollback restores the expected outputs.
The connection to AI citation starts here. Clean HTML, valid JSON-LD entity maps, and answer-first paragraphs make it easier to find content and pull answers from it. Broken structured data can undermine that machine-readable layer while the page still looks fine to an editor. Tests help keep pages in a form that can be cited, but a page that passes them may still go unchosen by an answer engine.
A deploy pipeline makes publication a deterministic event, not a manual act
Publication involves more than making a page visible. On a create or update event, the pipeline writes metadata, schema, and sitemap nodes, revalidates affected routes, purges changed cached pages, and pings search engines. Each action follows from the event. The person who publishes can keep the quality up without having to remember every step.
Repeatability is the point. On-demand invalidation through revalidateTag() can selectively purge cached pages when their underlying datasets change, without re-rendering the whole site. This makes freshness manageable across a large catalogue. It also connects source updates to the pages that depend on them, rather than treating cache maintenance as a separate editorial chore.
The sitemap belongs inside that same contract. It should list only indexable pages, have correct lastmod dates, and update on its own when content is published. Large catalogues can be segmented by type or date. Under this model, a stale sitemap is a deployment bug.
Scheduling also becomes a trigger within the system. A publishing cadence can start the same set of steps, while a standing watcher can start a draft when something relevant happens, with the review gates still in place. Because each approved deploy writes artifacts that fit together, new pages add to the same machine-readable entity graph. The library grows through additive changes rather than fresh opportunities to introduce incompatible schema or stale outputs.
How pipeline-built content earns citations from AI answer engines
An AI answer engine needs content it can retrieve, extract, and ground an answer in. A polished page can still be difficult to use if its claims are buried or its entities are unclear. The pipeline addresses that structural gap. Its value is not in gaming a prompt, but in making useful information consistently available in a form retrieval systems can work with.
What does that form look like in practice? Clean HTML exposes the page’s structure, while answer-first paragraph openings put the relevant claim before its explanation. When facts are stated clearly, those passages can be extracted and cited, and valid JSON-LD maps the entities they refer to. An llms.txt can provide a structured, LLM-readable index of key content, without itself guaranteeing use or citation.
These outputs support the brand’s owned answer layer. They do not replace corroboration across the broader web, which also supports visibility. A pipeline can make the brand’s own account consistent and retrievable. Third-party sources provide support beyond that account.
Internal linking strengthens the owned layer’s coherence. Links between related pages show how their ideas connect and tie the answers together. For a brand missing from AI answers, the question is therefore not only whether the writing is good. It is also whether retrieval systems can identify the relevant facts, connect them to clear entities, and find corroboration for them.
The human review gate inside an automated pipeline
Automation reserves editorial judgment for decisions that require it. AI draft generation can be one automated stage, while human decisions govern what enters the workflow and what is allowed to leave it.
The factual gate requires every claim to be verified, labelled, or removed. The editorial gate checks voice, structure, clarity, and audience fit against the brief. A risk and compliance gate addresses legal, brand, and policy constraints, and high-tier content does not skip it. The publication gate then confirms that the reviewed artifact is the version that ships, with the correct metadata and destination.
Those gates must be structural. A deploy stage that requires human sign-off cannot be advanced by an automated drafting step upstream. Every suggestion remains reviewable and reversible before it ships. This preserves the ability to reject output even when generation, formatting, and technical preparation happen automatically.
Does that just move the old bottleneck somewhere else? It narrows the work that needs human attention. Reviewers still evaluate claims and editorial choices, but they no longer have to act as a substitute for schema validation, metadata generation, or cache invalidation.
Measuring whether the pipeline's output is actually appearing in AI answers
When a deploy succeeds, it proves that the publishing contract was met. Proving that a page earned a citation requires a measurement layer outside the pipeline’s technical checks, with a clear distinction between citations, which link to content, and mentions, which reference a brand without a link. Both belong in reporting, but they are not interchangeable signals.
Core category questions can be queried in ChatGPT, Perplexity, and Google AI Overviews, with the resulting brand mentions and content citations recorded. This establishes whether the output is appearing at all. It also shifts the discussion from presumed visibility to answers that can actually be examined.
The Bing AI Performance Dashboard, public since February 10, 2026, provides first-party data on citations and grounding queries. Microsoft explicitly notes that the data represents only a sample of overall citation activity. The PR Newswire / Trajaan AEO & GEO Brand Report launched in April 2026 and expanded to APAC in September 2026. The report covers mentions, sources, and answers, connecting visibility over time with the domains shaping responses and the responses themselves.
That evidence can reveal what pipeline audits cannot. A technically sound page may remain absent because its broader corroboration layer is thin, while other pages are cited instead. Measurement shows which content appears and which models select it, giving the pipeline evidence for prioritizing corroborating content, updating entity maps, or increasing a topic cluster’s publication cadence. The feedback loop closes when those findings change what the system builds next, so each publishing cycle improves both the library and the decisions behind it.