How long does growth marketing take? Treat it as a monitoring problem: every experiment ships with a signal, a check date and a kill condition
Pre-launch signals, check dates and kill rules turn waiting into a decision.
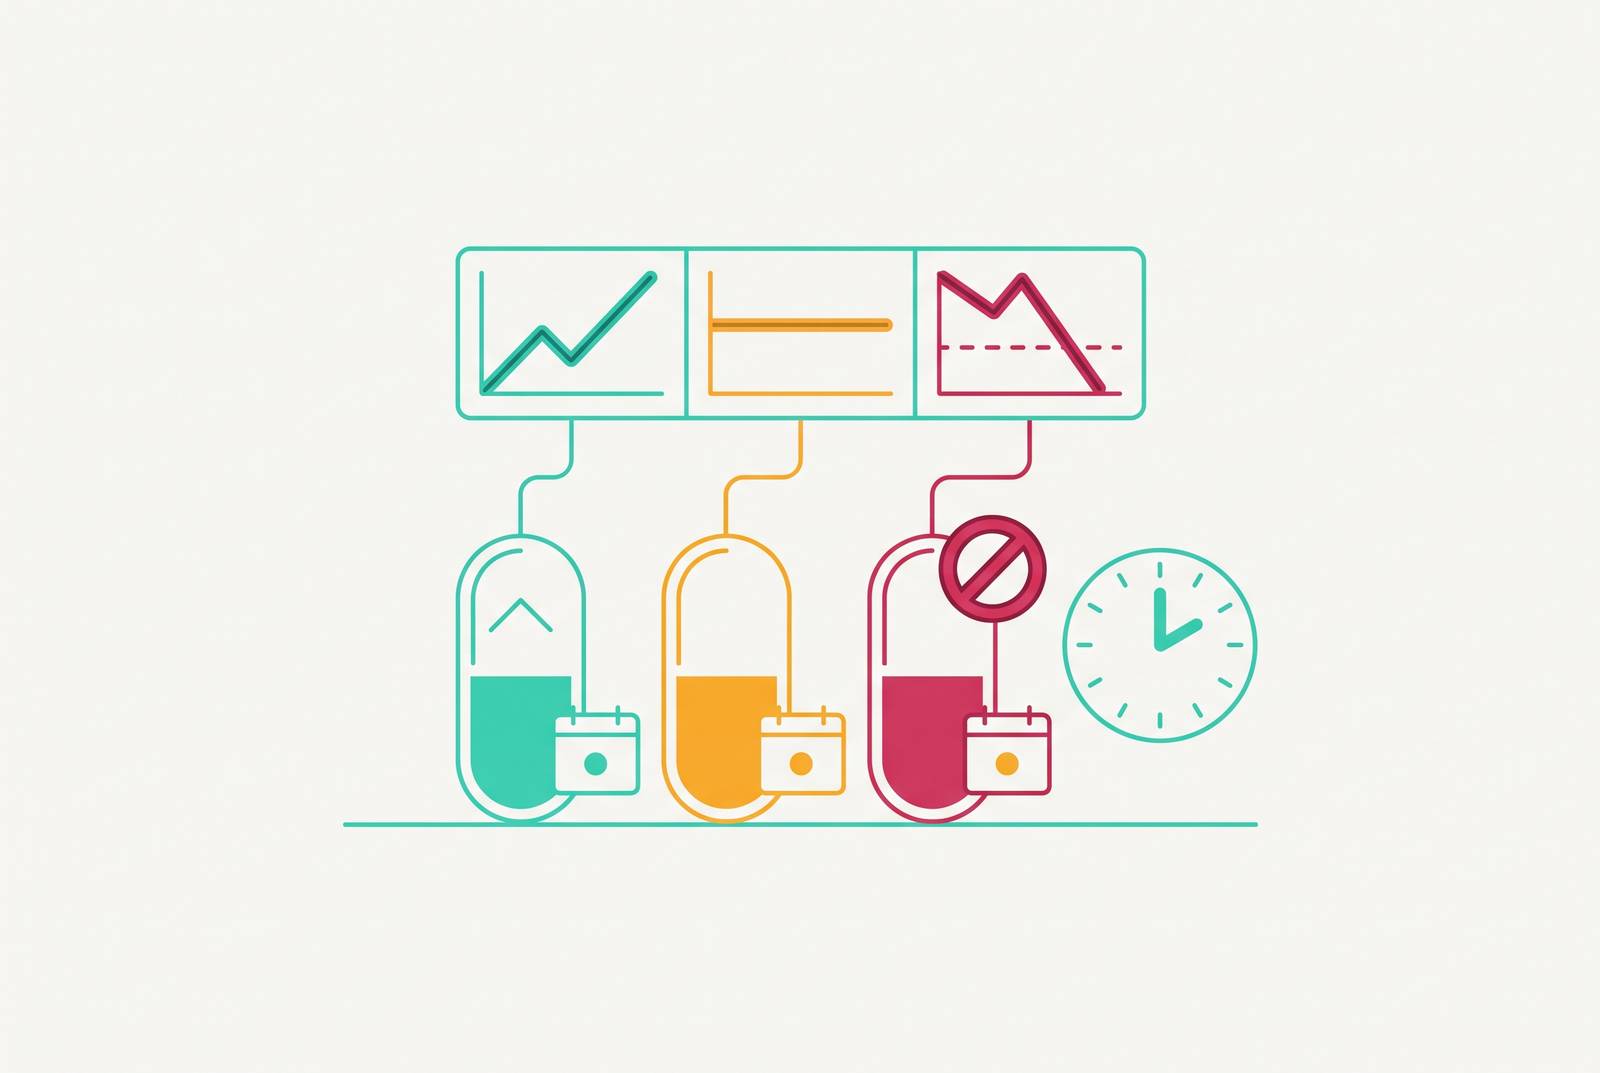
Growth marketing becomes easier to judge when every experiment ships with a signal, a check date, and a kill condition. Treating growth changes like software deployments turns an anxious wait into a monitoring problem a team can solve.
Why "how long does growth marketing take?" is the wrong question to ask
A founder stares at a dashboard, hoping the next change will show whether the work is paying off. How much longer should this take? The question sounds like a request for a date, but underneath it is a request for evidence. Is this bet working, or is patience becoming an excuse?
A calendar cannot settle that distinction on its own. The question mixes the time a single test needs to produce a signal with the time a whole growth system needs to mature. Those are different problems. An engineering approach separates them, then asks whether this experiment has produced its intended signal by its checkpoint. If not, a rule written before launch sets out what happens next.
The two clocks inside every growth program and why mixing them up stalls teams
Clock 1 is the experiment clock. It measures the window in which one test should produce readable evidence. For small growth experiments, one to two weeks is a useful working window, and a test that needs longer may be too large. That is not a universal deadline. A channel-level SEO experiment can reasonably need three to six months, with improved keyword rankings serving as the week-over-week or month-over-month goal metric.
Clock 2 is the system clock. It measures the compounding period in which repeated experiments build a framework that consistently outperforms its baselines. Quick wins, such as fixing broken tracking or getting more landing-page conversion, can show up in weeks. Real momentum typically takes several months of iteration.
The operational mistake is borrowing patience from the wrong clock. A team that expects system-level momentum in the time set for a small test can give up on promising work before it has time to grow. The reverse is just as damaging. Giving each experiment as much time as a compounding system lets weak bets keep going without evidence.
What a monitoring protocol for a growth experiment actually contains
The team can address this by writing a protocol before launch. Begin with the hypothesis, the customer-journey stage it concerns, and the primary metric and target. What change is expected, and what would count as evidence? Record the statistical confidence needed to interpret the result.
Next, give the experiment a start date and a check date appropriate to its channel. The checkpoint is a decision appointment. It should arrive when the test can reasonably produce the evidence its hypothesis requires. Write the kill condition beside it. With this threshold agreed in advance, the team knows when to stop or fix the current version and avoids having to negotiate once it sees the results.
Finally, give the experiment a place in a standing log. Every entry should keep the hypothesis, results, and what to do next, whether the test wins or loses. That record connects separate launches into a learning system. Without it, a failed experiment can leave little more than a vague recollection that something did not work. With it, the next test can begin from a specific unresolved question.
How to set kill conditions that actually fire before a zombie experiment consumes the quarter
Writing a kill condition can feel like pre-authorizing failure. That feeling can lead a team to agree with the principle but hold back from choosing a threshold. Before launch, however, no result needs defending. Pairing a fixed time limit with a minimum visitor count lets the team make the decision before emotional investment changes its judgment.
The threshold should answer one diagnostic question at a time. Has the experiment reached enough people to produce a meaningful signal? If not, weak results do not yet establish weak demand. Content and SEO experiments need a multi-month floor because crawling, indexing, and early ranking evaluation can collectively consume the first month. B2B experiments also need more time when higher CPCs, fewer impressions, and longer sales cycles make the signal take longer to appear.
Once reach is sufficient, the diagnosis can move downstream. A test can fail because it has no reach, because reach brings no interest, or because interest leads to no conversion. Each calls for a different correction. A kill condition therefore ends an unsupported course of action while leaving room to pursue the whole idea, and makes repeated testing safer.
AI assistance can summarize results and flag likely false positives, including segment-level losses hidden inside an aggregate win. But a named human should own the kill-or-continue decision and record the reasoning. Documenting and archiving losers prevents the same unsupported bets from returning under new names.
Experiment velocity as the actual driver of growth timeline, not the calendar
Growth timelines depend on how many instrumented experiments a team completes per unit of time. Many small tests can teach a team faster than one large monthly test, provided they produce interpretable results. Launch count alone is not experiment velocity. The team must make a decision on each experiment and use what it learned in the work that follows.
That rate depends on infrastructure as much as ambition. A standing log, pre-written kill conditions, and weekly reviews give the team a way to process feedback. Without them, more activity can create a larger backlog of unanswered questions. How quickly can this team turn a hypothesis into evidence and a decision?
GEO and AI answer engines as a growth channel with its own distinct monitoring logic
Generative engine optimization, or GEO, tests that discipline because AI visibility has a different signal from search rankings or ad click-through rates. ChatGPT, Claude, Gemini, and Perplexity are channels for brand discovery through synthesized answers. The unit to watch is the citation slot. Does the brand’s URL appear, where does it appear, and how does the engine attribute the claim?
The check date must reflect the engine’s sourcing mechanism. Perplexity crawls the web in real time and includes inline citations, so improvements can surface within hours to days. Its referrals appear in GA4 as perplexity.ai / referral, although isolating them from the generic Referral bucket requires a custom channel group or filter. Gemini instead depends on Google’s live index. Google indexation is therefore a prerequisite, while extractability and entity authority influence citation more than organic ranking position.
A single prompt run is not a verdict. AI share of voice measures the share of brand mentions, citations, or recommendations captured across a defined category-prompt set relative to all brand mentions in those answers. Because answers vary, visibility should be reported as ranges across a prompt panel.
For a team applying the protocol, that means running the core query set weekly. Checking every day adds too much noise, but checking once a month can miss changes that matter. Each run should record whether a citation appears, its list position, the sentiment, and which external sources or URLs are cited. The kill condition then needs to treat a lack of citations differently from a lack of referrals or conversions, because these signals come from different stages of the experiment.
Why third-party sources dominate AI citations and what that means for where to publish
A brand’s own website is the weakest citation source in this channel, while third-party sources account for the dominant share of AI citations. That changes the location of the experiment. Publishing a strong answer on an owned page and waiting may test the wrong distribution surface, leaving the quality of the answer unresolved.
The ground site is the brand-owned publishing surface. Phantom-site distribution means earning a place in industry publications, review platforms, community forums, and comparison sites. These are not interchangeable routes to visibility. A GEO protocol should track how fast the team earns third-party placements as well as its citation rate.
Placement is only one possible explanation for citation failure. Malformed HTML or excessive noise can cause problems at the parsing stage, while truncation and poor content ordering can affect fetching and context. Entity gaps or intent mismatch can interfere at generation. Rewriting the argument will not necessarily repair a failure to parse or fetch it.
How a multi-stage AI content pipeline keeps experiment velocity high without sacrificing citability
Publishing multiple answer assets across multiple surfaces on a weekly cadence requires a pipeline with its own checkpoints. Treating AI generation as a vending machine produces drafts without establishing whether they can earn citations. Volume is not the missing control here. The pipeline needs defined outputs and gates that keep an unfinished draft from becoming a published experiment.
The brief stage should set out the hypothesis and target prompt set before writing starts. AI assistance can then accelerate drafting, but the draft remains an input to review. At the review gate, a human decides whether to proceed, revise, or kill the asset. That is where speed meets editorial judgment. Distribution then routes the asset to the ground site or a third-party surface according to where it is most likely to earn a citation.
The measurement layer connects publication back to the experiment. Standing watchers can start drafts when something relevant happens, while the weekly prompt panel shows whether the assets that have been published are earning citations. These serve different purposes. One accelerates the response to an opportunity, and the other tests whether that response worked. Human review prevents volume from outrunning quality, while AI assistance reduces the drafting burden that would otherwise slow the cycle.
Applying the full monitoring protocol: one experiment from hypothesis to kill-or-scale decision
Consider an answer-asset experiment targeting five prompts on Perplexity. The hypothesis is that publishing answers suited to those prompts, with distribution chosen for citation potential, will earn citations and attributable visits. Before drafting, the team records citation rate across the five prompts as its primary signal and Perplexity referral traffic in GA4 as supporting evidence. It plans to run the prompt panel each week and make a decision at a four-week checkpoint. The broader growth system is not being judged at that checkpoint.
Before launch, the team also records a minimum answer-page view threshold. The notes do not supply a universal count, so the team must set that number for this experiment. The condition is specific nonetheless. Fewer views than the agreed minimum at four weeks will trigger a distribution correction, leaving the quality of the content unresolved.
The asset then passes through drafting, human review, and distribution. Each weekly panel records whether citations appear, where they appear, how the brand is described, and which sources are used. GA4 separately records the attributable referral visits. Those observations should not be collapsed into one success score. A citation and a visit answer different questions.
At four weeks, the written conditions govern the decision. If views fall below the minimum, the team fixes distribution before revising the content. If reach is sufficient but citation rate is zero, it checks malformed HTML, truncation, and structure before changing the argument. If citations and reach are present but conversion is absent, the offer or next step becomes the correction target. If the pre-written success conditions are met, the evidence supports continuing or scaling the test.
The named decision owner records the result, the diagnosis, and the next action in the experiment log. A loss shows where the test failed while leaving room to try the channel again. A win leaves conditions that the next experiment can test again. That entry is the compounding asset the next decision can build on.