"Creative agency" for a B2B startup, where people direct agents and check each piece: what a technical buyer should test before trusting machine-made decks, ads and pages
Buyers should test whether an AI agency's checks can stop bad work.
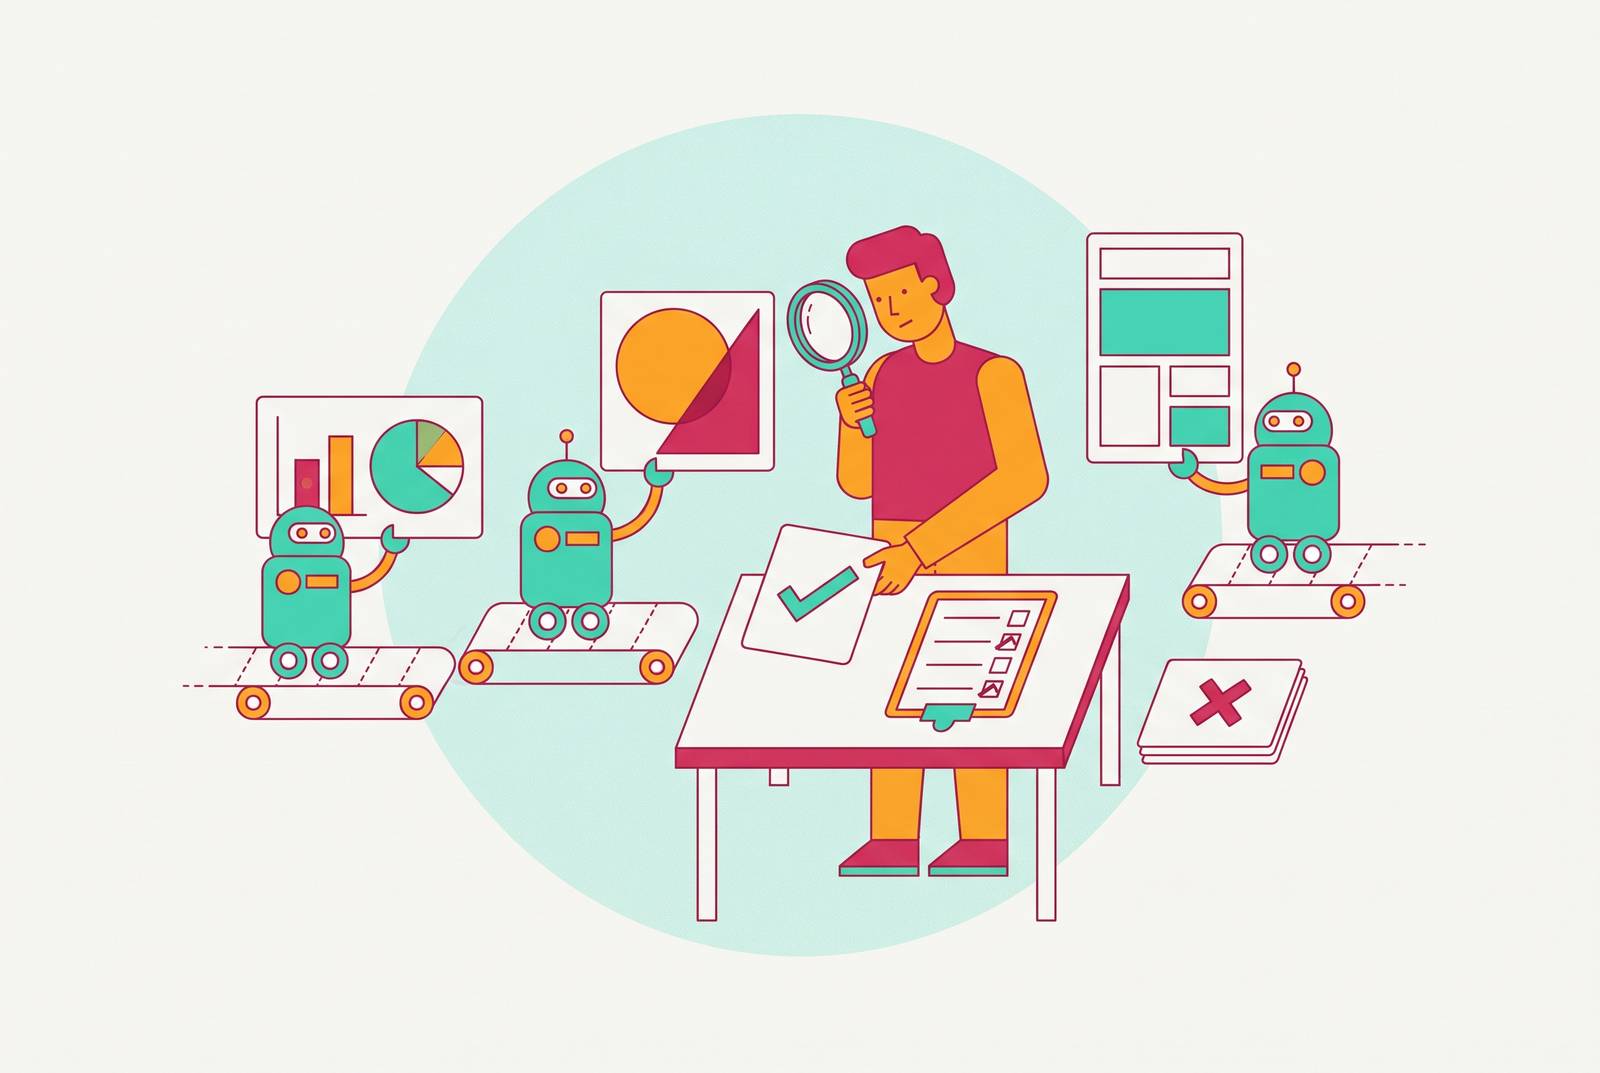
An agent-based creative agency should be judged by its controls. For a B2B startup buying machine-made decks, ads, and pages, the test is whether factual checks, brand rules, citation-ready content, measurement, and a human veto work in practice. A technical buyer needs evidence that the service can stop bad work.
Why the "human-directed, agent-produced" pitch deserves scrutiny before a technical buyer commits
“Humans direct and check each piece” sounds like a clear promise. It can describe a reviewer who checks every claim and rejects unsuitable work, or someone who polishes the wording before approving whatever the agent produced. An invented statistic in a sales deck, a landing page that misstates the product, or an ad that contradicts its capabilities exposes the difference.
Technical founders and growth engineers are well placed to expose that difference because they can compare the output with what the product actually does. They are also likely to recognize errors that a vendor’s reviewer could miss. This makes the audit part of the buying decision, rather than an assurance to leave with the vendor’s marketing team. What, specifically, should the buyer test?
How a well-structured pipeline is actually supposed to work — and where it breaks
A sound reference model has separate phases for human strategic input, agent production, and human quality assurance. Each phase needs someone who can stop the work before it moves to the next phase. At the start, people define the objective, the target members of the buying committee, competitive positioning, and proprietary context. The agent cannot infer that context reliably on its own. If the brief leaves it out, later review must repair a direction that should never have been approved.
Agent production then turns the brief into drafts, structures, and variants. The outline is an especially useful intervention point. A human editor can redirect or reject it before the agent expands an unsuitable argument into thousands of words. This is a strategic check because it asks whether the proposed piece serves the intended buyer and objective.
Human quality assurance comes last, but it cannot make up for every check missed earlier in the process. A tightly specified brief can still produce an inaccurate claim, while an accurate draft can still miss the brand’s position. These errors need different checks. The buyer’s reference model should therefore distinguish who sets the direction, who checks the output, and who can prevent its release.
Factual accuracy — the highest-consequence failure mode in agent-produced decks, ads, and pages
The most dangerous gap in final review is confident text that nobody verifies. AI predicts probable text from training data, so a specific claim can sound entirely reasonable and still be fabricated or misattributed. Fluency provides no evidence that it is true. In B2B content, this can lead to invented statistics in thought leadership, false claims about competitors that carry legal risks, and wrong product specifications that mislead technical evaluators.
Charts deserve particularly close attention because their visual authority can suppress skepticism. For sales decks, the practical test is to build customer-facing charts from approved, versioned spreadsheet data and compare the final slide with the source row by row. Values and labels both need checking. A person who did not create the deck should then present it on a test call and flag anything they cannot defend.
Landing pages need the same discipline at claim level. Every specific claim, statistic, or quoted figure remains unverified until traced to its primary source. If the source cannot be located and confirmed, the claim should be cut. Ads need this scrutiny too, because compressed copy can put a problematic claim before far more prospects than a buried paragraph.
To see whether those checks are sustainable, the buyer should request two operational measures. First-pass yield is the share of drafts passing all automated guardrails without regeneration. Human review rate is the share requiring manual intervention. These reveal how much correction the pipeline pushes onto people. A service unable to show either is asking the buyer to trust a black box.
Brand-voice fidelity — what it means to test whether a human veto actually stops bad work from shipping
Factual correctness does not establish that someone is steering the work. A deck, ad, and landing page can each be accurate yet sound as if they came from different businesses. That variance weakens the credibility signal technical buyers receive. Brand-voice fidelity is therefore an operational consistency requirement.
The prompt library and brand-guidelines document show how the brand’s voice is defined. A few adjectives and a tone word give the agent little constraint, whereas negative examples establish boundaries through phrases the brand does not use, framings to avoid, and competitor comparisons that are off-limits. Those boundaries make deviations easier to recognize. A centralized asset and prompt library should also hold approved prompts, citation requirements, banned phrases, and a disclosure policy for AI-assisted pages.
The buyer should ask for a rejected draft and examine what happened next, whether the vendor corrected the prompt and regenerated it, revised it manually, or approved it anyway. Rejection must change the course of the work. A veto that is available but never exercised in the vendor’s examples provides no evidence that unsuitable content will be stopped.
AI-answer-engine legibility — testing whether agent-produced content can actually be cited by ChatGPT, Claude, Gemini, and Perplexity
Once content is accurate and recognizably on-brand, the next question concerns external legibility. Can an AI answer engine find, extract, and cite it? Ranking on Google does not answer that question. A vendor claiming GEO or AEO capability needs to explain the routes it addresses rather than treating those claims as another name for SEO.
Training data, retrieval/RAG, and live search or browsing are distinct routes. Training is what models learned before they were put to use, so it matters that entity facts stay the same across independent sources over time. Retrieval concerns what a live-grounded engine pulls at query time, which favors standalone passages that answer a question without surrounding context. Live browsing concerns what an engine can fetch on demand, making freshness and crawlability relevant. A strategy for one route leaves the others unexplained.
The entity layer and robots.txt are quick places to start checking. The buyer should ask whether a Wikidata record has been created and verified, while recognizing that its absence does not make a brand universally invisible to models. Crawler rules also need precise interpretation. GPTBot is a training crawler, while OAI-SearchBot serves ChatGPT search, so blocking the former does not by itself remove a site from the latter. PerplexityBot belongs in the check too, but crawler settings alone cannot establish whether citations will appear.
Content structure provides another inspectable artifact. The recommended test is a 40–60 word opening capsule for each content pillar, stating its thesis as a self-contained block. Published pages should also expose structured data using the appropriate BlogPosting or Article schema, which the vendor should be able to show. The buyer still needs evidence that the claimed strategy reaches the intended engines.
Ground-site and phantom-site architecture — confirming the content strategy works on both human and machine readers
A ground site is the layer built for people, with pages that serve commercial and Google organic search intent. A phantom site, or citation layer, is content built primarily for machine discovery and citation, including definitions, entity relationships, and brand authority signals. The two purposes can complement each other. A credible vendor should identify which pages serve each purpose.
The citation layer needs the same quality bar as the human-facing work. Its intended audience does not excuse fabricated claims, generic filler, or incoherent prose if a person encounters it. The brand’s name is still attached to it. To test a page, the buyer should read it as a human and ask whether it contains at least one specific, verifiable, non-generic claim that could stand alone as an answer.
Indexing is not proof that this architecture works. Thin pages packed with entity signals may give an engine little it can extract without contradiction, leaving people with nothing of value and engines with nothing they can cite. Visibility can also move differently across surfaces. A page can lose Google clicks while gaining AI citations, or earn citations without ever ranking in Google, so the two layers need reporting that distinguishes those outcomes.
Measuring whether the pipeline is working — the indicators a technical buyer should require before and after launch
Without a baseline and before-and-after reporting, a buyer cannot distinguish a functioning control from a persuasive description of one. The measurement layer needs to be part of the work before launch.
The yield and intervention measures should be read together. Low first-pass yield points toward poorly calibrated prompts or model setup, while sustained manual intervention calls the promised speed and economics into question. Correction rate in review adds another signal. A falling rate can indicate improvement, whereas a flat or rising rate gives no such evidence, though fewer corrections alone cannot prove quality when the rigor of review is uncertain.
Share of citation should be tracked across buyer-relevant prompts in ChatGPT, Claude, Gemini, and Perplexity, with unprompted brand mentions showing whether the brand appears without being named in the question. Visible AI referral traffic and branded search lift provide downstream signals. During the sales conversation, the vendor should run a live buyer-relevant query in ChatGPT and Perplexity and discuss which sources appear and what they share. One query tests whether live measurement is available.
AI-assisted and human-only work should be compared using organic engagement, conversion to demo or contact, and correction rate, with each measure tracked separately. Reports also need to show ground-site and citation-layer pages separately. Otherwise, an organic-traffic-only report can conceal citation gains or leave an underperforming citation layer unexamined.
The practical audit — what to ask, what to check, and what a "no" on any gate should mean for the engagement
For a vendor conversation or proof of concept, the five gates become requests for specific evidence. They are not equally consequential. Factual errors create the greatest legal and credibility exposure, brand drift is readily visible to buyers, and failed AI legibility can quietly undermine the strategy. A “no” should therefore trigger a concrete follow-up.
Gate one is factual accuracy. Request yield data and a sample draft with citations, then trace a claim to its primary source. Ask how a hallucinated statistic discovered after publication would be corrected. Missing yield data, spot-checking in place of systematic verification, or no documented correction process calls for evidence of the missing control before commitment.
Gate two is human veto integrity. Ask for a rejected draft and what happened to it next, and ask whether there is a written human-only policy for Tier 3 content covering pricing, legal topics, and named competitors. “Light edit” or “final polish” does not establish stop authority. If no rejection example or content-tier structure exists, the follow-up is to require those safeguards to be demonstrated.
Gate three is brand-voice fidelity. Ask for negative examples from the prompt library and guidelines, then ask who owns the standard and how deviations are escalated. Adjectives alone do not define usable boundaries. A promise to learn the voice over time needs a structured intake process behind it.
Gate four is AI-answer-engine legibility. Check crawler rules, published schema, and the vendor’s handling of entity records, including Wikidata. Ask which of the three routes the strategy addresses. If crawler restrictions go unexplained, schema is missing, or GEO is described only as good SEO, the vendor needs to explain the technical choices and show that it can do what it claims.
Gate five is measurement. Ask for the live citation query and sample reports that show citation share, branded search lift, and how the cohorts performed. Confirm that both content layers appear in the reports. Organic-traffic-only measurement leaves the AI citation promise untested.
A vendor demonstrating all five gates with artifacts has a pipeline worth testing at small scale before full commitment. Failure to demonstrate any two leaves too much of the service dependent on the buyer not looking closely. The value of agent-produced creative is real only when its accountability architecture is as engineered as its production pipeline.